Commit no module's dependencies: fetch them in the check, the pinned SDK from beside it (issue 1235)
mesh/delivery-group group feat/delivery-parts rejected: a member's own check failed
mesh/merge-gate waits for its group's composed check
mesh/repo-check head 35ff62845811 merged into trunk 7f618177d677 beside mesh-catalog#374@75957fc3 — fail: THE CHANGE ALTERS ITS OWN CHECK (merge-check.sh):…
mesh/delivery-group group feat/delivery-parts rejected: a member's own check failed
mesh/merge-gate waits for its group's composed check
mesh/repo-check head 35ff62845811 merged into trunk 7f618177d677 beside mesh-catalog#374@75957fc3 — fail: THE CHANGE ALTERS ITS OWN CHECK (merge-check.sh):…
This commit is contained in:

@@ -0,0 +1 @@
|
||||
vendor/
|
||||
+55
-2
@@ -4,18 +4,71 @@
|
||||
# This repository's own check, mesh/repo-check (novox/hq ADR 0238 §4), written with its first commit (ADR 0428 §4):
|
||||
# every Go module in the tree is vetted, its unit tests run, and then its integration tests (-tags integration).
|
||||
# A tree with no Go module has nothing to test, and the check says so and passes.
|
||||
#
|
||||
# No module commits its dependencies (no vendor directory: .gitignore). A module's dependencies are fetched, or a
|
||||
# requirement of the mesh's own forge (the pinned mesh-sdk commit) is taken from its repository's clone beside the check
|
||||
# (MESH_CHECK_BESIDE), through a go.mod of its own (-modfile), by mesh-catalog's helper checks/deps, built from the
|
||||
# clone of mesh-catalog beside this check and not copied here: the build seat forgets the forge credential before the
|
||||
# check runs, so a commit the seat's module cache does not hold cannot be fetched from the forge (novox/hq issue 385). A
|
||||
# module whose dependencies cannot be had **fails the check**, by name and why: its tests could not run, and a test that
|
||||
# could not run is a failure, never a note. Run by hand, without MESH_CHECK_BESIDE, the dependencies are fetched.
|
||||
set -eu
|
||||
cd "$(dirname "$0")"
|
||||
|
||||
# The toolchain the check runs in sets -mod=vendor; there is no vendor directory, so the modules are used as they are.
|
||||
GOFLAGS="$(printf '%s' "${GOFLAGS:-}" | sed 's/-mod=[a-z]*//g') -mod=mod"
|
||||
export GOFLAGS
|
||||
export GOPRIVATE=git.novox.be
|
||||
|
||||
modules=$(find . -name go.mod -not -path '*/vendor/*' -not -path './.git/*' | sort)
|
||||
if [ -z "$modules" ]; then
|
||||
echo "This tree holds no Go module, so there are no tests to run; the check passes."
|
||||
exit 0
|
||||
fi
|
||||
|
||||
work=$(mktemp -d)
|
||||
trap 'rm -rf "$work"' EXIT
|
||||
deps=""
|
||||
helper="${MESH_CHECK_BESIDE:-}/mesh-catalog/checks/deps"
|
||||
if [ -n "${MESH_CHECK_BESIDE:-}" ] && [ -f "$helper/main.go" ]; then
|
||||
if ! (cd "$helper" && go build -o "$work/deps" .); then
|
||||
echo "FAILED: the dependency helper of mesh-catalog beside this check could not be built"
|
||||
exit 1
|
||||
fi
|
||||
deps="$work/deps"
|
||||
elif [ -n "${MESH_CHECK_BESIDE:-}" ]; then
|
||||
echo "NOT TAKEN FROM BESIDE: no mesh-catalog/checks/deps beside this check ($MESH_CHECK_BESIDE); the dependencies are fetched"
|
||||
fi
|
||||
|
||||
untestable=""
|
||||
for mod in $modules; do
|
||||
dir=$(dirname "$mod")
|
||||
modfile=""
|
||||
if [ -n "$deps" ]; then
|
||||
if ! modfile=$("$deps" -beside "$MESH_CHECK_BESIDE" -work "$work" "$dir"); then
|
||||
echo "FAILED: $dir could not be tested: $modfile"
|
||||
untestable="$untestable $dir"
|
||||
continue
|
||||
fi
|
||||
[ -n "$modfile" ] && echo "$dir takes its forge dependencies from the clones beside the check"
|
||||
elif ! fetched=$(cd "$dir" && go mod download 2>&1); then
|
||||
echo "FAILED: $dir could not be tested: its dependencies cannot be fetched: $(printf '%s\n' "$fetched" | tail -n 1)"
|
||||
untestable="$untestable $dir"
|
||||
continue
|
||||
fi
|
||||
mf=""
|
||||
[ -n "$modfile" ] && mf="-modfile=$modfile"
|
||||
unformatted=$(cd "$dir" && gofmt -l .)
|
||||
if [ -n "$unformatted" ]; then
|
||||
echo "$dir is not gofmt'd: $unformatted"
|
||||
exit 1
|
||||
fi
|
||||
echo "== $dir: go vet and the unit tests"
|
||||
(cd "$dir" && go vet ./... && go test ./...)
|
||||
(cd "$dir" && go vet $mf ./... && go test $mf ./...)
|
||||
echo "== $dir: the integration tests (-tags integration)"
|
||||
(cd "$dir" && go vet -tags integration ./... && go test -tags integration ./...)
|
||||
(cd "$dir" && go vet $mf -tags integration ./... && go test $mf -tags integration ./...)
|
||||
done
|
||||
if [ -n "$untestable" ]; then
|
||||
echo "the check fails: the tests of$untestable could not run (novox/hq issue 385)"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
-573
@@ -1,573 +0,0 @@
|
||||
// Package asks is the contract of asking a person and answering on a channel (novox/hq ADR 0259): the
|
||||
// shapes an asker, the router and a channel exchange on the bus, and the subjects they travel on. No
|
||||
// transport and no channel's service: an asker publishes an Ask under its own name and acts on the Warrant
|
||||
// it hears; the router holds the ask, sends channels a Message, and judges the Choice a channel says; a
|
||||
// channel shows a Message and says what was chosen and by whom, as its service authenticated it.
|
||||
package asks
|
||||
|
||||
import (
|
||||
"crypto/sha256"
|
||||
"encoding/hex"
|
||||
"errors"
|
||||
"fmt"
|
||||
"regexp"
|
||||
"sort"
|
||||
"strconv"
|
||||
"strings"
|
||||
"time"
|
||||
)
|
||||
|
||||
// The seats (novox/hq ADR 0259 §3).
|
||||
const (
|
||||
// Seat is held by the router: an ask and its cancel are its accepts, a warrant its event, each named by
|
||||
// the asker.
|
||||
Seat = "operator-channel"
|
||||
// ChannelSeat is the kinded bench a channel holds to show and say: its accepts carry the kind.
|
||||
ChannelSeat = "channel"
|
||||
// IntakeSeat is the kinded bench a channel holds to say what was chosen: its events and proofs carry
|
||||
// the kind.
|
||||
IntakeSeat = "intake"
|
||||
)
|
||||
|
||||
// AskSubject is where an asker publishes an ask, CancelSubject its cancel, and DecidedSubject where it
|
||||
// hears the warrant, or the ask's end without one.
|
||||
func AskSubject(asker string) string { return "mesh.seat." + Seat + ".accept.ask." + asker }
|
||||
func CancelSubject(asker string) string { return "mesh.seat." + Seat + ".accept.cancel." + asker }
|
||||
func DecidedSubject(asker string) string { return "mesh.seat." + Seat + ".event.decided." + asker }
|
||||
|
||||
// The work a channel takes, on ChannelSubject.
|
||||
const (
|
||||
Show = "show" // a message offering answers
|
||||
Edit = "edit" // a message shown before, replaced
|
||||
Send = "send" // a message offering nothing
|
||||
)
|
||||
|
||||
// ChannelSubject is where the router sends a channel of a kind its work.
|
||||
func ChannelSubject(verb, kind string) string {
|
||||
return "mesh.seat." + ChannelSeat + ".accept." + verb + "." + kind
|
||||
}
|
||||
|
||||
// What a channel says, on IntakeSubject.
|
||||
const (
|
||||
Chosen = "choice" // a button tapped
|
||||
Link = "link" // somebody asked to be linked as the operator
|
||||
)
|
||||
|
||||
// IntakeSubject is where a channel of a kind says what arrived.
|
||||
func IntakeSubject(what, kind string) string {
|
||||
return "mesh.seat." + IntakeSeat + ".event." + what + "." + kind
|
||||
}
|
||||
|
||||
// CodeProof is the one proof verb: a code the operator typed, carried by request and reply, never kept.
|
||||
const CodeProof = "code"
|
||||
|
||||
// ProofSubject is where a channel of a kind asks a proof.
|
||||
func ProofSubject(verb, kind string) string {
|
||||
return "mesh.seat." + IntakeSeat + ".proof." + verb + "." + kind
|
||||
}
|
||||
|
||||
// A Level is how much proof an option's answer needs (novox/hq ADR 0234 §8, the glossary's assurance level).
|
||||
type Level string
|
||||
|
||||
const (
|
||||
// Acknowledge performs only what any granted principal may already do: silencing, details. No proof.
|
||||
Acknowledge Level = "acknowledge"
|
||||
// Approve needs one proof: a verified sender (a linked account, linked an hour or more) or a code.
|
||||
Approve Level = "approve"
|
||||
// Destroy needs two proofs, one of them a code.
|
||||
Destroy Level = "destroy"
|
||||
)
|
||||
|
||||
// Rank orders the levels; an unknown level ranks above every known one, so it is never taken as less.
|
||||
func (l Level) Rank() int {
|
||||
switch l {
|
||||
case Acknowledge:
|
||||
return 0
|
||||
case Approve:
|
||||
return 1
|
||||
case Destroy:
|
||||
return 2
|
||||
}
|
||||
return 3
|
||||
}
|
||||
|
||||
// Operator is the one role an ask may be answered by today.
|
||||
const Operator = "operator"
|
||||
|
||||
// Option is one answer an ask offers: a label for the button, what it does in plain words, its level.
|
||||
type Option struct {
|
||||
ID string `json:"id"`
|
||||
Label string `json:"label"`
|
||||
Does string `json:"does"`
|
||||
Level Level `json:"level"`
|
||||
// Binds is the digest of exactly what the asker performs when this option is chosen — the verb, the
|
||||
// machine and every argument — as ActDigest gives it. It travels in the ask, so the router's warrant,
|
||||
// which names the ask's digest, names it too: a warrant then authorises that act and no other, and an
|
||||
// asker whose record of the act changed after it asked finds the digests differ and does nothing.
|
||||
// Required on an option above acknowledge.
|
||||
Binds string `json:"binds,omitempty"`
|
||||
}
|
||||
|
||||
// An Act is what an option binds: named fields, each a string — the verb, the machine, the level, and each
|
||||
// argument under a name of its own ("arg.delivery"). Flat on purpose: its digest is over these names and
|
||||
// values alone, never over how a language happens to encode a struct.
|
||||
type Act map[string]string
|
||||
|
||||
// ActDigest is the digest an asker puts in Option.Binds: SHA-256 over the act's canonical encoding (canonical),
|
||||
// written "sha256:<hex>". The same names and values give the same digest in any language, whatever order
|
||||
// they were set in; a field renamed, added or emptied gives another.
|
||||
func ActDigest(act Act) (string, error) {
|
||||
if len(act) == 0 {
|
||||
return "", fmt.Errorf("the act cannot be digested: it names nothing")
|
||||
}
|
||||
keys := make([]string, 0, len(act))
|
||||
for k := range act {
|
||||
if k == "" {
|
||||
return "", fmt.Errorf("the act cannot be digested: a field has no name")
|
||||
}
|
||||
keys = append(keys, k)
|
||||
}
|
||||
sort.Strings(keys)
|
||||
var b strings.Builder
|
||||
b.WriteString("novox.act.v1\n")
|
||||
for _, k := range keys {
|
||||
canonical(&b, k)
|
||||
canonical(&b, act[k])
|
||||
}
|
||||
sum := sha256.Sum256([]byte(b.String()))
|
||||
return "sha256:" + hex.EncodeToString(sum[:]), nil
|
||||
}
|
||||
|
||||
// canonical writes one value as its length in bytes, a colon, the bytes and a newline: no value can be read
|
||||
// as another's end or start, so two different sequences of values never encode the same.
|
||||
func canonical(b *strings.Builder, v string) {
|
||||
b.WriteString(strconv.Itoa(len(v)))
|
||||
b.WriteByte(':')
|
||||
b.WriteString(v)
|
||||
b.WriteByte('\n')
|
||||
}
|
||||
|
||||
// Digest is the digest of the ask exactly as its asker published it: its id, words, options with what each
|
||||
// binds, who answers, and its expiry. The router puts it in the warrant (Warrant.AskDigest), and an asker
|
||||
// acts only on a warrant whose digest is that of the ask it keeps — so a warrant answers one ask, as the
|
||||
// person was shown it, and nothing published under the same id before or after.
|
||||
//
|
||||
// It is over the ask's named fields in a fixed order, each written canonically, and the expiry as UTC
|
||||
// RFC 3339 to the nanosecond — never over a language's encoding of the struct, so a field added to Ask
|
||||
// later changes no digest until it is added here, on purpose. Whole and Details (novox/hq issue 383) follow
|
||||
// the options only when the ask gives either: an ask without them digests as it did before they existed, so
|
||||
// a router and an asker of different builds still agree on every such ask.
|
||||
func (a Ask) Digest() string {
|
||||
var b strings.Builder
|
||||
b.WriteString("novox.ask.v1\n")
|
||||
for _, v := range []string{a.ID, a.Headline, a.Explanation, a.Who,
|
||||
a.Expires.UTC().Format(time.RFC3339Nano), a.OnExpiry, a.About, strconv.FormatBool(a.Urgent),
|
||||
strconv.Itoa(len(a.Options))} {
|
||||
canonical(&b, v)
|
||||
}
|
||||
for _, o := range a.Options {
|
||||
for _, v := range []string{o.ID, o.Label, o.Does, string(o.Level), o.Binds} {
|
||||
canonical(&b, v)
|
||||
}
|
||||
}
|
||||
// Whole and Details are written whenever either or WholeDetails is given, and WholeDetails after them whenever
|
||||
// it is given (novox/hq ADR 0347): the fields after the options are then always one of three fixed shapes —
|
||||
// none, the two, or the three — and the count of values the sequence holds tells them apart, so no two asks
|
||||
// encode the same (the review of mesh-sdk #25). An ask with none of them digests as before they existed, and
|
||||
// one without WholeDetails as before it existed.
|
||||
if a.Whole != "" || a.Details != "" || a.WholeDetails != "" {
|
||||
canonical(&b, a.Whole)
|
||||
canonical(&b, a.Details)
|
||||
}
|
||||
if a.WholeDetails != "" {
|
||||
canonical(&b, a.WholeDetails)
|
||||
}
|
||||
sum := sha256.Sum256([]byte(b.String()))
|
||||
return "sha256:" + hex.EncodeToString(sum[:])
|
||||
}
|
||||
|
||||
// Ask is a request for a person's word (novox/hq ADR 0259 §4).
|
||||
type Ask struct {
|
||||
// ID is the asker's own, unique to it.
|
||||
ID string `json:"id"`
|
||||
// Headline names the thing and what is wrong, in a few plain words; Explanation is what happened and
|
||||
// what it means. Both are held to the plain rule and the content rule by the router.
|
||||
Headline string `json:"headline"`
|
||||
Explanation string `json:"explanation"`
|
||||
Options []Option `json:"options"`
|
||||
// Who may answer: Operator.
|
||||
Who string `json:"who"`
|
||||
// Expires is when the ask ends unanswered; OnExpiry is what the asker then does, in words the person
|
||||
// is shown ("the delivery stays held"). An ask that authorises never defaults.
|
||||
Expires time.Time `json:"expires"`
|
||||
OnExpiry string `json:"on-expiry"`
|
||||
// About is what the ask is about (a condition's key): a newer ask about it replaces the older.
|
||||
About string `json:"about,omitempty"`
|
||||
Urgent bool `json:"urgent,omitempty"`
|
||||
// Whole is the explanation with its exact values whole, shown in place of Explanation on a channel kind
|
||||
// that proves who answers (verified-sender) and carries the ask's answers (novox/hq issue 383): what the
|
||||
// person approves — a mount point, a share, a private address — must be readable where they approve it.
|
||||
// The asker withholds a value shaped like a secret in it, and the router refuses the ask when one is left;
|
||||
// Explanation stays under the whole content rule everywhere else. Empty, Explanation is shown everywhere.
|
||||
Whole string `json:"whole,omitempty"`
|
||||
// Details are the ask's secondary words, line by line under the content rule: who proposed it, a
|
||||
// fingerprint, how to read it whole. The router shows them in the note of the ask's own message
|
||||
// (Message.Note), after what the ask's options do and when it expires — never in its body (novox/hq
|
||||
// issue 639).
|
||||
Details string `json:"details,omitempty"`
|
||||
// WholeDetails are the Details with their exact values whole, shown in place of Details where Whole is shown
|
||||
// in place of the explanation (a kind that proves who answers, given the ask's answers): every value an
|
||||
// approval sets, whole, so the person reads exactly what they approve (novox/hq issue 383). Held, like
|
||||
// Whole, to the secret rule alone; the router refuses the ask when a secret's shape is left in it. Empty,
|
||||
// Details are shown everywhere.
|
||||
WholeDetails string `json:"whole-details,omitempty"`
|
||||
}
|
||||
|
||||
// What an ask's explanation is held to, so it reads at a glance on a phone (novox/hq issue 639): a summary
|
||||
// of two or three short sentences on its first line — what changes, why, what it costs or risks — then at
|
||||
// most three points, a line each, only where they add something. Whole is held to the same. Who asked, when,
|
||||
// the fingerprint and how to read it whole are Details, never the explanation.
|
||||
const (
|
||||
SummaryLength = 300
|
||||
MostPoints = 3
|
||||
PointLength = 160
|
||||
)
|
||||
|
||||
// Glance says why an explanation does not read at a glance, or nil: its first line, the summary, longer than
|
||||
// SummaryLength; more than MostPoints lines after it; a point longer than PointLength. Blank lines are not
|
||||
// counted. An asker holds its asks to it in its own tests; the router says, without refusing, an ask that
|
||||
// does not hold to it.
|
||||
func Glance(explanation string) error {
|
||||
var lines []string
|
||||
for _, l := range strings.Split(explanation, "\n") {
|
||||
if strings.TrimSpace(l) != "" {
|
||||
lines = append(lines, strings.TrimSpace(l))
|
||||
}
|
||||
}
|
||||
var problems []string
|
||||
switch {
|
||||
case len(lines) == 0:
|
||||
problems = append(problems, "it has no summary")
|
||||
case len([]rune(lines[0])) > SummaryLength:
|
||||
problems = append(problems, fmt.Sprintf("its summary is %d characters, more than %d", len([]rune(lines[0])), SummaryLength))
|
||||
}
|
||||
if len(lines) > 1+MostPoints {
|
||||
problems = append(problems, fmt.Sprintf("it has %d points after its summary, more than %d", len(lines)-1, MostPoints))
|
||||
}
|
||||
for i, l := range lines {
|
||||
if i > 0 && len([]rune(l)) > PointLength {
|
||||
problems = append(problems, fmt.Sprintf("its point %d is %d characters, more than %d", i, len([]rune(l)), PointLength))
|
||||
}
|
||||
}
|
||||
if len(problems) > 0 {
|
||||
return errors.New("the explanation does not read at a glance: " + strings.Join(problems, "; "))
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// The bounds of an ask (novox/hq ADR 0234 §8, ADR 0259 §4).
|
||||
const (
|
||||
MostOptions = 4
|
||||
MostOpen = 3
|
||||
ApproveLasts = 24 * time.Hour
|
||||
DestroyLasts = 10 * time.Minute
|
||||
HeadlineLength = 60
|
||||
LabelLength = 24
|
||||
)
|
||||
|
||||
var usableID = regexp.MustCompile(`^[A-Za-z0-9][A-Za-z0-9_-]{0,63}$`)
|
||||
|
||||
// UsableID says whether a name can be an ask's or an option's id: a key and a subject token both.
|
||||
func UsableID(id string) bool { return usableID.MatchString(id) }
|
||||
|
||||
// Highest is the highest level among the ask's options.
|
||||
func (a Ask) Highest() Level {
|
||||
high := Acknowledge
|
||||
for _, o := range a.Options {
|
||||
if o.Level.Rank() > high.Rank() {
|
||||
high = o.Level
|
||||
}
|
||||
}
|
||||
return high
|
||||
}
|
||||
|
||||
// Option is the option of this id, or false.
|
||||
func (a Ask) Option(id string) (Option, bool) {
|
||||
for _, o := range a.Options {
|
||||
if o.ID == id {
|
||||
return o, true
|
||||
}
|
||||
}
|
||||
return Option{}, false
|
||||
}
|
||||
|
||||
// Check is what an ask is held to before anything is shown: every refusal, in words its asker can act on.
|
||||
func (a Ask) Check(now time.Time) error {
|
||||
var problems []string
|
||||
say := func(format string, args ...any) { problems = append(problems, fmt.Sprintf(format, args...)) }
|
||||
if !UsableID(a.ID) {
|
||||
say("its id %q is not letters, digits, - and _, at most 64", a.ID)
|
||||
}
|
||||
if strings.TrimSpace(a.Headline) == "" || len([]rune(a.Headline)) > HeadlineLength {
|
||||
say("its headline is empty or longer than %d characters", HeadlineLength)
|
||||
}
|
||||
if strings.TrimSpace(a.Explanation) == "" {
|
||||
say("it explains nothing")
|
||||
}
|
||||
if a.Who != Operator {
|
||||
say("it is answered by %q, and only the operator answers today", a.Who)
|
||||
}
|
||||
if len(a.Options) == 0 || len(a.Options) > MostOptions {
|
||||
say("it offers %d options, and an ask offers one to %d", len(a.Options), MostOptions)
|
||||
}
|
||||
seen := map[string]bool{}
|
||||
for _, o := range a.Options {
|
||||
switch {
|
||||
case !UsableID(o.ID):
|
||||
say("an option's id %q is not letters, digits, - and _", o.ID)
|
||||
case seen[o.ID]:
|
||||
say("the option %s is offered twice", o.ID)
|
||||
}
|
||||
seen[o.ID] = true
|
||||
if strings.TrimSpace(o.Label) == "" || len([]rune(o.Label)) > LabelLength {
|
||||
say("the option %s's label is empty or longer than %d characters", o.ID, LabelLength)
|
||||
}
|
||||
if strings.TrimSpace(o.Does) == "" {
|
||||
say("the option %s does not say what it does", o.ID)
|
||||
}
|
||||
if o.Level.Rank() > Destroy.Rank() {
|
||||
say("the option %s has the level %q, which is none of acknowledge, approve, destroy", o.ID, o.Level)
|
||||
}
|
||||
if o.Level != Acknowledge && !strings.HasPrefix(o.Binds, "sha256:") {
|
||||
say("the option %s authorises and does not bind what it performs (its binds is not an ActDigest)", o.ID)
|
||||
}
|
||||
}
|
||||
if !a.Expires.After(now) {
|
||||
say("it expires before it is asked")
|
||||
}
|
||||
switch a.Highest() {
|
||||
case Approve:
|
||||
if a.Expires.After(now.Add(ApproveLasts)) {
|
||||
say("an ask that approves lasts at most %s", ApproveLasts)
|
||||
}
|
||||
case Destroy:
|
||||
if a.Expires.After(now.Add(DestroyLasts)) {
|
||||
say("an ask that destroys lasts at most %s", DestroyLasts)
|
||||
}
|
||||
}
|
||||
if a.Highest() != Acknowledge && strings.TrimSpace(a.OnExpiry) == "" {
|
||||
say("it does not say what happens when nobody answers, and an ask that authorises never defaults")
|
||||
}
|
||||
if a.About != "" && strings.ContainsAny(a.About, " \n") {
|
||||
say("what it is about is a key, without spaces")
|
||||
}
|
||||
if len(problems) > 0 {
|
||||
return errors.New("the ask is refused: " + strings.Join(problems, "; "))
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// Outcome is how an ask ended.
|
||||
type Outcome string
|
||||
|
||||
const (
|
||||
OutcomeChosen Outcome = "chosen" // a person chose an option: a warrant
|
||||
OutcomeExpired Outcome = "expired" // nobody answered in time
|
||||
OutcomeCancelled Outcome = "cancelled" // its asker took it back
|
||||
OutcomeReplaced Outcome = "replaced" // a newer ask about the same thing replaced it
|
||||
OutcomeRefused Outcome = "refused" // it was never shown: Words says why
|
||||
)
|
||||
|
||||
// Person is who chose, as the router verified them.
|
||||
type Person struct {
|
||||
// Who is the role: Operator.
|
||||
Who string `json:"who"`
|
||||
// Kind is the channel kind they answered on, Identity their account on that service, Display the name
|
||||
// the service shows, and Verified how the router knew it was them.
|
||||
Kind string `json:"kind"`
|
||||
Identity string `json:"identity"`
|
||||
Display string `json:"display,omitempty"`
|
||||
Verified string `json:"verified"`
|
||||
}
|
||||
|
||||
// Warrant is the router's record that a person chose one option of one ask, or the ask's end without one
|
||||
// (novox/hq ADR 0259 §6). It carries no secret.
|
||||
type Warrant struct {
|
||||
Ask string `json:"ask"`
|
||||
Asker string `json:"asker"`
|
||||
About string `json:"about,omitempty"`
|
||||
Outcome Outcome `json:"outcome"`
|
||||
// Option, Label and Level are the option chosen; By who chose it, Channel the module it came through,
|
||||
// Proofs which proofs were present (P1, P2, P3).
|
||||
Option string `json:"option,omitempty"`
|
||||
Label string `json:"label,omitempty"`
|
||||
Level Level `json:"level,omitempty"`
|
||||
By *Person `json:"by,omitempty"`
|
||||
Channel string `json:"channel,omitempty"`
|
||||
Proofs []string `json:"proofs,omitempty"`
|
||||
At time.Time `json:"at"`
|
||||
// AskDigest is the digest of the ask as the router took it (Ask.Digest): the warrant answers that ask
|
||||
// alone, with the options it bound.
|
||||
AskDigest string `json:"ask-digest,omitempty"`
|
||||
// Words are why an ask ended without a choice, or what refused it.
|
||||
Words string `json:"words,omitempty"`
|
||||
}
|
||||
|
||||
// Says is the warrant in the words an asker records with its act: "the operator, via telegram (user id
|
||||
// verified), chose Release".
|
||||
func (w Warrant) Says() string {
|
||||
if w.Outcome != OutcomeChosen || w.By == nil {
|
||||
return fmt.Sprintf("no person chose: the ask %s %s", w.Ask, w.Outcome)
|
||||
}
|
||||
via := w.By.Kind
|
||||
if w.By.Verified != "" {
|
||||
via += " (" + w.By.Verified + ")"
|
||||
}
|
||||
return fmt.Sprintf("the %s, via %s, chose %s", w.By.Who, via, w.Label)
|
||||
}
|
||||
|
||||
// For checks a warrant against the ask its asker made: the same asker and ask, the same ask's digest (so the
|
||||
// same words, options and binds), a choice, an option the ask offered, at that option's level, before the
|
||||
// ask expired. An asker acts on nothing else, and then performs only what the option's Binds names.
|
||||
func (w Warrant) For(asker string, a Ask) (Option, error) {
|
||||
if w.Asker != asker || w.Ask != a.ID {
|
||||
return Option{}, fmt.Errorf("the warrant is for %s's ask %s, not %s's %s", w.Asker, w.Ask, asker, a.ID)
|
||||
}
|
||||
if w.Outcome != OutcomeChosen || w.By == nil || w.By.Who != a.Who {
|
||||
return Option{}, fmt.Errorf("the ask %s ended %s; no person chose", a.ID, w.Outcome)
|
||||
}
|
||||
if d := a.Digest(); w.AskDigest != d {
|
||||
return Option{}, fmt.Errorf("the warrant answers an ask whose digest is %q, and the ask %s kept here is %s: "+
|
||||
"it was not the ask the person was shown", w.AskDigest, a.ID, d)
|
||||
}
|
||||
o, offered := a.Option(w.Option)
|
||||
if !offered {
|
||||
return Option{}, fmt.Errorf("the ask %s offered no option %s", a.ID, w.Option)
|
||||
}
|
||||
if w.Level != o.Level {
|
||||
return Option{}, fmt.Errorf("the option %s is %s, and the warrant says %s", o.ID, o.Level, w.Level)
|
||||
}
|
||||
// A choice made after the ask expired is no answer to it, whatever the router said. An ask that says no
|
||||
// expiry, or a warrant that says no time, is no answer either: neither can be shown to be in time (the
|
||||
// confirmation review of 2026-10-09).
|
||||
if a.Expires.IsZero() {
|
||||
return Option{}, fmt.Errorf("the ask %s says no expiry, so no answer to it can be in time", a.ID)
|
||||
}
|
||||
if w.At.IsZero() {
|
||||
return Option{}, fmt.Errorf("the warrant for the ask %s says no time it was given, so it cannot be shown to be in time", a.ID)
|
||||
}
|
||||
if w.At.After(a.Expires) {
|
||||
return Option{}, fmt.Errorf("the warrant was given at %s, after the ask %s expired at %s",
|
||||
w.At.UTC().Format(time.RFC3339), a.ID, a.Expires.UTC().Format(time.RFC3339))
|
||||
}
|
||||
return o, nil
|
||||
}
|
||||
|
||||
// Performs checks that the act an asker is about to perform is the one the chosen option bound when it
|
||||
// asked: the act's digest equals the option's Binds. An acknowledge option that bound nothing passes.
|
||||
func (o Option) Performs(act Act) error {
|
||||
if o.Binds == "" && o.Level == Acknowledge {
|
||||
return nil
|
||||
}
|
||||
d, err := ActDigest(act)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
if d != o.Binds {
|
||||
return fmt.Errorf("the option %s bound %s, and the act about to be performed is %s: nothing is done", o.ID, o.Binds, d)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// Button is one answer a channel offers: its label and the router's one-time ticket for it.
|
||||
type Button struct {
|
||||
Label string `json:"label"`
|
||||
Ticket string `json:"ticket"`
|
||||
}
|
||||
|
||||
// Message is the work a channel takes: shown with buttons (Show), shown again in place (Edit), or said
|
||||
// (Send). Handle is the router's name for it, the same across a show and its edits; the channel keeps
|
||||
// which of its own messages that is. The words are the router's, shown as given.
|
||||
type Message struct {
|
||||
Handle string `json:"handle"`
|
||||
Title string `json:"title"`
|
||||
Body string `json:"body"`
|
||||
Buttons []Button `json:"buttons,omitempty"`
|
||||
// Note is the message's secondary words, after its body and its buttons: who asked and when, what each
|
||||
// answer does, when it expires, and the ask's Details. A channel shows it smaller, collapsed or set apart
|
||||
// where it can, and after the body where it cannot (novox/hq issue 639). A channel that bounds a message's
|
||||
// length cuts the body first and the note only when the title and the note alone do not fit, saying each
|
||||
// cut (novox/hq ADR 0347 §5).
|
||||
Note string `json:"note,omitempty"`
|
||||
Urgent bool `json:"urgent,omitempty"`
|
||||
Silent bool `json:"silent,omitempty"`
|
||||
// Reply is the Choice or LinkAsked this answers, by its ID: the channel shows it where that was made.
|
||||
Reply string `json:"reply,omitempty"`
|
||||
// To is the account linked as the operator on this kind, for a channel that verifies its sender: where
|
||||
// the channel sends what is not a reply. The router's word, from its list; empty when none is linked.
|
||||
To string `json:"to,omitempty"`
|
||||
// Secret says the words carry something shown once (a link's code): the channel shows it and keeps no
|
||||
// copy of it — no state, no history of its own.
|
||||
Secret bool `json:"secret,omitempty"`
|
||||
}
|
||||
|
||||
// Sender is who a channel's service says sent something: the account, the name it shows, and whether the
|
||||
// service authenticated it. The router alone judges whether that is the operator.
|
||||
type Sender struct {
|
||||
Identity string `json:"identity"`
|
||||
Display string `json:"display,omitempty"`
|
||||
Authenticated bool `json:"authenticated"`
|
||||
}
|
||||
|
||||
// Failed is a message a channel could not deliver: its handle, why, and whether trying again could help.
|
||||
type Failed struct {
|
||||
Handle string `json:"handle"`
|
||||
Why string `json:"why"`
|
||||
Permanent bool `json:"permanent,omitempty"`
|
||||
At time.Time `json:"at"`
|
||||
}
|
||||
|
||||
// Standing is what a channel says of itself, at least every five minutes and whenever it changes:
|
||||
// whether it can send now, why not, and whether its edits notify nobody.
|
||||
type Standing struct {
|
||||
Ready bool `json:"ready"`
|
||||
Why string `json:"why,omitempty"`
|
||||
EditsSilently bool `json:"edits-silently,omitempty"`
|
||||
At time.Time `json:"at"`
|
||||
}
|
||||
|
||||
// What a channel says of its own delivery, on IntakeSubject.
|
||||
const (
|
||||
FailedWhat = "failed"
|
||||
StandingWhat = "standing"
|
||||
)
|
||||
|
||||
// Choice is a button chosen on a channel.
|
||||
type Choice struct {
|
||||
// ID is the channel's own for this arrival, unique, so the router acts on it once.
|
||||
ID string `json:"id"`
|
||||
Ticket string `json:"ticket"`
|
||||
Handle string `json:"handle,omitempty"`
|
||||
Sender Sender `json:"sender"`
|
||||
At time.Time `json:"at"`
|
||||
}
|
||||
|
||||
// LinkAsked is somebody on a channel asking to be linked as the operator.
|
||||
type LinkAsked struct {
|
||||
ID string `json:"id"`
|
||||
Sender Sender `json:"sender"`
|
||||
At time.Time `json:"at"`
|
||||
}
|
||||
|
||||
// Code is a code a person typed on a channel, asked as a proof: never in an event, never kept.
|
||||
type Code struct {
|
||||
Sender Sender `json:"sender"`
|
||||
Code string `json:"code"`
|
||||
Purpose string `json:"purpose"`
|
||||
}
|
||||
|
||||
// ProofAnswer is the router's answer to a proof: whether it was taken, and words to say to the person.
|
||||
type ProofAnswer struct {
|
||||
Accepted bool `json:"accepted"`
|
||||
Words string `json:"words"`
|
||||
}
|
||||
-149
@@ -1,149 +0,0 @@
|
||||
package asks
|
||||
|
||||
import (
|
||||
"encoding/json"
|
||||
"errors"
|
||||
"fmt"
|
||||
"reflect"
|
||||
"strings"
|
||||
)
|
||||
|
||||
// ConditionSubject is where a module says a condition to the operator: a by-caller accept of the operator-channel
|
||||
// seat, `mesh.seat.operator-channel.accept.condition.<publisher>` (novox/hq ADR 0437 §9). The router reads the
|
||||
// verb at the fifth part and the caller at the sixth, so the publisher is one token, the module's own name; it is
|
||||
// refused when empty or when it holds a dot, a wildcard or whitespace.
|
||||
func ConditionSubject(publisher string) (string, error) {
|
||||
if publisher == "" {
|
||||
return "", errors.New("asks: the condition's publisher is empty")
|
||||
}
|
||||
if strings.ContainsAny(publisher, ".*> \t\r\n") || strings.ContainsFunc(publisher, func(r rune) bool { return r <= ' ' }) {
|
||||
return "", fmt.Errorf("asks: the condition's publisher %q is not one token: it holds a dot, a wildcard or whitespace", publisher)
|
||||
}
|
||||
return "mesh.seat." + Seat + ".accept.condition." + publisher, nil
|
||||
}
|
||||
|
||||
// ConditionVersion is the version of the condition value this package writes and the only one it reads.
|
||||
const ConditionVersion = 1
|
||||
|
||||
// ErrUnknownConditionVersion is what DecodeCondition returns for a value whose version is missing or not
|
||||
// ConditionVersion. Test it with errors.Is.
|
||||
var ErrUnknownConditionVersion = errors.New("asks: unknown condition version")
|
||||
|
||||
// The words a condition's explanation opens with (novox/hq ADR 0253 §1).
|
||||
const (
|
||||
NothingToDo = "Nothing for you to do."
|
||||
NeedsYou = "Needs you: "
|
||||
)
|
||||
|
||||
// The severities and states of a condition.
|
||||
const (
|
||||
SeverityUrgent = "urgent"
|
||||
SeverityWarning = "warning"
|
||||
StateRaised = "raised"
|
||||
StateCleared = "cleared"
|
||||
)
|
||||
|
||||
// Scope is what a condition is about, under the controller's names.
|
||||
type Scope struct {
|
||||
Scope string `json:"scope"`
|
||||
ID string `json:"id"`
|
||||
Machine string `json:"machine,omitempty"`
|
||||
}
|
||||
|
||||
// Action is one answer a notification offers, under the controller's names.
|
||||
type Action struct {
|
||||
Label string `json:"label"`
|
||||
Verb string `json:"verb"`
|
||||
Machine string `json:"machine,omitempty"`
|
||||
Arguments map[string]string `json:"arguments,omitempty"`
|
||||
Level Level `json:"level,omitempty"`
|
||||
}
|
||||
|
||||
// Condition is a condition a module says to the operator, under the names of the controller's conditions: its key,
|
||||
// severity, subject, state (raised or cleared), summary and the plain words of ADR 0253. A cleared condition needs
|
||||
// only its key, subject and state. The router alone chooses the channels.
|
||||
type Condition struct {
|
||||
V int `json:"v"`
|
||||
Key string `json:"key"`
|
||||
Severity string `json:"severity,omitempty"`
|
||||
Subject Scope `json:"subject"`
|
||||
State string `json:"state"`
|
||||
Summary string `json:"summary,omitempty"`
|
||||
Headline string `json:"headline,omitempty"`
|
||||
Needs string `json:"needs,omitempty"`
|
||||
Explanation string `json:"explanation,omitempty"`
|
||||
Resolved string `json:"resolved,omitempty"`
|
||||
Actions []Action `json:"actions,omitempty"`
|
||||
}
|
||||
|
||||
func (c Condition) check() error {
|
||||
if c.Key == "" {
|
||||
return errors.New("asks: a condition has no key")
|
||||
}
|
||||
if c.Subject.Scope == "" || c.Subject.ID == "" {
|
||||
return errors.New("asks: a condition's subject needs its scope and id")
|
||||
}
|
||||
switch c.State {
|
||||
case StateCleared:
|
||||
return nil
|
||||
case StateRaised:
|
||||
default:
|
||||
return fmt.Errorf("asks: the condition's state %q is not raised or cleared", c.State)
|
||||
}
|
||||
switch c.Severity {
|
||||
case SeverityUrgent, SeverityWarning:
|
||||
default:
|
||||
return fmt.Errorf("asks: the condition's severity %q is not urgent or warning", c.Severity)
|
||||
}
|
||||
if c.Headline == "" {
|
||||
return errors.New("asks: a raised condition has no headline")
|
||||
}
|
||||
if n := len([]rune(c.Headline)); n > HeadlineLength {
|
||||
return fmt.Errorf("asks: the condition's headline is %d characters, more than %d", n, HeadlineLength)
|
||||
}
|
||||
verdict := NothingToDo
|
||||
if c.Needs != "" {
|
||||
verdict = NeedsYou + c.Needs
|
||||
}
|
||||
if !strings.HasPrefix(c.Explanation, verdict) {
|
||||
return fmt.Errorf("asks: the condition's explanation must open with %q", verdict)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// EncodeCondition is c as JSON at ConditionVersion; it refuses what ADR 0253 and ADR 0437 §9 refuse.
|
||||
func EncodeCondition(c Condition) ([]byte, error) {
|
||||
if err := c.check(); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
c.V = ConditionVersion
|
||||
return json.Marshal(c)
|
||||
}
|
||||
|
||||
// DecodeCondition reads a condition; it refuses an unknown version (ErrUnknownConditionVersion) and what
|
||||
// EncodeCondition refuses.
|
||||
func DecodeCondition(data []byte) (Condition, error) {
|
||||
var probe struct {
|
||||
V *int `json:"v"`
|
||||
}
|
||||
if err := json.Unmarshal(data, &probe); err != nil {
|
||||
return Condition{}, fmt.Errorf("asks: the condition is not JSON: %w", err)
|
||||
}
|
||||
if probe.V == nil {
|
||||
return Condition{}, fmt.Errorf("%w: no version in the value, this reader reads %d", ErrUnknownConditionVersion, ConditionVersion)
|
||||
}
|
||||
if *probe.V != ConditionVersion {
|
||||
return Condition{}, fmt.Errorf("%w: the value is version %d, this reader reads %d", ErrUnknownConditionVersion, *probe.V, ConditionVersion)
|
||||
}
|
||||
var c Condition
|
||||
if err := json.Unmarshal(data, &c); err != nil {
|
||||
return Condition{}, fmt.Errorf("asks: the condition does not fit its shape: %w", err)
|
||||
}
|
||||
if err := c.check(); err != nil {
|
||||
return Condition{}, err
|
||||
}
|
||||
return c, nil
|
||||
}
|
||||
|
||||
// SameCondition says whether two conditions are the same value.
|
||||
func SameCondition(a, b Condition) bool { return reflect.DeepEqual(a, b) }
|
||||
Vendored
-41
@@ -1,41 +0,0 @@
|
||||
package delivery
|
||||
|
||||
import "time"
|
||||
|
||||
// BuildRecord is the layout mesh-controller internal/chain/records.go Build writes (line 91), the fields a reader outside
|
||||
// the controller reads (novox/hq ADR 0437 §4 §5, issue 1223). The controller's record carries more; a decode ignores
|
||||
// what is not here. Path is the module's directory in its repository, as the controller writes it (Build.Path, records.go:100,
|
||||
// set from the build request trimmed of slashes at internal/inventory/chain_requests.go:19); empty for a module whose
|
||||
// manifest is the repository's root. SourceInputs has no json keys of its own: it is written under its Go field names, as the controller
|
||||
// writes it.
|
||||
type BuildRecord struct {
|
||||
ID string `json:"id"`
|
||||
State string `json:"state,omitempty"`
|
||||
Repository string `json:"repository"`
|
||||
Ref string `json:"ref,omitempty"`
|
||||
Module string `json:"module,omitempty"`
|
||||
Path string `json:"path,omitempty"`
|
||||
Commit string `json:"commit,omitempty"`
|
||||
At time.Time `json:"at,omitzero"`
|
||||
SourceFingerprint string `json:"source-fingerprint,omitempty"`
|
||||
SourceInputs *SourceInputs `json:"source-inputs,omitempty"`
|
||||
}
|
||||
|
||||
// BuildsBucket is the bucket the builds are kept in: mesh-controller internal/broker/controller_buckets.go:101,
|
||||
// BucketName(ControllerSeat, ChainBuilds), with ControllerSeat "mesh-controller" (internal/broker/streams.go:359) and
|
||||
// ChainBuilds "builds" (controller_buckets.go:113).
|
||||
const BuildsBucket = "mesh-controller_builds"
|
||||
|
||||
// BuildKey is a build's record under its module, a build that knew none under the request's key: copied from
|
||||
// mesh-controller internal/chain/keys.go:35-40 (BuildKey, with RequestKey at line 42).
|
||||
func BuildKey(module, id string) string {
|
||||
if module == "" {
|
||||
return "req." + id
|
||||
}
|
||||
return module + ".build." + id
|
||||
}
|
||||
|
||||
// NewestKey is the key of a module's newest build, of any state: copied from mesh-controller internal/chain/keys.go:44.
|
||||
// The key holds no record: its value is the newest build's id as raw bytes (internal/inventory/chain_builds.go:210 and
|
||||
// :546), and the record lives at BuildKey(module, id). The pointer is a hint, checked against that record.
|
||||
func NewestKey(module string) string { return module + ".newest" }
|
||||
Vendored
-390
@@ -1,390 +0,0 @@
|
||||
// Package delivery is the one home of the keys and values the parts of delivery read and write on the bus
|
||||
// (novox/hq ADR 0429 §2: the key layouts another repository reads live in mesh-sdk; research 063 section 01). The
|
||||
// node-engine writes the have keys, the watchman of the repository mesh-delivery writes presence and pulse, the
|
||||
// view reads all of them, and the controller grants them; every one imports this package, and nothing else defines
|
||||
// these names.
|
||||
//
|
||||
// **Buckets** are named `<owner module>_<name>` as the broker names a module's state (provider.BucketOf): the
|
||||
// node-engine's `have`, and the watchman's `presence` and `pulse`.
|
||||
//
|
||||
// **Keys.** A have key is `<node>.<module>`, and a node's own facts are `<node>.node`, so a module may not be named
|
||||
// `node`. A presence key is `<node>` for a node and `part.<part>.<instance>` for a part's instance, so a node may
|
||||
// not be named `part`. A pulse key is `<bucket>.<key>`: the full name of the bucket watched, then that bucket's key,
|
||||
// which may hold dots, so it splits at the first dot. A name is refused when it is empty or holds a dot, a wildcard,
|
||||
// whitespace or a character a bus key refuses, and the error names it.
|
||||
//
|
||||
// **Values** are JSON of under about 500 bytes, each carrying its version in `v`. A reader refuses a value whose
|
||||
// version is missing or one it does not know, with an error that is ErrUnknownVersion (research 063 section 05
|
||||
// question 9 item 7): a writer writes a new version only once every reader's have shows a version that reads it. A
|
||||
// writer writes only when the new value differs from the one before (the Same functions).
|
||||
//
|
||||
// **Source, candidates, modules and the forge** (issue 1200; ADR 0437 §5, release 3): the gate's bucket `source` with
|
||||
// its one key `main` (every repository's merged head and the group that moved it), the indexer's `candidates.<group>`
|
||||
// and `modules.<module>` (a module's source fingerprint, or none and why), and the forge bridge's messages named
|
||||
// `forge.<owner>.<name>.<kind>` (source.go).
|
||||
//
|
||||
// **Merges, asks, owed and answers** (issue 1201; ADR 0437 §6, §8): the gate's `merges.<group>`, its asks
|
||||
// `merge.<group>.<heads hash>` (the router's ask whole), its owed keys `<repository>.<number>.<head>.<act>` that the
|
||||
// forge bridge performs, and the teller's answer under the ask's own key (gate.go).
|
||||
//
|
||||
// **The source fingerprint** (issue 1203; ADR 0437 §5): one function of named inputs that the controller's builder and
|
||||
// the indexer both call, so they agree byte for byte (fingerprint.go).
|
||||
//
|
||||
// Standard library only, and this module's own asks package.
|
||||
package delivery
|
||||
|
||||
import (
|
||||
"bytes"
|
||||
"encoding/json"
|
||||
"errors"
|
||||
"fmt"
|
||||
"regexp"
|
||||
"strings"
|
||||
"time"
|
||||
)
|
||||
|
||||
// The buckets of delivery's parts. Each is written by one owner: every node's node-engine writes the have keys of
|
||||
// its own node only, and the watchman writes presence and pulse.
|
||||
const (
|
||||
HaveBucket = "node-engine_have"
|
||||
PresenceBucket = WatchmanModule + "_presence"
|
||||
PulseBucket = WatchmanModule + "_pulse"
|
||||
)
|
||||
|
||||
// HaveHistory and PresenceHistory are the revisions the have and presence buckets keep per key (research 063
|
||||
// section 01).
|
||||
const (
|
||||
HaveHistory = 20
|
||||
PresenceHistory = 20
|
||||
)
|
||||
|
||||
// PulseMoveBound is how long a move may take: a pulse key lives for this time minus the move's age, and the bucket
|
||||
// expires it on its own (the server writes a delete marker), so a move that overruns it is seen to stall.
|
||||
const PulseMoveBound = 120 * time.Second
|
||||
|
||||
// Version is the version of every value this package writes and the only one it reads.
|
||||
const Version = 1
|
||||
|
||||
// ErrUnknownVersion is what a decode returns for a value whose version is missing or not Version. Test it with
|
||||
// errors.Is; the message names the version seen and the one read.
|
||||
var ErrUnknownVersion = errors.New("delivery: unknown value version")
|
||||
|
||||
// Phase is how far a module's change has come on a node.
|
||||
type Phase string
|
||||
|
||||
// The phases of a module's change on a node.
|
||||
const (
|
||||
PhaseBackingUp Phase = "backing-up"
|
||||
PhaseApplying Phase = "applying"
|
||||
PhaseChecking Phase = "checking"
|
||||
PhaseRunning Phase = "running"
|
||||
PhaseFailed Phase = "failed"
|
||||
)
|
||||
|
||||
// Health is what the module's own check says.
|
||||
type Health string
|
||||
|
||||
// The healths a have carries.
|
||||
const (
|
||||
HealthOK Health = "ok"
|
||||
HealthFailed Health = "failed"
|
||||
HealthWaits Health = "waits"
|
||||
HealthUnknown Health = "unknown"
|
||||
)
|
||||
|
||||
var nameOK = regexp.MustCompile(`^[-/_=a-zA-Z0-9]+$`)
|
||||
|
||||
// checkName refuses a name that is empty or holds a dot, a wildcard, whitespace or a character a bus key refuses.
|
||||
func checkName(kind, name string) error {
|
||||
if name == "" {
|
||||
return fmt.Errorf("delivery: the %s name is empty", kind)
|
||||
}
|
||||
if !nameOK.MatchString(name) {
|
||||
return fmt.Errorf("delivery: the %s name %q holds a dot, a wildcard, whitespace or a character a key refuses", kind, name)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// HaveKey is the key, in HaveBucket, of a module's have on a node: `<node>.<module>`. A module named `node` is
|
||||
// refused, since `<node>.node` is the node's own facts.
|
||||
func HaveKey(node, module string) (string, error) {
|
||||
if err := checkName("node", node); err != nil {
|
||||
return "", err
|
||||
}
|
||||
if err := checkName("module", module); err != nil {
|
||||
return "", err
|
||||
}
|
||||
if module == "node" {
|
||||
return "", fmt.Errorf(`delivery: the module name "node" is refused: %s.node is the node's own key`, node)
|
||||
}
|
||||
return node + "." + module, nil
|
||||
}
|
||||
|
||||
// HaveNodeKey is the key, in HaveBucket, of a node's own facts: `<node>.node`.
|
||||
func HaveNodeKey(node string) (string, error) {
|
||||
if err := checkName("node", node); err != nil {
|
||||
return "", err
|
||||
}
|
||||
return node + ".node", nil
|
||||
}
|
||||
|
||||
// ParseHaveKey is the inverse of HaveKey and HaveNodeKey: isNode is true for `<node>.node`, with module empty.
|
||||
func ParseHaveKey(key string) (node, module string, isNode bool, err error) {
|
||||
node, module, ok := strings.Cut(key, ".")
|
||||
if !ok {
|
||||
return "", "", false, fmt.Errorf("delivery: %q is not a have key, <node>.<module>", key)
|
||||
}
|
||||
if err := checkName("node", node); err != nil {
|
||||
return "", "", false, fmt.Errorf("delivery: %q is not a have key: %w", key, err)
|
||||
}
|
||||
if err := checkName("module", module); err != nil {
|
||||
return "", "", false, fmt.Errorf("delivery: %q is not a have key: %w", key, err)
|
||||
}
|
||||
if module == "node" {
|
||||
return node, "", true, nil
|
||||
}
|
||||
return node, module, false, nil
|
||||
}
|
||||
|
||||
// PresenceNodeKey is the key, in PresenceBucket, of a node: `<node>`. A node named `part` is refused.
|
||||
func PresenceNodeKey(node string) (string, error) {
|
||||
if err := checkName("node", node); err != nil {
|
||||
return "", err
|
||||
}
|
||||
if node == "part" {
|
||||
return "", errors.New(`delivery: the node name "part" is refused: part.<part>.<instance> is a part's key`)
|
||||
}
|
||||
return node, nil
|
||||
}
|
||||
|
||||
// PresencePartKey is the key, in PresenceBucket, of a part's instance: `part.<part>.<instance>`.
|
||||
func PresencePartKey(part, instance string) (string, error) {
|
||||
if err := checkName("part", part); err != nil {
|
||||
return "", err
|
||||
}
|
||||
if err := checkName("instance", instance); err != nil {
|
||||
return "", err
|
||||
}
|
||||
return "part." + part + "." + instance, nil
|
||||
}
|
||||
|
||||
// ParsePresenceKey is the inverse of PresenceNodeKey and PresencePartKey: for a node's key part and instance are
|
||||
// empty, for a part's key node is.
|
||||
func ParsePresenceKey(key string) (node, part, instance string, err error) {
|
||||
if !strings.Contains(key, ".") {
|
||||
node, err = PresenceNodeKey(key)
|
||||
if err != nil {
|
||||
return "", "", "", fmt.Errorf("delivery: %q is not a presence key: %w", key, err)
|
||||
}
|
||||
return node, "", "", nil
|
||||
}
|
||||
fields := strings.Split(key, ".")
|
||||
if len(fields) != 3 || fields[0] != "part" {
|
||||
return "", "", "", fmt.Errorf("delivery: %q is not a presence key, <node> or part.<part>.<instance>", key)
|
||||
}
|
||||
if _, err := PresencePartKey(fields[1], fields[2]); err != nil {
|
||||
return "", "", "", fmt.Errorf("delivery: %q is not a presence key: %w", key, err)
|
||||
}
|
||||
return "", fields[1], fields[2], nil
|
||||
}
|
||||
|
||||
// PulseKey is the key, in PulseBucket, of the move watched at key of bucket: `<bucket>.<key>`. The bucket is the
|
||||
// full bucket name and holds no dot; the key may.
|
||||
func PulseKey(bucket, key string) (string, error) {
|
||||
if err := checkName("bucket", bucket); err != nil {
|
||||
return "", err
|
||||
}
|
||||
if key == "" || strings.HasPrefix(key, ".") || strings.HasSuffix(key, ".") || strings.Contains(key, "..") {
|
||||
return "", fmt.Errorf("delivery: the pulse key %q is empty or has an empty part", key)
|
||||
}
|
||||
for _, part := range strings.Split(key, ".") {
|
||||
if err := checkName("key", part); err != nil {
|
||||
return "", err
|
||||
}
|
||||
}
|
||||
return bucket + "." + key, nil
|
||||
}
|
||||
|
||||
// ParsePulseKey is the inverse of PulseKey, splitting at the first dot.
|
||||
func ParsePulseKey(pulseKey string) (bucket, key string, err error) {
|
||||
bucket, key, ok := strings.Cut(pulseKey, ".")
|
||||
if !ok {
|
||||
return "", "", fmt.Errorf("delivery: %q is not a pulse key, <bucket>.<key>", pulseKey)
|
||||
}
|
||||
if _, err := PulseKey(bucket, key); err != nil {
|
||||
return "", "", fmt.Errorf("delivery: %q is not a pulse key: %w", pulseKey, err)
|
||||
}
|
||||
return bucket, key, nil
|
||||
}
|
||||
|
||||
// PulseTTL is the time to live of a pulse key for a move of the given age: PulseMoveBound minus the age. At or past
|
||||
// the bound the move is stalled, with no time left and nothing to write: the watchman raises it at once.
|
||||
func PulseTTL(moveAge time.Duration) (ttl time.Duration, stalled bool) {
|
||||
if moveAge >= PulseMoveBound {
|
||||
return 0, true
|
||||
}
|
||||
return PulseMoveBound - moveAge, false
|
||||
}
|
||||
|
||||
// Have is a module's state on a node, written by that node's node-engine under HaveKey. FP is the module's
|
||||
// fingerprint once the indexer exists (design 47 release 3); until then Build is the build the node was sent, and
|
||||
// the view compares by build.
|
||||
type Have struct {
|
||||
V int `json:"v"`
|
||||
FP string `json:"fp,omitempty"`
|
||||
Build string `json:"build,omitempty"`
|
||||
Phase Phase `json:"phase"`
|
||||
Health Health `json:"health"`
|
||||
Detail string `json:"detail,omitempty"`
|
||||
}
|
||||
|
||||
// HaveNode is a node's own facts, written under HaveNodeKey. Each field is the node-engine's own JSON, carried whole:
|
||||
// this package names the facts and does not type them.
|
||||
type HaveNode struct {
|
||||
V int `json:"v"`
|
||||
Windows json.RawMessage `json:"windows,omitempty"`
|
||||
Busy json.RawMessage `json:"busy,omitempty"`
|
||||
Strays json.RawMessage `json:"strays,omitempty"`
|
||||
Filters json.RawMessage `json:"filters,omitempty"`
|
||||
Profile json.RawMessage `json:"profile,omitempty"`
|
||||
}
|
||||
|
||||
// Presence is whether a node or a part's instance is online; the entry's own time says since when. The watchman
|
||||
// writes it.
|
||||
type Presence struct {
|
||||
V int `json:"v"`
|
||||
Online bool `json:"online"`
|
||||
}
|
||||
|
||||
// Pulse is the value of a pulse key: the watched key mirrored, its revision, and who owes the next move (a node or
|
||||
// a part instance). The watchman writes it with the time to live PulseTTL gives.
|
||||
type Pulse struct {
|
||||
V int `json:"v"`
|
||||
Bucket string `json:"bucket"`
|
||||
Key string `json:"key"`
|
||||
Revision uint64 `json:"revision"`
|
||||
Owes string `json:"owes,omitempty"`
|
||||
}
|
||||
|
||||
func checkVersion(data []byte) error {
|
||||
var probe struct {
|
||||
V *int `json:"v"`
|
||||
}
|
||||
if err := json.Unmarshal(data, &probe); err != nil {
|
||||
return fmt.Errorf("delivery: value is not JSON: %w", err)
|
||||
}
|
||||
if probe.V == nil {
|
||||
return fmt.Errorf("%w: no version in the value, this reader reads %d", ErrUnknownVersion, Version)
|
||||
}
|
||||
if *probe.V != Version {
|
||||
return fmt.Errorf("%w: the value is version %d, this reader reads %d", ErrUnknownVersion, *probe.V, Version)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
func decode(data []byte, into any) error {
|
||||
if err := checkVersion(data); err != nil {
|
||||
return err
|
||||
}
|
||||
if err := json.Unmarshal(data, into); err != nil {
|
||||
return fmt.Errorf("delivery: value does not fit its shape: %w", err)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
func (h Have) check() error {
|
||||
switch h.Phase {
|
||||
case PhaseBackingUp, PhaseApplying, PhaseChecking, PhaseRunning, PhaseFailed:
|
||||
default:
|
||||
return fmt.Errorf("delivery: phase %q is not backing-up, applying, checking, running or failed", h.Phase)
|
||||
}
|
||||
switch h.Health {
|
||||
case HealthOK, HealthFailed, HealthWaits, HealthUnknown:
|
||||
default:
|
||||
return fmt.Errorf("delivery: health %q is not ok, failed, waits or unknown", h.Health)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// EncodeHave is h as JSON at Version; it refuses a phase or health outside the lists.
|
||||
func EncodeHave(h Have) ([]byte, error) {
|
||||
if err := h.check(); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
h.V = Version
|
||||
return json.Marshal(h)
|
||||
}
|
||||
|
||||
// DecodeHave reads a have; it refuses an unknown version (ErrUnknownVersion) and a phase or health outside the lists.
|
||||
func DecodeHave(data []byte) (Have, error) {
|
||||
var h Have
|
||||
if err := decode(data, &h); err != nil {
|
||||
return Have{}, err
|
||||
}
|
||||
if err := h.check(); err != nil {
|
||||
return Have{}, err
|
||||
}
|
||||
return h, nil
|
||||
}
|
||||
|
||||
// EncodeHaveNode is n as JSON at Version.
|
||||
func EncodeHaveNode(n HaveNode) ([]byte, error) {
|
||||
n.V = Version
|
||||
return json.Marshal(n)
|
||||
}
|
||||
|
||||
// DecodeHaveNode reads a node's facts; it refuses an unknown version (ErrUnknownVersion).
|
||||
func DecodeHaveNode(data []byte) (HaveNode, error) {
|
||||
var n HaveNode
|
||||
err := decode(data, &n)
|
||||
return n, err
|
||||
}
|
||||
|
||||
// EncodePresence is p as JSON at Version.
|
||||
func EncodePresence(p Presence) ([]byte, error) {
|
||||
p.V = Version
|
||||
return json.Marshal(p)
|
||||
}
|
||||
|
||||
// DecodePresence reads a presence; it refuses an unknown version (ErrUnknownVersion).
|
||||
func DecodePresence(data []byte) (Presence, error) {
|
||||
var p Presence
|
||||
err := decode(data, &p)
|
||||
return p, err
|
||||
}
|
||||
|
||||
// EncodePulse is p as JSON at Version.
|
||||
func EncodePulse(p Pulse) ([]byte, error) {
|
||||
p.V = Version
|
||||
return json.Marshal(p)
|
||||
}
|
||||
|
||||
// DecodePulse reads a pulse; it refuses an unknown version (ErrUnknownVersion).
|
||||
func DecodePulse(data []byte) (Pulse, error) {
|
||||
var p Pulse
|
||||
err := decode(data, &p)
|
||||
return p, err
|
||||
}
|
||||
|
||||
// SameHave says whether two haves are the same value, so a writer writes only when they differ.
|
||||
func SameHave(a, b Have) bool { return a == b }
|
||||
|
||||
// SameHaveNode says whether two node facts are the same value, comparing each carried JSON without its spacing.
|
||||
func SameHaveNode(a, b HaveNode) bool {
|
||||
return a.V == b.V && sameJSON(a.Windows, b.Windows) && sameJSON(a.Busy, b.Busy) &&
|
||||
sameJSON(a.Strays, b.Strays) && sameJSON(a.Filters, b.Filters) && sameJSON(a.Profile, b.Profile)
|
||||
}
|
||||
|
||||
// SamePresence says whether two presences are the same value.
|
||||
func SamePresence(a, b Presence) bool { return a == b }
|
||||
|
||||
// SamePulse says whether two pulses are the same value.
|
||||
func SamePulse(a, b Pulse) bool { return a == b }
|
||||
|
||||
func sameJSON(a, b json.RawMessage) bool {
|
||||
var ca, cb bytes.Buffer
|
||||
if json.Compact(&ca, a) != nil || json.Compact(&cb, b) != nil {
|
||||
return bytes.Equal(a, b)
|
||||
}
|
||||
return bytes.Equal(ca.Bytes(), cb.Bytes())
|
||||
}
|
||||
Vendored
-63
@@ -1,63 +0,0 @@
|
||||
package delivery
|
||||
|
||||
import (
|
||||
"crypto/sha256"
|
||||
"encoding/hex"
|
||||
"sort"
|
||||
"strings"
|
||||
)
|
||||
|
||||
// SourceInputs are what a module's source fingerprint is of (novox/hq ADR 0437 §5): the module, the git tree of
|
||||
// its directory, its bases (references, of which only the digest counts), the root tree of each repository its
|
||||
// artifacts read (by artifact), each artifact's toolchain line, and the reason the source does not pin the build
|
||||
// when it does not (a build that resolves packages when built). A context is the value the builder records for it:
|
||||
// a repository's root tree, or for an image that compiles a Go program the `narrow:` hash of the build source it was
|
||||
// handed (mesh-controller internal/builder/builder.go:1146-1156).
|
||||
type SourceInputs struct {
|
||||
Module string
|
||||
Tree string
|
||||
Bases []string
|
||||
Contexts map[string]string
|
||||
Toolchains map[string]string
|
||||
Unpinned string
|
||||
}
|
||||
|
||||
// SourceFingerprint is the module's source fingerprint, `src1:` and the hex sha256 of its inputs' lines, or none
|
||||
// and the reason when the source does not pin the build: Unpinned when set, "no tree" when Tree is empty. It is the
|
||||
// one function the controller's builder and the indexer both call, so they agree byte for byte. The lines are
|
||||
// "module <m>" and "tree <t>", then "base <digest>" (once each), "context <artifact> <tree>" and "toolchain
|
||||
// <artifact> <line>" sorted, all joined by a newline.
|
||||
func SourceFingerprint(in SourceInputs) (fp, none string) {
|
||||
if in.Unpinned != "" {
|
||||
return "", in.Unpinned
|
||||
}
|
||||
if in.Tree == "" {
|
||||
return "", "no tree"
|
||||
}
|
||||
lines := []string{"module " + in.Module, "tree " + in.Tree}
|
||||
bases := map[string]bool{}
|
||||
for _, b := range in.Bases {
|
||||
bases[ReferenceDigest(b)] = true
|
||||
}
|
||||
for b := range bases {
|
||||
lines = append(lines, "base "+b)
|
||||
}
|
||||
for a, t := range in.Contexts {
|
||||
lines = append(lines, "context "+a+" "+t)
|
||||
}
|
||||
for a, t := range in.Toolchains {
|
||||
lines = append(lines, "toolchain "+a+" "+t)
|
||||
}
|
||||
sort.Strings(lines[2:])
|
||||
sum := sha256.Sum256([]byte(strings.Join(lines, "\n")))
|
||||
return SourcePrefix + hex.EncodeToString(sum[:]), ""
|
||||
}
|
||||
|
||||
// ReferenceDigest is a reference's digest, `sha256:...`, so the registry address a base was copied into does not
|
||||
// enter the fingerprint; the reference itself when it carries none.
|
||||
func ReferenceDigest(reference string) string {
|
||||
if _, digest, pinned := strings.Cut(reference, "@"); pinned && digest != "" {
|
||||
return digest
|
||||
}
|
||||
return reference
|
||||
}
|
||||
-404
@@ -1,404 +0,0 @@
|
||||
package delivery
|
||||
|
||||
import (
|
||||
"crypto/sha256"
|
||||
"encoding/hex"
|
||||
"encoding/json"
|
||||
"fmt"
|
||||
"reflect"
|
||||
"regexp"
|
||||
"strconv"
|
||||
"strings"
|
||||
|
||||
"git.novox.be/novox/mesh-sdk/go/asks"
|
||||
)
|
||||
|
||||
// The gate's buckets and the teller's (ADR 0437 §6, §8). The gate writes merges (each pull request's expected
|
||||
// head, its state and each merge commit), its asks (`merge.<group>.<heads hash>`, the router's ask whole) and owed
|
||||
// (one key per act it owes the forge, which the forge bridge performs once per revision). The teller writes its
|
||||
// answer under the ask's own key in its bucket answers.
|
||||
const (
|
||||
MergesBucket = GateModule + "_merges"
|
||||
AsksBucket = GateModule + "_asks"
|
||||
OwedBucket = GateModule + "_owed"
|
||||
AnswersBucket = TellerModule + "_answers"
|
||||
MergesHistory = 10
|
||||
AsksHistory = 5
|
||||
OwedHistory = 5
|
||||
AnswersHistory = 5
|
||||
)
|
||||
|
||||
// AskKindMerge is the kind of the gate's ask for a group's merge, the first part of its key.
|
||||
const AskKindMerge = "merge"
|
||||
|
||||
// The acts the gate owes the forge, the last part of an owed key.
|
||||
const (
|
||||
OwedStatus = "status"
|
||||
OwedView = "view"
|
||||
OwedNote = "note"
|
||||
OwedComment = "comment"
|
||||
)
|
||||
|
||||
// The states of a pull request in a merge.
|
||||
type MergeState string
|
||||
|
||||
// The states a merge's pull request is in.
|
||||
const (
|
||||
MergeMerging MergeState = "merging"
|
||||
MergeMerged MergeState = "merged"
|
||||
MergeRefused MergeState = "refused"
|
||||
)
|
||||
|
||||
// The states a status the gate owes the forge may carry.
|
||||
var statusStates = []string{"pending", "success", "failure", "error", "warning"}
|
||||
|
||||
var hashOK = regexp.MustCompile(`^[0-9a-f]{12}$`)
|
||||
|
||||
// MergesKey is the key, in MergesBucket, of a group: `<group>`.
|
||||
func MergesKey(group string) (string, error) {
|
||||
if err := checkName("group", group); err != nil {
|
||||
return "", err
|
||||
}
|
||||
return group, nil
|
||||
}
|
||||
|
||||
// MergeAskKey is the key, in AsksBucket, of the ask for merging a group at these heads: `merge.<group>.<heads
|
||||
// hash>`. The teller's answer has the same key in AnswersBucket (AnswerKey).
|
||||
func MergeAskKey(group string, heads []Head) (string, error) {
|
||||
if err := checkName("group", group); err != nil {
|
||||
return "", err
|
||||
}
|
||||
hash, err := HeadsHash(heads)
|
||||
if err != nil {
|
||||
return "", err
|
||||
}
|
||||
return AskKindMerge + "." + group + "." + hash, nil
|
||||
}
|
||||
|
||||
// ParseAskKey is the inverse of MergeAskKey: the kind, the group and the heads hash.
|
||||
func ParseAskKey(key string) (kind, group, hash string, err error) {
|
||||
parts := strings.Split(key, ".")
|
||||
if len(parts) != 3 || parts[0] != AskKindMerge {
|
||||
return "", "", "", fmt.Errorf("delivery: %q is not an ask key, merge.<group>.<heads hash>", key)
|
||||
}
|
||||
if err := checkName("group", parts[1]); err != nil {
|
||||
return "", "", "", fmt.Errorf("delivery: %q is not an ask key: %w", key, err)
|
||||
}
|
||||
if !hashOK.MatchString(parts[2]) {
|
||||
return "", "", "", fmt.Errorf("delivery: %q is not an ask key: %q is not 12 hex digits", key, parts[2])
|
||||
}
|
||||
return parts[0], parts[1], parts[2], nil
|
||||
}
|
||||
|
||||
// AnswerKey is the key, in AnswersBucket, of the teller's answer to the ask at askKey: the same string.
|
||||
func AnswerKey(askKey string) string { return askKey }
|
||||
|
||||
// AskID is the id the teller gives the router for the ask at askKey. The router's ids refuse dots (asks.UsableID),
|
||||
// so in the readable part a dot becomes `-` and any other byte outside letters, digits, `_` and `-` becomes `_`; that part is cut to fit, and every id ends in `-` and
|
||||
// the first 12 hex digits of the sha256 of the whole key, so two keys never give one id. It cannot be read back:
|
||||
// the teller keeps the key beside it.
|
||||
func AskID(askKey string) string {
|
||||
const most = 64 // the router's bound on an id
|
||||
const tail = 13 // "-" and 12 hex digits
|
||||
readable := []byte(askKey)
|
||||
for i, c := range readable {
|
||||
switch {
|
||||
case c >= 'A' && c <= 'Z', c >= 'a' && c <= 'z', c >= '0' && c <= '9':
|
||||
case c == '.':
|
||||
readable[i] = '-'
|
||||
default: // a slash, an equals sign or any other byte the router's id refuses
|
||||
readable[i] = '_'
|
||||
}
|
||||
}
|
||||
if len(readable) > 0 && (readable[0] == '-' || readable[0] == '_') {
|
||||
readable[0] = 'k' // an id starts with a letter or digit
|
||||
}
|
||||
if len(readable) > most-tail {
|
||||
readable = readable[:most-tail]
|
||||
}
|
||||
sum := sha256.Sum256([]byte(askKey))
|
||||
return string(readable) + "-" + hex.EncodeToString(sum[:])[:12]
|
||||
}
|
||||
|
||||
func checkOwedAct(act string) (kind, context string, err error) {
|
||||
kind, context, hasContext := strings.Cut(act, "=")
|
||||
switch kind {
|
||||
case OwedStatus:
|
||||
if !hasContext {
|
||||
return "", "", fmt.Errorf("delivery: the owed act %q is a status without its context, status=<context>", act)
|
||||
}
|
||||
if err := checkName("status context", context); err != nil {
|
||||
return "", "", err
|
||||
}
|
||||
return kind, context, nil
|
||||
case OwedView, OwedNote, OwedComment:
|
||||
if hasContext {
|
||||
return "", "", fmt.Errorf("delivery: the owed act %q takes no context", act)
|
||||
}
|
||||
return kind, "", nil
|
||||
}
|
||||
return "", "", fmt.Errorf("delivery: the owed act %q is not status=<context>, view, note or comment", act)
|
||||
}
|
||||
|
||||
// ParseOwedAct splits an owed act into its kind and, for a status, its context.
|
||||
func ParseOwedAct(act string) (kind, context string, err error) { return checkOwedAct(act) }
|
||||
|
||||
// OwedKey is the key, in OwedBucket, of an act the gate owes the forge on a pull request at a head:
|
||||
// `<repository>.<number>.<head>.<act>`, the act being `status=<context>` (mesh/merge-gate), `view`, `note` or
|
||||
// `comment`.
|
||||
func OwedKey(repository string, number int, head, act string) (string, error) {
|
||||
if err := checkRepository(repository); err != nil {
|
||||
return "", err
|
||||
}
|
||||
if number <= 0 {
|
||||
return "", fmt.Errorf("delivery: an owed key needs the pull request number, not %d", number)
|
||||
}
|
||||
if err := checkName("head", head); err != nil {
|
||||
return "", err
|
||||
}
|
||||
if _, _, err := checkOwedAct(act); err != nil {
|
||||
return "", err
|
||||
}
|
||||
return repository + "." + strconv.Itoa(number) + "." + head + "." + act, nil
|
||||
}
|
||||
|
||||
// ParseOwedKey is the inverse of OwedKey; act is whole, as `status=<context>` for a status.
|
||||
func ParseOwedKey(key string) (repository string, number int, head, act string, err error) {
|
||||
parts := strings.Split(key, ".")
|
||||
if len(parts) != 4 {
|
||||
return "", 0, "", "", fmt.Errorf("delivery: %q is not an owed key, <repository>.<number>.<head>.<act>", key)
|
||||
}
|
||||
number, convErr := strconv.Atoi(parts[1])
|
||||
if convErr != nil {
|
||||
return "", 0, "", "", fmt.Errorf("delivery: %q is not an owed key: %q is not a pull request number", key, parts[1])
|
||||
}
|
||||
if _, err := OwedKey(parts[0], number, parts[2], parts[3]); err != nil {
|
||||
return "", 0, "", "", fmt.Errorf("delivery: %q is not an owed key: %w", key, err)
|
||||
}
|
||||
return parts[0], number, parts[2], parts[3], nil
|
||||
}
|
||||
|
||||
// Merge is the value of a merges key: the ask approved and, for each pull request, the head the approval expects
|
||||
// and how far its merge has come.
|
||||
type Merge struct {
|
||||
V int `json:"v"`
|
||||
Group string `json:"group"`
|
||||
Ask string `json:"ask"`
|
||||
Pulls []MergePull `json:"pulls"`
|
||||
}
|
||||
|
||||
// MergePull is one pull request of a merge: its expected head, its state, the merge commit once merged, the
|
||||
// forge's words when refused.
|
||||
type MergePull struct {
|
||||
Head
|
||||
State MergeState `json:"state"`
|
||||
Commit string `json:"commit,omitempty"`
|
||||
Words string `json:"words,omitempty"`
|
||||
}
|
||||
|
||||
func (m Merge) check() error {
|
||||
if err := checkName("group", m.Group); err != nil {
|
||||
return err
|
||||
}
|
||||
if m.Ask == "" {
|
||||
return fmt.Errorf("delivery: a merge names no ask")
|
||||
}
|
||||
if len(m.Pulls) == 0 {
|
||||
return fmt.Errorf("delivery: a merge names no pull request")
|
||||
}
|
||||
for _, p := range m.Pulls {
|
||||
who := fmt.Sprintf("%s#%d", p.Repository, p.Number)
|
||||
switch p.State {
|
||||
case MergeMerging:
|
||||
case MergeMerged:
|
||||
if p.Commit == "" {
|
||||
return fmt.Errorf("delivery: the merged pull request %s has no merge commit", who)
|
||||
}
|
||||
case MergeRefused:
|
||||
if p.Words == "" {
|
||||
return fmt.Errorf("delivery: the refused pull request %s has no words of the forge", who)
|
||||
}
|
||||
default:
|
||||
return fmt.Errorf("delivery: the state %q of %s is not merging, merged or refused", p.State, who)
|
||||
}
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// Ask is the value of an asks key: the router's ask whole as the gate composes it, so the teller publishes it
|
||||
// unchanged, and the group and heads it was composed for.
|
||||
type Ask struct {
|
||||
V int `json:"v"`
|
||||
Group string `json:"group"`
|
||||
Heads []Head `json:"heads"`
|
||||
Ask asks.Ask `json:"ask"`
|
||||
}
|
||||
|
||||
func (a Ask) check() error {
|
||||
key, err := MergeAskKey(a.Group, a.Heads)
|
||||
if err != nil {
|
||||
return fmt.Errorf("delivery: an ask needs its group and at least one pull request's head: %w", err)
|
||||
}
|
||||
if want := AskID(key); a.Ask.ID != want {
|
||||
return fmt.Errorf("delivery: the ask's id %q is not %q, the id its group and heads give", a.Ask.ID, want)
|
||||
}
|
||||
if len(a.Ask.Options) == 0 {
|
||||
return fmt.Errorf("delivery: the ask has no option")
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// Answer is the teller's answer to an ask: the option chosen, the warrant's id and its words.
|
||||
type Answer struct {
|
||||
V int `json:"v"`
|
||||
Option string `json:"option"`
|
||||
Warrant string `json:"warrant"`
|
||||
Words string `json:"words"`
|
||||
}
|
||||
|
||||
func (a Answer) check() error {
|
||||
for _, f := range []struct{ name, value string }{{"option", a.Option}, {"warrant", a.Warrant}, {"words", a.Words}} {
|
||||
if f.value == "" {
|
||||
return fmt.Errorf("delivery: an answer has no %s", f.name)
|
||||
}
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// Owed is the value of an owed key: what the forge bridge performs. A status needs Context and State, a view and a
|
||||
// comment need Text, a note needs Text and Ref (the notes ref, mesh-plan).
|
||||
type Owed struct {
|
||||
V int `json:"v"`
|
||||
Act string `json:"act"`
|
||||
Context string `json:"context,omitempty"`
|
||||
State string `json:"state,omitempty"`
|
||||
Text string `json:"text,omitempty"`
|
||||
Ref string `json:"ref,omitempty"`
|
||||
}
|
||||
|
||||
func (o Owed) check() error {
|
||||
switch o.Act {
|
||||
case OwedStatus:
|
||||
if o.Context == "" {
|
||||
return fmt.Errorf("delivery: an owed status has no context")
|
||||
}
|
||||
for _, s := range statusStates {
|
||||
if o.State == s {
|
||||
return nil
|
||||
}
|
||||
}
|
||||
return fmt.Errorf("delivery: the owed status state %q is not %s", o.State, strings.Join(statusStates, ", "))
|
||||
case OwedView, OwedComment:
|
||||
if o.Text == "" {
|
||||
return fmt.Errorf("delivery: an owed %s has no text", o.Act)
|
||||
}
|
||||
case OwedNote:
|
||||
if o.Text == "" {
|
||||
return fmt.Errorf("delivery: an owed note has no text")
|
||||
}
|
||||
if o.Ref == "" {
|
||||
return fmt.Errorf("delivery: an owed note has no ref")
|
||||
}
|
||||
default:
|
||||
return fmt.Errorf("delivery: the owed act %q is not status, view, note or comment", o.Act)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// EncodeMerge is m as JSON at Version; it refuses a merged pull request without its merge commit, a refused one
|
||||
// without the forge's words and a state outside the list.
|
||||
func EncodeMerge(m Merge) ([]byte, error) {
|
||||
if err := m.check(); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
m.V = Version
|
||||
return json.Marshal(m)
|
||||
}
|
||||
|
||||
// DecodeMerge reads a merge; it refuses an unknown version (ErrUnknownVersion) and what EncodeMerge refuses.
|
||||
func DecodeMerge(data []byte) (Merge, error) {
|
||||
var m Merge
|
||||
if err := decode(data, &m); err != nil {
|
||||
return Merge{}, err
|
||||
}
|
||||
if err := m.check(); err != nil {
|
||||
return Merge{}, err
|
||||
}
|
||||
return m, nil
|
||||
}
|
||||
|
||||
// EncodeAsk is a as JSON at Version; it refuses an ask whose id is not the one its group and heads give, or with
|
||||
// no option.
|
||||
func EncodeAsk(a Ask) ([]byte, error) {
|
||||
if err := a.check(); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
a.V = Version
|
||||
return json.Marshal(a)
|
||||
}
|
||||
|
||||
// DecodeAsk reads an ask; it refuses an unknown version (ErrUnknownVersion) and what EncodeAsk refuses.
|
||||
func DecodeAsk(data []byte) (Ask, error) {
|
||||
var a Ask
|
||||
if err := decode(data, &a); err != nil {
|
||||
return Ask{}, err
|
||||
}
|
||||
if err := a.check(); err != nil {
|
||||
return Ask{}, err
|
||||
}
|
||||
return a, nil
|
||||
}
|
||||
|
||||
// EncodeAnswer is a as JSON at Version; it refuses an answer missing its option, warrant or words.
|
||||
func EncodeAnswer(a Answer) ([]byte, error) {
|
||||
if err := a.check(); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
a.V = Version
|
||||
return json.Marshal(a)
|
||||
}
|
||||
|
||||
// DecodeAnswer reads an answer; it refuses an unknown version (ErrUnknownVersion) and what EncodeAnswer refuses.
|
||||
func DecodeAnswer(data []byte) (Answer, error) {
|
||||
var a Answer
|
||||
if err := decode(data, &a); err != nil {
|
||||
return Answer{}, err
|
||||
}
|
||||
if err := a.check(); err != nil {
|
||||
return Answer{}, err
|
||||
}
|
||||
return a, nil
|
||||
}
|
||||
|
||||
// EncodeOwed is o as JSON at Version; it refuses an act missing what it needs.
|
||||
func EncodeOwed(o Owed) ([]byte, error) {
|
||||
if err := o.check(); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
o.V = Version
|
||||
return json.Marshal(o)
|
||||
}
|
||||
|
||||
// DecodeOwed reads an owed act; it refuses an unknown version (ErrUnknownVersion) and what EncodeOwed refuses.
|
||||
func DecodeOwed(data []byte) (Owed, error) {
|
||||
var o Owed
|
||||
if err := decode(data, &o); err != nil {
|
||||
return Owed{}, err
|
||||
}
|
||||
if err := o.check(); err != nil {
|
||||
return Owed{}, err
|
||||
}
|
||||
return o, nil
|
||||
}
|
||||
|
||||
// SameMerge says whether two merges are the same value, so a writer writes only when they differ.
|
||||
func SameMerge(a, b Merge) bool { return reflect.DeepEqual(a, b) }
|
||||
|
||||
// SameAsk says whether two asks are the same value.
|
||||
func SameAsk(a, b Ask) bool { return reflect.DeepEqual(a, b) }
|
||||
|
||||
// SameAnswer says whether two answers are the same value.
|
||||
func SameAnswer(a, b Answer) bool { return a == b }
|
||||
|
||||
// SameOwed says whether two owed acts are the same value.
|
||||
func SameOwed(a, b Owed) bool { return a == b }
|
||||
Vendored
-420
@@ -1,420 +0,0 @@
|
||||
package delivery
|
||||
|
||||
import (
|
||||
"crypto/sha256"
|
||||
"encoding/hex"
|
||||
"encoding/json"
|
||||
"fmt"
|
||||
"reflect"
|
||||
"sort"
|
||||
"strings"
|
||||
)
|
||||
|
||||
// The modules of the parts release 3 adds (novox/hq ADR 0437): their buckets are their own state, `<module>_<name>`.
|
||||
const (
|
||||
GateModule = "mesh-delivery-gate"
|
||||
IndexerModule = "mesh-delivery-indexer"
|
||||
ForgeBridgeModule = "mesh-delivery-forge-bridge"
|
||||
TellerModule = "mesh-delivery-teller"
|
||||
)
|
||||
|
||||
// The gate's source bucket and the indexer's candidates and modules buckets (ADR 0437 §5). The source bucket has
|
||||
// one key, SourceMainKey: every repository's merged head and the group that moved it, written by the gate alone by
|
||||
// compare-and-set; its revision is the mesh's source revision. The indexer writes the other two.
|
||||
const (
|
||||
SourceBucket = GateModule + "_source"
|
||||
SourceMainKey = "main"
|
||||
SourceHistory = 64
|
||||
CandidatesBucket = IndexerModule + "_candidates"
|
||||
// CandidatesHistory is the revisions the candidates bucket keeps per key.
|
||||
CandidatesHistory = 10
|
||||
ModulesBucket = IndexerModule + "_modules"
|
||||
// ModulesHistory is the revisions the modules bucket keeps per key.
|
||||
ModulesHistory = 20
|
||||
)
|
||||
|
||||
// ForgeStream is the forge bridge's stream as its manifest declares it; the broker derives the real names.
|
||||
const ForgeStream = "forge"
|
||||
|
||||
// The kinds of forge message, the last part of a forge event's name.
|
||||
const (
|
||||
ForgePull = "pull"
|
||||
ForgeMerged = "merged"
|
||||
ForgeRefused = "refused"
|
||||
)
|
||||
|
||||
// The actions of a pull message.
|
||||
const (
|
||||
PullOpened = "opened"
|
||||
PullUpdated = "updated"
|
||||
PullClosed = "closed"
|
||||
)
|
||||
|
||||
// SourcePrefix opens every source fingerprint.
|
||||
const SourcePrefix = "src1:"
|
||||
|
||||
// CandidatesKey is the key, in CandidatesBucket, of a group: `<group>`, the branch name the group's pull requests
|
||||
// share (a slash is allowed); a lone pull request is a group of one under its branch name.
|
||||
func CandidatesKey(group string) (string, error) {
|
||||
if err := checkName("group", group); err != nil {
|
||||
return "", err
|
||||
}
|
||||
return group, nil
|
||||
}
|
||||
|
||||
// ParseCandidatesKey is the inverse of CandidatesKey.
|
||||
func ParseCandidatesKey(key string) (group string, err error) {
|
||||
if group, err = CandidatesKey(key); err != nil {
|
||||
return "", fmt.Errorf("delivery: %q is not a candidates key: %w", key, err)
|
||||
}
|
||||
return group, nil
|
||||
}
|
||||
|
||||
// ModulesKey is the key, in ModulesBucket, of a module: `<module>`.
|
||||
func ModulesKey(module string) (string, error) {
|
||||
if err := checkName("module", module); err != nil {
|
||||
return "", err
|
||||
}
|
||||
return module, nil
|
||||
}
|
||||
|
||||
// ParseModulesKey is the inverse of ModulesKey.
|
||||
func ParseModulesKey(key string) (module string, err error) {
|
||||
if module, err = ModulesKey(key); err != nil {
|
||||
return "", fmt.Errorf("delivery: %q is not a modules key: %w", key, err)
|
||||
}
|
||||
return module, nil
|
||||
}
|
||||
|
||||
// checkRepository refuses a repository that is not `<owner>/<name>`: exactly one slash, each part a valid name.
|
||||
func checkRepository(repository string) error {
|
||||
owner, name, ok := strings.Cut(repository, "/")
|
||||
if !ok || strings.Contains(name, "/") {
|
||||
return fmt.Errorf("delivery: the repository %q is not <owner>/<name>, with exactly one slash", repository)
|
||||
}
|
||||
if err := checkName("repository owner", owner); err != nil {
|
||||
return fmt.Errorf("delivery: the repository %q: %w", repository, err)
|
||||
}
|
||||
if err := checkName("repository name", name); err != nil {
|
||||
return fmt.Errorf("delivery: the repository %q: %w", repository, err)
|
||||
}
|
||||
if strings.Contains(owner, "/") {
|
||||
return fmt.Errorf("delivery: the repository %q is not <owner>/<name>, with exactly one slash", repository)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
func checkForgeKind(kind string) error {
|
||||
switch kind {
|
||||
case ForgePull, ForgeMerged, ForgeRefused:
|
||||
return nil
|
||||
}
|
||||
return fmt.Errorf("delivery: the forge kind %q is not pull, merged or refused", kind)
|
||||
}
|
||||
|
||||
// ForgeEvent is the name of a forge message of the given kind: `forge.<owner>.<name>.<kind>`.
|
||||
func ForgeEvent(repository, kind string) (string, error) {
|
||||
if err := checkRepository(repository); err != nil {
|
||||
return "", err
|
||||
}
|
||||
if err := checkForgeKind(kind); err != nil {
|
||||
return "", err
|
||||
}
|
||||
owner, name, _ := strings.Cut(repository, "/")
|
||||
return "forge." + owner + "." + name + "." + kind, nil
|
||||
}
|
||||
|
||||
// ParseForgeEvent is the inverse of ForgeEvent.
|
||||
func ParseForgeEvent(event string) (repository, kind string, err error) {
|
||||
parts := strings.Split(event, ".")
|
||||
if len(parts) != 4 || parts[0] != "forge" {
|
||||
return "", "", fmt.Errorf("delivery: %q is not a forge event, forge.<owner>.<name>.<kind>", event)
|
||||
}
|
||||
repository = parts[1] + "/" + parts[2]
|
||||
if _, err := ForgeEvent(repository, parts[3]); err != nil {
|
||||
return "", "", fmt.Errorf("delivery: %q is not a forge event: %w", event, err)
|
||||
}
|
||||
return repository, parts[3], nil
|
||||
}
|
||||
|
||||
// Head is one pull request at one commit: the repository as `<owner>/<name>` and the full sha.
|
||||
type Head struct {
|
||||
Repository string `json:"repository"`
|
||||
Number int `json:"number"`
|
||||
Head string `json:"head"`
|
||||
}
|
||||
|
||||
// HeadsHash is the first 12 hex digits of the sha256 over the lines `<repository>#<number>=<head>`, sorted and
|
||||
// joined by a newline: the same for every order of heads, different when any head changes. An empty list is refused.
|
||||
func HeadsHash(heads []Head) (string, error) {
|
||||
if len(heads) == 0 {
|
||||
return "", fmt.Errorf("delivery: a heads hash needs at least one pull request")
|
||||
}
|
||||
lines := make([]string, len(heads))
|
||||
for i, h := range heads {
|
||||
lines[i] = fmt.Sprintf("%s#%d=%s", h.Repository, h.Number, h.Head)
|
||||
}
|
||||
sort.Strings(lines)
|
||||
sum := sha256.Sum256([]byte(strings.Join(lines, "\n")))
|
||||
return hex.EncodeToString(sum[:])[:12], nil
|
||||
}
|
||||
|
||||
// Source is the value of SourceMainKey: every repository's merged head (repository to full sha, not only the
|
||||
// group's) and the group that moved it.
|
||||
type Source struct {
|
||||
V int `json:"v"`
|
||||
Group string `json:"group"`
|
||||
Heads map[string]string `json:"heads"`
|
||||
}
|
||||
|
||||
func (s Source) check() error {
|
||||
if len(s.Heads) == 0 {
|
||||
return fmt.Errorf("delivery: a source names no repository")
|
||||
}
|
||||
for repository, head := range s.Heads {
|
||||
if repository == "" {
|
||||
return fmt.Errorf("delivery: a source names a repository with no name")
|
||||
}
|
||||
if head == "" {
|
||||
return fmt.Errorf("delivery: the source's head of %s is empty", repository)
|
||||
}
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// Candidate is the value of a candidates key: the group's pull requests and heads, the heads hash, the base (the
|
||||
// source revision it was previewed onto) and the modules each pull request touches. It carries no fingerprint
|
||||
// until release 4 (ADR 0437 §5).
|
||||
type Candidate struct {
|
||||
V int `json:"v"`
|
||||
Group string `json:"group"`
|
||||
Base uint64 `json:"base"`
|
||||
HeadsHash string `json:"heads"`
|
||||
Pulls []CandidatePull `json:"pulls"`
|
||||
}
|
||||
|
||||
// CandidatePull is one pull request of a candidate and the modules it touches.
|
||||
type CandidatePull struct {
|
||||
Head
|
||||
Modules []string `json:"modules"`
|
||||
}
|
||||
|
||||
func (c Candidate) check() error {
|
||||
if len(c.Pulls) == 0 {
|
||||
return fmt.Errorf("delivery: a candidate names no pull request")
|
||||
}
|
||||
heads := make([]Head, len(c.Pulls))
|
||||
for i, p := range c.Pulls {
|
||||
heads[i] = p.Head
|
||||
}
|
||||
want, _ := HeadsHash(heads)
|
||||
if c.HeadsHash != want {
|
||||
return fmt.Errorf("delivery: the candidate's heads hash %q is not the hash %q of its pull requests' heads", c.HeadsHash, want)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// Module is the value of a modules key: the module's source fingerprint, or none and why (a build that resolves
|
||||
// packages when built gets none, said here), and where it was computed: Repository and Commit are the trunk merge,
|
||||
// Src the source revision then (0 before the gate writes source.main). Exactly one of FP and None is set.
|
||||
type Module struct {
|
||||
V int `json:"v"`
|
||||
FP string `json:"fp,omitempty"`
|
||||
None string `json:"none,omitempty"`
|
||||
Src uint64 `json:"src,omitempty"`
|
||||
Repository string `json:"repository"`
|
||||
Commit string `json:"commit"`
|
||||
}
|
||||
|
||||
func (m Module) check() error {
|
||||
switch {
|
||||
case m.FP != "" && m.None != "":
|
||||
return fmt.Errorf("delivery: a module has both a fingerprint and a reason for none")
|
||||
case m.FP == "" && m.None == "":
|
||||
return fmt.Errorf("delivery: a module has neither a fingerprint nor a reason for none")
|
||||
case m.FP != "" && !strings.HasPrefix(m.FP, SourcePrefix):
|
||||
return fmt.Errorf("delivery: the module's fingerprint %q does not start with %s", m.FP, SourcePrefix)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// Forge is a message of the forge bridge's stream, trimmed to repository, branch, pull request and head. A pull
|
||||
// message says Action; a merged message carries the merge commit, the tree of every directory holding a
|
||||
// module.json and the repository's root tree; a refused message names the owed act it answers and the forge's own
|
||||
// words. A pull message may also carry the module directories its head changes (Dirs, in the order the forge said) and
|
||||
// DirsKnown, true when the forge could say them: known and empty is DirsKnown with no Dirs, not known is neither
|
||||
// (the forge's module_dirs and module_dirs_said, mesh-catalog modules/gitea/trunk.ts). Other messages carry neither.
|
||||
type Forge struct {
|
||||
V int `json:"v"`
|
||||
Kind string `json:"kind"`
|
||||
Repository string `json:"repository"`
|
||||
Branch string `json:"branch,omitempty"`
|
||||
Number int `json:"number,omitempty"`
|
||||
Head string `json:"head,omitempty"`
|
||||
Action string `json:"action,omitempty"`
|
||||
Dirs []string `json:"dirs,omitempty"`
|
||||
DirsKnown bool `json:"dirs-known,omitempty"`
|
||||
Merge string `json:"merge,omitempty"`
|
||||
Trees map[string]string `json:"trees,omitempty"`
|
||||
Root string `json:"root,omitempty"`
|
||||
Act string `json:"act,omitempty"`
|
||||
Words string `json:"words,omitempty"`
|
||||
}
|
||||
|
||||
func (f Forge) check() error {
|
||||
if err := checkRepository(f.Repository); err != nil {
|
||||
return err
|
||||
}
|
||||
if err := checkForgeKind(f.Kind); err != nil {
|
||||
return err
|
||||
}
|
||||
switch f.Kind {
|
||||
case ForgePull:
|
||||
if f.Number <= 0 {
|
||||
return fmt.Errorf("delivery: a pull message needs its pull request number")
|
||||
}
|
||||
if f.Head == "" {
|
||||
return fmt.Errorf("delivery: a pull message needs its head")
|
||||
}
|
||||
switch f.Action {
|
||||
case PullOpened, PullUpdated, PullClosed:
|
||||
default:
|
||||
return fmt.Errorf("delivery: the pull action %q is not opened, updated or closed", f.Action)
|
||||
}
|
||||
if len(f.Dirs) > 0 && !f.DirsKnown {
|
||||
return fmt.Errorf("delivery: a pull message with module directories must say it knows them (dirs-known)")
|
||||
}
|
||||
case ForgeMerged:
|
||||
if len(f.Dirs) > 0 || f.DirsKnown {
|
||||
return fmt.Errorf("delivery: a merged message carries no module directories")
|
||||
}
|
||||
if f.Number <= 0 {
|
||||
return fmt.Errorf("delivery: a merged message needs its pull request number")
|
||||
}
|
||||
if f.Head == "" {
|
||||
return fmt.Errorf("delivery: a merged message needs its head")
|
||||
}
|
||||
if f.Merge == "" {
|
||||
return fmt.Errorf("delivery: a merged message needs its merge commit")
|
||||
}
|
||||
if f.Root == "" {
|
||||
return fmt.Errorf("delivery: a merged message needs the repository's root tree")
|
||||
}
|
||||
if len(f.Trees) == 0 {
|
||||
return fmt.Errorf("delivery: a merged message needs the tree of at least one directory holding a module.json")
|
||||
}
|
||||
for dir, tree := range f.Trees {
|
||||
if tree == "" {
|
||||
return fmt.Errorf("delivery: a merged message's tree of the directory %q is empty", dir)
|
||||
}
|
||||
}
|
||||
case ForgeRefused:
|
||||
if len(f.Dirs) > 0 || f.DirsKnown {
|
||||
return fmt.Errorf("delivery: a refused message carries no module directories")
|
||||
}
|
||||
if f.Act == "" {
|
||||
return fmt.Errorf("delivery: a refused message needs the act it answers")
|
||||
}
|
||||
if f.Words == "" {
|
||||
return fmt.Errorf("delivery: a refused message needs the forge's words")
|
||||
}
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// EncodeSource is s as JSON at Version; it refuses a source with no repository or an empty head.
|
||||
func EncodeSource(s Source) ([]byte, error) {
|
||||
if err := s.check(); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
s.V = Version
|
||||
return json.Marshal(s)
|
||||
}
|
||||
|
||||
// DecodeSource reads a source; it refuses an unknown version (ErrUnknownVersion) and what EncodeSource refuses.
|
||||
func DecodeSource(data []byte) (Source, error) {
|
||||
var s Source
|
||||
if err := decode(data, &s); err != nil {
|
||||
return Source{}, err
|
||||
}
|
||||
if err := s.check(); err != nil {
|
||||
return Source{}, err
|
||||
}
|
||||
return s, nil
|
||||
}
|
||||
|
||||
// EncodeCandidate is c as JSON at Version; it refuses a heads hash that is not the hash of its pull requests' heads.
|
||||
func EncodeCandidate(c Candidate) ([]byte, error) {
|
||||
if err := c.check(); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
c.V = Version
|
||||
return json.Marshal(c)
|
||||
}
|
||||
|
||||
// DecodeCandidate reads a candidate; it refuses an unknown version (ErrUnknownVersion) and what EncodeCandidate refuses.
|
||||
func DecodeCandidate(data []byte) (Candidate, error) {
|
||||
var c Candidate
|
||||
if err := decode(data, &c); err != nil {
|
||||
return Candidate{}, err
|
||||
}
|
||||
if err := c.check(); err != nil {
|
||||
return Candidate{}, err
|
||||
}
|
||||
return c, nil
|
||||
}
|
||||
|
||||
// EncodeModule is m as JSON at Version; it refuses both or neither of a fingerprint and a reason, and a
|
||||
// fingerprint not of the form src1:.
|
||||
func EncodeModule(m Module) ([]byte, error) {
|
||||
if err := m.check(); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
m.V = Version
|
||||
return json.Marshal(m)
|
||||
}
|
||||
|
||||
// DecodeModule reads a module; it refuses an unknown version (ErrUnknownVersion) and what EncodeModule refuses.
|
||||
func DecodeModule(data []byte) (Module, error) {
|
||||
var m Module
|
||||
if err := decode(data, &m); err != nil {
|
||||
return Module{}, err
|
||||
}
|
||||
if err := m.check(); err != nil {
|
||||
return Module{}, err
|
||||
}
|
||||
return m, nil
|
||||
}
|
||||
|
||||
// EncodeForge is f as JSON at Version; it refuses a message missing what its kind needs.
|
||||
func EncodeForge(f Forge) ([]byte, error) {
|
||||
if err := f.check(); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
f.V = Version
|
||||
return json.Marshal(f)
|
||||
}
|
||||
|
||||
// DecodeForge reads a forge message; it refuses an unknown version (ErrUnknownVersion) and what EncodeForge refuses.
|
||||
func DecodeForge(data []byte) (Forge, error) {
|
||||
var f Forge
|
||||
if err := decode(data, &f); err != nil {
|
||||
return Forge{}, err
|
||||
}
|
||||
if err := f.check(); err != nil {
|
||||
return Forge{}, err
|
||||
}
|
||||
return f, nil
|
||||
}
|
||||
|
||||
// SameSource says whether two sources are the same value, so a writer writes only when they differ.
|
||||
func SameSource(a, b Source) bool { return reflect.DeepEqual(a, b) }
|
||||
|
||||
// SameCandidate says whether two candidates are the same value.
|
||||
func SameCandidate(a, b Candidate) bool { return reflect.DeepEqual(a, b) }
|
||||
|
||||
// SameModule says whether two modules are the same value.
|
||||
func SameModule(a, b Module) bool { return a == b }
|
||||
|
||||
// SameForge says whether two forge messages are the same value.
|
||||
func SameForge(a, b Forge) bool { return reflect.DeepEqual(a, b) }
|
||||
-65
@@ -1,65 +0,0 @@
|
||||
package delivery
|
||||
|
||||
import (
|
||||
"encoding/json"
|
||||
"fmt"
|
||||
"time"
|
||||
)
|
||||
|
||||
// WatchmanModule is the watchman's module: its buckets are its own state, `<module>_<name>`, and the controller's
|
||||
// broker grants it alone the bus's connect and disconnect events (novox/hq ADR 0431).
|
||||
const WatchmanModule = "mesh-delivery-watchman"
|
||||
|
||||
// StuckBucket holds what stopped moving (novox/hq ADR 0433 §2): one key per key whose pulse expired, written by the
|
||||
// watchman, read by the controller's self-check, which raises each as a condition until it says moved. No key of it
|
||||
// is removed: a key that moves again is written as moved.
|
||||
const StuckBucket = WatchmanModule + "_stuck"
|
||||
|
||||
// StuckKey is the key, in StuckBucket, of the key that stopped moving: `<bucket>.<key>`, formed as PulseKey forms a
|
||||
// pulse's, so a node or part gone offline is `mesh-delivery-watchman_presence.<presence key>`.
|
||||
func StuckKey(bucket, key string) (string, error) {
|
||||
stuck, err := PulseKey(bucket, key)
|
||||
if err != nil {
|
||||
return "", fmt.Errorf("delivery: no stuck key: %w", err)
|
||||
}
|
||||
return stuck, nil
|
||||
}
|
||||
|
||||
// ParseStuckKey is the inverse of StuckKey, splitting at the first dot.
|
||||
func ParseStuckKey(stuckKey string) (bucket, key string, err error) {
|
||||
bucket, key, err = ParsePulseKey(stuckKey)
|
||||
if err != nil {
|
||||
return "", "", fmt.Errorf("delivery: %q is not a stuck key: %w", stuckKey, err)
|
||||
}
|
||||
return bucket, key, nil
|
||||
}
|
||||
|
||||
// Stuck is the value of a stuck key: the key that stopped moving, what it waited for in words, since when, and
|
||||
// whether it has moved again since. The watchman writes it; the controller reads it.
|
||||
type Stuck struct {
|
||||
V int `json:"v"`
|
||||
Bucket string `json:"bucket"`
|
||||
Key string `json:"key"`
|
||||
Waited string `json:"waited,omitempty"`
|
||||
Since time.Time `json:"since"`
|
||||
Moved bool `json:"moved,omitempty"`
|
||||
}
|
||||
|
||||
// EncodeStuck is s as JSON at Version.
|
||||
func EncodeStuck(s Stuck) ([]byte, error) {
|
||||
s.V = Version
|
||||
return json.Marshal(s)
|
||||
}
|
||||
|
||||
// DecodeStuck reads a stuck value; it refuses an unknown version (ErrUnknownVersion).
|
||||
func DecodeStuck(data []byte) (Stuck, error) {
|
||||
var s Stuck
|
||||
err := decode(data, &s)
|
||||
return s, err
|
||||
}
|
||||
|
||||
// SameStuck says whether two stuck values are the same, so a writer writes only when they differ.
|
||||
func SameStuck(a, b Stuck) bool {
|
||||
return a.V == b.V && a.Bucket == b.Bucket && a.Key == b.Key && a.Waited == b.Waited && a.Since.Equal(b.Since) &&
|
||||
a.Moved == b.Moved
|
||||
}
|
||||
Generated
Vendored
-21
@@ -1,21 +0,0 @@
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2024 Antithesis
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all
|
||||
copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
SOFTWARE.
|
||||
modules/mesh-delivery-forge-bridge/vendor/github.com/antithesishq/antithesis-sdk-go/assert/assert.go
Generated
Vendored
-214
@@ -1,214 +0,0 @@
|
||||
//go:build enable_antithesis_sdk
|
||||
|
||||
// Package assert enables defining [test properties] about your program or [workload]. It is part of the [Antithesis Go SDK], which enables Go applications to integrate with the [Antithesis platform].
|
||||
//
|
||||
// Code that uses this package should be instrumented with the [antithesis-go-generator] utility. This step is required for the Always, Sometime, and Reachable methods. It is not required for the Unreachable and AlwaysOrUnreachable methods, but it will improve the experience of using them.
|
||||
//
|
||||
// These functions are no-ops with minimal performance overhead when called outside of the Antithesis environment. However, if the environment variable ANTITHESIS_SDK_LOCAL_OUTPUT is set, these functions will log to the file pointed to by that variable using a structured JSON format defined [here]. This allows you to make use of the Antithesis assertions package in your regular testing, or even in production. In particular, very few assertions frameworks offer a convenient way to define [Sometimes assertions], but they can be quite useful even outside Antithesis.
|
||||
//
|
||||
// Each function in this package takes a parameter called message, which is a human readable identifier used to aggregate assertions. Antithesis generates one test property per unique message and this test property will be named "<message>" in the [triage report].
|
||||
//
|
||||
// This test property either passes or fails, which depends upon the evaluation of every assertion that shares its message. Different assertions in different parts of the code should have different message, but the same assertion should always have the same message even if it is moved to a different file.
|
||||
//
|
||||
// Each function also takes a parameter called details, which is a key-value map of optional additional information provided by the user to add context for assertion failures. The information that is logged will appear in the [triage report], under the details section of the corresponding property. Normally the values passed to details are evaluated at runtime.
|
||||
//
|
||||
// [Antithesis Go SDK]: https://antithesis.com/docs/using_antithesis/sdk/go/
|
||||
// [Antithesis platform]: https://antithesis.com
|
||||
// [test properties]: https://antithesis.com/docs/properties_assertions/properties/
|
||||
// [workload]: https://antithesis.com/docs/test_templates/first_test/
|
||||
// [antithesis-go-generator]: https://antithesis.com/docs/using_antithesis/sdk/go/instrumentor/
|
||||
// [triage report]: https://antithesis.com/docs/reports/
|
||||
// [here]: https://antithesis.com/docs/using_antithesis/sdk/fallback/
|
||||
// [Sometimes assertions]: https://antithesis.com/docs/best_practices/sometimes_assertions/
|
||||
//
|
||||
// [details]: https://antithesis.com/docs/reports/
|
||||
package assert
|
||||
|
||||
import (
|
||||
"encoding/json"
|
||||
"fmt"
|
||||
)
|
||||
|
||||
type assertInfo struct {
|
||||
Location *locationInfo `json:"location"`
|
||||
Details map[string]any `json:"details"`
|
||||
AssertType string `json:"assert_type"`
|
||||
DisplayType string `json:"display_type"`
|
||||
Message string `json:"message"`
|
||||
Id string `json:"id"`
|
||||
Hit bool `json:"hit"`
|
||||
MustHit bool `json:"must_hit"`
|
||||
Condition bool `json:"condition"`
|
||||
}
|
||||
|
||||
// Create a custom json marshaler for assertInfo so that we can force Errors to be marshaled with their error details.
|
||||
// Without this, custom errors are marshaled as an empty object because the default json marshaler doesn't include the error
|
||||
// (because it's a method - not an exported struct field).
|
||||
func (f assertInfo) MarshalJSON() ([]byte, error) {
|
||||
type alias assertInfo // prevent infinite recursion
|
||||
a := alias(f)
|
||||
if a.Details != nil {
|
||||
a.Details = normalizeMap(a.Details)
|
||||
}
|
||||
return json.Marshal(a)
|
||||
}
|
||||
|
||||
type jsonError struct {
|
||||
innerError error
|
||||
}
|
||||
|
||||
func (e jsonError) MarshalJSON() ([]byte, error) {
|
||||
// Marshal this as the debug output string instead of e.Error(). These should be equivalent, but Sprintf correctly
|
||||
// handles nil values for us (which otherwise are annoying to defend against due to this - https://go.dev/doc/faq#nil_error)
|
||||
return json.Marshal(fmt.Sprintf("%+v", e.innerError))
|
||||
}
|
||||
|
||||
// Recursively replace any `error` with jsonError while doing a deep copy.
|
||||
// Most of the logic is in the normalize method below. This method exists to localize the type assertions
|
||||
// and provide a function that takes in/out a map instead of any.
|
||||
func normalizeMap(v map[string]any) map[string]any {
|
||||
return normalize(v).(map[string]any)
|
||||
}
|
||||
|
||||
func normalize(input any) any {
|
||||
// This switch will miss some cases (pointers, structs, non-any types), but should catch a very large proportion of real error interfaces
|
||||
// in real details objects. We can augment this if we find other cases common enough to support.
|
||||
switch inputTyped := input.(type) {
|
||||
case error:
|
||||
// Check if the underlying error implements json.Marshaler, so that if the error
|
||||
// already knows who to marshal itself, we don't override that.
|
||||
if _, ok := inputTyped.(json.Marshaler); ok {
|
||||
return inputTyped
|
||||
} else {
|
||||
return jsonError{inputTyped}
|
||||
}
|
||||
case map[string]any:
|
||||
out := make(map[string]any, len(inputTyped))
|
||||
for k, v := range inputTyped {
|
||||
out[k] = normalize(v)
|
||||
}
|
||||
return out
|
||||
case []any:
|
||||
out := make([]any, len(inputTyped))
|
||||
for i := range inputTyped {
|
||||
out[i] = normalize(inputTyped[i])
|
||||
}
|
||||
return out
|
||||
default:
|
||||
return input
|
||||
}
|
||||
}
|
||||
|
||||
type wrappedAssertInfo struct {
|
||||
A *assertInfo `json:"antithesis_assert"`
|
||||
}
|
||||
|
||||
// --------------------------------------------------------------------------------
|
||||
// Assertions
|
||||
// --------------------------------------------------------------------------------
|
||||
const (
|
||||
wasHit = true
|
||||
mustBeHit = true
|
||||
optionallyHit = false
|
||||
expectingTrue = true
|
||||
)
|
||||
|
||||
const (
|
||||
universalTest = "always"
|
||||
existentialTest = "sometimes"
|
||||
reachabilityTest = "reachability"
|
||||
)
|
||||
|
||||
const (
|
||||
alwaysDisplay = "Always"
|
||||
alwaysOrUnreachableDisplay = "AlwaysOrUnreachable"
|
||||
sometimesDisplay = "Sometimes"
|
||||
reachableDisplay = "Reachable"
|
||||
unreachableDisplay = "Unreachable"
|
||||
)
|
||||
|
||||
// Always asserts that condition is true every time this function is called, and that it is called at least once. The corresponding test property will be viewable in the Antithesis SDK: Always group of your triage report.
|
||||
func Always(condition bool, message string, details map[string]any) {
|
||||
locationInfo := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, locationInfo)
|
||||
assertImpl(condition, message, details, locationInfo, wasHit, mustBeHit, universalTest, alwaysDisplay, id)
|
||||
}
|
||||
|
||||
// AlwaysOrUnreachable asserts that condition is true every time this function is called. The corresponding test property will pass if the assertion is never encountered (unlike Always assertion types). This test property will be viewable in the “Antithesis SDK: Always” group of your triage report.
|
||||
func AlwaysOrUnreachable(condition bool, message string, details map[string]any) {
|
||||
locationInfo := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, locationInfo)
|
||||
assertImpl(condition, message, details, locationInfo, wasHit, optionallyHit, universalTest, alwaysOrUnreachableDisplay, id)
|
||||
}
|
||||
|
||||
// Sometimes asserts that condition is true at least one time that this function was called. (If the assertion is never encountered, the test property will therefore fail.) This test property will be viewable in the “Antithesis SDK: Sometimes” group.
|
||||
func Sometimes(condition bool, message string, details map[string]any) {
|
||||
locationInfo := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, locationInfo)
|
||||
assertImpl(condition, message, details, locationInfo, wasHit, mustBeHit, existentialTest, sometimesDisplay, id)
|
||||
}
|
||||
|
||||
// Unreachable asserts that a line of code is never reached. The corresponding test property will fail if this function is ever called. (If it is never called the test property will therefore pass.) This test property will be viewable in the “Antithesis SDK: Reachablity assertions” group.
|
||||
func Unreachable(message string, details map[string]any) {
|
||||
locationInfo := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, locationInfo)
|
||||
assertImpl(false, message, details, locationInfo, wasHit, optionallyHit, reachabilityTest, unreachableDisplay, id)
|
||||
}
|
||||
|
||||
// Reachable asserts that a line of code is reached at least once. The corresponding test property will pass if this function is ever called. (If it is never called the test property will therefore fail.) This test property will be viewable in the “Antithesis SDK: Reachablity assertions” group.
|
||||
func Reachable(message string, details map[string]any) {
|
||||
locationInfo := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, locationInfo)
|
||||
assertImpl(true, message, details, locationInfo, wasHit, mustBeHit, reachabilityTest, reachableDisplay, id)
|
||||
}
|
||||
|
||||
// AssertRaw is a low-level method designed to be used by third-party frameworks. Regular users of the assert package should not call it.
|
||||
func AssertRaw(cond bool, message string, details map[string]any,
|
||||
classname, funcname, filename string, line int,
|
||||
hit bool, mustHit bool,
|
||||
assertType string, displayType string,
|
||||
id string,
|
||||
) {
|
||||
assertImpl(cond, message, details,
|
||||
&locationInfo{classname, funcname, filename, line, columnUnknown},
|
||||
hit, mustHit,
|
||||
assertType, displayType,
|
||||
id)
|
||||
}
|
||||
|
||||
func assertImpl(cond bool, message string, details map[string]any,
|
||||
loc *locationInfo,
|
||||
hit bool, mustHit bool,
|
||||
assertType string, displayType string,
|
||||
id string,
|
||||
) {
|
||||
trackerEntry := assertTracker.getTrackerEntry(id, loc.Filename, loc.Classname)
|
||||
|
||||
// Always grab the Filename and Classname captured when the trackerEntry was established
|
||||
// This provides the consistency needed between instrumentation-time and runtime
|
||||
if loc.Filename != trackerEntry.Filename {
|
||||
loc.Filename = trackerEntry.Filename
|
||||
}
|
||||
|
||||
if loc.Classname != trackerEntry.Classname {
|
||||
loc.Classname = trackerEntry.Classname
|
||||
}
|
||||
|
||||
aI := &assertInfo{
|
||||
Hit: hit,
|
||||
MustHit: mustHit,
|
||||
AssertType: assertType,
|
||||
DisplayType: displayType,
|
||||
Message: message,
|
||||
Condition: cond,
|
||||
Id: id,
|
||||
Location: loc,
|
||||
Details: details,
|
||||
}
|
||||
|
||||
trackerEntry.emit(aI)
|
||||
}
|
||||
|
||||
func makeKey(message string, _ *locationInfo) string {
|
||||
return message
|
||||
}
|
||||
Generated
Vendored
-16
@@ -1,16 +0,0 @@
|
||||
//go:build !enable_antithesis_sdk
|
||||
|
||||
package assert
|
||||
|
||||
func Always(condition bool, message string, details map[string]any) {}
|
||||
func AlwaysOrUnreachable(condition bool, message string, details map[string]any) {}
|
||||
func Sometimes(condition bool, message string, details map[string]any) {}
|
||||
func Unreachable(message string, details map[string]any) {}
|
||||
func Reachable(message string, details map[string]any) {}
|
||||
func AssertRaw(cond bool, message string, details map[string]any,
|
||||
classname, funcname, filename string, line int,
|
||||
hit bool, mustHit bool,
|
||||
assertType string, displayType string,
|
||||
id string,
|
||||
) {
|
||||
}
|
||||
Generated
Vendored
-30
@@ -1,30 +0,0 @@
|
||||
package assert
|
||||
|
||||
// Allowable numeric types of comparison parameters
|
||||
type Number interface {
|
||||
~int | ~int8 | ~int16 | ~int32 | ~int64 | ~uint8 | ~uint16 | ~uint32 | ~float32 | ~float64 | ~uint64 | ~uint | ~uintptr
|
||||
}
|
||||
|
||||
// Internally, numeric guidanceFn Operands only use these
|
||||
type operandConstraint interface {
|
||||
int32 | int64 | uint64 | float64
|
||||
}
|
||||
|
||||
type numConstraint interface {
|
||||
uint64 | float64
|
||||
}
|
||||
|
||||
// Used for boolean assertions
|
||||
type NamedBool struct {
|
||||
First string `json:"first"`
|
||||
Second bool `json:"second"`
|
||||
}
|
||||
|
||||
// Convenience function to construct a NamedBool used for boolean assertions
|
||||
func NewNamedBool(first string, second bool) *NamedBool {
|
||||
p := NamedBool{
|
||||
First: first,
|
||||
Second: second,
|
||||
}
|
||||
return &p
|
||||
}
|
||||
Generated
Vendored
-66
@@ -1,66 +0,0 @@
|
||||
//go:build enable_antithesis_sdk
|
||||
|
||||
package assert
|
||||
|
||||
import (
|
||||
"sync"
|
||||
|
||||
"github.com/antithesishq/antithesis-sdk-go/internal"
|
||||
)
|
||||
|
||||
// TODO: Tracker is intended to prevent sending the same guidance
|
||||
// more than once. In this case, we always send, so the tracker
|
||||
// is not presently used.
|
||||
type booleanGuidance struct {
|
||||
n int
|
||||
}
|
||||
|
||||
type booleanGuidanceTracker map[string]*booleanGuidance
|
||||
|
||||
var (
|
||||
boolean_guidance_tracker booleanGuidanceTracker = make(booleanGuidanceTracker)
|
||||
boolean_guidance_tracker_mutex sync.Mutex
|
||||
boolean_guidance_info_mutex sync.Mutex
|
||||
)
|
||||
|
||||
func (tracker booleanGuidanceTracker) getTrackerEntry(messageKey string) *booleanGuidance {
|
||||
var trackerEntry *booleanGuidance
|
||||
var ok bool
|
||||
|
||||
if tracker == nil {
|
||||
return nil
|
||||
}
|
||||
|
||||
boolean_guidance_tracker_mutex.Lock()
|
||||
defer boolean_guidance_tracker_mutex.Unlock()
|
||||
if trackerEntry, ok = boolean_guidance_tracker[messageKey]; !ok {
|
||||
trackerEntry = newBooleanGuidance()
|
||||
tracker[messageKey] = trackerEntry
|
||||
}
|
||||
|
||||
return trackerEntry
|
||||
}
|
||||
|
||||
// Create a boolean guidance tracker
|
||||
func newBooleanGuidance() *booleanGuidance {
|
||||
trackerInfo := booleanGuidance{}
|
||||
return &trackerInfo
|
||||
}
|
||||
|
||||
func (tI *booleanGuidance) send_value(bgI *booleanGuidanceInfo) {
|
||||
if tI == nil {
|
||||
return
|
||||
}
|
||||
|
||||
boolean_guidance_info_mutex.Lock()
|
||||
defer boolean_guidance_info_mutex.Unlock()
|
||||
|
||||
// The tracker entry should be consulted to determine
|
||||
// if this Guidance info has already been sent, or not.
|
||||
|
||||
emitBooleanGuidance(bgI)
|
||||
}
|
||||
|
||||
func emitBooleanGuidance(bgI *booleanGuidanceInfo) error {
|
||||
return internal.Json_data(map[string]any{"antithesis_guidance": bgI})
|
||||
}
|
||||
Generated
Vendored
-58
@@ -1,58 +0,0 @@
|
||||
//go:build enable_antithesis_sdk
|
||||
|
||||
package assert
|
||||
|
||||
import (
|
||||
"path"
|
||||
"runtime"
|
||||
"strings"
|
||||
)
|
||||
|
||||
// stackFrameOffset indicates how many frames to go up in the
|
||||
// call stack to find the filename/location/line info. As
|
||||
// this work is always done in NewLocationInfo(), the offset is
|
||||
// specified from the perspective of NewLocationInfo
|
||||
type stackFrameOffset int
|
||||
|
||||
// Order is important here since iota is being used
|
||||
const (
|
||||
offsetNewLocationInfo stackFrameOffset = iota
|
||||
offsetHere
|
||||
offsetAPICaller
|
||||
offsetAPICallersCaller
|
||||
)
|
||||
|
||||
// locationInfo represents the attributes known at instrumentation time
|
||||
// for each Antithesis assertion discovered
|
||||
type locationInfo struct {
|
||||
Classname string `json:"class"`
|
||||
Funcname string `json:"function"`
|
||||
Filename string `json:"file"`
|
||||
Line int `json:"begin_line"`
|
||||
Column int `json:"begin_column"`
|
||||
}
|
||||
|
||||
// columnUnknown is used when the column associated with
|
||||
// a locationInfo is not available
|
||||
const columnUnknown = 0
|
||||
|
||||
// NewLocationInfo creates a locationInfo directly from
|
||||
// the current execution context
|
||||
func newLocationInfo(nframes stackFrameOffset) *locationInfo {
|
||||
// Get location info and add to details
|
||||
funcname := "*function*"
|
||||
classname := "*class*"
|
||||
pc, filename, line, ok := runtime.Caller(int(nframes))
|
||||
if !ok {
|
||||
filename = "*file*"
|
||||
line = 0
|
||||
} else {
|
||||
if this_func := runtime.FuncForPC(pc); this_func != nil {
|
||||
fullname := this_func.Name()
|
||||
funcname = path.Ext(fullname)
|
||||
classname, _ = strings.CutSuffix(fullname, funcname)
|
||||
funcname = funcname[1:]
|
||||
}
|
||||
}
|
||||
return &locationInfo{classname, funcname, filename, line, columnUnknown}
|
||||
}
|
||||
Generated
Vendored
-323
@@ -1,323 +0,0 @@
|
||||
//go:build enable_antithesis_sdk
|
||||
|
||||
package assert
|
||||
|
||||
import (
|
||||
"math"
|
||||
"sync"
|
||||
|
||||
"github.com/antithesishq/antithesis-sdk-go/internal"
|
||||
)
|
||||
|
||||
// --------------------------------------------------------------------------------
|
||||
// IntegerGap is used for:
|
||||
// - int, int8, int16, int32, int64:
|
||||
// - uint, uint8, uint16, uint32, uint64, uintptr:
|
||||
//
|
||||
// FloatGap is used for:
|
||||
// - float32, float64
|
||||
// --------------------------------------------------------------------------------
|
||||
type numericGapType int
|
||||
|
||||
const (
|
||||
integerGapType numericGapType = iota
|
||||
floatGapType
|
||||
)
|
||||
|
||||
func gapTypeForOperand[T Number](num T) numericGapType {
|
||||
gapType := integerGapType
|
||||
|
||||
switch any(num).(type) {
|
||||
case float32, float64:
|
||||
gapType = floatGapType
|
||||
}
|
||||
return gapType
|
||||
}
|
||||
|
||||
// --------------------------------------------------------------------------------
|
||||
// numericGuidanceTracker - Tracking Info for Numeric Guidance
|
||||
//
|
||||
// For GuidanceFnMaximize:
|
||||
// - gap is the largest value sent so far
|
||||
//
|
||||
// For GuidanceFnMinimize:
|
||||
// - gap is the most negative value sent so far
|
||||
//
|
||||
// --------------------------------------------------------------------------------
|
||||
type numericGuidanceInfo struct {
|
||||
gap any
|
||||
descriminator numericGapType
|
||||
maximize bool
|
||||
}
|
||||
|
||||
type numericGuidanceTracker map[string]*numericGuidanceInfo
|
||||
|
||||
var (
|
||||
numeric_guidance_tracker numericGuidanceTracker = make(numericGuidanceTracker)
|
||||
numeric_guidance_tracker_mutex sync.Mutex
|
||||
numeric_guidance_info_mutex sync.Mutex
|
||||
)
|
||||
|
||||
func (tracker numericGuidanceTracker) getTrackerEntry(messageKey string, trackerType numericGapType, maximize bool) *numericGuidanceInfo {
|
||||
var trackerEntry *numericGuidanceInfo
|
||||
var ok bool
|
||||
|
||||
if tracker == nil {
|
||||
return nil
|
||||
}
|
||||
|
||||
numeric_guidance_tracker_mutex.Lock()
|
||||
defer numeric_guidance_tracker_mutex.Unlock()
|
||||
if trackerEntry, ok = numeric_guidance_tracker[messageKey]; !ok {
|
||||
trackerEntry = newNumericGuidanceInfo(trackerType, maximize)
|
||||
tracker[messageKey] = trackerEntry
|
||||
}
|
||||
|
||||
return trackerEntry
|
||||
}
|
||||
|
||||
// Create an numeric guidance entry
|
||||
func newNumericGuidanceInfo(trackerType numericGapType, maximize bool) *numericGuidanceInfo {
|
||||
|
||||
var gap any
|
||||
if trackerType == integerGapType {
|
||||
gap = newGapValue(uint64(math.MaxUint64), maximize)
|
||||
} else {
|
||||
gap = newGapValue(float64(math.MaxFloat64), maximize)
|
||||
}
|
||||
trackerInfo := numericGuidanceInfo{
|
||||
maximize: maximize,
|
||||
descriminator: trackerType,
|
||||
gap: gap,
|
||||
}
|
||||
return &trackerInfo
|
||||
}
|
||||
|
||||
func (tI *numericGuidanceInfo) should_maximize() bool {
|
||||
return tI.maximize
|
||||
}
|
||||
|
||||
func (tI *numericGuidanceInfo) is_integer_gap() bool {
|
||||
return tI.descriminator == integerGapType
|
||||
}
|
||||
|
||||
// --------------------------------------------------------------------------------
|
||||
// Represents integral and floating point extremes
|
||||
// --------------------------------------------------------------------------------
|
||||
type gapValue[T numConstraint] struct {
|
||||
gap_size T
|
||||
gap_is_negative bool
|
||||
}
|
||||
|
||||
func newGapValue[T numConstraint](sz T, is_neg bool) any {
|
||||
switch any(sz).(type) {
|
||||
case uint64:
|
||||
return gapValue[uint64]{gap_size: uint64(sz), gap_is_negative: is_neg}
|
||||
|
||||
case float64:
|
||||
return gapValue[float64]{gap_size: float64(sz), gap_is_negative: is_neg}
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
func is_same_sign(left_val int64, right_val int64) bool {
|
||||
same_sign := false
|
||||
if left_val < 0 {
|
||||
// left is negative
|
||||
if right_val < 0 {
|
||||
same_sign = true
|
||||
}
|
||||
} else {
|
||||
// left is non-negative
|
||||
if right_val >= 0 {
|
||||
same_sign = true
|
||||
}
|
||||
}
|
||||
return same_sign
|
||||
}
|
||||
|
||||
func abs_int64(val int64) uint64 {
|
||||
if val >= 0 {
|
||||
return uint64(val)
|
||||
}
|
||||
return uint64(0 - val)
|
||||
}
|
||||
|
||||
func is_greater_than[T numConstraint](left gapValue[T], right gapValue[T]) bool {
|
||||
if !left.gap_is_negative && !right.gap_is_negative {
|
||||
return left.gap_size > right.gap_size
|
||||
}
|
||||
if !left.gap_is_negative && right.gap_is_negative {
|
||||
return true // any positive is greater than a negative
|
||||
}
|
||||
if left.gap_is_negative && right.gap_is_negative {
|
||||
return right.gap_size > left.gap_size
|
||||
}
|
||||
if left.gap_is_negative && !right.gap_is_negative {
|
||||
return false // any negative is less than a positive
|
||||
}
|
||||
return false
|
||||
}
|
||||
|
||||
func is_less_than[T numConstraint](left gapValue[T], right gapValue[T]) bool {
|
||||
if !left.gap_is_negative && !right.gap_is_negative {
|
||||
return left.gap_size < right.gap_size
|
||||
}
|
||||
if !left.gap_is_negative && right.gap_is_negative {
|
||||
return false // any positive is greater than a negative
|
||||
}
|
||||
if left.gap_is_negative && right.gap_is_negative {
|
||||
return right.gap_size < left.gap_size
|
||||
}
|
||||
if left.gap_is_negative && !right.gap_is_negative {
|
||||
return true // any negative is less than a positive
|
||||
}
|
||||
return true
|
||||
}
|
||||
|
||||
func send_value_if_needed(tI *numericGuidanceInfo, gI *guidanceInfo) {
|
||||
if tI == nil {
|
||||
return
|
||||
}
|
||||
|
||||
numeric_guidance_info_mutex.Lock()
|
||||
defer numeric_guidance_info_mutex.Unlock()
|
||||
|
||||
// if this is a catalog entry (gI.hit is false)
|
||||
// do not update the reference gap in the tracker (tI *numericGuidanceInfo)
|
||||
if !gI.Hit {
|
||||
emitGuidance(gI)
|
||||
return
|
||||
}
|
||||
|
||||
should_send := false
|
||||
maximize := tI.should_maximize()
|
||||
|
||||
var gap gapValue[uint64]
|
||||
var float_gap gapValue[float64]
|
||||
|
||||
// Needs to have individual case statements to assist
|
||||
// the compiler to infer the actual type of the var named 'operands'
|
||||
switch operands := (gI.Data).(type) {
|
||||
case numericOperands[int32]:
|
||||
gap = makeGap(operands)
|
||||
case numericOperands[int64]:
|
||||
gap = makeGap(operands)
|
||||
case numericOperands[uint64]:
|
||||
gap = makeGap(operands)
|
||||
case numericOperands[float64]:
|
||||
float_gap = makeFloatGap(operands)
|
||||
}
|
||||
|
||||
var prev_gap gapValue[uint64]
|
||||
var prev_float_gap gapValue[float64]
|
||||
has_prev_gap := false
|
||||
has_prev_float_gap := false
|
||||
|
||||
prev_gap, has_prev_gap = tI.gap.(gapValue[uint64])
|
||||
if !has_prev_gap {
|
||||
prev_float_gap, has_prev_float_gap = tI.gap.(gapValue[float64])
|
||||
}
|
||||
|
||||
if has_prev_gap {
|
||||
if maximize {
|
||||
should_send = is_greater_than(gap, prev_gap)
|
||||
} else {
|
||||
should_send = is_less_than(gap, prev_gap)
|
||||
}
|
||||
}
|
||||
|
||||
if has_prev_float_gap {
|
||||
if maximize {
|
||||
should_send = is_greater_than(float_gap, prev_float_gap)
|
||||
} else {
|
||||
should_send = is_less_than(float_gap, prev_float_gap)
|
||||
}
|
||||
}
|
||||
|
||||
if should_send {
|
||||
if tI.is_integer_gap() {
|
||||
tI.gap = gap
|
||||
} else {
|
||||
tI.gap = float_gap
|
||||
}
|
||||
emitGuidance(gI)
|
||||
}
|
||||
}
|
||||
|
||||
func emitGuidance(gI *guidanceInfo) error {
|
||||
return internal.Json_data(map[string]any{"antithesis_guidance": gI})
|
||||
}
|
||||
|
||||
// When left and right are the same sign (both negative, or both non-negative)
|
||||
// Calculate: <result> = (left - right). The gap_size is abs(<result>) and
|
||||
// gap_is_negative is (right > left)
|
||||
func makeGap[Op operandConstraint](operand numericOperands[Op]) gapValue[uint64] {
|
||||
|
||||
var gap_size uint64
|
||||
var gap_is_negative bool
|
||||
|
||||
switch this_op := any(operand).(type) {
|
||||
case numericOperands[int32]:
|
||||
result := int64(this_op.Left) - int64(this_op.Right)
|
||||
gap_size = abs_int64(result)
|
||||
gap_is_negative = result < 0
|
||||
|
||||
case numericOperands[int64]:
|
||||
if is_same_sign(this_op.Left, this_op.Right) {
|
||||
result := int64(this_op.Left) - int64(this_op.Right)
|
||||
gap_size = abs_int64(result)
|
||||
gap_is_negative = result < 0
|
||||
break
|
||||
}
|
||||
|
||||
// Otherwise left and right are opposite signs
|
||||
// gap = abs(left) + abs(right)
|
||||
// gap_is_negative = left < right
|
||||
left_gap_size := abs_int64(this_op.Left)
|
||||
right_gap_size := abs_int64(this_op.Right)
|
||||
gap_size = left_gap_size + right_gap_size
|
||||
gap_is_negative = this_op.Left < this_op.Right
|
||||
|
||||
case numericOperands[uint64]:
|
||||
left_val := this_op.Left
|
||||
right_val := this_op.Right
|
||||
gap_is_negative = false
|
||||
if left_val < right_val {
|
||||
gap_is_negative = true
|
||||
gap_size = right_val - left_val
|
||||
} else {
|
||||
gap_size = left_val - right_val
|
||||
}
|
||||
|
||||
default:
|
||||
zero_gap, _ := newGapValue(uint64(0), false).(gapValue[uint64])
|
||||
return zero_gap
|
||||
}
|
||||
|
||||
this_gap, _ := newGapValue(gap_size, gap_is_negative).(gapValue[uint64])
|
||||
return this_gap
|
||||
} // MakeGap
|
||||
|
||||
func makeFloatGap[Op operandConstraint](operand numericOperands[Op]) gapValue[float64] {
|
||||
switch this_op := any(operand).(type) {
|
||||
case numericOperands[float64]:
|
||||
left_val := this_op.Left
|
||||
right_val := this_op.Right
|
||||
gap_is_negative := false
|
||||
var gap_size float64
|
||||
if left_val < right_val {
|
||||
gap_is_negative = true
|
||||
gap_size = right_val - left_val
|
||||
} else {
|
||||
gap_size = left_val - right_val
|
||||
}
|
||||
|
||||
this_gap, _ := newGapValue(gap_size, gap_is_negative).(gapValue[float64])
|
||||
return this_gap
|
||||
|
||||
default:
|
||||
zero_gap, _ := newGapValue(float64(0.0), false).(gapValue[float64])
|
||||
return zero_gap
|
||||
}
|
||||
} // MakeFloatGap
|
||||
Generated
Vendored
-330
@@ -1,330 +0,0 @@
|
||||
//go:build enable_antithesis_sdk
|
||||
|
||||
package assert
|
||||
|
||||
// A type for writing raw assertions.
|
||||
// guidanceFnType allows the assertion to provide guidance to
|
||||
// the Antithesis platform when testing in Antithesis.
|
||||
// Regular users of the assert package should not use it.
|
||||
type guidanceFnType int
|
||||
|
||||
const (
|
||||
guidanceFnMaximize guidanceFnType = iota // Maximize (left - right) values
|
||||
guidanceFnMinimize // Minimize (left - right) values
|
||||
guidanceFnWantAll // Encourages fuzzing explorations where boolean values are true
|
||||
guidanceFnWantNone // Encourages fuzzing explorations where boolean values are false
|
||||
guidanceFnExplore
|
||||
)
|
||||
|
||||
// guidanceFnExplore
|
||||
|
||||
func get_guidance_type_string(gt guidanceFnType) string {
|
||||
switch gt {
|
||||
case guidanceFnMaximize, guidanceFnMinimize:
|
||||
return "numeric"
|
||||
case guidanceFnWantAll, guidanceFnWantNone:
|
||||
return "boolean"
|
||||
case guidanceFnExplore:
|
||||
return "json"
|
||||
}
|
||||
return ""
|
||||
}
|
||||
|
||||
type numericOperands[T operandConstraint] struct {
|
||||
Left T `json:"left"`
|
||||
Right T `json:"right"`
|
||||
}
|
||||
|
||||
type guidanceInfo struct {
|
||||
Data any `json:"guidance_data,omitempty"`
|
||||
Location *locationInfo `json:"location"`
|
||||
GuidanceType string `json:"guidance_type"`
|
||||
Message string `json:"message"`
|
||||
Id string `json:"id"`
|
||||
Maximize bool `json:"maximize"`
|
||||
Hit bool `json:"hit"`
|
||||
}
|
||||
|
||||
type booleanGuidanceInfo struct {
|
||||
Data any `json:"guidance_data,omitempty"`
|
||||
Location *locationInfo `json:"location"`
|
||||
GuidanceType string `json:"guidance_type"`
|
||||
Message string `json:"message"`
|
||||
Id string `json:"id"`
|
||||
Maximize bool `json:"maximize"`
|
||||
Hit bool `json:"hit"`
|
||||
}
|
||||
|
||||
func uses_maximize(gt guidanceFnType) bool {
|
||||
return gt == guidanceFnMaximize || gt == guidanceFnWantAll
|
||||
}
|
||||
|
||||
func newOperands[T Number](left, right T) any {
|
||||
switch any(left).(type) {
|
||||
case int8, int16, int32:
|
||||
return numericOperands[int32]{int32(left), int32(right)}
|
||||
case int, int64:
|
||||
return numericOperands[int64]{int64(left), int64(right)}
|
||||
case uint8, uint16, uint32, uint, uint64, uintptr:
|
||||
return numericOperands[uint64]{uint64(left), uint64(right)}
|
||||
case float32, float64:
|
||||
return numericOperands[float64]{float64(left), float64(right)}
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
func build_numeric_guidance[T Number](gt guidanceFnType, message string, left, right T, loc *locationInfo, id string, hit bool) *guidanceInfo {
|
||||
|
||||
operands := newOperands(left, right)
|
||||
if !hit {
|
||||
operands = nil
|
||||
}
|
||||
|
||||
gI := guidanceInfo{
|
||||
GuidanceType: get_guidance_type_string(gt),
|
||||
Message: message,
|
||||
Id: id,
|
||||
Location: loc,
|
||||
Maximize: uses_maximize(gt),
|
||||
Data: operands,
|
||||
Hit: hit,
|
||||
}
|
||||
|
||||
return &gI
|
||||
}
|
||||
|
||||
type namedBoolDictionary map[string]bool
|
||||
|
||||
func build_boolean_guidance(gt guidanceFnType, message string, named_bools []NamedBool,
|
||||
loc *locationInfo,
|
||||
id string, hit bool) *booleanGuidanceInfo {
|
||||
|
||||
var guidance_data any
|
||||
|
||||
// To ensure the sequence and naming for the named_bool values
|
||||
if hit {
|
||||
named_bool_dictionary := namedBoolDictionary{}
|
||||
for _, named_bool := range named_bools {
|
||||
named_bool_dictionary[named_bool.First] = named_bool.Second
|
||||
}
|
||||
guidance_data = named_bool_dictionary
|
||||
}
|
||||
|
||||
bgI := booleanGuidanceInfo{
|
||||
GuidanceType: get_guidance_type_string(gt),
|
||||
Message: message,
|
||||
Id: id,
|
||||
Location: loc,
|
||||
Maximize: uses_maximize(gt),
|
||||
Data: guidance_data,
|
||||
Hit: hit,
|
||||
}
|
||||
|
||||
return &bgI
|
||||
}
|
||||
|
||||
func behavior_to_guidance(behavior string) guidanceFnType {
|
||||
guidance := guidanceFnExplore
|
||||
switch behavior {
|
||||
case "maximize":
|
||||
guidance = guidanceFnMaximize
|
||||
case "minimize":
|
||||
guidance = guidanceFnMinimize
|
||||
case "all":
|
||||
guidance = guidanceFnWantAll
|
||||
case "none":
|
||||
guidance = guidanceFnWantNone
|
||||
}
|
||||
return guidance
|
||||
}
|
||||
|
||||
func numericGuidanceImpl[T Number](left, right T, message, id string, loc *locationInfo, guidanceFn guidanceFnType, hit bool) {
|
||||
tI := numeric_guidance_tracker.getTrackerEntry(id, gapTypeForOperand(left), uses_maximize(guidanceFn))
|
||||
gI := build_numeric_guidance(guidanceFn, message, left, right, loc, id, hit)
|
||||
send_value_if_needed(tI, gI)
|
||||
}
|
||||
|
||||
func booleanGuidanceImpl(named_bools []NamedBool, message, id string, loc *locationInfo, guidanceFn guidanceFnType, hit bool) {
|
||||
tI := boolean_guidance_tracker.getTrackerEntry(id)
|
||||
bgI := build_boolean_guidance(guidanceFn, message, named_bools, loc, id, hit)
|
||||
tI.send_value(bgI)
|
||||
}
|
||||
|
||||
// NumericGuidanceRaw is a low-level method designed to be used by third-party frameworks. Regular users of the assert package should not call it.
|
||||
func NumericGuidanceRaw[T Number](
|
||||
left, right T,
|
||||
message, id string,
|
||||
classname, funcname, filename string,
|
||||
line int,
|
||||
behavior string,
|
||||
hit bool,
|
||||
) {
|
||||
loc := &locationInfo{classname, funcname, filename, line, columnUnknown}
|
||||
guidanceFn := behavior_to_guidance(behavior)
|
||||
numericGuidanceImpl(left, right, message, id, loc, guidanceFn, hit)
|
||||
}
|
||||
|
||||
// BooleanGuidanceRaw is a low-level method designed to be used by third-party frameworks. Regular users of the assert package should not call it.
|
||||
func BooleanGuidanceRaw(
|
||||
named_bools []NamedBool,
|
||||
message, id string,
|
||||
classname, funcname, filename string,
|
||||
line int,
|
||||
behavior string,
|
||||
hit bool,
|
||||
) {
|
||||
loc := &locationInfo{classname, funcname, filename, line, columnUnknown}
|
||||
guidanceFn := behavior_to_guidance(behavior)
|
||||
booleanGuidanceImpl(named_bools, message, id, loc, guidanceFn, hit)
|
||||
}
|
||||
|
||||
func add_numeric_details[T Number](details map[string]any, left, right T) map[string]any {
|
||||
// ----------------------------------------------------
|
||||
// Can not use maps.Clone() until go 1.21.0 or above
|
||||
// enhancedDetails := maps.Clone(details)
|
||||
// ----------------------------------------------------
|
||||
enhancedDetails := map[string]any{}
|
||||
for k, v := range details {
|
||||
enhancedDetails[k] = v
|
||||
}
|
||||
enhancedDetails["left"] = left
|
||||
enhancedDetails["right"] = right
|
||||
return enhancedDetails
|
||||
}
|
||||
|
||||
func add_boolean_details(details map[string]any, named_bools []NamedBool) map[string]any {
|
||||
// ----------------------------------------------------
|
||||
// Can not use maps.Clone() until go 1.21.0 or above
|
||||
// enhancedDetails := maps.Clone(details)
|
||||
// ----------------------------------------------------
|
||||
enhancedDetails := map[string]any{}
|
||||
for k, v := range details {
|
||||
enhancedDetails[k] = v
|
||||
}
|
||||
for _, named_bool := range named_bools {
|
||||
enhancedDetails[named_bool.First] = named_bool.Second
|
||||
}
|
||||
return enhancedDetails
|
||||
}
|
||||
|
||||
// Equivalent to asserting Always(left > right, message, details). Information about left and right will automatically be added to the details parameter, with keys left and right. If you use this function for assertions that compare numeric quantities, you may help Antithesis find more bugs.
|
||||
func AlwaysGreaterThan[T Number](left, right T, message string, details map[string]any) {
|
||||
loc := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, loc)
|
||||
condition := left > right
|
||||
all_details := add_numeric_details(details, left, right)
|
||||
assertImpl(condition, message, all_details, loc, wasHit, mustBeHit, universalTest, alwaysDisplay, id)
|
||||
|
||||
numericGuidanceImpl(left, right, message, id, loc, guidanceFnMinimize, wasHit)
|
||||
}
|
||||
|
||||
// Equivalent to asserting Always(left >= right, message, details). Information about left and right will automatically be added to the details parameter, with keys left and right. If you use this function for assertions that compare numeric quantities, you may help Antithesis find more bugs.
|
||||
func AlwaysGreaterThanOrEqualTo[T Number](left, right T, message string, details map[string]any) {
|
||||
loc := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, loc)
|
||||
condition := left >= right
|
||||
all_details := add_numeric_details(details, left, right)
|
||||
assertImpl(condition, message, all_details, loc, wasHit, mustBeHit, universalTest, alwaysDisplay, id)
|
||||
|
||||
numericGuidanceImpl(left, right, message, id, loc, guidanceFnMinimize, wasHit)
|
||||
}
|
||||
|
||||
// Equivalent to asserting Sometimes(T left > T right, message, details). Information about left and right will automatically be added to the details parameter, with keys left and right. If you use this function for assertions that compare numeric quantities, you may help Antithesis find more bugs.
|
||||
func SometimesGreaterThan[T Number](left, right T, message string, details map[string]any) {
|
||||
loc := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, loc)
|
||||
condition := left > right
|
||||
all_details := add_numeric_details(details, left, right)
|
||||
assertImpl(condition, message, all_details, loc, wasHit, mustBeHit, existentialTest, sometimesDisplay, id)
|
||||
|
||||
numericGuidanceImpl(left, right, message, id, loc, guidanceFnMaximize, wasHit)
|
||||
}
|
||||
|
||||
// Equivalent to asserting Sometimes(T left >= T right, message, details). Information about left and right will automatically be added to the details parameter, with keys left and right. If you use this function for assertions that compare numeric quantities, you may help Antithesis find more bugs.
|
||||
func SometimesGreaterThanOrEqualTo[T Number](left, right T, message string, details map[string]any) {
|
||||
loc := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, loc)
|
||||
condition := left >= right
|
||||
all_details := add_numeric_details(details, left, right)
|
||||
assertImpl(condition, message, all_details, loc, wasHit, mustBeHit, existentialTest, sometimesDisplay, id)
|
||||
|
||||
numericGuidanceImpl(left, right, message, id, loc, guidanceFnMaximize, wasHit)
|
||||
}
|
||||
|
||||
// Equivalent to asserting Always(left < right, message, details). Information about left and right will automatically be added to the details parameter, with keys left and right. If you use this function for assertions that compare numeric quantities, you may help Antithesis find more bugs.
|
||||
func AlwaysLessThan[T Number](left, right T, message string, details map[string]any) {
|
||||
loc := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, loc)
|
||||
condition := left < right
|
||||
all_details := add_numeric_details(details, left, right)
|
||||
assertImpl(condition, message, all_details, loc, wasHit, mustBeHit, universalTest, alwaysDisplay, id)
|
||||
|
||||
numericGuidanceImpl(left, right, message, id, loc, guidanceFnMaximize, wasHit)
|
||||
}
|
||||
|
||||
// Equivalent to asserting Always(left <= right, message, details). Information about left and right will automatically be added to the details parameter, with keys left and right. If you use this function for assertions that compare numeric quantities, you may help Antithesis find more bugs.
|
||||
func AlwaysLessThanOrEqualTo[T Number](left, right T, message string, details map[string]any) {
|
||||
loc := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, loc)
|
||||
condition := left <= right
|
||||
all_details := add_numeric_details(details, left, right)
|
||||
assertImpl(condition, message, all_details, loc, wasHit, mustBeHit, universalTest, alwaysDisplay, id)
|
||||
|
||||
numericGuidanceImpl(left, right, message, id, loc, guidanceFnMaximize, wasHit)
|
||||
}
|
||||
|
||||
// Equivalent to asserting Sometimes(T left < T right, message, details). Information about left and right will automatically be added to the details parameter, with keys left and right. If you use this function for assertions that compare numeric quantities, you may help Antithesis find more bugs.
|
||||
func SometimesLessThan[T Number](left, right T, message string, details map[string]any) {
|
||||
loc := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, loc)
|
||||
condition := left < right
|
||||
all_details := add_numeric_details(details, left, right)
|
||||
assertImpl(condition, message, all_details, loc, wasHit, mustBeHit, existentialTest, sometimesDisplay, id)
|
||||
|
||||
numericGuidanceImpl(left, right, message, id, loc, guidanceFnMinimize, wasHit)
|
||||
}
|
||||
|
||||
// Equivalent to asserting Sometimes(T left <= T right, message, details). Information about left and right will automatically be added to the details parameter, with keys left and right. If you use this function for assertions that compare numeric quantities, you may help Antithesis find more bugs.
|
||||
func SometimesLessThanOrEqualTo[T Number](left, right T, message string, details map[string]any) {
|
||||
loc := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, loc)
|
||||
condition := left <= right
|
||||
all_details := add_numeric_details(details, left, right)
|
||||
assertImpl(condition, message, all_details, loc, wasHit, mustBeHit, existentialTest, sometimesDisplay, id)
|
||||
|
||||
numericGuidanceImpl(left, right, message, id, loc, guidanceFnMinimize, wasHit)
|
||||
}
|
||||
|
||||
// Asserts that every time this is called, at least one bool in named_bools is true. Equivalent to Always(named_bools[0].second || named_bools[1].second || ..., message, details). If you use this for assertions about the behavior of booleans, you may help Antithesis find more bugs. Information about named_bools will automatically be added to the details parameter, and the keys will be the names of the bools.
|
||||
func AlwaysSome(named_bools []NamedBool, message string, details map[string]any) {
|
||||
loc := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, loc)
|
||||
disjunction := false
|
||||
for _, named_bool := range named_bools {
|
||||
if named_bool.Second {
|
||||
disjunction = true
|
||||
break
|
||||
}
|
||||
}
|
||||
all_details := add_boolean_details(details, named_bools)
|
||||
assertImpl(disjunction, message, all_details, loc, wasHit, mustBeHit, universalTest, alwaysDisplay, id)
|
||||
|
||||
booleanGuidanceImpl(named_bools, message, id, loc, guidanceFnWantNone, wasHit)
|
||||
}
|
||||
|
||||
// Asserts that at least one time this is called, every bool in named_bools is true. Equivalent to Sometimes(named_bools[0].second && named_bools[1].second && ..., message, details). If you use this for assertions about the behavior of booleans, you may help Antithesis find more bugs. Information about named_bools will automatically be added to the details parameter, and the keys will be the names of the bools.
|
||||
func SometimesAll(named_bools []NamedBool, message string, details map[string]any) {
|
||||
loc := newLocationInfo(offsetAPICaller)
|
||||
id := makeKey(message, loc)
|
||||
conjunction := true
|
||||
for _, named_bool := range named_bools {
|
||||
if !named_bool.Second {
|
||||
conjunction = false
|
||||
break
|
||||
}
|
||||
}
|
||||
all_details := add_boolean_details(details, named_bools)
|
||||
assertImpl(conjunction, message, all_details, loc, wasHit, mustBeHit, existentialTest, sometimesDisplay, id)
|
||||
|
||||
booleanGuidanceImpl(named_bools, message, id, loc, guidanceFnWantAll, wasHit)
|
||||
}
|
||||
Generated
Vendored
-34
@@ -1,34 +0,0 @@
|
||||
//go:build !enable_antithesis_sdk
|
||||
|
||||
package assert
|
||||
|
||||
func AlwaysGreaterThan[T Number](left, right T, message string, details map[string]any) {}
|
||||
func AlwaysGreaterThanOrEqualTo[T Number](left, right T, message string, details map[string]any) {}
|
||||
func SometimesGreaterThan[T Number](left, right T, message string, details map[string]any) {}
|
||||
func SometimesGreaterThanOrEqualTo[T Number](left, right T, message string, details map[string]any) {}
|
||||
func AlwaysLessThan[T Number](left, right T, message string, details map[string]any) {}
|
||||
func AlwaysLessThanOrEqualTo[T Number](left, right T, message string, details map[string]any) {}
|
||||
func SometimesLessThan[T Number](left, right T, message string, details map[string]any) {}
|
||||
func SometimesLessThanOrEqualTo[T Number](left, right T, message string, details map[string]any) {}
|
||||
|
||||
func AlwaysSome(named_bool []NamedBool, message string, details map[string]any) {}
|
||||
func SometimesAll(named_bool []NamedBool, message string, details map[string]any) {}
|
||||
|
||||
func NumericGuidanceRaw[T Number](left, right T,
|
||||
message, id string,
|
||||
classname, funcname, filename string,
|
||||
line int,
|
||||
behavior string,
|
||||
hit bool,
|
||||
) {
|
||||
}
|
||||
|
||||
func BooleanGuidanceRaw(
|
||||
named_bools []NamedBool,
|
||||
message, id string,
|
||||
classname, funcname, filename string,
|
||||
line int,
|
||||
behavior string,
|
||||
hit bool,
|
||||
) {
|
||||
}
|
||||
Generated
Vendored
-111
@@ -1,111 +0,0 @@
|
||||
//go:build enable_antithesis_sdk
|
||||
|
||||
package assert
|
||||
|
||||
import (
|
||||
"runtime"
|
||||
"sync"
|
||||
"sync/atomic"
|
||||
|
||||
"github.com/antithesishq/antithesis-sdk-go/internal"
|
||||
)
|
||||
|
||||
type trackerInfo struct {
|
||||
Filename string
|
||||
Classname string
|
||||
PassCount int
|
||||
FailCount int
|
||||
}
|
||||
|
||||
type emitTracker map[string]*trackerInfo
|
||||
|
||||
// assert_tracker (global) keeps track of the unique asserts evaluated
|
||||
var (
|
||||
assertTracker emitTracker = make(emitTracker)
|
||||
trackerMutex sync.Mutex
|
||||
trackerInfoMutex sync.Mutex
|
||||
)
|
||||
|
||||
func (tracker emitTracker) getTrackerEntry(messageKey string, filename, classname string) *trackerInfo {
|
||||
var trackerEntry *trackerInfo
|
||||
var ok bool
|
||||
|
||||
if tracker == nil {
|
||||
return nil
|
||||
}
|
||||
|
||||
trackerMutex.Lock()
|
||||
defer trackerMutex.Unlock()
|
||||
if trackerEntry, ok = tracker[messageKey]; !ok {
|
||||
trackerEntry = newTrackerInfo(filename, classname)
|
||||
tracker[messageKey] = trackerEntry
|
||||
}
|
||||
return trackerEntry
|
||||
}
|
||||
|
||||
func newTrackerInfo(filename, classname string) *trackerInfo {
|
||||
trackerInfo := trackerInfo{
|
||||
PassCount: 0,
|
||||
FailCount: 0,
|
||||
Filename: filename,
|
||||
Classname: classname,
|
||||
}
|
||||
return &trackerInfo
|
||||
}
|
||||
|
||||
func (ti *trackerInfo) emit(ai *assertInfo) {
|
||||
if ti == nil || ai == nil {
|
||||
return
|
||||
}
|
||||
|
||||
// Registrations are just sent to voidstar
|
||||
hit := ai.Hit
|
||||
if !hit {
|
||||
emitAssert(ai)
|
||||
return
|
||||
}
|
||||
|
||||
var err error
|
||||
cond := ai.Condition
|
||||
|
||||
trackerInfoMutex.Lock()
|
||||
defer trackerInfoMutex.Unlock()
|
||||
if cond {
|
||||
if ti.PassCount == 0 {
|
||||
err = emitAssert(ai)
|
||||
}
|
||||
if err == nil {
|
||||
ti.PassCount++
|
||||
}
|
||||
return
|
||||
}
|
||||
if ti.FailCount == 0 {
|
||||
err = emitAssert(ai)
|
||||
}
|
||||
if err == nil {
|
||||
ti.FailCount++
|
||||
}
|
||||
}
|
||||
|
||||
func versionMessage() {
|
||||
languageBlock := map[string]any{
|
||||
"name": "Go",
|
||||
"version": runtime.Version(),
|
||||
}
|
||||
versionBlock := map[string]any{
|
||||
"language": languageBlock,
|
||||
"sdk_version": internal.SDK_Version,
|
||||
"protocol_version": internal.Protocol_Version,
|
||||
}
|
||||
internal.Json_data(map[string]any{"antithesis_sdk": versionBlock})
|
||||
}
|
||||
|
||||
// package-level flag
|
||||
var hasEmitted atomic.Bool // initialzed to false
|
||||
|
||||
func emitAssert(ai *assertInfo) error {
|
||||
if hasEmitted.CompareAndSwap(false, true) {
|
||||
versionMessage()
|
||||
}
|
||||
return internal.Json_data(wrappedAssertInfo{ai})
|
||||
}
|
||||
modules/mesh-delivery-forge-bridge/vendor/github.com/antithesishq/antithesis-sdk-go/internal/emit.go
Generated
Vendored
-100
@@ -1,100 +0,0 @@
|
||||
//go:build enable_antithesis_sdk
|
||||
|
||||
package internal
|
||||
|
||||
import (
|
||||
"encoding/json"
|
||||
"log"
|
||||
"math/rand"
|
||||
"os"
|
||||
)
|
||||
|
||||
func Json_data(v any) error {
|
||||
if data, err := json.Marshal(v); err != nil {
|
||||
return err
|
||||
} else {
|
||||
handler.output(string(data))
|
||||
return nil
|
||||
}
|
||||
}
|
||||
|
||||
func Get_random() uint64 {
|
||||
return handler.random()
|
||||
}
|
||||
|
||||
func Notify(edge uint64) bool {
|
||||
return handler.notify(edge)
|
||||
}
|
||||
|
||||
func InitCoverage(num_edges uint64, symbols string) uint64 {
|
||||
return handler.init_coverage(num_edges, symbols)
|
||||
}
|
||||
|
||||
type libHandler interface {
|
||||
output(message string)
|
||||
random() uint64
|
||||
notify(edge uint64) bool
|
||||
init_coverage(num_edges uint64, symbols string) uint64
|
||||
}
|
||||
|
||||
const (
|
||||
errorLogLinePrefix = "[* antithesis-sdk-go *]"
|
||||
)
|
||||
|
||||
var handler libHandler
|
||||
|
||||
type localHandler struct {
|
||||
outputFile *os.File // can be nil
|
||||
}
|
||||
|
||||
func (h *localHandler) output(message string) {
|
||||
msg_len := len(message)
|
||||
if msg_len == 0 {
|
||||
return
|
||||
}
|
||||
if h.outputFile != nil {
|
||||
h.outputFile.WriteString(message + "\n")
|
||||
}
|
||||
}
|
||||
|
||||
func (h *localHandler) random() uint64 {
|
||||
return rand.Uint64()
|
||||
}
|
||||
|
||||
func (h *localHandler) notify(edge uint64) bool {
|
||||
return false
|
||||
}
|
||||
|
||||
func (h *localHandler) init_coverage(num_edges uint64, symbols string) uint64 {
|
||||
return 0
|
||||
}
|
||||
|
||||
func init() {
|
||||
handler = init_in_antithesis()
|
||||
if handler == nil {
|
||||
// Otherwise fallback to the local handler.
|
||||
handler = openLocalHandler()
|
||||
}
|
||||
}
|
||||
|
||||
// If `localOutputEnvVar` is set to a non-empty path, attempt to open that path and truncate the file
|
||||
// to serve as the log file of the local handler.
|
||||
// Otherwise, we don't have a log file, and logging is a no-op in the local handler.
|
||||
func openLocalHandler() *localHandler {
|
||||
path, is_set := os.LookupEnv(localOutputEnvVar)
|
||||
if !is_set || len(path) == 0 {
|
||||
return &localHandler{nil}
|
||||
}
|
||||
|
||||
// Open the file R/W (create if needed and possible)
|
||||
file, err := os.OpenFile(path, os.O_RDWR|os.O_CREATE, 0644)
|
||||
if err != nil {
|
||||
log.Printf("%s Failed to open path %s: %v", errorLogLinePrefix, path, err)
|
||||
file = nil
|
||||
} else if err = file.Truncate(0); err != nil {
|
||||
log.Printf("%s Failed to truncate file at %s: %v", errorLogLinePrefix, path, err)
|
||||
file = nil
|
||||
}
|
||||
|
||||
return &localHandler{file}
|
||||
}
|
||||
Generated
Vendored
-12
@@ -1,12 +0,0 @@
|
||||
package internal
|
||||
|
||||
// --------------------------------------------------------------------------------
|
||||
// Versions
|
||||
// --------------------------------------------------------------------------------
|
||||
const SDK_Version = "0.7.0"
|
||||
const Protocol_Version = "1.1.0"
|
||||
|
||||
// --------------------------------------------------------------------------------
|
||||
// Environment Vars
|
||||
// --------------------------------------------------------------------------------
|
||||
const localOutputEnvVar = "ANTITHESIS_SDK_LOCAL_OUTPUT"
|
||||
Generated
Vendored
-160
@@ -1,160 +0,0 @@
|
||||
//go:build enable_antithesis_sdk && linux && amd64 && cgo
|
||||
|
||||
package internal
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"unsafe"
|
||||
"os"
|
||||
)
|
||||
|
||||
// --------------------------------------------------------------------------------
|
||||
// To build and run an executable with this package
|
||||
//
|
||||
// CC=clang CGO_ENABLED=1 go run ./main.go
|
||||
// --------------------------------------------------------------------------------
|
||||
|
||||
// \/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/
|
||||
//
|
||||
// The commented lines below, and the `import "C"` line which must directly follow
|
||||
// the commented lines are used by CGO. They are load-bearing, and should not be
|
||||
// changed without first understanding how CGO uses them.
|
||||
//
|
||||
// \/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/\/
|
||||
|
||||
// #cgo LDFLAGS: -ldl
|
||||
//
|
||||
// #include <dlfcn.h>
|
||||
// #include <stdbool.h>
|
||||
// #include <stdint.h>
|
||||
// #include <stdlib.h>
|
||||
//
|
||||
// typedef void (*go_fuzz_json_data_fn)(const char *data, size_t size);
|
||||
// void
|
||||
// go_fuzz_json_data(void *f, const char *data, size_t size) {
|
||||
// ((go_fuzz_json_data_fn)f)(data, size);
|
||||
// }
|
||||
//
|
||||
// typedef void (*go_fuzz_flush_fn)(void);
|
||||
// void
|
||||
// go_fuzz_flush(void *f) {
|
||||
// ((go_fuzz_flush_fn)f)();
|
||||
// }
|
||||
//
|
||||
// typedef uint64_t (*go_fuzz_get_random_fn)(void);
|
||||
// uint64_t
|
||||
// go_fuzz_get_random(void *f) {
|
||||
// return ((go_fuzz_get_random_fn)f)();
|
||||
// }
|
||||
//
|
||||
// typedef bool (*go_notify_coverage_fn)(size_t);
|
||||
// int
|
||||
// go_notify_coverage(void *f, size_t edges) {
|
||||
// bool b = ((go_notify_coverage_fn)f)(edges);
|
||||
// return b ? 1 : 0;
|
||||
// }
|
||||
//
|
||||
// typedef uint64_t (*go_init_coverage_fn)(size_t num_edges, const char *symbols);
|
||||
// uint64_t
|
||||
// go_init_coverage(void *f, size_t num_edges, const char *symbols) {
|
||||
// return ((go_init_coverage_fn)f)(num_edges, symbols);
|
||||
// }
|
||||
//
|
||||
import "C"
|
||||
|
||||
const (
|
||||
defaultNativeLibraryPath = "/usr/lib/libvoidstar.so"
|
||||
)
|
||||
|
||||
type voidstarHandler struct {
|
||||
fuzzJsonData unsafe.Pointer
|
||||
fuzzFlush unsafe.Pointer
|
||||
fuzzGetRandom unsafe.Pointer
|
||||
initCoverage unsafe.Pointer
|
||||
notifyCoverage unsafe.Pointer
|
||||
}
|
||||
|
||||
func (h *voidstarHandler) output(message string) {
|
||||
msg_len := len(message)
|
||||
if msg_len == 0 {
|
||||
return
|
||||
}
|
||||
cstrMessage := C.CString(message)
|
||||
defer C.free(unsafe.Pointer(cstrMessage))
|
||||
C.go_fuzz_json_data(h.fuzzJsonData, cstrMessage, C.ulong(msg_len))
|
||||
C.go_fuzz_flush(h.fuzzFlush)
|
||||
}
|
||||
|
||||
func (h *voidstarHandler) random() uint64 {
|
||||
return uint64(C.go_fuzz_get_random(h.fuzzGetRandom))
|
||||
}
|
||||
|
||||
func (h *voidstarHandler) init_coverage(num_edge uint64, symbols string) uint64 {
|
||||
cstrSymbols := C.CString(symbols)
|
||||
defer C.free(unsafe.Pointer(cstrSymbols))
|
||||
return uint64(C.go_init_coverage(h.initCoverage, C.ulong(num_edge), cstrSymbols))
|
||||
}
|
||||
|
||||
func (h *voidstarHandler) notify(edge uint64) bool {
|
||||
ival := int(C.go_notify_coverage(h.notifyCoverage, C.ulong(edge)))
|
||||
return ival == 1
|
||||
}
|
||||
|
||||
// Attempt to load libvoidstar and some symbols from `path`
|
||||
func openSharedLib(path string) (*voidstarHandler, error) {
|
||||
cstrPath := C.CString(path)
|
||||
defer C.free(unsafe.Pointer(cstrPath))
|
||||
|
||||
dlError := func(message string) error {
|
||||
return fmt.Errorf("%s: (%s)", message, C.GoString(C.dlerror()))
|
||||
}
|
||||
|
||||
sharedLib := C.dlopen(cstrPath, C.int(C.RTLD_NOW))
|
||||
if sharedLib == nil {
|
||||
return nil, dlError("Can not load the Antithesis native library")
|
||||
}
|
||||
|
||||
loadFunc := func(name string) (symbol unsafe.Pointer, err error) {
|
||||
cstrName := C.CString(name)
|
||||
defer C.free(unsafe.Pointer(cstrName))
|
||||
if symbol = C.dlsym(sharedLib, cstrName); symbol == nil {
|
||||
err = dlError(fmt.Sprintf("Can not access symbol %s", name))
|
||||
}
|
||||
return
|
||||
}
|
||||
|
||||
fuzzJsonData, err := loadFunc("fuzz_json_data")
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
fuzzFlush, err := loadFunc("fuzz_flush")
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
fuzzGetRandom, err := loadFunc("fuzz_get_random")
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
notifyCoverage, err := loadFunc("notify_coverage")
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
initCoverage, err := loadFunc("init_coverage_module")
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
return &voidstarHandler{fuzzJsonData, fuzzFlush, fuzzGetRandom, initCoverage, notifyCoverage}, nil
|
||||
}
|
||||
|
||||
// If we have a file at `defaultNativeLibraryPath`, we load the shared library
|
||||
// (and panic on any error encountered during load).
|
||||
func init_in_antithesis() libHandler {
|
||||
if _, err := os.Stat(defaultNativeLibraryPath); err == nil {
|
||||
handler, err := openSharedLib(defaultNativeLibraryPath)
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
return handler
|
||||
}
|
||||
return nil
|
||||
}
|
||||
Generated
Vendored
-7
@@ -1,7 +0,0 @@
|
||||
//go:build enable_antithesis_sdk && (!linux || !amd64 || !cgo)
|
||||
|
||||
package internal
|
||||
|
||||
func init_in_antithesis() libHandler {
|
||||
return nil
|
||||
}
|
||||
-202
@@ -1,202 +0,0 @@
|
||||
|
||||
Apache License
|
||||
Version 2.0, January 2004
|
||||
http://www.apache.org/licenses/
|
||||
|
||||
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
||||
|
||||
1. Definitions.
|
||||
|
||||
"License" shall mean the terms and conditions for use, reproduction,
|
||||
and distribution as defined by Sections 1 through 9 of this document.
|
||||
|
||||
"Licensor" shall mean the copyright owner or entity authorized by
|
||||
the copyright owner that is granting the License.
|
||||
|
||||
"Legal Entity" shall mean the union of the acting entity and all
|
||||
other entities that control, are controlled by, or are under common
|
||||
control with that entity. For the purposes of this definition,
|
||||
"control" means (i) the power, direct or indirect, to cause the
|
||||
direction or management of such entity, whether by contract or
|
||||
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
||||
outstanding shares, or (iii) beneficial ownership of such entity.
|
||||
|
||||
"You" (or "Your") shall mean an individual or Legal Entity
|
||||
exercising permissions granted by this License.
|
||||
|
||||
"Source" form shall mean the preferred form for making modifications,
|
||||
including but not limited to software source code, documentation
|
||||
source, and configuration files.
|
||||
|
||||
"Object" form shall mean any form resulting from mechanical
|
||||
transformation or translation of a Source form, including but
|
||||
not limited to compiled object code, generated documentation,
|
||||
and conversions to other media types.
|
||||
|
||||
"Work" shall mean the work of authorship, whether in Source or
|
||||
Object form, made available under the License, as indicated by a
|
||||
copyright notice that is included in or attached to the work
|
||||
(an example is provided in the Appendix below).
|
||||
|
||||
"Derivative Works" shall mean any work, whether in Source or Object
|
||||
form, that is based on (or derived from) the Work and for which the
|
||||
editorial revisions, annotations, elaborations, or other modifications
|
||||
represent, as a whole, an original work of authorship. For the purposes
|
||||
of this License, Derivative Works shall not include works that remain
|
||||
separable from, or merely link (or bind by name) to the interfaces of,
|
||||
the Work and Derivative Works thereof.
|
||||
|
||||
"Contribution" shall mean any work of authorship, including
|
||||
the original version of the Work and any modifications or additions
|
||||
to that Work or Derivative Works thereof, that is intentionally
|
||||
submitted to Licensor for inclusion in the Work by the copyright owner
|
||||
or by an individual or Legal Entity authorized to submit on behalf of
|
||||
the copyright owner. For the purposes of this definition, "submitted"
|
||||
means any form of electronic, verbal, or written communication sent
|
||||
to the Licensor or its representatives, including but not limited to
|
||||
communication on electronic mailing lists, source code control systems,
|
||||
and issue tracking systems that are managed by, or on behalf of, the
|
||||
Licensor for the purpose of discussing and improving the Work, but
|
||||
excluding communication that is conspicuously marked or otherwise
|
||||
designated in writing by the copyright owner as "Not a Contribution."
|
||||
|
||||
"Contributor" shall mean Licensor and any individual or Legal Entity
|
||||
on behalf of whom a Contribution has been received by Licensor and
|
||||
subsequently incorporated within the Work.
|
||||
|
||||
2. Grant of Copyright License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
copyright license to reproduce, prepare Derivative Works of,
|
||||
publicly display, publicly perform, sublicense, and distribute the
|
||||
Work and such Derivative Works in Source or Object form.
|
||||
|
||||
3. Grant of Patent License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
(except as stated in this section) patent license to make, have made,
|
||||
use, offer to sell, sell, import, and otherwise transfer the Work,
|
||||
where such license applies only to those patent claims licensable
|
||||
by such Contributor that are necessarily infringed by their
|
||||
Contribution(s) alone or by combination of their Contribution(s)
|
||||
with the Work to which such Contribution(s) was submitted. If You
|
||||
institute patent litigation against any entity (including a
|
||||
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
||||
or a Contribution incorporated within the Work constitutes direct
|
||||
or contributory patent infringement, then any patent licenses
|
||||
granted to You under this License for that Work shall terminate
|
||||
as of the date such litigation is filed.
|
||||
|
||||
4. Redistribution. You may reproduce and distribute copies of the
|
||||
Work or Derivative Works thereof in any medium, with or without
|
||||
modifications, and in Source or Object form, provided that You
|
||||
meet the following conditions:
|
||||
|
||||
(a) You must give any other recipients of the Work or
|
||||
Derivative Works a copy of this License; and
|
||||
|
||||
(b) You must cause any modified files to carry prominent notices
|
||||
stating that You changed the files; and
|
||||
|
||||
(c) You must retain, in the Source form of any Derivative Works
|
||||
that You distribute, all copyright, patent, trademark, and
|
||||
attribution notices from the Source form of the Work,
|
||||
excluding those notices that do not pertain to any part of
|
||||
the Derivative Works; and
|
||||
|
||||
(d) If the Work includes a "NOTICE" text file as part of its
|
||||
distribution, then any Derivative Works that You distribute must
|
||||
include a readable copy of the attribution notices contained
|
||||
within such NOTICE file, excluding those notices that do not
|
||||
pertain to any part of the Derivative Works, in at least one
|
||||
of the following places: within a NOTICE text file distributed
|
||||
as part of the Derivative Works; within the Source form or
|
||||
documentation, if provided along with the Derivative Works; or,
|
||||
within a display generated by the Derivative Works, if and
|
||||
wherever such third-party notices normally appear. The contents
|
||||
of the NOTICE file are for informational purposes only and
|
||||
do not modify the License. You may add Your own attribution
|
||||
notices within Derivative Works that You distribute, alongside
|
||||
or as an addendum to the NOTICE text from the Work, provided
|
||||
that such additional attribution notices cannot be construed
|
||||
as modifying the License.
|
||||
|
||||
You may add Your own copyright statement to Your modifications and
|
||||
may provide additional or different license terms and conditions
|
||||
for use, reproduction, or distribution of Your modifications, or
|
||||
for any such Derivative Works as a whole, provided Your use,
|
||||
reproduction, and distribution of the Work otherwise complies with
|
||||
the conditions stated in this License.
|
||||
|
||||
5. Submission of Contributions. Unless You explicitly state otherwise,
|
||||
any Contribution intentionally submitted for inclusion in the Work
|
||||
by You to the Licensor shall be under the terms and conditions of
|
||||
this License, without any additional terms or conditions.
|
||||
Notwithstanding the above, nothing herein shall supersede or modify
|
||||
the terms of any separate license agreement you may have executed
|
||||
with Licensor regarding such Contributions.
|
||||
|
||||
6. Trademarks. This License does not grant permission to use the trade
|
||||
names, trademarks, service marks, or product names of the Licensor,
|
||||
except as required for reasonable and customary use in describing the
|
||||
origin of the Work and reproducing the content of the NOTICE file.
|
||||
|
||||
7. Disclaimer of Warranty. Unless required by applicable law or
|
||||
agreed to in writing, Licensor provides the Work (and each
|
||||
Contributor provides its Contributions) on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
||||
implied, including, without limitation, any warranties or conditions
|
||||
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
||||
PARTICULAR PURPOSE. You are solely responsible for determining the
|
||||
appropriateness of using or redistributing the Work and assume any
|
||||
risks associated with Your exercise of permissions under this License.
|
||||
|
||||
8. Limitation of Liability. In no event and under no legal theory,
|
||||
whether in tort (including negligence), contract, or otherwise,
|
||||
unless required by applicable law (such as deliberate and grossly
|
||||
negligent acts) or agreed to in writing, shall any Contributor be
|
||||
liable to You for damages, including any direct, indirect, special,
|
||||
incidental, or consequential damages of any character arising as a
|
||||
result of this License or out of the use or inability to use the
|
||||
Work (including but not limited to damages for loss of goodwill,
|
||||
work stoppage, computer failure or malfunction, or any and all
|
||||
other commercial damages or losses), even if such Contributor
|
||||
has been advised of the possibility of such damages.
|
||||
|
||||
9. Accepting Warranty or Additional Liability. While redistributing
|
||||
the Work or Derivative Works thereof, You may choose to offer,
|
||||
and charge a fee for, acceptance of support, warranty, indemnity,
|
||||
or other liability obligations and/or rights consistent with this
|
||||
License. However, in accepting such obligations, You may act only
|
||||
on Your own behalf and on Your sole responsibility, not on behalf
|
||||
of any other Contributor, and only if You agree to indemnify,
|
||||
defend, and hold each Contributor harmless for any liability
|
||||
incurred by, or claims asserted against, such Contributor by reason
|
||||
of your accepting any such warranty or additional liability.
|
||||
|
||||
END OF TERMS AND CONDITIONS
|
||||
|
||||
APPENDIX: How to apply the Apache License to your work.
|
||||
|
||||
To apply the Apache License to your work, attach the following
|
||||
boilerplate notice, with the fields enclosed by brackets "[]"
|
||||
replaced with your own identifying information. (Don't include
|
||||
the brackets!) The text should be enclosed in the appropriate
|
||||
comment syntax for the file format. We also recommend that a
|
||||
file or class name and description of purpose be included on the
|
||||
same "printed page" as the copyright notice for easier
|
||||
identification within third-party archives.
|
||||
|
||||
Copyright [yyyy] [name of copyright owner]
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
Generated
Vendored
-35
@@ -1,35 +0,0 @@
|
||||
# TPM 2.0 client library
|
||||
|
||||
## Tests
|
||||
|
||||
This library contains unit tests in `github.com/google/go-tpm/tpm2`, which just
|
||||
tests that various encoding and error checking functions work correctly. It also
|
||||
contains more comprehensive integration tests in
|
||||
`github.com/google/go-tpm/tpm2/test`, which run actual commands on a TPM.
|
||||
|
||||
By default, these integration tests are run against the
|
||||
[`go-tpm-tools`](https://github.com/google/go-tpm-tools)
|
||||
simulator, which is baesed on the
|
||||
[Microsoft Reference TPM2 code](https://github.com/microsoft/ms-tpm-20-ref). To
|
||||
run both the unit and integration tests, run (in this directory)
|
||||
```bash
|
||||
go test . ./test
|
||||
```
|
||||
|
||||
These integration tests can also be run against a real TPM device. This is
|
||||
slightly more complex as the tests often need to be built as a normal user and
|
||||
then executed as root. For example,
|
||||
```bash
|
||||
# Build the test binary without running it
|
||||
go test -c github.com/google/go-tpm/tpm2/test
|
||||
# Execute the test binary as root
|
||||
sudo ./test.test --tpm-path=/dev/tpmrm0
|
||||
```
|
||||
On Linux, The `--tpm-path` causes the integration tests to be run against a
|
||||
real TPM located at that path (usually `/dev/tpmrm0` or `/dev/tpm0`). On Windows, the story is similar, execept that
|
||||
the `--use-tbs` flag is used instead.
|
||||
|
||||
Tip: if your TPM host is remote and you don't want to install Go on it, this
|
||||
same two-step process can be used. The test binary can be copied to a remote
|
||||
host and run without extra installation (as the test binary has very few
|
||||
*runtime* dependancies).
|
||||
Generated
Vendored
-576
@@ -1,576 +0,0 @@
|
||||
// Copyright (c) 2018, Google LLC All rights reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
package tpm2
|
||||
|
||||
import (
|
||||
"crypto"
|
||||
"crypto/elliptic"
|
||||
"fmt"
|
||||
"strings"
|
||||
|
||||
// Register the relevant hash implementations to prevent a runtime failure.
|
||||
_ "crypto/sha1"
|
||||
_ "crypto/sha256"
|
||||
_ "crypto/sha512"
|
||||
|
||||
"github.com/google/go-tpm/tpmutil"
|
||||
)
|
||||
|
||||
var hashInfo = []struct {
|
||||
alg Algorithm
|
||||
hash crypto.Hash
|
||||
}{
|
||||
{AlgSHA1, crypto.SHA1},
|
||||
{AlgSHA256, crypto.SHA256},
|
||||
{AlgSHA384, crypto.SHA384},
|
||||
{AlgSHA512, crypto.SHA512},
|
||||
{AlgSHA3_256, crypto.SHA3_256},
|
||||
{AlgSHA3_384, crypto.SHA3_384},
|
||||
{AlgSHA3_512, crypto.SHA3_512},
|
||||
}
|
||||
|
||||
// MAX_DIGEST_BUFFER is the maximum size of []byte request or response fields.
|
||||
// Typically used for chunking of big blobs of data (such as for hashing or
|
||||
// encryption).
|
||||
const maxDigestBuffer = 1024
|
||||
|
||||
// Algorithm represents a TPM_ALG_ID value.
|
||||
type Algorithm uint16
|
||||
|
||||
// HashToAlgorithm looks up the TPM2 algorithm corresponding to the provided crypto.Hash
|
||||
func HashToAlgorithm(hash crypto.Hash) (Algorithm, error) {
|
||||
for _, info := range hashInfo {
|
||||
if info.hash == hash {
|
||||
return info.alg, nil
|
||||
}
|
||||
}
|
||||
return AlgUnknown, fmt.Errorf("go hash algorithm #%d has no TPM2 algorithm", hash)
|
||||
}
|
||||
|
||||
// IsNull returns true if a is AlgNull or zero (unset).
|
||||
func (a Algorithm) IsNull() bool {
|
||||
return a == AlgNull || a == AlgUnknown
|
||||
}
|
||||
|
||||
// UsesCount returns true if a signature algorithm uses count value.
|
||||
func (a Algorithm) UsesCount() bool {
|
||||
return a == AlgECDAA
|
||||
}
|
||||
|
||||
// UsesHash returns true if the algorithm requires the use of a hash.
|
||||
func (a Algorithm) UsesHash() bool {
|
||||
return a == AlgOAEP
|
||||
}
|
||||
|
||||
// Hash returns a crypto.Hash based on the given TPM_ALG_ID.
|
||||
// An error is returned if the given algorithm is not a hash algorithm or is not available.
|
||||
func (a Algorithm) Hash() (crypto.Hash, error) {
|
||||
for _, info := range hashInfo {
|
||||
if info.alg == a {
|
||||
if !info.hash.Available() {
|
||||
return crypto.Hash(0), fmt.Errorf("go hash algorithm #%d not available", info.hash)
|
||||
}
|
||||
return info.hash, nil
|
||||
}
|
||||
}
|
||||
return crypto.Hash(0), fmt.Errorf("hash algorithm not supported: 0x%x", a)
|
||||
}
|
||||
|
||||
func (a Algorithm) String() string {
|
||||
var s strings.Builder
|
||||
var err error
|
||||
switch a {
|
||||
case AlgUnknown:
|
||||
_, err = s.WriteString("AlgUnknown")
|
||||
case AlgRSA:
|
||||
_, err = s.WriteString("RSA")
|
||||
case AlgSHA1:
|
||||
_, err = s.WriteString("SHA1")
|
||||
case AlgHMAC:
|
||||
_, err = s.WriteString("HMAC")
|
||||
case AlgAES:
|
||||
_, err = s.WriteString("AES")
|
||||
case AlgKeyedHash:
|
||||
_, err = s.WriteString("KeyedHash")
|
||||
case AlgXOR:
|
||||
_, err = s.WriteString("XOR")
|
||||
case AlgSHA256:
|
||||
_, err = s.WriteString("SHA256")
|
||||
case AlgSHA384:
|
||||
_, err = s.WriteString("SHA384")
|
||||
case AlgSHA512:
|
||||
_, err = s.WriteString("SHA512")
|
||||
case AlgNull:
|
||||
_, err = s.WriteString("AlgNull")
|
||||
case AlgRSASSA:
|
||||
_, err = s.WriteString("RSASSA")
|
||||
case AlgRSAES:
|
||||
_, err = s.WriteString("RSAES")
|
||||
case AlgRSAPSS:
|
||||
_, err = s.WriteString("RSAPSS")
|
||||
case AlgOAEP:
|
||||
_, err = s.WriteString("OAEP")
|
||||
case AlgECDSA:
|
||||
_, err = s.WriteString("ECDSA")
|
||||
case AlgECDH:
|
||||
_, err = s.WriteString("ECDH")
|
||||
case AlgECDAA:
|
||||
_, err = s.WriteString("ECDAA")
|
||||
case AlgKDF2:
|
||||
_, err = s.WriteString("KDF2")
|
||||
case AlgECC:
|
||||
_, err = s.WriteString("ECC")
|
||||
case AlgSymCipher:
|
||||
_, err = s.WriteString("SymCipher")
|
||||
case AlgSHA3_256:
|
||||
_, err = s.WriteString("SHA3_256")
|
||||
case AlgSHA3_384:
|
||||
_, err = s.WriteString("SHA3_384")
|
||||
case AlgSHA3_512:
|
||||
_, err = s.WriteString("SHA3_512")
|
||||
case AlgCTR:
|
||||
_, err = s.WriteString("CTR")
|
||||
case AlgOFB:
|
||||
_, err = s.WriteString("OFB")
|
||||
case AlgCBC:
|
||||
_, err = s.WriteString("CBC")
|
||||
case AlgCFB:
|
||||
_, err = s.WriteString("CFB")
|
||||
case AlgECB:
|
||||
_, err = s.WriteString("ECB")
|
||||
default:
|
||||
return fmt.Sprintf("Alg?<%d>", int(a))
|
||||
}
|
||||
if err != nil {
|
||||
return fmt.Sprintf("Writing to string builder failed: %v", err)
|
||||
}
|
||||
return s.String()
|
||||
}
|
||||
|
||||
// Supported Algorithms.
|
||||
const (
|
||||
AlgUnknown Algorithm = 0x0000
|
||||
AlgRSA Algorithm = 0x0001
|
||||
AlgSHA1 Algorithm = 0x0004
|
||||
AlgHMAC Algorithm = 0x0005
|
||||
AlgAES Algorithm = 0x0006
|
||||
AlgKeyedHash Algorithm = 0x0008
|
||||
AlgXOR Algorithm = 0x000A
|
||||
AlgSHA256 Algorithm = 0x000B
|
||||
AlgSHA384 Algorithm = 0x000C
|
||||
AlgSHA512 Algorithm = 0x000D
|
||||
AlgNull Algorithm = 0x0010
|
||||
AlgRSASSA Algorithm = 0x0014
|
||||
AlgRSAES Algorithm = 0x0015
|
||||
AlgRSAPSS Algorithm = 0x0016
|
||||
AlgOAEP Algorithm = 0x0017
|
||||
AlgECDSA Algorithm = 0x0018
|
||||
AlgECDH Algorithm = 0x0019
|
||||
AlgECDAA Algorithm = 0x001A
|
||||
AlgKDF2 Algorithm = 0x0021
|
||||
AlgECC Algorithm = 0x0023
|
||||
AlgSymCipher Algorithm = 0x0025
|
||||
AlgSHA3_256 Algorithm = 0x0027
|
||||
AlgSHA3_384 Algorithm = 0x0028
|
||||
AlgSHA3_512 Algorithm = 0x0029
|
||||
AlgCTR Algorithm = 0x0040
|
||||
AlgOFB Algorithm = 0x0041
|
||||
AlgCBC Algorithm = 0x0042
|
||||
AlgCFB Algorithm = 0x0043
|
||||
AlgECB Algorithm = 0x0044
|
||||
)
|
||||
|
||||
// HandleType defines a type of handle.
|
||||
type HandleType uint8
|
||||
|
||||
// Supported handle types
|
||||
const (
|
||||
HandleTypePCR HandleType = 0x00
|
||||
HandleTypeNVIndex HandleType = 0x01
|
||||
HandleTypeHMACSession HandleType = 0x02
|
||||
HandleTypeLoadedSession HandleType = 0x02
|
||||
HandleTypePolicySession HandleType = 0x03
|
||||
HandleTypeSavedSession HandleType = 0x03
|
||||
HandleTypePermanent HandleType = 0x40
|
||||
HandleTypeTransient HandleType = 0x80
|
||||
HandleTypePersistent HandleType = 0x81
|
||||
)
|
||||
|
||||
// SessionType defines the type of session created in StartAuthSession.
|
||||
type SessionType uint8
|
||||
|
||||
// Supported session types.
|
||||
const (
|
||||
SessionHMAC SessionType = 0x00
|
||||
SessionPolicy SessionType = 0x01
|
||||
SessionTrial SessionType = 0x03
|
||||
)
|
||||
|
||||
// SessionAttributes represents an attribute of a session.
|
||||
type SessionAttributes byte
|
||||
|
||||
// Session Attributes (Structures 8.4 TPMA_SESSION)
|
||||
const (
|
||||
AttrContinueSession SessionAttributes = 1 << iota
|
||||
AttrAuditExclusive
|
||||
AttrAuditReset
|
||||
_ // bit 3 reserved
|
||||
_ // bit 4 reserved
|
||||
AttrDecrypt
|
||||
AttrEcrypt
|
||||
AttrAudit
|
||||
)
|
||||
|
||||
// EmptyAuth represents the empty authorization value.
|
||||
var EmptyAuth []byte
|
||||
|
||||
// KeyProp is a bitmask used in Attributes field of key templates. Individual
|
||||
// flags should be OR-ed to form a full mask.
|
||||
type KeyProp uint32
|
||||
|
||||
// Key properties.
|
||||
const (
|
||||
FlagFixedTPM KeyProp = 0x00000002
|
||||
FlagStClear KeyProp = 0x00000004
|
||||
FlagFixedParent KeyProp = 0x00000010
|
||||
FlagSensitiveDataOrigin KeyProp = 0x00000020
|
||||
FlagUserWithAuth KeyProp = 0x00000040
|
||||
FlagAdminWithPolicy KeyProp = 0x00000080
|
||||
FlagNoDA KeyProp = 0x00000400
|
||||
FlagRestricted KeyProp = 0x00010000
|
||||
FlagDecrypt KeyProp = 0x00020000
|
||||
FlagSign KeyProp = 0x00040000
|
||||
|
||||
FlagSealDefault = FlagFixedTPM | FlagFixedParent
|
||||
FlagSignerDefault = FlagSign | FlagRestricted | FlagFixedTPM |
|
||||
FlagFixedParent | FlagSensitiveDataOrigin | FlagUserWithAuth
|
||||
FlagStorageDefault = FlagDecrypt | FlagRestricted | FlagFixedTPM |
|
||||
FlagFixedParent | FlagSensitiveDataOrigin | FlagUserWithAuth
|
||||
)
|
||||
|
||||
// TPMProp represents a Property Tag (TPM_PT) used with calls to GetCapability(CapabilityTPMProperties).
|
||||
type TPMProp uint32
|
||||
|
||||
// TPM Capability Properties, see TPM 2.0 Spec, Rev 1.38, Table 23.
|
||||
// Fixed TPM Properties (PT_FIXED)
|
||||
const (
|
||||
FamilyIndicator TPMProp = 0x100 + iota
|
||||
SpecLevel
|
||||
SpecRevision
|
||||
SpecDayOfYear
|
||||
SpecYear
|
||||
Manufacturer
|
||||
VendorString1
|
||||
VendorString2
|
||||
VendorString3
|
||||
VendorString4
|
||||
VendorTPMType
|
||||
FirmwareVersion1
|
||||
FirmwareVersion2
|
||||
InputMaxBufferSize
|
||||
TransientObjectsMin
|
||||
PersistentObjectsMin
|
||||
LoadedObjectsMin
|
||||
ActiveSessionsMax
|
||||
PCRCount
|
||||
PCRSelectMin
|
||||
ContextGapMax
|
||||
_ // (PT_FIXED + 21) is skipped
|
||||
NVCountersMax
|
||||
NVIndexMax
|
||||
MemoryMethod
|
||||
ClockUpdate
|
||||
ContextHash
|
||||
ContextSym
|
||||
ContextSymSize
|
||||
OrderlyCount
|
||||
CommandMaxSize
|
||||
ResponseMaxSize
|
||||
DigestMaxSize
|
||||
ObjectContextMaxSize
|
||||
SessionContextMaxSize
|
||||
PSFamilyIndicator
|
||||
PSSpecLevel
|
||||
PSSpecRevision
|
||||
PSSpecDayOfYear
|
||||
PSSpecYear
|
||||
SplitSigningMax
|
||||
TotalCommands
|
||||
LibraryCommands
|
||||
VendorCommands
|
||||
NVMaxBufferSize
|
||||
TPMModes
|
||||
CapabilityMaxBufferSize
|
||||
)
|
||||
|
||||
// Variable TPM Properties (PT_VAR)
|
||||
const (
|
||||
TPMAPermanent TPMProp = 0x200 + iota
|
||||
TPMAStartupClear
|
||||
HRNVIndex
|
||||
HRLoaded
|
||||
HRLoadedAvail
|
||||
HRActive
|
||||
HRActiveAvail
|
||||
HRTransientAvail
|
||||
CurrentPersistent
|
||||
AvailPersistent
|
||||
NVCounters
|
||||
NVCountersAvail
|
||||
AlgorithmSet
|
||||
LoadedCurves
|
||||
LockoutCounter
|
||||
MaxAuthFail
|
||||
LockoutInterval
|
||||
LockoutRecovery
|
||||
NVWriteRecovery
|
||||
AuditCounter0
|
||||
AuditCounter1
|
||||
)
|
||||
|
||||
// Allowed ranges of different kinds of Handles (TPM_HANDLE)
|
||||
// These constants have type TPMProp for backwards compatibility.
|
||||
const (
|
||||
PCRFirst TPMProp = 0x00000000
|
||||
HMACSessionFirst TPMProp = 0x02000000
|
||||
LoadedSessionFirst TPMProp = 0x02000000
|
||||
PolicySessionFirst TPMProp = 0x03000000
|
||||
ActiveSessionFirst TPMProp = 0x03000000
|
||||
TransientFirst TPMProp = 0x80000000
|
||||
PersistentFirst TPMProp = 0x81000000
|
||||
PersistentLast TPMProp = 0x81FFFFFF
|
||||
PlatformPersistent TPMProp = 0x81800000
|
||||
NVIndexFirst TPMProp = 0x01000000
|
||||
NVIndexLast TPMProp = 0x01FFFFFF
|
||||
PermanentFirst TPMProp = 0x40000000
|
||||
PermanentLast TPMProp = 0x4000010F
|
||||
)
|
||||
|
||||
// Reserved Handles.
|
||||
const (
|
||||
HandleOwner tpmutil.Handle = 0x40000001 + iota
|
||||
HandleRevoke
|
||||
HandleTransport
|
||||
HandleOperator
|
||||
HandleAdmin
|
||||
HandleEK
|
||||
HandleNull
|
||||
HandleUnassigned
|
||||
HandlePasswordSession
|
||||
HandleLockout
|
||||
HandleEndorsement
|
||||
HandlePlatform
|
||||
)
|
||||
|
||||
// Capability identifies some TPM property or state type.
|
||||
type Capability uint32
|
||||
|
||||
// TPM Capabilities.
|
||||
const (
|
||||
CapabilityAlgs Capability = iota
|
||||
CapabilityHandles
|
||||
CapabilityCommands
|
||||
CapabilityPPCommands
|
||||
CapabilityAuditCommands
|
||||
CapabilityPCRs
|
||||
CapabilityTPMProperties
|
||||
CapabilityPCRProperties
|
||||
CapabilityECCCurves
|
||||
CapabilityAuthPolicies
|
||||
)
|
||||
|
||||
// TPM Structure Tags. Tags are used to disambiguate structures, similar to Alg
|
||||
// values: tag value defines what kind of data lives in a nested field.
|
||||
const (
|
||||
TagNull tpmutil.Tag = 0x8000
|
||||
TagNoSessions tpmutil.Tag = 0x8001
|
||||
TagSessions tpmutil.Tag = 0x8002
|
||||
TagAttestCertify tpmutil.Tag = 0x8017
|
||||
TagAttestQuote tpmutil.Tag = 0x8018
|
||||
TagAttestCreation tpmutil.Tag = 0x801a
|
||||
TagAuthSecret tpmutil.Tag = 0x8023
|
||||
TagHashCheck tpmutil.Tag = 0x8024
|
||||
TagAuthSigned tpmutil.Tag = 0x8025
|
||||
)
|
||||
|
||||
// StartupType instructs the TPM on how to handle its state during Shutdown or
|
||||
// Startup.
|
||||
type StartupType uint16
|
||||
|
||||
// Startup types
|
||||
const (
|
||||
StartupClear StartupType = iota
|
||||
StartupState
|
||||
)
|
||||
|
||||
// EllipticCurve identifies specific EC curves.
|
||||
type EllipticCurve uint16
|
||||
|
||||
// ECC curves supported by TPM 2.0 spec.
|
||||
const (
|
||||
CurveNISTP192 = EllipticCurve(iota + 1)
|
||||
CurveNISTP224
|
||||
CurveNISTP256
|
||||
CurveNISTP384
|
||||
CurveNISTP521
|
||||
|
||||
CurveBNP256 = EllipticCurve(iota + 10)
|
||||
CurveBNP638
|
||||
|
||||
CurveSM2P256 = EllipticCurve(0x0020)
|
||||
)
|
||||
|
||||
var toGoCurve = map[EllipticCurve]elliptic.Curve{
|
||||
CurveNISTP224: elliptic.P224(),
|
||||
CurveNISTP256: elliptic.P256(),
|
||||
CurveNISTP384: elliptic.P384(),
|
||||
CurveNISTP521: elliptic.P521(),
|
||||
}
|
||||
|
||||
// Supported TPM operations.
|
||||
const (
|
||||
CmdNVUndefineSpaceSpecial tpmutil.Command = 0x0000011F
|
||||
CmdEvictControl tpmutil.Command = 0x00000120
|
||||
CmdUndefineSpace tpmutil.Command = 0x00000122
|
||||
CmdClear tpmutil.Command = 0x00000126
|
||||
CmdHierarchyChangeAuth tpmutil.Command = 0x00000129
|
||||
CmdDefineSpace tpmutil.Command = 0x0000012A
|
||||
CmdPCRAllocate tpmutil.Command = 0x0000012B
|
||||
CmdCreatePrimary tpmutil.Command = 0x00000131
|
||||
CmdIncrementNVCounter tpmutil.Command = 0x00000134
|
||||
CmdWriteNV tpmutil.Command = 0x00000137
|
||||
CmdWriteLockNV tpmutil.Command = 0x00000138
|
||||
CmdDictionaryAttackLockReset tpmutil.Command = 0x00000139
|
||||
CmdDictionaryAttackParameters tpmutil.Command = 0x0000013A
|
||||
CmdPCREvent tpmutil.Command = 0x0000013C
|
||||
CmdPCRReset tpmutil.Command = 0x0000013D
|
||||
CmdSequenceComplete tpmutil.Command = 0x0000013E
|
||||
CmdStartup tpmutil.Command = 0x00000144
|
||||
CmdShutdown tpmutil.Command = 0x00000145
|
||||
CmdActivateCredential tpmutil.Command = 0x00000147
|
||||
CmdCertify tpmutil.Command = 0x00000148
|
||||
CmdCertifyCreation tpmutil.Command = 0x0000014A
|
||||
CmdReadNV tpmutil.Command = 0x0000014E
|
||||
CmdReadLockNV tpmutil.Command = 0x0000014F
|
||||
CmdPolicySecret tpmutil.Command = 0x00000151
|
||||
CmdCreate tpmutil.Command = 0x00000153
|
||||
CmdECDHZGen tpmutil.Command = 0x00000154
|
||||
CmdImport tpmutil.Command = 0x00000156
|
||||
CmdLoad tpmutil.Command = 0x00000157
|
||||
CmdQuote tpmutil.Command = 0x00000158
|
||||
CmdRSADecrypt tpmutil.Command = 0x00000159
|
||||
CmdSequenceUpdate tpmutil.Command = 0x0000015C
|
||||
CmdSign tpmutil.Command = 0x0000015D
|
||||
CmdUnseal tpmutil.Command = 0x0000015E
|
||||
CmdPolicySigned tpmutil.Command = 0x00000160
|
||||
CmdContextLoad tpmutil.Command = 0x00000161
|
||||
CmdContextSave tpmutil.Command = 0x00000162
|
||||
CmdECDHKeyGen tpmutil.Command = 0x00000163
|
||||
CmdEncryptDecrypt tpmutil.Command = 0x00000164
|
||||
CmdFlushContext tpmutil.Command = 0x00000165
|
||||
CmdLoadExternal tpmutil.Command = 0x00000167
|
||||
CmdMakeCredential tpmutil.Command = 0x00000168
|
||||
CmdReadPublicNV tpmutil.Command = 0x00000169
|
||||
CmdPolicyCommandCode tpmutil.Command = 0x0000016C
|
||||
CmdPolicyOr tpmutil.Command = 0x00000171
|
||||
CmdReadPublic tpmutil.Command = 0x00000173
|
||||
CmdRSAEncrypt tpmutil.Command = 0x00000174
|
||||
CmdStartAuthSession tpmutil.Command = 0x00000176
|
||||
CmdGetCapability tpmutil.Command = 0x0000017A
|
||||
CmdGetRandom tpmutil.Command = 0x0000017B
|
||||
CmdHash tpmutil.Command = 0x0000017D
|
||||
CmdPCRRead tpmutil.Command = 0x0000017E
|
||||
CmdPolicyPCR tpmutil.Command = 0x0000017F
|
||||
CmdReadClock tpmutil.Command = 0x00000181
|
||||
CmdPCRExtend tpmutil.Command = 0x00000182
|
||||
CmdEventSequenceComplete tpmutil.Command = 0x00000185
|
||||
CmdHashSequenceStart tpmutil.Command = 0x00000186
|
||||
CmdPolicyGetDigest tpmutil.Command = 0x00000189
|
||||
CmdPolicyPassword tpmutil.Command = 0x0000018C
|
||||
CmdEncryptDecrypt2 tpmutil.Command = 0x00000193
|
||||
)
|
||||
|
||||
// Regular TPM 2.0 devices use 24-bit mask (3 bytes) for PCR selection.
|
||||
const sizeOfPCRSelect = 3
|
||||
|
||||
const defaultRSAExponent = 1<<16 + 1
|
||||
|
||||
// NVAttr is a bitmask used in Attributes field of NV indexes. Individual
|
||||
// flags should be OR-ed to form a full mask.
|
||||
type NVAttr uint32
|
||||
|
||||
// NV Attributes
|
||||
const (
|
||||
AttrPPWrite NVAttr = 0x00000001
|
||||
AttrOwnerWrite NVAttr = 0x00000002
|
||||
AttrAuthWrite NVAttr = 0x00000004
|
||||
AttrPolicyWrite NVAttr = 0x00000008
|
||||
AttrPolicyDelete NVAttr = 0x00000400
|
||||
AttrWriteLocked NVAttr = 0x00000800
|
||||
AttrWriteAll NVAttr = 0x00001000
|
||||
AttrWriteDefine NVAttr = 0x00002000
|
||||
AttrWriteSTClear NVAttr = 0x00004000
|
||||
AttrGlobalLock NVAttr = 0x00008000
|
||||
AttrPPRead NVAttr = 0x00010000
|
||||
AttrOwnerRead NVAttr = 0x00020000
|
||||
AttrAuthRead NVAttr = 0x00040000
|
||||
AttrPolicyRead NVAttr = 0x00080000
|
||||
AttrNoDA NVAttr = 0x02000000
|
||||
AttrOrderly NVAttr = 0x04000000
|
||||
AttrClearSTClear NVAttr = 0x08000000
|
||||
AttrReadLocked NVAttr = 0x10000000
|
||||
AttrWritten NVAttr = 0x20000000
|
||||
AttrPlatformCreate NVAttr = 0x40000000
|
||||
AttrReadSTClear NVAttr = 0x80000000
|
||||
)
|
||||
|
||||
var permMap = map[NVAttr]string{
|
||||
AttrPPWrite: "PPWrite",
|
||||
AttrOwnerWrite: "OwnerWrite",
|
||||
AttrAuthWrite: "AuthWrite",
|
||||
AttrPolicyWrite: "PolicyWrite",
|
||||
AttrPolicyDelete: "PolicyDelete",
|
||||
AttrWriteLocked: "WriteLocked",
|
||||
AttrWriteAll: "WriteAll",
|
||||
AttrWriteDefine: "WriteDefine",
|
||||
AttrWriteSTClear: "WriteSTClear",
|
||||
AttrGlobalLock: "GlobalLock",
|
||||
AttrPPRead: "PPRead",
|
||||
AttrOwnerRead: "OwnerRead",
|
||||
AttrAuthRead: "AuthRead",
|
||||
AttrPolicyRead: "PolicyRead",
|
||||
AttrNoDA: "No Do",
|
||||
AttrOrderly: "Oderly",
|
||||
AttrClearSTClear: "ClearSTClear",
|
||||
AttrReadLocked: "ReadLocked",
|
||||
AttrWritten: "Writte",
|
||||
AttrPlatformCreate: "PlatformCreate",
|
||||
AttrReadSTClear: "ReadSTClear",
|
||||
}
|
||||
|
||||
// String returns a textual representation of the set of NVAttr
|
||||
func (p NVAttr) String() string {
|
||||
var retString strings.Builder
|
||||
for iterator, item := range permMap {
|
||||
if (p & iterator) != 0 {
|
||||
retString.WriteString(item + " + ")
|
||||
}
|
||||
}
|
||||
if retString.String() == "" {
|
||||
return "Permission/s not found"
|
||||
}
|
||||
return strings.TrimSuffix(retString.String(), " + ")
|
||||
|
||||
}
|
||||
Generated
Vendored
-362
@@ -1,362 +0,0 @@
|
||||
package tpm2
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
|
||||
"github.com/google/go-tpm/tpmutil"
|
||||
)
|
||||
|
||||
type (
|
||||
// RCFmt0 holds Format 0 error codes
|
||||
RCFmt0 uint8
|
||||
|
||||
// RCFmt1 holds Format 1 error codes
|
||||
RCFmt1 uint8
|
||||
|
||||
// RCWarn holds error codes used in warnings
|
||||
RCWarn uint8
|
||||
|
||||
// RCIndex is used to reference arguments, handles and sessions in errors
|
||||
RCIndex uint8
|
||||
)
|
||||
|
||||
// Format 0 error codes.
|
||||
const (
|
||||
RCInitialize RCFmt0 = 0x00
|
||||
RCFailure RCFmt0 = 0x01
|
||||
RCSequence RCFmt0 = 0x03
|
||||
RCPrivate RCFmt0 = 0x0B
|
||||
RCHMAC RCFmt0 = 0x19
|
||||
RCDisabled RCFmt0 = 0x20
|
||||
RCExclusive RCFmt0 = 0x21
|
||||
RCAuthType RCFmt0 = 0x24
|
||||
RCAuthMissing RCFmt0 = 0x25
|
||||
RCPolicy RCFmt0 = 0x26
|
||||
RCPCR RCFmt0 = 0x27
|
||||
RCPCRChanged RCFmt0 = 0x28
|
||||
RCUpgrade RCFmt0 = 0x2D
|
||||
RCTooManyContexts RCFmt0 = 0x2E
|
||||
RCAuthUnavailable RCFmt0 = 0x2F
|
||||
RCReboot RCFmt0 = 0x30
|
||||
RCUnbalanced RCFmt0 = 0x31
|
||||
RCCommandSize RCFmt0 = 0x42
|
||||
RCCommandCode RCFmt0 = 0x43
|
||||
RCAuthSize RCFmt0 = 0x44
|
||||
RCAuthContext RCFmt0 = 0x45
|
||||
RCNVRange RCFmt0 = 0x46
|
||||
RCNVSize RCFmt0 = 0x47
|
||||
RCNVLocked RCFmt0 = 0x48
|
||||
RCNVAuthorization RCFmt0 = 0x49
|
||||
RCNVUninitialized RCFmt0 = 0x4A
|
||||
RCNVSpace RCFmt0 = 0x4B
|
||||
RCNVDefined RCFmt0 = 0x4C
|
||||
RCBadContext RCFmt0 = 0x50
|
||||
RCCPHash RCFmt0 = 0x51
|
||||
RCParent RCFmt0 = 0x52
|
||||
RCNeedsTest RCFmt0 = 0x53
|
||||
RCNoResult RCFmt0 = 0x54
|
||||
RCSensitive RCFmt0 = 0x55
|
||||
)
|
||||
|
||||
var fmt0Msg = map[RCFmt0]string{
|
||||
RCInitialize: "TPM not initialized by TPM2_Startup or already initialized",
|
||||
RCFailure: "commands not being accepted because of a TPM failure",
|
||||
RCSequence: "improper use of a sequence handle",
|
||||
RCPrivate: "not currently used",
|
||||
RCHMAC: "not currently used",
|
||||
RCDisabled: "the command is disabled",
|
||||
RCExclusive: "command failed because audit sequence required exclusivity",
|
||||
RCAuthType: "authorization handle is not correct for command",
|
||||
RCAuthMissing: "5 command requires an authorization session for handle and it is not present",
|
||||
RCPolicy: "policy failure in math operation or an invalid authPolicy value",
|
||||
RCPCR: "PCR check fail",
|
||||
RCPCRChanged: "PCR have changed since checked",
|
||||
RCUpgrade: "TPM is in field upgrade mode unless called via TPM2_FieldUpgradeData(), then it is not in field upgrade mode",
|
||||
RCTooManyContexts: "context ID counter is at maximum",
|
||||
RCAuthUnavailable: "authValue or authPolicy is not available for selected entity",
|
||||
RCReboot: "a _TPM_Init and Startup(CLEAR) is required before the TPM can resume operation",
|
||||
RCUnbalanced: "the protection algorithms (hash and symmetric) are not reasonably balanced; the digest size of the hash must be larger than the key size of the symmetric algorithm",
|
||||
RCCommandSize: "command commandSize value is inconsistent with contents of the command buffer; either the size is not the same as the octets loaded by the hardware interface layer or the value is not large enough to hold a command header",
|
||||
RCCommandCode: "command code not supported",
|
||||
RCAuthSize: "the value of authorizationSize is out of range or the number of octets in the Authorization Area is greater than required",
|
||||
RCAuthContext: "use of an authorization session with a context command or another command that cannot have an authorization session",
|
||||
RCNVRange: "NV offset+size is out of range",
|
||||
RCNVSize: "Requested allocation size is larger than allowed",
|
||||
RCNVLocked: "NV access locked",
|
||||
RCNVAuthorization: "NV access authorization fails in command actions",
|
||||
RCNVUninitialized: "an NV Index is used before being initialized or the state saved by TPM2_Shutdown(STATE) could not be restored",
|
||||
RCNVSpace: "insufficient space for NV allocation",
|
||||
RCNVDefined: "NV Index or persistent object already defined",
|
||||
RCBadContext: "context in TPM2_ContextLoad() is not valid",
|
||||
RCCPHash: "cpHash value already set or not correct for use",
|
||||
RCParent: "handle for parent is not a valid parent",
|
||||
RCNeedsTest: "some function needs testing",
|
||||
RCNoResult: "returned when an internal function cannot process a request due to an unspecified problem; this code is usually related to invalid parameters that are not properly filtered by the input unmarshaling code",
|
||||
RCSensitive: "the sensitive area did not unmarshal correctly after decryption",
|
||||
}
|
||||
|
||||
// Format 1 error codes.
|
||||
const (
|
||||
RCAsymmetric = 0x01
|
||||
RCAttributes = 0x02
|
||||
RCHash = 0x03
|
||||
RCValue = 0x04
|
||||
RCHierarchy = 0x05
|
||||
RCKeySize = 0x07
|
||||
RCMGF = 0x08
|
||||
RCMode = 0x09
|
||||
RCType = 0x0A
|
||||
RCHandle = 0x0B
|
||||
RCKDF = 0x0C
|
||||
RCRange = 0x0D
|
||||
RCAuthFail = 0x0E
|
||||
RCNonce = 0x0F
|
||||
RCPP = 0x10
|
||||
RCScheme = 0x12
|
||||
RCSize = 0x15
|
||||
RCSymmetric = 0x16
|
||||
RCTag = 0x17
|
||||
RCSelector = 0x18
|
||||
RCInsufficient = 0x1A
|
||||
RCSignature = 0x1B
|
||||
RCKey = 0x1C
|
||||
RCPolicyFail = 0x1D
|
||||
RCIntegrity = 0x1F
|
||||
RCTicket = 0x20
|
||||
RCReservedBits = 0x21
|
||||
RCBadAuth = 0x22
|
||||
RCExpired = 0x23
|
||||
RCPolicyCC = 0x24
|
||||
RCBinding = 0x25
|
||||
RCCurve = 0x26
|
||||
RCECCPoint = 0x27
|
||||
)
|
||||
|
||||
var fmt1Msg = map[RCFmt1]string{
|
||||
RCAsymmetric: "asymmetric algorithm not supported or not correct",
|
||||
RCAttributes: "inconsistent attributes",
|
||||
RCHash: "hash algorithm not supported or not appropriate",
|
||||
RCValue: "value is out of range or is not correct for the context",
|
||||
RCHierarchy: "hierarchy is not enabled or is not correct for the use",
|
||||
RCKeySize: "key size is not supported",
|
||||
RCMGF: "mask generation function not supported",
|
||||
RCMode: "mode of operation not supported",
|
||||
RCType: "the type of the value is not appropriate for the use",
|
||||
RCHandle: "the handle is not correct for the use",
|
||||
RCKDF: "unsupported key derivation function or function not appropriate for use",
|
||||
RCRange: "value was out of allowed range",
|
||||
RCAuthFail: "the authorization HMAC check failed and DA counter incremented",
|
||||
RCNonce: "invalid nonce size or nonce value mismatch",
|
||||
RCPP: "authorization requires assertion of PP",
|
||||
RCScheme: "unsupported or incompatible scheme",
|
||||
RCSize: "structure is the wrong size",
|
||||
RCSymmetric: "unsupported symmetric algorithm or key size, or not appropriate for instance",
|
||||
RCTag: "incorrect structure tag",
|
||||
RCSelector: "union selector is incorrect",
|
||||
RCInsufficient: "the TPM was unable to unmarshal a value because there were not enough octets in the input buffer",
|
||||
RCSignature: "the signature is not valid",
|
||||
RCKey: "key fields are not compatible with the selected use",
|
||||
RCPolicyFail: "a policy check failed",
|
||||
RCIntegrity: "integrity check failed",
|
||||
RCTicket: "invalid ticket",
|
||||
RCReservedBits: "reserved bits not set to zero as required",
|
||||
RCBadAuth: "authorization failure without DA implications",
|
||||
RCExpired: "the policy has expired",
|
||||
RCPolicyCC: "the commandCode in the policy is not the commandCode of the command or the command code in a policy command references a command that is not implemented",
|
||||
RCBinding: "public and sensitive portions of an object are not cryptographically bound",
|
||||
RCCurve: "curve not supported",
|
||||
RCECCPoint: "point is not on the required curve",
|
||||
}
|
||||
|
||||
// Warning codes.
|
||||
const (
|
||||
RCContextGap RCWarn = 0x01
|
||||
RCObjectMemory RCWarn = 0x02
|
||||
RCSessionMemory RCWarn = 0x03
|
||||
RCMemory RCWarn = 0x04
|
||||
RCSessionHandles RCWarn = 0x05
|
||||
RCObjectHandles RCWarn = 0x06
|
||||
RCLocality RCWarn = 0x07
|
||||
RCYielded RCWarn = 0x08
|
||||
RCCanceled RCWarn = 0x09
|
||||
RCTesting RCWarn = 0x0A
|
||||
RCReferenceH0 RCWarn = 0x10
|
||||
RCReferenceH1 RCWarn = 0x11
|
||||
RCReferenceH2 RCWarn = 0x12
|
||||
RCReferenceH3 RCWarn = 0x13
|
||||
RCReferenceH4 RCWarn = 0x14
|
||||
RCReferenceH5 RCWarn = 0x15
|
||||
RCReferenceH6 RCWarn = 0x16
|
||||
RCReferenceS0 RCWarn = 0x18
|
||||
RCReferenceS1 RCWarn = 0x19
|
||||
RCReferenceS2 RCWarn = 0x1A
|
||||
RCReferenceS3 RCWarn = 0x1B
|
||||
RCReferenceS4 RCWarn = 0x1C
|
||||
RCReferenceS5 RCWarn = 0x1D
|
||||
RCReferenceS6 RCWarn = 0x1E
|
||||
RCNVRate RCWarn = 0x20
|
||||
RCLockout RCWarn = 0x21
|
||||
RCRetry RCWarn = 0x22
|
||||
RCNVUnavailable RCWarn = 0x23
|
||||
)
|
||||
|
||||
var warnMsg = map[RCWarn]string{
|
||||
RCContextGap: "gap for context ID is too large",
|
||||
RCObjectMemory: "out of memory for object contexts",
|
||||
RCSessionMemory: "out of memory for session contexts",
|
||||
RCMemory: "out of shared object/session memory or need space for internal operations",
|
||||
RCSessionHandles: "out of session handles",
|
||||
RCObjectHandles: "out of object handles",
|
||||
RCLocality: "bad locality",
|
||||
RCYielded: "the TPM has suspended operation on the command; forward progress was made and the command may be retried",
|
||||
RCCanceled: "the command was canceled",
|
||||
RCTesting: "TPM is performing self-tests",
|
||||
RCReferenceH0: "the 1st handle in the handle area references a transient object or session that is not loaded",
|
||||
RCReferenceH1: "the 2nd handle in the handle area references a transient object or session that is not loaded",
|
||||
RCReferenceH2: "the 3rd handle in the handle area references a transient object or session that is not loaded",
|
||||
RCReferenceH3: "the 4th handle in the handle area references a transient object or session that is not loaded",
|
||||
RCReferenceH4: "the 5th handle in the handle area references a transient object or session that is not loaded",
|
||||
RCReferenceH5: "the 6th handle in the handle area references a transient object or session that is not loaded",
|
||||
RCReferenceH6: "the 7th handle in the handle area references a transient object or session that is not loaded",
|
||||
RCReferenceS0: "the 1st authorization session handle references a session that is not loaded",
|
||||
RCReferenceS1: "the 2nd authorization session handle references a session that is not loaded",
|
||||
RCReferenceS2: "the 3rd authorization session handle references a session that is not loaded",
|
||||
RCReferenceS3: "the 4th authorization session handle references a session that is not loaded",
|
||||
RCReferenceS4: "the 5th authorization session handle references a session that is not loaded",
|
||||
RCReferenceS5: "the 6th authorization session handle references a session that is not loaded",
|
||||
RCReferenceS6: "the 7th authorization session handle references a session that is not loaded",
|
||||
RCNVRate: "the TPM is rate-limiting accesses to prevent wearout of NV",
|
||||
RCLockout: "authorizations for objects subject to DA protection are not allowed at this time because the TPM is in DA lockout mode",
|
||||
RCRetry: "the TPM was not able to start the command",
|
||||
RCNVUnavailable: "the command may require writing of NV and NV is not current accessible",
|
||||
}
|
||||
|
||||
// Indexes for arguments, handles and sessions.
|
||||
const (
|
||||
RC1 RCIndex = iota + 1
|
||||
RC2
|
||||
RC3
|
||||
RC4
|
||||
RC5
|
||||
RC6
|
||||
RC7
|
||||
RC8
|
||||
RC9
|
||||
RCA
|
||||
RCB
|
||||
RCC
|
||||
RCD
|
||||
RCE
|
||||
RCF
|
||||
)
|
||||
|
||||
const unknownCode = "unknown error code"
|
||||
|
||||
// Error is returned for all Format 0 errors from the TPM. It is used for general
|
||||
// errors not specific to a parameter, handle or session.
|
||||
type Error struct {
|
||||
Code RCFmt0
|
||||
}
|
||||
|
||||
func (e Error) Error() string {
|
||||
msg := fmt0Msg[e.Code]
|
||||
if msg == "" {
|
||||
msg = unknownCode
|
||||
}
|
||||
return fmt.Sprintf("error code 0x%x : %s", e.Code, msg)
|
||||
}
|
||||
|
||||
// VendorError represents a vendor-specific error response. These types of responses
|
||||
// are not decoded and Code contains the complete response code.
|
||||
type VendorError struct {
|
||||
Code uint32
|
||||
}
|
||||
|
||||
func (e VendorError) Error() string {
|
||||
return fmt.Sprintf("vendor error code 0x%x", e.Code)
|
||||
}
|
||||
|
||||
// Warning is typically used to report transient errors.
|
||||
type Warning struct {
|
||||
Code RCWarn
|
||||
}
|
||||
|
||||
func (w Warning) Error() string {
|
||||
msg := warnMsg[w.Code]
|
||||
if msg == "" {
|
||||
msg = unknownCode
|
||||
}
|
||||
return fmt.Sprintf("warning code 0x%x : %s", w.Code, msg)
|
||||
}
|
||||
|
||||
// ParameterError describes an error related to a parameter, and the parameter number.
|
||||
type ParameterError struct {
|
||||
Code RCFmt1
|
||||
Parameter RCIndex
|
||||
}
|
||||
|
||||
func (e ParameterError) Error() string {
|
||||
msg := fmt1Msg[e.Code]
|
||||
if msg == "" {
|
||||
msg = unknownCode
|
||||
}
|
||||
return fmt.Sprintf("parameter %d, error code 0x%x : %s", e.Parameter, e.Code, msg)
|
||||
}
|
||||
|
||||
// HandleError describes an error related to a handle, and the handle number.
|
||||
type HandleError struct {
|
||||
Code RCFmt1
|
||||
Handle RCIndex
|
||||
}
|
||||
|
||||
func (e HandleError) Error() string {
|
||||
msg := fmt1Msg[e.Code]
|
||||
if msg == "" {
|
||||
msg = unknownCode
|
||||
}
|
||||
return fmt.Sprintf("handle %d, error code 0x%x : %s", e.Handle, e.Code, msg)
|
||||
}
|
||||
|
||||
// SessionError describes an error related to a session, and the session number.
|
||||
type SessionError struct {
|
||||
Code RCFmt1
|
||||
Session RCIndex
|
||||
}
|
||||
|
||||
func (e SessionError) Error() string {
|
||||
msg := fmt1Msg[e.Code]
|
||||
if msg == "" {
|
||||
msg = unknownCode
|
||||
}
|
||||
return fmt.Sprintf("session %d, error code 0x%x : %s", e.Session, e.Code, msg)
|
||||
}
|
||||
|
||||
// Decode a TPM2 response code and return the appropriate error. Logic
|
||||
// according to the "Response Code Evaluation" chart in Part 1 of the TPM 2.0
|
||||
// spec.
|
||||
func decodeResponse(code tpmutil.ResponseCode) error {
|
||||
if code == tpmutil.RCSuccess {
|
||||
return nil
|
||||
}
|
||||
if code&0x180 == 0 { // Bits 7:8 == 0 is a TPM1 error
|
||||
return fmt.Errorf("response status 0x%x", code)
|
||||
}
|
||||
if code&0x80 == 0 { // Bit 7 unset
|
||||
if code&0x400 > 0 { // Bit 10 set, vendor specific code
|
||||
return VendorError{uint32(code)}
|
||||
}
|
||||
if code&0x800 > 0 { // Bit 11 set, warning with code in bit 0:6
|
||||
return Warning{RCWarn(code & 0x7f)}
|
||||
}
|
||||
// error with code in bit 0:6
|
||||
return Error{RCFmt0(code & 0x7f)}
|
||||
}
|
||||
if code&0x40 > 0 { // Bit 6 set, code in 0:5, parameter number in 8:11
|
||||
return ParameterError{RCFmt1(code & 0x3f), RCIndex((code & 0xf00) >> 8)}
|
||||
}
|
||||
if code&0x800 == 0 { // Bit 11 unset, code in 0:5, handle in 8:10
|
||||
return HandleError{RCFmt1(code & 0x3f), RCIndex((code & 0x700) >> 8)}
|
||||
}
|
||||
// Code in 0:5, Session in 8:10
|
||||
return SessionError{RCFmt1(code & 0x3f), RCIndex((code & 0x700) >> 8)}
|
||||
}
|
||||
Generated
Vendored
-116
@@ -1,116 +0,0 @@
|
||||
// Copyright (c) 2018, Google LLC All rights reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
package tpm2
|
||||
|
||||
import (
|
||||
"crypto"
|
||||
"crypto/hmac"
|
||||
"encoding/binary"
|
||||
"hash"
|
||||
)
|
||||
|
||||
// KDFa implements TPM 2.0's default key derivation function, as defined in
|
||||
// section 11.4.9.2 of the TPM revision 2 specification part 1.
|
||||
// See: https://trustedcomputinggroup.org/resource/tpm-library-specification/
|
||||
// The key & label parameters must not be zero length.
|
||||
// The label parameter is a non-null-terminated string.
|
||||
// The contextU & contextV parameters are optional.
|
||||
// Deprecated: Use KDFaHash.
|
||||
func KDFa(hashAlg Algorithm, key []byte, label string, contextU, contextV []byte, bits int) ([]byte, error) {
|
||||
h, err := hashAlg.Hash()
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
return KDFaHash(h, key, label, contextU, contextV, bits), nil
|
||||
}
|
||||
|
||||
// KDFe implements TPM 2.0's ECDH key derivation function, as defined in
|
||||
// section 11.4.9.3 of the TPM revision 2 specification part 1.
|
||||
// See: https://trustedcomputinggroup.org/resource/tpm-library-specification/
|
||||
// The z parameter is the x coordinate of one party's private ECC key multiplied
|
||||
// by the other party's public ECC point.
|
||||
// The use parameter is a non-null-terminated string.
|
||||
// The partyUInfo and partyVInfo are the x coordinates of the initiator's and
|
||||
// Deprecated: Use KDFeHash.
|
||||
func KDFe(hashAlg Algorithm, z []byte, use string, partyUInfo, partyVInfo []byte, bits int) ([]byte, error) {
|
||||
h, err := hashAlg.Hash()
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
return KDFeHash(h, z, use, partyUInfo, partyVInfo, bits), nil
|
||||
}
|
||||
|
||||
// KDFaHash implements TPM 2.0's default key derivation function, as defined in
|
||||
// section 11.4.9.2 of the TPM revision 2 specification part 1.
|
||||
// See: https://trustedcomputinggroup.org/resource/tpm-library-specification/
|
||||
// The key & label parameters must not be zero length.
|
||||
// The label parameter is a non-null-terminated string.
|
||||
// The contextU & contextV parameters are optional.
|
||||
func KDFaHash(h crypto.Hash, key []byte, label string, contextU, contextV []byte, bits int) []byte {
|
||||
mac := hmac.New(h.New, key)
|
||||
|
||||
out := kdf(mac, bits, func() {
|
||||
mac.Write([]byte(label))
|
||||
mac.Write([]byte{0}) // Terminating null character for C-string.
|
||||
mac.Write(contextU)
|
||||
mac.Write(contextV)
|
||||
binary.Write(mac, binary.BigEndian, uint32(bits))
|
||||
})
|
||||
return out
|
||||
}
|
||||
|
||||
// KDFeHash implements TPM 2.0's ECDH key derivation function, as defined in
|
||||
// section 11.4.9.3 of the TPM revision 2 specification part 1.
|
||||
// See: https://trustedcomputinggroup.org/resource/tpm-library-specification/
|
||||
// The z parameter is the x coordinate of one party's private ECC key multiplied
|
||||
// by the other party's public ECC point.
|
||||
// The use parameter is a non-null-terminated string.
|
||||
// The partyUInfo and partyVInfo are the x coordinates of the initiator's and
|
||||
// the responder's ECC points, respectively.
|
||||
func KDFeHash(h crypto.Hash, z []byte, use string, partyUInfo, partyVInfo []byte, bits int) []byte {
|
||||
hash := h.New()
|
||||
|
||||
out := kdf(hash, bits, func() {
|
||||
hash.Write(z)
|
||||
hash.Write([]byte(use))
|
||||
hash.Write([]byte{0}) // Terminating null character for C-string.
|
||||
hash.Write(partyUInfo)
|
||||
hash.Write(partyVInfo)
|
||||
})
|
||||
return out
|
||||
}
|
||||
|
||||
func kdf(h hash.Hash, bits int, update func()) []byte {
|
||||
bytes := (bits + 7) / 8
|
||||
out := []byte{}
|
||||
|
||||
for counter := 1; len(out) < bytes; counter++ {
|
||||
h.Reset()
|
||||
binary.Write(h, binary.BigEndian, uint32(counter))
|
||||
update()
|
||||
|
||||
out = h.Sum(out)
|
||||
}
|
||||
// out's length is a multiple of hash size, so there will be excess
|
||||
// bytes if bytes isn't a multiple of hash size.
|
||||
out = out[:bytes]
|
||||
|
||||
// As mentioned in the KDFa and KDFe specs mentioned above,
|
||||
// the unused bits of the most significant octet are masked off.
|
||||
if maskBits := uint8(bits % 8); maskBits > 0 {
|
||||
out[0] &= (1 << maskBits) - 1
|
||||
}
|
||||
return out
|
||||
}
|
||||
Generated
Vendored
-57
@@ -1,57 +0,0 @@
|
||||
//go:build !windows
|
||||
|
||||
// Copyright (c) 2019, Google LLC All rights reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
package tpm2
|
||||
|
||||
import (
|
||||
"errors"
|
||||
"fmt"
|
||||
"io"
|
||||
"os"
|
||||
|
||||
"github.com/google/go-tpm/tpmutil"
|
||||
)
|
||||
|
||||
// OpenTPM opens a channel to the TPM at the given path. If the file is a
|
||||
// device, then it treats it like a normal TPM device, and if the file is a
|
||||
// Unix domain socket, then it opens a connection to the socket.
|
||||
//
|
||||
// This function may also be invoked with no paths, as tpm2.OpenTPM(). In this
|
||||
// case, the default paths on Linux (/dev/tpmrm0 then /dev/tpm0), will be used.
|
||||
func OpenTPM(path ...string) (tpm io.ReadWriteCloser, err error) {
|
||||
switch len(path) {
|
||||
case 0:
|
||||
tpm, err = tpmutil.OpenTPM("/dev/tpmrm0")
|
||||
if errors.Is(err, os.ErrNotExist) {
|
||||
tpm, err = tpmutil.OpenTPM("/dev/tpm0")
|
||||
}
|
||||
case 1:
|
||||
tpm, err = tpmutil.OpenTPM(path[0])
|
||||
default:
|
||||
return nil, errors.New("cannot specify multiple paths to tpm2.OpenTPM")
|
||||
}
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
// Make sure this is a TPM 2.0
|
||||
_, err = GetManufacturer(tpm)
|
||||
if err != nil {
|
||||
tpm.Close()
|
||||
return nil, fmt.Errorf("open %s: device is not a TPM 2.0", path)
|
||||
}
|
||||
return tpm, nil
|
||||
}
|
||||
Generated
Vendored
-39
@@ -1,39 +0,0 @@
|
||||
//go:build windows
|
||||
|
||||
// Copyright (c) 2018, Google LLC All rights reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
package tpm2
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"io"
|
||||
|
||||
"github.com/google/go-tpm/tpmutil"
|
||||
"github.com/google/go-tpm/tpmutil/tbs"
|
||||
)
|
||||
|
||||
// OpenTPM opens a channel to the TPM.
|
||||
func OpenTPM() (io.ReadWriteCloser, error) {
|
||||
info, err := tbs.GetDeviceInfo()
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
if info.TPMVersion != tbs.TPMVersion20 {
|
||||
return nil, fmt.Errorf("openTPM: device is not a TPM 2.0")
|
||||
}
|
||||
|
||||
return tpmutil.OpenTPM()
|
||||
}
|
||||
Generated
Vendored
-1112
File diff suppressed because it is too large
Load Diff
Generated
Vendored
-2354
File diff suppressed because it is too large
Load Diff
Generated
Vendored
-211
@@ -1,211 +0,0 @@
|
||||
// Copyright (c) 2018, Google LLC All rights reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
package tpmutil
|
||||
|
||||
import (
|
||||
"bytes"
|
||||
"encoding/binary"
|
||||
"errors"
|
||||
"fmt"
|
||||
"io"
|
||||
"reflect"
|
||||
)
|
||||
|
||||
var (
|
||||
selfMarshalerType = reflect.TypeOf((*SelfMarshaler)(nil)).Elem()
|
||||
handlesAreaType = reflect.TypeOf((*[]Handle)(nil))
|
||||
)
|
||||
|
||||
// packWithHeader takes a header and a sequence of elements that are either of
|
||||
// fixed length or slices of fixed-length types and packs them into a single
|
||||
// byte array using binary.Write. It updates the CommandHeader to have the right
|
||||
// length.
|
||||
func packWithHeader(ch commandHeader, cmd ...interface{}) ([]byte, error) {
|
||||
hdrSize := binary.Size(ch)
|
||||
body, err := Pack(cmd...)
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("couldn't pack message body: %v", err)
|
||||
}
|
||||
bodySize := len(body)
|
||||
ch.Size = uint32(hdrSize + bodySize)
|
||||
header, err := Pack(ch)
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("couldn't pack message header: %v", err)
|
||||
}
|
||||
return append(header, body...), nil
|
||||
}
|
||||
|
||||
// Pack encodes a set of elements into a single byte array, using
|
||||
// encoding/binary. This means that all the elements must be encodeable
|
||||
// according to the rules of encoding/binary.
|
||||
//
|
||||
// It has one difference from encoding/binary: it encodes byte slices with a
|
||||
// prepended length, to match how the TPM encodes variable-length arrays. If
|
||||
// you wish to add a byte slice without length prefix, use RawBytes.
|
||||
func Pack(elts ...interface{}) ([]byte, error) {
|
||||
buf := new(bytes.Buffer)
|
||||
if err := packType(buf, elts...); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
return buf.Bytes(), nil
|
||||
}
|
||||
|
||||
// tryMarshal attempts to use a TPMMarshal() method defined on the type
|
||||
// to pack v into buf. True is returned if the method exists and the
|
||||
// marshal was attempted.
|
||||
func tryMarshal(buf io.Writer, v reflect.Value) (bool, error) {
|
||||
t := v.Type()
|
||||
if t.Implements(selfMarshalerType) {
|
||||
if v.Kind() == reflect.Ptr && v.IsNil() {
|
||||
return true, fmt.Errorf("cannot call TPMMarshal on a nil pointer of type %T", v)
|
||||
}
|
||||
return true, v.Interface().(SelfMarshaler).TPMMarshal(buf)
|
||||
}
|
||||
|
||||
// We might have a non-pointer struct field, but we dont have a
|
||||
// pointer with which to implement the interface.
|
||||
// If the pointer of the type implements the interface, we should be
|
||||
// able to construct a value to call TPMMarshal() with.
|
||||
// TODO(awly): Try and avoid blowing away private data by using Addr() instead of Set()
|
||||
if reflect.PtrTo(t).Implements(selfMarshalerType) {
|
||||
tmp := reflect.New(t)
|
||||
tmp.Elem().Set(v)
|
||||
return true, tmp.Interface().(SelfMarshaler).TPMMarshal(buf)
|
||||
}
|
||||
|
||||
return false, nil
|
||||
}
|
||||
|
||||
func packValue(buf io.Writer, v reflect.Value) error {
|
||||
if v.Type() == handlesAreaType {
|
||||
v = v.Convert(reflect.TypeOf((*handleList)(nil)))
|
||||
}
|
||||
if canMarshal, err := tryMarshal(buf, v); canMarshal {
|
||||
return err
|
||||
}
|
||||
|
||||
switch v.Kind() {
|
||||
case reflect.Ptr:
|
||||
if v.IsNil() {
|
||||
return fmt.Errorf("cannot pack nil %s", v.Type().String())
|
||||
}
|
||||
return packValue(buf, v.Elem())
|
||||
case reflect.Struct:
|
||||
for i := 0; i < v.NumField(); i++ {
|
||||
f := v.Field(i)
|
||||
if err := packValue(buf, f); err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
default:
|
||||
return binary.Write(buf, binary.BigEndian, v.Interface())
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
func packType(buf io.Writer, elts ...interface{}) error {
|
||||
for _, e := range elts {
|
||||
if err := packValue(buf, reflect.ValueOf(e)); err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
|
||||
return nil
|
||||
}
|
||||
|
||||
// tryUnmarshal attempts to use TPMUnmarshal() to perform the
|
||||
// unpack, if the given value implements SelfMarshaler.
|
||||
// True is returned if v implements SelfMarshaler & TPMUnmarshal
|
||||
// was called, along with an error returned from TPMUnmarshal.
|
||||
func tryUnmarshal(buf io.Reader, v reflect.Value) (bool, error) {
|
||||
t := v.Type()
|
||||
if t.Implements(selfMarshalerType) {
|
||||
if v.Kind() == reflect.Ptr && v.IsNil() {
|
||||
return true, fmt.Errorf("cannot call TPMUnmarshal on a nil pointer")
|
||||
}
|
||||
return true, v.Interface().(SelfMarshaler).TPMUnmarshal(buf)
|
||||
}
|
||||
|
||||
// We might have a non-pointer struct field, which is addressable,
|
||||
// If the pointer of the type implements the interface, and the
|
||||
// value is addressable, we should be able to call TPMUnmarshal().
|
||||
if v.CanAddr() && reflect.PtrTo(t).Implements(selfMarshalerType) {
|
||||
return true, v.Addr().Interface().(SelfMarshaler).TPMUnmarshal(buf)
|
||||
}
|
||||
|
||||
return false, nil
|
||||
}
|
||||
|
||||
// Unpack is a convenience wrapper around UnpackBuf. Unpack returns the number
|
||||
// of bytes read from b to fill elts and error, if any.
|
||||
func Unpack(b []byte, elts ...interface{}) (int, error) {
|
||||
buf := bytes.NewBuffer(b)
|
||||
err := UnpackBuf(buf, elts...)
|
||||
read := len(b) - buf.Len()
|
||||
return read, err
|
||||
}
|
||||
|
||||
func unpackValue(buf io.Reader, v reflect.Value) error {
|
||||
if v.Type() == handlesAreaType {
|
||||
v = v.Convert(reflect.TypeOf((*handleList)(nil)))
|
||||
}
|
||||
if didUnmarshal, err := tryUnmarshal(buf, v); didUnmarshal {
|
||||
return err
|
||||
}
|
||||
|
||||
switch v.Kind() {
|
||||
case reflect.Ptr:
|
||||
if v.IsNil() {
|
||||
return fmt.Errorf("cannot unpack nil %s", v.Type().String())
|
||||
}
|
||||
return unpackValue(buf, v.Elem())
|
||||
case reflect.Struct:
|
||||
for i := 0; i < v.NumField(); i++ {
|
||||
f := v.Field(i)
|
||||
if err := unpackValue(buf, f); err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
return nil
|
||||
default:
|
||||
// binary.Read can only set pointer values, so we need to take the address.
|
||||
if !v.CanAddr() {
|
||||
return fmt.Errorf("cannot unpack unaddressable leaf type %q", v.Type().String())
|
||||
}
|
||||
return binary.Read(buf, binary.BigEndian, v.Addr().Interface())
|
||||
}
|
||||
}
|
||||
|
||||
// UnpackBuf recursively unpacks types from a reader just as encoding/binary
|
||||
// does under binary.BigEndian, but with one difference: it unpacks a byte
|
||||
// slice by first reading an integer with lengthPrefixSize bytes, then reading
|
||||
// that many bytes. It assumes that incoming values are pointers to values so
|
||||
// that, e.g., underlying slices can be resized as needed.
|
||||
func UnpackBuf(buf io.Reader, elts ...interface{}) error {
|
||||
for _, e := range elts {
|
||||
v := reflect.ValueOf(e)
|
||||
if v.Kind() != reflect.Ptr {
|
||||
return fmt.Errorf("non-pointer value %q passed to UnpackBuf", v.Type().String())
|
||||
}
|
||||
if v.IsNil() {
|
||||
return errors.New("nil pointer passed to UnpackBuf")
|
||||
}
|
||||
|
||||
if err := unpackValue(buf, v); err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
return nil
|
||||
}
|
||||
Generated
Vendored
-10
@@ -1,10 +0,0 @@
|
||||
//go:build !linux && !darwin
|
||||
|
||||
package tpmutil
|
||||
|
||||
import (
|
||||
"os"
|
||||
)
|
||||
|
||||
// Not implemented on Windows.
|
||||
func poll(_ *os.File) error { return nil }
|
||||
Generated
Vendored
-32
@@ -1,32 +0,0 @@
|
||||
//go:build linux || darwin
|
||||
|
||||
package tpmutil
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"os"
|
||||
|
||||
"golang.org/x/sys/unix"
|
||||
)
|
||||
|
||||
// poll blocks until the file descriptor is ready for reading or an error occurs.
|
||||
func poll(f *os.File) error {
|
||||
var (
|
||||
fds = []unix.PollFd{{
|
||||
Fd: int32(f.Fd()),
|
||||
Events: 0x1, // POLLIN
|
||||
}}
|
||||
timeout = -1 // Indefinite timeout
|
||||
)
|
||||
|
||||
if _, err := unix.Poll(fds, timeout); err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
// Revents is filled in by the kernel.
|
||||
// If the expected event happened, Revents should match Events.
|
||||
if fds[0].Revents != fds[0].Events {
|
||||
return fmt.Errorf("unexpected poll Revents 0x%x", fds[0].Revents)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
Generated
Vendored
-113
@@ -1,113 +0,0 @@
|
||||
// Copyright (c) 2018, Google LLC All rights reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
// Package tpmutil provides common utility functions for both TPM 1.2 and TPM
|
||||
// 2.0 devices.
|
||||
package tpmutil
|
||||
|
||||
import (
|
||||
"errors"
|
||||
"io"
|
||||
"os"
|
||||
"time"
|
||||
)
|
||||
|
||||
// maxTPMResponse is the largest possible response from the TPM. We need to know
|
||||
// this because we don't always know the length of the TPM response, and
|
||||
// /dev/tpm insists on giving it all back in a single value rather than
|
||||
// returning a header and a body in separate responses.
|
||||
const maxTPMResponse = 4096
|
||||
|
||||
// RunCommandRaw executes the given raw command and returns the raw response.
|
||||
// Does not check the response code except to execute retry logic.
|
||||
func RunCommandRaw(rw io.ReadWriter, inb []byte) ([]byte, error) {
|
||||
if rw == nil {
|
||||
return nil, errors.New("nil TPM handle")
|
||||
}
|
||||
|
||||
// f(t) = (2^t)ms, up to 2s
|
||||
var backoffFac uint
|
||||
var rh responseHeader
|
||||
var outb []byte
|
||||
|
||||
for {
|
||||
if _, err := rw.Write(inb); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
// If the TPM is a real device, it may not be ready for reading
|
||||
// immediately after writing the command. Wait until the file
|
||||
// descriptor is ready to be read from.
|
||||
if f, ok := rw.(*os.File); ok {
|
||||
if err := poll(f); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
}
|
||||
|
||||
outb = make([]byte, maxTPMResponse)
|
||||
outlen, err := rw.Read(outb)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
// Resize the buffer to match the amount read from the TPM.
|
||||
outb = outb[:outlen]
|
||||
|
||||
_, err = Unpack(outb, &rh)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
// If TPM is busy, retry the command after waiting a few ms.
|
||||
if rh.Res == RCRetry {
|
||||
if backoffFac < 11 {
|
||||
dur := (1 << backoffFac) * time.Millisecond
|
||||
time.Sleep(dur)
|
||||
backoffFac++
|
||||
} else {
|
||||
return nil, err
|
||||
}
|
||||
} else {
|
||||
break
|
||||
}
|
||||
}
|
||||
|
||||
return outb, nil
|
||||
}
|
||||
|
||||
// RunCommand executes cmd with given tag and arguments. Returns TPM response
|
||||
// body (without response header) and response code from the header. Returned
|
||||
// error may be nil if response code is not RCSuccess; caller should check
|
||||
// both.
|
||||
func RunCommand(rw io.ReadWriter, tag Tag, cmd Command, in ...interface{}) ([]byte, ResponseCode, error) {
|
||||
inb, err := packWithHeader(commandHeader{tag, 0, cmd}, in...)
|
||||
if err != nil {
|
||||
return nil, 0, err
|
||||
}
|
||||
|
||||
outb, err := RunCommandRaw(rw, inb)
|
||||
if err != nil {
|
||||
return nil, 0, err
|
||||
}
|
||||
|
||||
var rh responseHeader
|
||||
read, err := Unpack(outb, &rh)
|
||||
if err != nil {
|
||||
return nil, 0, err
|
||||
}
|
||||
if rh.Res != RCSuccess {
|
||||
return nil, rh.Res, nil
|
||||
}
|
||||
|
||||
return outb[read:], rh.Res, nil
|
||||
}
|
||||
Generated
Vendored
-111
@@ -1,111 +0,0 @@
|
||||
//go:build !windows
|
||||
|
||||
// Copyright (c) 2018, Google LLC All rights reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
package tpmutil
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"io"
|
||||
"net"
|
||||
"os"
|
||||
)
|
||||
|
||||
// OpenTPM opens a channel to the TPM at the given path. If the file is a
|
||||
// device, then it treats it like a normal TPM device, and if the file is a
|
||||
// Unix domain socket, then it opens a connection to the socket.
|
||||
func OpenTPM(path string) (io.ReadWriteCloser, error) {
|
||||
// If it's a regular file, then open it
|
||||
var rwc io.ReadWriteCloser
|
||||
fi, err := os.Stat(path)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
if fi.Mode()&os.ModeDevice != 0 {
|
||||
var f *os.File
|
||||
f, err = os.OpenFile(path, os.O_RDWR, 0600)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
rwc = io.ReadWriteCloser(f)
|
||||
} else if fi.Mode()&os.ModeSocket != 0 {
|
||||
rwc = NewEmulatorReadWriteCloser(path)
|
||||
} else {
|
||||
return nil, fmt.Errorf("unsupported TPM file mode %s", fi.Mode().String())
|
||||
}
|
||||
|
||||
return rwc, nil
|
||||
}
|
||||
|
||||
// dialer abstracts the net.Dial call so test code can provide its own net.Conn
|
||||
// implementation.
|
||||
type dialer func(network, path string) (net.Conn, error)
|
||||
|
||||
// EmulatorReadWriteCloser manages connections with a TPM emulator over a Unix
|
||||
// domain socket. These emulators often operate in a write/read/disconnect
|
||||
// sequence, so the Write method always connects, and the Read method always
|
||||
// closes. EmulatorReadWriteCloser is not thread safe.
|
||||
type EmulatorReadWriteCloser struct {
|
||||
path string
|
||||
conn net.Conn
|
||||
dialer dialer
|
||||
}
|
||||
|
||||
// NewEmulatorReadWriteCloser stores information about a Unix domain socket to
|
||||
// write to and read from.
|
||||
func NewEmulatorReadWriteCloser(path string) *EmulatorReadWriteCloser {
|
||||
return &EmulatorReadWriteCloser{
|
||||
path: path,
|
||||
dialer: net.Dial,
|
||||
}
|
||||
}
|
||||
|
||||
// Read implements io.Reader by reading from the Unix domain socket and closing
|
||||
// it.
|
||||
func (erw *EmulatorReadWriteCloser) Read(p []byte) (int, error) {
|
||||
// Read is always the second operation in a Write/Read sequence.
|
||||
if erw.conn == nil {
|
||||
return 0, fmt.Errorf("must call Write then Read in an alternating sequence")
|
||||
}
|
||||
n, err := erw.conn.Read(p)
|
||||
erw.conn.Close()
|
||||
erw.conn = nil
|
||||
return n, err
|
||||
}
|
||||
|
||||
// Write implements io.Writer by connecting to the Unix domain socket and
|
||||
// writing.
|
||||
func (erw *EmulatorReadWriteCloser) Write(p []byte) (int, error) {
|
||||
if erw.conn != nil {
|
||||
return 0, fmt.Errorf("must call Write then Read in an alternating sequence")
|
||||
}
|
||||
var err error
|
||||
erw.conn, err = erw.dialer("unix", erw.path)
|
||||
if err != nil {
|
||||
return 0, err
|
||||
}
|
||||
return erw.conn.Write(p)
|
||||
}
|
||||
|
||||
// Close implements io.Closer by closing the Unix domain socket if one is open.
|
||||
func (erw *EmulatorReadWriteCloser) Close() error {
|
||||
if erw.conn == nil {
|
||||
return fmt.Errorf("cannot call Close when no connection is open")
|
||||
}
|
||||
err := erw.conn.Close()
|
||||
erw.conn = nil
|
||||
return err
|
||||
}
|
||||
Generated
Vendored
-84
@@ -1,84 +0,0 @@
|
||||
// Copyright (c) 2018, Google LLC All rights reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
package tpmutil
|
||||
|
||||
import (
|
||||
"io"
|
||||
|
||||
"github.com/google/go-tpm/tpmutil/tbs"
|
||||
)
|
||||
|
||||
// winTPMBuffer is a ReadWriteCloser to access the TPM in Windows.
|
||||
type winTPMBuffer struct {
|
||||
context tbs.Context
|
||||
outBuffer []byte
|
||||
}
|
||||
|
||||
// Executes the TPM command specified by commandBuffer (at Normal Priority), returning the number
|
||||
// of bytes in the command and any error code returned by executing the TPM command. Command
|
||||
// response can be read by calling Read().
|
||||
func (rwc *winTPMBuffer) Write(commandBuffer []byte) (int, error) {
|
||||
// TPM spec defines longest possible response to be maxTPMResponse.
|
||||
rwc.outBuffer = rwc.outBuffer[:maxTPMResponse]
|
||||
|
||||
outBufferLen, err := rwc.context.SubmitCommand(
|
||||
tbs.NormalPriority,
|
||||
commandBuffer,
|
||||
rwc.outBuffer,
|
||||
)
|
||||
|
||||
if err != nil {
|
||||
rwc.outBuffer = rwc.outBuffer[:0]
|
||||
return 0, err
|
||||
}
|
||||
// Shrink outBuffer so it is length of response.
|
||||
rwc.outBuffer = rwc.outBuffer[:outBufferLen]
|
||||
return len(commandBuffer), nil
|
||||
}
|
||||
|
||||
// Provides TPM response from the command called in the last Write call.
|
||||
func (rwc *winTPMBuffer) Read(responseBuffer []byte) (int, error) {
|
||||
if len(rwc.outBuffer) == 0 {
|
||||
return 0, io.EOF
|
||||
}
|
||||
lenCopied := copy(responseBuffer, rwc.outBuffer)
|
||||
// Cut out the piece of slice which was just read out, maintaining original slice capacity.
|
||||
rwc.outBuffer = append(rwc.outBuffer[:0], rwc.outBuffer[lenCopied:]...)
|
||||
return lenCopied, nil
|
||||
}
|
||||
|
||||
func (rwc *winTPMBuffer) Close() error {
|
||||
return rwc.context.Close()
|
||||
}
|
||||
|
||||
// OpenTPM creates a new instance of a ReadWriteCloser which can interact with a
|
||||
// Windows TPM.
|
||||
func OpenTPM() (io.ReadWriteCloser, error) {
|
||||
tpmContext, err := tbs.CreateContext(tbs.TPMVersion20, tbs.IncludeTPM12|tbs.IncludeTPM20)
|
||||
rwc := &winTPMBuffer{
|
||||
context: tpmContext,
|
||||
outBuffer: make([]byte, 0, maxTPMResponse),
|
||||
}
|
||||
return rwc, err
|
||||
}
|
||||
|
||||
// FromContext creates a new instance of a ReadWriteCloser which can
|
||||
// interact with a Windows TPM, using the specified TBS handle.
|
||||
func FromContext(ctx tbs.Context) io.ReadWriteCloser {
|
||||
return &winTPMBuffer{
|
||||
context: ctx,
|
||||
outBuffer: make([]byte, 0, maxTPMResponse),
|
||||
}
|
||||
}
|
||||
Generated
Vendored
-195
@@ -1,195 +0,0 @@
|
||||
// Copyright (c) 2018, Google LLC All rights reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
package tpmutil
|
||||
|
||||
import (
|
||||
"bytes"
|
||||
"encoding/binary"
|
||||
"fmt"
|
||||
"io"
|
||||
)
|
||||
|
||||
// maxBytesBufferSize sets a sane upper bound on the size of a U32Bytes
|
||||
// buffer. This limit exists to prevent a maliciously large size prefix
|
||||
// from resulting in a massive memory allocation, potentially causing
|
||||
// an OOM condition on the system.
|
||||
// We expect no buffer from a TPM to approach 1Mb in size.
|
||||
const maxBytesBufferSize uint32 = 1024 * 1024 // 1Mb.
|
||||
|
||||
// RawBytes is for Pack and RunCommand arguments that are already encoded.
|
||||
// Compared to []byte, RawBytes will not be prepended with slice length during
|
||||
// encoding.
|
||||
type RawBytes []byte
|
||||
|
||||
// U16Bytes is a byte slice with a 16-bit header
|
||||
type U16Bytes []byte
|
||||
|
||||
// TPMMarshal packs U16Bytes
|
||||
func (b *U16Bytes) TPMMarshal(out io.Writer) error {
|
||||
size := len([]byte(*b))
|
||||
if err := binary.Write(out, binary.BigEndian, uint16(size)); err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
n, err := out.Write(*b)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
if n != size {
|
||||
return fmt.Errorf("unable to write all contents of U16Bytes")
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// TPMUnmarshal unpacks a U16Bytes
|
||||
func (b *U16Bytes) TPMUnmarshal(in io.Reader) error {
|
||||
var tmpSize uint16
|
||||
if err := binary.Read(in, binary.BigEndian, &tmpSize); err != nil {
|
||||
return err
|
||||
}
|
||||
size := int(tmpSize)
|
||||
|
||||
if len(*b) >= size {
|
||||
*b = (*b)[:size]
|
||||
} else {
|
||||
*b = append(*b, make([]byte, size-len(*b))...)
|
||||
}
|
||||
|
||||
n, err := in.Read(*b)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
if n != size {
|
||||
return io.ErrUnexpectedEOF
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// U32Bytes is a byte slice with a 32-bit header
|
||||
type U32Bytes []byte
|
||||
|
||||
// TPMMarshal packs U32Bytes
|
||||
func (b *U32Bytes) TPMMarshal(out io.Writer) error {
|
||||
size := len([]byte(*b))
|
||||
if err := binary.Write(out, binary.BigEndian, uint32(size)); err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
n, err := out.Write(*b)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
if n != size {
|
||||
return fmt.Errorf("unable to write all contents of U32Bytes")
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// TPMUnmarshal unpacks a U32Bytes
|
||||
func (b *U32Bytes) TPMUnmarshal(in io.Reader) error {
|
||||
var tmpSize uint32
|
||||
if err := binary.Read(in, binary.BigEndian, &tmpSize); err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
if tmpSize > maxBytesBufferSize {
|
||||
return bytes.ErrTooLarge
|
||||
}
|
||||
// We can now safely cast to an int on 32-bit or 64-bit machines
|
||||
size := int(tmpSize)
|
||||
|
||||
if len(*b) >= size {
|
||||
*b = (*b)[:size]
|
||||
} else {
|
||||
*b = append(*b, make([]byte, size-len(*b))...)
|
||||
}
|
||||
|
||||
n, err := in.Read(*b)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
if n != size {
|
||||
return fmt.Errorf("unable to read all contents in to U32Bytes")
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// Tag is a command tag.
|
||||
type Tag uint16
|
||||
|
||||
// Command is an identifier of a TPM command.
|
||||
type Command uint32
|
||||
|
||||
// A commandHeader is the header for a TPM command.
|
||||
type commandHeader struct {
|
||||
Tag Tag
|
||||
Size uint32
|
||||
Cmd Command
|
||||
}
|
||||
|
||||
// ResponseCode is a response code returned by TPM.
|
||||
type ResponseCode uint32
|
||||
|
||||
// RCSuccess is response code for successful command. Identical for TPM 1.2 and
|
||||
// 2.0.
|
||||
const RCSuccess ResponseCode = 0x000
|
||||
|
||||
// RCRetry is response code for TPM is busy.
|
||||
const RCRetry ResponseCode = 0x922
|
||||
|
||||
// A responseHeader is a header for TPM responses.
|
||||
type responseHeader struct {
|
||||
Tag Tag
|
||||
Size uint32
|
||||
Res ResponseCode
|
||||
}
|
||||
|
||||
// A Handle is a reference to a TPM object.
|
||||
type Handle uint32
|
||||
|
||||
// HandleValue returns the handle value. This behavior is intended to satisfy
|
||||
// an interface that can be implemented by other, more complex types as well.
|
||||
func (h Handle) HandleValue() uint32 {
|
||||
return uint32(h)
|
||||
}
|
||||
|
||||
type handleList []Handle
|
||||
|
||||
func (l *handleList) TPMMarshal(_ io.Writer) error {
|
||||
return fmt.Errorf("TPMMarhsal on []Handle is not supported yet")
|
||||
}
|
||||
|
||||
func (l *handleList) TPMUnmarshal(in io.Reader) error {
|
||||
var numHandles uint16
|
||||
if err := binary.Read(in, binary.BigEndian, &numHandles); err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
// Make len(e) match size exactly.
|
||||
size := int(numHandles)
|
||||
if len(*l) >= size {
|
||||
*l = (*l)[:size]
|
||||
} else {
|
||||
*l = append(*l, make([]Handle, size-len(*l))...)
|
||||
}
|
||||
return binary.Read(in, binary.BigEndian, *l)
|
||||
}
|
||||
|
||||
// SelfMarshaler allows custom types to override default encoding/decoding
|
||||
// behavior in Pack, Unpack and UnpackBuf.
|
||||
type SelfMarshaler interface {
|
||||
TPMMarshal(out io.Writer) error
|
||||
TPMUnmarshal(in io.Reader) error
|
||||
}
|
||||
Generated
Vendored
-267
@@ -1,267 +0,0 @@
|
||||
// Copyright (c) 2018, Google LLC All rights reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
// Package tbs provides an low-level interface directly mapping to Windows
|
||||
// Tbs.dll system library commands:
|
||||
// https://docs.microsoft.com/en-us/windows/desktop/TBS/tpm-base-services-portal
|
||||
// Public field descriptions contain links to the high-level Windows documentation.
|
||||
package tbs
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"syscall"
|
||||
"unsafe"
|
||||
)
|
||||
|
||||
// Context references the current TPM context
|
||||
type Context uintptr
|
||||
|
||||
// Version of TPM being used by the application.
|
||||
type Version uint32
|
||||
|
||||
// Flag indicates TPM versions that are supported by the application.
|
||||
type Flag uint32
|
||||
|
||||
// CommandPriority is used to determine which pending command to submit whenever the TPM is free.
|
||||
type CommandPriority uint32
|
||||
|
||||
// Command parameters:
|
||||
// https://github.com/tpn/winsdk-10/blob/master/Include/10.0.10240.0/shared/tbs.h
|
||||
const (
|
||||
// https://docs.microsoft.com/en-us/windows/desktop/api/Tbs/ns-tbs-tdtbs_context_params2
|
||||
// OR flags to use multiple.
|
||||
RequestRaw Flag = 1 << iota // Add flag to request raw context
|
||||
IncludeTPM12 // Add flag to support TPM 1.2
|
||||
IncludeTPM20 // Add flag to support TPM 2
|
||||
|
||||
TPMVersion12 Version = 1 // For TPM 1.2 applications
|
||||
TPMVersion20 Version = 2 // For TPM 2 applications or applications using multiple TPM versions
|
||||
|
||||
// https://docs.microsoft.com/en-us/windows/desktop/tbs/command-scheduling
|
||||
// https://docs.microsoft.com/en-us/windows/desktop/api/Tbs/nf-tbs-tbsip_submit_command#parameters
|
||||
LowPriority CommandPriority = 100 // For low priority application use
|
||||
NormalPriority CommandPriority = 200 // For normal priority application use
|
||||
HighPriority CommandPriority = 300 // For high priority application use
|
||||
SystemPriority CommandPriority = 400 // For system tasks that access the TPM
|
||||
|
||||
commandLocalityZero uint32 = 0 // Windows currently only supports TBS_COMMAND_LOCALITY_ZERO.
|
||||
)
|
||||
|
||||
// Error is the return type of all functions in this package.
|
||||
type Error uint32
|
||||
|
||||
func (err Error) Error() string {
|
||||
if description, ok := errorDescriptions[err]; ok {
|
||||
return fmt.Sprintf("TBS Error 0x%X: %s", uint32(err), description)
|
||||
}
|
||||
return fmt.Sprintf("Unrecognized TBS Error 0x%X", uint32(err))
|
||||
}
|
||||
|
||||
func getError(err uintptr) error {
|
||||
// tbs.dll uses 0x0 as the return value for success.
|
||||
if err == 0 {
|
||||
return nil
|
||||
}
|
||||
return Error(err)
|
||||
}
|
||||
|
||||
// TBS Return Codes:
|
||||
// https://docs.microsoft.com/en-us/windows/desktop/TBS/tbs-return-codes
|
||||
const (
|
||||
ErrInternalError Error = 0x80284001
|
||||
ErrBadParameter Error = 0x80284002
|
||||
ErrInvalidOutputPointer Error = 0x80284003
|
||||
ErrInvalidContext Error = 0x80284004
|
||||
ErrInsufficientBuffer Error = 0x80284005
|
||||
ErrIOError Error = 0x80284006
|
||||
ErrInvalidContextParam Error = 0x80284007
|
||||
ErrServiceNotRunning Error = 0x80284008
|
||||
ErrTooManyTBSContexts Error = 0x80284009
|
||||
ErrTooManyResources Error = 0x8028400A
|
||||
ErrServiceStartPending Error = 0x8028400B
|
||||
ErrPPINotSupported Error = 0x8028400C
|
||||
ErrCommandCanceled Error = 0x8028400D
|
||||
ErrBufferTooLarge Error = 0x8028400E
|
||||
ErrTPMNotFound Error = 0x8028400F
|
||||
ErrServiceDisabled Error = 0x80284010
|
||||
ErrNoEventLog Error = 0x80284011
|
||||
ErrAccessDenied Error = 0x80284012
|
||||
ErrProvisioningNotAllowed Error = 0x80284013
|
||||
ErrPPIFunctionUnsupported Error = 0x80284014
|
||||
ErrOwnerauthNotFound Error = 0x80284015
|
||||
)
|
||||
|
||||
var errorDescriptions = map[Error]string{
|
||||
ErrInternalError: "An internal software error occurred.",
|
||||
ErrBadParameter: "One or more parameter values are not valid.",
|
||||
ErrInvalidOutputPointer: "A specified output pointer is bad.",
|
||||
ErrInvalidContext: "The specified context handle does not refer to a valid context.",
|
||||
ErrInsufficientBuffer: "The specified output buffer is too small.",
|
||||
ErrIOError: "An error occurred while communicating with the TPM.",
|
||||
ErrInvalidContextParam: "A context parameter that is not valid was passed when attempting to create a TBS context.",
|
||||
ErrServiceNotRunning: "The TBS service is not running and could not be started.",
|
||||
ErrTooManyTBSContexts: "A new context could not be created because there are too many open contexts.",
|
||||
ErrTooManyResources: "A new virtual resource could not be created because there are too many open virtual resources.",
|
||||
ErrServiceStartPending: "The TBS service has been started but is not yet running.",
|
||||
ErrPPINotSupported: "The physical presence interface is not supported.",
|
||||
ErrCommandCanceled: "The command was canceled.",
|
||||
ErrBufferTooLarge: "The input or output buffer is too large.",
|
||||
ErrTPMNotFound: "A compatible Trusted Platform Module (TPM) Security Device cannot be found on this computer.",
|
||||
ErrServiceDisabled: "The TBS service has been disabled.",
|
||||
ErrNoEventLog: "The TBS event log is not available.",
|
||||
ErrAccessDenied: "The caller does not have the appropriate rights to perform the requested operation.",
|
||||
ErrProvisioningNotAllowed: "The TPM provisioning action is not allowed by the specified flags.",
|
||||
ErrPPIFunctionUnsupported: "The Physical Presence Interface of this firmware does not support the requested method.",
|
||||
ErrOwnerauthNotFound: "The requested TPM OwnerAuth value was not found.",
|
||||
}
|
||||
|
||||
// Tbs.dll provides an API for making calls to the TPM:
|
||||
// https://docs.microsoft.com/en-us/windows/desktop/TBS/tpm-base-services-portal
|
||||
var (
|
||||
tbsDLL = syscall.NewLazyDLL("Tbs.dll")
|
||||
tbsGetDeviceInfo = tbsDLL.NewProc("Tbsi_GetDeviceInfo")
|
||||
tbsCreateContext = tbsDLL.NewProc("Tbsi_Context_Create")
|
||||
tbsContextClose = tbsDLL.NewProc("Tbsip_Context_Close")
|
||||
tbsSubmitCommand = tbsDLL.NewProc("Tbsip_Submit_Command")
|
||||
tbsGetTCGLog = tbsDLL.NewProc("Tbsi_Get_TCG_Log")
|
||||
)
|
||||
|
||||
// Returns the address of the beginning of a slice or 0 for a nil slice.
|
||||
func sliceAddress(s []byte) uintptr {
|
||||
if len(s) == 0 {
|
||||
return 0
|
||||
}
|
||||
return uintptr(unsafe.Pointer(&(s[0])))
|
||||
}
|
||||
|
||||
// DeviceInfo is TPM_DEVICE_INFO from tbs.h
|
||||
type DeviceInfo struct {
|
||||
StructVersion uint32
|
||||
TPMVersion Version
|
||||
TPMInterfaceType uint32
|
||||
TPMImpRevision uint32
|
||||
}
|
||||
|
||||
// GetDeviceInfo gets the DeviceInfo of the current TPM:
|
||||
// https://docs.microsoft.com/en-us/windows/win32/api/tbs/nf-tbs-tbsi_getdeviceinfo
|
||||
func GetDeviceInfo() (*DeviceInfo, error) {
|
||||
info := DeviceInfo{}
|
||||
// TBS_RESULT Tbsi_GetDeviceInfo(
|
||||
// UINT32 Size,
|
||||
// PVOID Info
|
||||
// );
|
||||
if err := tbsGetDeviceInfo.Find(); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
result, _, _ := tbsGetDeviceInfo.Call(
|
||||
unsafe.Sizeof(info),
|
||||
uintptr(unsafe.Pointer(&info)),
|
||||
)
|
||||
return &info, getError(result)
|
||||
}
|
||||
|
||||
// CreateContext creates a new TPM context:
|
||||
// https://docs.microsoft.com/en-us/windows/desktop/api/Tbs/nf-tbs-tbsi_context_create
|
||||
func CreateContext(version Version, flag Flag) (Context, error) {
|
||||
var context Context
|
||||
params := struct {
|
||||
Version
|
||||
Flag
|
||||
}{version, flag}
|
||||
// TBS_RESULT Tbsi_Context_Create(
|
||||
// _In_ PCTBS_CONTEXT_PARAMS pContextParams,
|
||||
// _Out_ PTBS_HCONTEXT *phContext
|
||||
// );
|
||||
if err := tbsCreateContext.Find(); err != nil {
|
||||
return context, err
|
||||
}
|
||||
result, _, _ := tbsCreateContext.Call(
|
||||
uintptr(unsafe.Pointer(¶ms)),
|
||||
uintptr(unsafe.Pointer(&context)),
|
||||
)
|
||||
return context, getError(result)
|
||||
}
|
||||
|
||||
// Close closes an existing TPM context:
|
||||
// https://docs.microsoft.com/en-us/windows/desktop/api/Tbs/nf-tbs-tbsip_context_close
|
||||
func (context Context) Close() error {
|
||||
// TBS_RESULT Tbsip_Context_Close(
|
||||
// _In_ TBS_HCONTEXT hContext
|
||||
// );
|
||||
if err := tbsContextClose.Find(); err != nil {
|
||||
return err
|
||||
}
|
||||
result, _, _ := tbsContextClose.Call(uintptr(context))
|
||||
return getError(result)
|
||||
}
|
||||
|
||||
// SubmitCommand sends commandBuffer to the TPM, returning the number of bytes
|
||||
// written to responseBuffer. ErrInsufficientBuffer is returned if the
|
||||
// responseBuffer is too short. ErrInvalidOutputPointer is returned if the
|
||||
// responseBuffer is nil. On failure, the returned length is unspecified.
|
||||
// https://docs.microsoft.com/en-us/windows/desktop/api/Tbs/nf-tbs-tbsip_submit_command
|
||||
func (context Context) SubmitCommand(
|
||||
priority CommandPriority,
|
||||
commandBuffer []byte,
|
||||
responseBuffer []byte,
|
||||
) (uint32, error) {
|
||||
responseBufferLen := uint32(len(responseBuffer))
|
||||
|
||||
// TBS_RESULT Tbsip_Submit_Command(
|
||||
// _In_ TBS_HCONTEXT hContext,
|
||||
// _In_ TBS_COMMAND_LOCALITY Locality,
|
||||
// _In_ TBS_COMMAND_PRIORITY Priority,
|
||||
// _In_ const PCBYTE *pabCommand,
|
||||
// _In_ UINT32 cbCommand,
|
||||
// _Out_ PBYTE *pabResult,
|
||||
// _Inout_ UINT32 *pcbOutput
|
||||
// );
|
||||
if err := tbsSubmitCommand.Find(); err != nil {
|
||||
return 0, err
|
||||
}
|
||||
result, _, _ := tbsSubmitCommand.Call(
|
||||
uintptr(context),
|
||||
uintptr(commandLocalityZero),
|
||||
uintptr(priority),
|
||||
sliceAddress(commandBuffer),
|
||||
uintptr(len(commandBuffer)),
|
||||
sliceAddress(responseBuffer),
|
||||
uintptr(unsafe.Pointer(&responseBufferLen)),
|
||||
)
|
||||
return responseBufferLen, getError(result)
|
||||
}
|
||||
|
||||
// GetTCGLog gets the system event log, returning the number of bytes written
|
||||
// to logBuffer. If logBuffer is nil, the size of the TCG log is returned.
|
||||
// ErrInsufficientBuffer is returned if the logBuffer is too short. On failure,
|
||||
// the returned length is unspecified.
|
||||
// https://docs.microsoft.com/en-us/windows/desktop/api/Tbs/nf-tbs-tbsi_get_tcg_log
|
||||
func (context Context) GetTCGLog(logBuffer []byte) (uint32, error) {
|
||||
logBufferLen := uint32(len(logBuffer))
|
||||
|
||||
// TBS_RESULT Tbsi_Get_TCG_Log(
|
||||
// TBS_HCONTEXT hContext,
|
||||
// PBYTE pOutputBuf,
|
||||
// PUINT32 pOutputBufLen
|
||||
// );
|
||||
if err := tbsGetTCGLog.Find(); err != nil {
|
||||
return 0, err
|
||||
}
|
||||
result, _, _ := tbsGetTCGLog.Call(
|
||||
uintptr(context),
|
||||
sliceAddress(logBuffer),
|
||||
uintptr(unsafe.Pointer(&logBufferLen)),
|
||||
)
|
||||
return logBufferLen, getError(result)
|
||||
}
|
||||
-304
@@ -1,304 +0,0 @@
|
||||
Copyright (c) 2012 The Go Authors. All rights reserved.
|
||||
Copyright (c) 2019 Klaus Post. All rights reserved.
|
||||
|
||||
Redistribution and use in source and binary forms, with or without
|
||||
modification, are permitted provided that the following conditions are
|
||||
met:
|
||||
|
||||
* Redistributions of source code must retain the above copyright
|
||||
notice, this list of conditions and the following disclaimer.
|
||||
* Redistributions in binary form must reproduce the above
|
||||
copyright notice, this list of conditions and the following disclaimer
|
||||
in the documentation and/or other materials provided with the
|
||||
distribution.
|
||||
* Neither the name of Google Inc. nor the names of its
|
||||
contributors may be used to endorse or promote products derived from
|
||||
this software without specific prior written permission.
|
||||
|
||||
THIS SOFTWARE IS PROVIDED BY THE COPYRIGHT HOLDERS AND CONTRIBUTORS
|
||||
"AS IS" AND ANY EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT
|
||||
LIMITED TO, THE IMPLIED WARRANTIES OF MERCHANTABILITY AND FITNESS FOR
|
||||
A PARTICULAR PURPOSE ARE DISCLAIMED. IN NO EVENT SHALL THE COPYRIGHT
|
||||
OWNER OR CONTRIBUTORS BE LIABLE FOR ANY DIRECT, INDIRECT, INCIDENTAL,
|
||||
SPECIAL, EXEMPLARY, OR CONSEQUENTIAL DAMAGES (INCLUDING, BUT NOT
|
||||
LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR SERVICES; LOSS OF USE,
|
||||
DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER CAUSED AND ON ANY
|
||||
THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY, OR TORT
|
||||
(INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE
|
||||
OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
|
||||
|
||||
------------------
|
||||
|
||||
Files: gzhttp/*
|
||||
|
||||
Apache License
|
||||
Version 2.0, January 2004
|
||||
http://www.apache.org/licenses/
|
||||
|
||||
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
||||
|
||||
1. Definitions.
|
||||
|
||||
"License" shall mean the terms and conditions for use, reproduction,
|
||||
and distribution as defined by Sections 1 through 9 of this document.
|
||||
|
||||
"Licensor" shall mean the copyright owner or entity authorized by
|
||||
the copyright owner that is granting the License.
|
||||
|
||||
"Legal Entity" shall mean the union of the acting entity and all
|
||||
other entities that control, are controlled by, or are under common
|
||||
control with that entity. For the purposes of this definition,
|
||||
"control" means (i) the power, direct or indirect, to cause the
|
||||
direction or management of such entity, whether by contract or
|
||||
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
||||
outstanding shares, or (iii) beneficial ownership of such entity.
|
||||
|
||||
"You" (or "Your") shall mean an individual or Legal Entity
|
||||
exercising permissions granted by this License.
|
||||
|
||||
"Source" form shall mean the preferred form for making modifications,
|
||||
including but not limited to software source code, documentation
|
||||
source, and configuration files.
|
||||
|
||||
"Object" form shall mean any form resulting from mechanical
|
||||
transformation or translation of a Source form, including but
|
||||
not limited to compiled object code, generated documentation,
|
||||
and conversions to other media types.
|
||||
|
||||
"Work" shall mean the work of authorship, whether in Source or
|
||||
Object form, made available under the License, as indicated by a
|
||||
copyright notice that is included in or attached to the work
|
||||
(an example is provided in the Appendix below).
|
||||
|
||||
"Derivative Works" shall mean any work, whether in Source or Object
|
||||
form, that is based on (or derived from) the Work and for which the
|
||||
editorial revisions, annotations, elaborations, or other modifications
|
||||
represent, as a whole, an original work of authorship. For the purposes
|
||||
of this License, Derivative Works shall not include works that remain
|
||||
separable from, or merely link (or bind by name) to the interfaces of,
|
||||
the Work and Derivative Works thereof.
|
||||
|
||||
"Contribution" shall mean any work of authorship, including
|
||||
the original version of the Work and any modifications or additions
|
||||
to that Work or Derivative Works thereof, that is intentionally
|
||||
submitted to Licensor for inclusion in the Work by the copyright owner
|
||||
or by an individual or Legal Entity authorized to submit on behalf of
|
||||
the copyright owner. For the purposes of this definition, "submitted"
|
||||
means any form of electronic, verbal, or written communication sent
|
||||
to the Licensor or its representatives, including but not limited to
|
||||
communication on electronic mailing lists, source code control systems,
|
||||
and issue tracking systems that are managed by, or on behalf of, the
|
||||
Licensor for the purpose of discussing and improving the Work, but
|
||||
excluding communication that is conspicuously marked or otherwise
|
||||
designated in writing by the copyright owner as "Not a Contribution."
|
||||
|
||||
"Contributor" shall mean Licensor and any individual or Legal Entity
|
||||
on behalf of whom a Contribution has been received by Licensor and
|
||||
subsequently incorporated within the Work.
|
||||
|
||||
2. Grant of Copyright License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
copyright license to reproduce, prepare Derivative Works of,
|
||||
publicly display, publicly perform, sublicense, and distribute the
|
||||
Work and such Derivative Works in Source or Object form.
|
||||
|
||||
3. Grant of Patent License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
(except as stated in this section) patent license to make, have made,
|
||||
use, offer to sell, sell, import, and otherwise transfer the Work,
|
||||
where such license applies only to those patent claims licensable
|
||||
by such Contributor that are necessarily infringed by their
|
||||
Contribution(s) alone or by combination of their Contribution(s)
|
||||
with the Work to which such Contribution(s) was submitted. If You
|
||||
institute patent litigation against any entity (including a
|
||||
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
||||
or a Contribution incorporated within the Work constitutes direct
|
||||
or contributory patent infringement, then any patent licenses
|
||||
granted to You under this License for that Work shall terminate
|
||||
as of the date such litigation is filed.
|
||||
|
||||
4. Redistribution. You may reproduce and distribute copies of the
|
||||
Work or Derivative Works thereof in any medium, with or without
|
||||
modifications, and in Source or Object form, provided that You
|
||||
meet the following conditions:
|
||||
|
||||
(a) You must give any other recipients of the Work or
|
||||
Derivative Works a copy of this License; and
|
||||
|
||||
(b) You must cause any modified files to carry prominent notices
|
||||
stating that You changed the files; and
|
||||
|
||||
(c) You must retain, in the Source form of any Derivative Works
|
||||
that You distribute, all copyright, patent, trademark, and
|
||||
attribution notices from the Source form of the Work,
|
||||
excluding those notices that do not pertain to any part of
|
||||
the Derivative Works; and
|
||||
|
||||
(d) If the Work includes a "NOTICE" text file as part of its
|
||||
distribution, then any Derivative Works that You distribute must
|
||||
include a readable copy of the attribution notices contained
|
||||
within such NOTICE file, excluding those notices that do not
|
||||
pertain to any part of the Derivative Works, in at least one
|
||||
of the following places: within a NOTICE text file distributed
|
||||
as part of the Derivative Works; within the Source form or
|
||||
documentation, if provided along with the Derivative Works; or,
|
||||
within a display generated by the Derivative Works, if and
|
||||
wherever such third-party notices normally appear. The contents
|
||||
of the NOTICE file are for informational purposes only and
|
||||
do not modify the License. You may add Your own attribution
|
||||
notices within Derivative Works that You distribute, alongside
|
||||
or as an addendum to the NOTICE text from the Work, provided
|
||||
that such additional attribution notices cannot be construed
|
||||
as modifying the License.
|
||||
|
||||
You may add Your own copyright statement to Your modifications and
|
||||
may provide additional or different license terms and conditions
|
||||
for use, reproduction, or distribution of Your modifications, or
|
||||
for any such Derivative Works as a whole, provided Your use,
|
||||
reproduction, and distribution of the Work otherwise complies with
|
||||
the conditions stated in this License.
|
||||
|
||||
5. Submission of Contributions. Unless You explicitly state otherwise,
|
||||
any Contribution intentionally submitted for inclusion in the Work
|
||||
by You to the Licensor shall be under the terms and conditions of
|
||||
this License, without any additional terms or conditions.
|
||||
Notwithstanding the above, nothing herein shall supersede or modify
|
||||
the terms of any separate license agreement you may have executed
|
||||
with Licensor regarding such Contributions.
|
||||
|
||||
6. Trademarks. This License does not grant permission to use the trade
|
||||
names, trademarks, service marks, or product names of the Licensor,
|
||||
except as required for reasonable and customary use in describing the
|
||||
origin of the Work and reproducing the content of the NOTICE file.
|
||||
|
||||
7. Disclaimer of Warranty. Unless required by applicable law or
|
||||
agreed to in writing, Licensor provides the Work (and each
|
||||
Contributor provides its Contributions) on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
||||
implied, including, without limitation, any warranties or conditions
|
||||
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
||||
PARTICULAR PURPOSE. You are solely responsible for determining the
|
||||
appropriateness of using or redistributing the Work and assume any
|
||||
risks associated with Your exercise of permissions under this License.
|
||||
|
||||
8. Limitation of Liability. In no event and under no legal theory,
|
||||
whether in tort (including negligence), contract, or otherwise,
|
||||
unless required by applicable law (such as deliberate and grossly
|
||||
negligent acts) or agreed to in writing, shall any Contributor be
|
||||
liable to You for damages, including any direct, indirect, special,
|
||||
incidental, or consequential damages of any character arising as a
|
||||
result of this License or out of the use or inability to use the
|
||||
Work (including but not limited to damages for loss of goodwill,
|
||||
work stoppage, computer failure or malfunction, or any and all
|
||||
other commercial damages or losses), even if such Contributor
|
||||
has been advised of the possibility of such damages.
|
||||
|
||||
9. Accepting Warranty or Additional Liability. While redistributing
|
||||
the Work or Derivative Works thereof, You may choose to offer,
|
||||
and charge a fee for, acceptance of support, warranty, indemnity,
|
||||
or other liability obligations and/or rights consistent with this
|
||||
License. However, in accepting such obligations, You may act only
|
||||
on Your own behalf and on Your sole responsibility, not on behalf
|
||||
of any other Contributor, and only if You agree to indemnify,
|
||||
defend, and hold each Contributor harmless for any liability
|
||||
incurred by, or claims asserted against, such Contributor by reason
|
||||
of your accepting any such warranty or additional liability.
|
||||
|
||||
END OF TERMS AND CONDITIONS
|
||||
|
||||
APPENDIX: How to apply the Apache License to your work.
|
||||
|
||||
To apply the Apache License to your work, attach the following
|
||||
boilerplate notice, with the fields enclosed by brackets "[]"
|
||||
replaced with your own identifying information. (Don't include
|
||||
the brackets!) The text should be enclosed in the appropriate
|
||||
comment syntax for the file format. We also recommend that a
|
||||
file or class name and description of purpose be included on the
|
||||
same "printed page" as the copyright notice for easier
|
||||
identification within third-party archives.
|
||||
|
||||
Copyright 2016-2017 The New York Times Company
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
|
||||
------------------
|
||||
|
||||
Files: s2/cmd/internal/readahead/*
|
||||
|
||||
The MIT License (MIT)
|
||||
|
||||
Copyright (c) 2015 Klaus Post
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all
|
||||
copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
SOFTWARE.
|
||||
|
||||
---------------------
|
||||
Files: snappy/*
|
||||
Files: internal/snapref/*
|
||||
|
||||
Copyright (c) 2011 The Snappy-Go Authors. All rights reserved.
|
||||
|
||||
Redistribution and use in source and binary forms, with or without
|
||||
modification, are permitted provided that the following conditions are
|
||||
met:
|
||||
|
||||
* Redistributions of source code must retain the above copyright
|
||||
notice, this list of conditions and the following disclaimer.
|
||||
* Redistributions in binary form must reproduce the above
|
||||
copyright notice, this list of conditions and the following disclaimer
|
||||
in the documentation and/or other materials provided with the
|
||||
distribution.
|
||||
* Neither the name of Google Inc. nor the names of its
|
||||
contributors may be used to endorse or promote products derived from
|
||||
this software without specific prior written permission.
|
||||
|
||||
THIS SOFTWARE IS PROVIDED BY THE COPYRIGHT HOLDERS AND CONTRIBUTORS
|
||||
"AS IS" AND ANY EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT
|
||||
LIMITED TO, THE IMPLIED WARRANTIES OF MERCHANTABILITY AND FITNESS FOR
|
||||
A PARTICULAR PURPOSE ARE DISCLAIMED. IN NO EVENT SHALL THE COPYRIGHT
|
||||
OWNER OR CONTRIBUTORS BE LIABLE FOR ANY DIRECT, INDIRECT, INCIDENTAL,
|
||||
SPECIAL, EXEMPLARY, OR CONSEQUENTIAL DAMAGES (INCLUDING, BUT NOT
|
||||
LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR SERVICES; LOSS OF USE,
|
||||
DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER CAUSED AND ON ANY
|
||||
THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY, OR TORT
|
||||
(INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE
|
||||
OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
|
||||
|
||||
-----------------
|
||||
|
||||
Files: s2/cmd/internal/filepathx/*
|
||||
|
||||
Copyright 2016 The filepathx Authors
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy of this software and associated documentation files (the "Software"), to deal in the Software without restriction, including without limitation the rights to use, copy, modify, merge, publish, distribute, sublicense, and/or sell copies of the Software, and to permit persons to whom the Software is furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM, OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE SOFTWARE.
|
||||
Generated
Vendored
-997
@@ -1,997 +0,0 @@
|
||||
// Copyright 2009 The Go Authors. All rights reserved.
|
||||
// Copyright (c) 2015 Klaus Post
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package flate
|
||||
|
||||
import (
|
||||
"errors"
|
||||
"fmt"
|
||||
"io"
|
||||
"math"
|
||||
|
||||
"github.com/klauspost/compress/internal/le"
|
||||
)
|
||||
|
||||
const (
|
||||
NoCompression = 0
|
||||
BestSpeed = 1
|
||||
BestCompression = 9
|
||||
DefaultCompression = -1
|
||||
|
||||
// HuffmanOnly disables Lempel-Ziv match searching and only performs Huffman
|
||||
// entropy encoding. This mode is useful in compressing data that has
|
||||
// already been compressed with an LZ style algorithm (e.g. Snappy or LZ4)
|
||||
// that lacks an entropy encoder. Compression gains are achieved when
|
||||
// certain bytes in the input stream occur more frequently than others.
|
||||
//
|
||||
// Note that HuffmanOnly produces a compressed output that is
|
||||
// RFC 1951 compliant. That is, any valid DEFLATE decompressor will
|
||||
// continue to be able to decompress this output.
|
||||
HuffmanOnly = -2
|
||||
ConstantCompression = HuffmanOnly // compatibility alias.
|
||||
|
||||
logWindowSize = 15
|
||||
windowSize = 1 << logWindowSize
|
||||
windowMask = windowSize - 1
|
||||
logMaxOffsetSize = 15 // Standard DEFLATE
|
||||
minMatchLength = 4 // The smallest match that the compressor looks for
|
||||
maxMatchLength = 258 // The longest match for the compressor
|
||||
minOffsetSize = 1 // The shortest offset that makes any sense
|
||||
|
||||
// The maximum number of tokens we will encode at the time.
|
||||
// Smaller sizes usually creates less optimal blocks.
|
||||
// Bigger can make context switching slow.
|
||||
// We use this for levels 7-9, so we make it big.
|
||||
maxFlateBlockTokens = 1 << 15
|
||||
maxStoreBlockSize = 65535
|
||||
hashBits = 17 // After 17 performance degrades
|
||||
hashSize = 1 << hashBits
|
||||
hashMask = (1 << hashBits) - 1
|
||||
hashShift = (hashBits + minMatchLength - 1) / minMatchLength
|
||||
maxHashOffset = 1 << 28
|
||||
|
||||
skipNever = math.MaxInt32
|
||||
|
||||
debugDeflate = false
|
||||
)
|
||||
|
||||
type compressionLevel struct {
|
||||
good, lazy, nice, chain, fastSkipHashing, level int
|
||||
}
|
||||
|
||||
// Compression levels have been rebalanced from zlib deflate defaults
|
||||
// to give a bigger spread in speed and compression.
|
||||
// See https://blog.klauspost.com/rebalancing-deflate-compression-levels/
|
||||
var levels = []compressionLevel{
|
||||
{}, // 0
|
||||
// Level 1-6 uses specialized algorithm - values not used
|
||||
{0, 0, 0, 0, 0, 1},
|
||||
{0, 0, 0, 0, 0, 2},
|
||||
{0, 0, 0, 0, 0, 3},
|
||||
{0, 0, 0, 0, 0, 4},
|
||||
{0, 0, 0, 0, 0, 5},
|
||||
{0, 0, 0, 0, 0, 6},
|
||||
// Levels 7-9 use increasingly more lazy matching
|
||||
// and increasingly stringent conditions for "good enough".
|
||||
{8, 12, 16, 24, skipNever, 7},
|
||||
{16, 30, 40, 64, skipNever, 8},
|
||||
{32, 258, 258, 1024, skipNever, 9},
|
||||
}
|
||||
|
||||
// advancedState contains state for the advanced levels, with bigger hash tables, etc.
|
||||
type advancedState struct {
|
||||
// deflate state
|
||||
length int
|
||||
offset int
|
||||
maxInsertIndex int
|
||||
chainHead int
|
||||
hashOffset int
|
||||
|
||||
ii uint16 // position of last match, intended to overflow to reset.
|
||||
|
||||
// input window: unprocessed data is window[index:windowEnd]
|
||||
index int
|
||||
hashMatch [maxMatchLength + minMatchLength]uint32
|
||||
|
||||
// Input hash chains
|
||||
// hashHead[hashValue] contains the largest inputIndex with the specified hash value
|
||||
// If hashHead[hashValue] is within the current window, then
|
||||
// hashPrev[hashHead[hashValue] & windowMask] contains the previous index
|
||||
// with the same hash value.
|
||||
hashHead [hashSize]uint32
|
||||
hashPrev [windowSize]uint32
|
||||
}
|
||||
|
||||
type compressor struct {
|
||||
compressionLevel
|
||||
|
||||
h *huffmanEncoder
|
||||
w *huffmanBitWriter
|
||||
|
||||
// compression algorithm
|
||||
fill func(*compressor, []byte) int // copy data to window
|
||||
step func(*compressor) // process window
|
||||
|
||||
window []byte
|
||||
windowEnd int
|
||||
blockStart int // window index where current tokens start
|
||||
err error
|
||||
|
||||
// queued output tokens
|
||||
tokens tokens
|
||||
fast fastEnc
|
||||
state *advancedState
|
||||
|
||||
sync bool // requesting flush
|
||||
byteAvailable bool // if true, still need to process window[index-1].
|
||||
}
|
||||
|
||||
func (d *compressor) fillDeflate(b []byte) int {
|
||||
s := d.state
|
||||
if s.index >= 2*windowSize-(minMatchLength+maxMatchLength) {
|
||||
// shift the window by windowSize
|
||||
//copy(d.window[:], d.window[windowSize:2*windowSize])
|
||||
*(*[windowSize]byte)(d.window) = *(*[windowSize]byte)(d.window[windowSize:])
|
||||
s.index -= windowSize
|
||||
d.windowEnd -= windowSize
|
||||
if d.blockStart >= windowSize {
|
||||
d.blockStart -= windowSize
|
||||
} else {
|
||||
d.blockStart = math.MaxInt32
|
||||
}
|
||||
s.hashOffset += windowSize
|
||||
if s.hashOffset > maxHashOffset {
|
||||
delta := s.hashOffset - 1
|
||||
s.hashOffset -= delta
|
||||
s.chainHead -= delta
|
||||
// Iterate over slices instead of arrays to avoid copying
|
||||
// the entire table onto the stack (Issue #18625).
|
||||
for i, v := range s.hashPrev[:] {
|
||||
if int(v) > delta {
|
||||
s.hashPrev[i] = uint32(int(v) - delta)
|
||||
} else {
|
||||
s.hashPrev[i] = 0
|
||||
}
|
||||
}
|
||||
for i, v := range s.hashHead[:] {
|
||||
if int(v) > delta {
|
||||
s.hashHead[i] = uint32(int(v) - delta)
|
||||
} else {
|
||||
s.hashHead[i] = 0
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
n := copy(d.window[d.windowEnd:], b)
|
||||
d.windowEnd += n
|
||||
return n
|
||||
}
|
||||
|
||||
func (d *compressor) writeBlock(tok *tokens, index int, eof bool) error {
|
||||
if index > 0 || eof {
|
||||
var window []byte
|
||||
if d.blockStart <= index {
|
||||
window = d.window[d.blockStart:index]
|
||||
}
|
||||
d.blockStart = index
|
||||
//d.w.writeBlock(tok, eof, window)
|
||||
d.w.writeBlockDynamic(tok, eof, window, d.sync)
|
||||
return d.w.err
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// writeBlockSkip writes the current block and uses the number of tokens
|
||||
// to determine if the block should be stored on no matches, or
|
||||
// only huffman encoded.
|
||||
func (d *compressor) writeBlockSkip(tok *tokens, index int, eof bool) error {
|
||||
if index > 0 || eof {
|
||||
if d.blockStart <= index {
|
||||
window := d.window[d.blockStart:index]
|
||||
// If we removed less than a 64th of all literals
|
||||
// we huffman compress the block.
|
||||
if int(tok.n) > len(window)-int(tok.n>>6) {
|
||||
d.w.writeBlockHuff(eof, window, d.sync)
|
||||
} else {
|
||||
// Write a dynamic huffman block.
|
||||
d.w.writeBlockDynamic(tok, eof, window, d.sync)
|
||||
}
|
||||
} else {
|
||||
d.w.writeBlock(tok, eof, nil)
|
||||
}
|
||||
d.blockStart = index
|
||||
return d.w.err
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// fillWindow will fill the current window with the supplied
|
||||
// dictionary and calculate all hashes.
|
||||
// This is much faster than doing a full encode.
|
||||
// Should only be used after a start/reset.
|
||||
func (d *compressor) fillWindow(b []byte) {
|
||||
// Do not fill window if we are in store-only or huffman mode.
|
||||
if d.level <= 0 && d.level > -MinCustomWindowSize {
|
||||
return
|
||||
}
|
||||
if d.fast != nil {
|
||||
// encode the last data, but discard the result
|
||||
if len(b) > maxMatchOffset {
|
||||
b = b[len(b)-maxMatchOffset:]
|
||||
}
|
||||
d.fast.Encode(&d.tokens, b)
|
||||
d.tokens.Reset()
|
||||
return
|
||||
}
|
||||
s := d.state
|
||||
// If we are given too much, cut it.
|
||||
if len(b) > windowSize {
|
||||
b = b[len(b)-windowSize:]
|
||||
}
|
||||
// Add all to window.
|
||||
n := copy(d.window[d.windowEnd:], b)
|
||||
|
||||
// Calculate 256 hashes at the time (more L1 cache hits)
|
||||
loops := (n + 256 - minMatchLength) / 256
|
||||
for j := range loops {
|
||||
startindex := j * 256
|
||||
end := min(startindex+256+minMatchLength-1, n)
|
||||
tocheck := d.window[startindex:end]
|
||||
dstSize := len(tocheck) - minMatchLength + 1
|
||||
|
||||
if dstSize <= 0 {
|
||||
continue
|
||||
}
|
||||
|
||||
dst := s.hashMatch[:dstSize]
|
||||
bulkHash4(tocheck, dst)
|
||||
var newH uint32
|
||||
for i, val := range dst {
|
||||
di := i + startindex
|
||||
newH = val & hashMask
|
||||
// Get previous value with the same hash.
|
||||
// Our chain should point to the previous value.
|
||||
s.hashPrev[di&windowMask] = s.hashHead[newH]
|
||||
// Set the head of the hash chain to us.
|
||||
s.hashHead[newH] = uint32(di + s.hashOffset)
|
||||
}
|
||||
}
|
||||
// Update window information.
|
||||
d.windowEnd += n
|
||||
d.blockStart = d.windowEnd
|
||||
s.index = n
|
||||
}
|
||||
|
||||
// Try to find a match starting at index whose length is greater than prevSize.
|
||||
// We only look at chainCount possibilities before giving up.
|
||||
// pos = s.index, prevHead = s.chainHead-s.hashOffset, prevLength=minMatchLength-1, lookahead
|
||||
func (d *compressor) findMatch(pos int, prevHead int, lookahead int) (length, offset int, ok bool) {
|
||||
minMatchLook := min(lookahead, maxMatchLength)
|
||||
|
||||
win := d.window[0 : pos+minMatchLook]
|
||||
|
||||
// We quit when we get a match that's at least nice long
|
||||
nice := min(d.nice, len(win)-pos)
|
||||
|
||||
// If we've got a match that's good enough, only look in 1/4 the chain.
|
||||
tries := d.chain
|
||||
length = minMatchLength - 1
|
||||
|
||||
wEnd := win[pos+length]
|
||||
wPos := win[pos:]
|
||||
minIndex := max(pos-windowSize, 0)
|
||||
offset = 0
|
||||
|
||||
if d.chain < 100 {
|
||||
for i := prevHead; tries > 0; tries-- {
|
||||
if wEnd == win[i+length] {
|
||||
n := matchLen(win[i:i+minMatchLook], wPos)
|
||||
if n > length {
|
||||
length = n
|
||||
offset = pos - i
|
||||
ok = true
|
||||
if n >= nice {
|
||||
// The match is good enough that we don't try to find a better one.
|
||||
break
|
||||
}
|
||||
wEnd = win[pos+n]
|
||||
}
|
||||
}
|
||||
if i <= minIndex {
|
||||
// hashPrev[i & windowMask] has already been overwritten, so stop now.
|
||||
break
|
||||
}
|
||||
i = int(d.state.hashPrev[i&windowMask]) - d.state.hashOffset
|
||||
if i < minIndex {
|
||||
break
|
||||
}
|
||||
}
|
||||
return
|
||||
}
|
||||
|
||||
// Minimum gain to accept a match.
|
||||
cGain := 4
|
||||
|
||||
// Some like it higher (CSV), some like it lower (JSON)
|
||||
const baseCost = 3
|
||||
// Base is 4 bytes at with an additional cost.
|
||||
// Matches must be better than this.
|
||||
|
||||
for i := prevHead; tries > 0; tries-- {
|
||||
if wEnd == win[i+length] {
|
||||
n := matchLen(win[i:i+minMatchLook], wPos)
|
||||
if n > length {
|
||||
// Calculate gain. Estimate
|
||||
newGain := d.h.bitLengthRaw(wPos[:n]) - int(offsetExtraBits[offsetCode(uint32(pos-i))]) - baseCost - int(lengthExtraBits[lengthCodes[(n-3)&255]])
|
||||
|
||||
//fmt.Println("gain:", newGain, "prev:", cGain, "raw:", d.h.bitLengthRaw(wPos[:n]), "this-len:", n, "prev-len:", length)
|
||||
if newGain > cGain {
|
||||
length = n
|
||||
offset = pos - i
|
||||
cGain = newGain
|
||||
ok = true
|
||||
if n >= nice {
|
||||
// The match is good enough that we don't try to find a better one.
|
||||
break
|
||||
}
|
||||
wEnd = win[pos+n]
|
||||
}
|
||||
}
|
||||
}
|
||||
if i <= minIndex {
|
||||
// hashPrev[i & windowMask] has already been overwritten, so stop now.
|
||||
break
|
||||
}
|
||||
i = int(d.state.hashPrev[i&windowMask]) - d.state.hashOffset
|
||||
if i < minIndex {
|
||||
break
|
||||
}
|
||||
}
|
||||
return
|
||||
}
|
||||
|
||||
func (d *compressor) writeStoredBlock(buf []byte) error {
|
||||
if d.w.writeStoredHeader(len(buf), false); d.w.err != nil {
|
||||
return d.w.err
|
||||
}
|
||||
d.w.writeBytes(buf)
|
||||
return d.w.err
|
||||
}
|
||||
|
||||
// hash4 returns a hash representation of the first 4 bytes
|
||||
// of the supplied slice.
|
||||
// The caller must ensure that len(b) >= 4.
|
||||
func hash4(b []byte) uint32 {
|
||||
return hash4u(le.Load32(b, 0), hashBits)
|
||||
}
|
||||
|
||||
// hash4 returns the hash of u to fit in a hash table with h bits.
|
||||
// Preferably h should be a constant and should always be <32.
|
||||
func hash4u(u uint32, h uint8) uint32 {
|
||||
return (u * prime4bytes) >> (32 - h)
|
||||
}
|
||||
|
||||
// bulkHash4 will compute hashes using the same
|
||||
// algorithm as hash4
|
||||
func bulkHash4(b []byte, dst []uint32) {
|
||||
if len(b) < 4 {
|
||||
return
|
||||
}
|
||||
hb := le.Load32(b, 0)
|
||||
|
||||
dst[0] = hash4u(hb, hashBits)
|
||||
end := len(b) - 4 + 1
|
||||
for i := 1; i < end; i++ {
|
||||
hb = (hb >> 8) | uint32(b[i+3])<<24
|
||||
dst[i] = hash4u(hb, hashBits)
|
||||
}
|
||||
}
|
||||
|
||||
func (d *compressor) initDeflate() {
|
||||
d.window = make([]byte, 2*windowSize)
|
||||
d.byteAvailable = false
|
||||
d.err = nil
|
||||
if d.state == nil {
|
||||
return
|
||||
}
|
||||
s := d.state
|
||||
s.index = 0
|
||||
s.hashOffset = 1
|
||||
s.length = minMatchLength - 1
|
||||
s.offset = 0
|
||||
s.chainHead = -1
|
||||
}
|
||||
|
||||
// deflateLazy is the same as deflate, but with d.fastSkipHashing == skipNever,
|
||||
// meaning it always has lazy matching on.
|
||||
func (d *compressor) deflateLazy() {
|
||||
s := d.state
|
||||
// Sanity enables additional runtime tests.
|
||||
// It's intended to be used during development
|
||||
// to supplement the currently ad-hoc unit tests.
|
||||
const sanity = debugDeflate
|
||||
|
||||
if d.windowEnd-s.index < minMatchLength+maxMatchLength && !d.sync {
|
||||
return
|
||||
}
|
||||
if d.windowEnd != s.index && d.chain > 100 {
|
||||
// Get literal huffman coder.
|
||||
if d.h == nil {
|
||||
d.h = newHuffmanEncoder(maxFlateBlockTokens)
|
||||
}
|
||||
var tmp [256]uint16
|
||||
toIndex := d.window[s.index:d.windowEnd]
|
||||
toIndex = toIndex[:min(len(toIndex), maxFlateBlockTokens)]
|
||||
for _, v := range toIndex {
|
||||
tmp[v]++
|
||||
}
|
||||
d.h.generate(tmp[:], 15)
|
||||
}
|
||||
|
||||
s.maxInsertIndex = d.windowEnd - (minMatchLength - 1)
|
||||
|
||||
for {
|
||||
if sanity && s.index > d.windowEnd {
|
||||
panic("index > windowEnd")
|
||||
}
|
||||
lookahead := d.windowEnd - s.index
|
||||
if lookahead < minMatchLength+maxMatchLength {
|
||||
if !d.sync {
|
||||
return
|
||||
}
|
||||
if sanity && s.index > d.windowEnd {
|
||||
panic("index > windowEnd")
|
||||
}
|
||||
if lookahead == 0 {
|
||||
// Flush current output block if any.
|
||||
if d.byteAvailable {
|
||||
// There is still one pending token that needs to be flushed
|
||||
d.tokens.AddLiteral(d.window[s.index-1])
|
||||
d.byteAvailable = false
|
||||
}
|
||||
if d.tokens.n > 0 {
|
||||
if d.err = d.writeBlock(&d.tokens, s.index, false); d.err != nil {
|
||||
return
|
||||
}
|
||||
d.tokens.Reset()
|
||||
}
|
||||
return
|
||||
}
|
||||
}
|
||||
if s.index < s.maxInsertIndex {
|
||||
// Update the hash
|
||||
hash := hash4(d.window[s.index:])
|
||||
ch := s.hashHead[hash]
|
||||
s.chainHead = int(ch)
|
||||
s.hashPrev[s.index&windowMask] = ch
|
||||
s.hashHead[hash] = uint32(s.index + s.hashOffset)
|
||||
}
|
||||
prevLength := s.length
|
||||
prevOffset := s.offset
|
||||
s.length = minMatchLength - 1
|
||||
s.offset = 0
|
||||
minIndex := max(s.index-windowSize, 0)
|
||||
|
||||
if s.chainHead-s.hashOffset >= minIndex && lookahead > prevLength && prevLength < d.lazy {
|
||||
if newLength, newOffset, ok := d.findMatch(s.index, s.chainHead-s.hashOffset, lookahead); ok {
|
||||
s.length = newLength
|
||||
s.offset = newOffset
|
||||
}
|
||||
}
|
||||
|
||||
if prevLength >= minMatchLength && s.length <= prevLength {
|
||||
// No better match, but check for better match at end...
|
||||
//
|
||||
// Skip forward a number of bytes.
|
||||
// Offset of 2 seems to yield best results. 3 is sometimes better.
|
||||
const checkOff = 2
|
||||
|
||||
// Check all, except full length
|
||||
if prevLength < maxMatchLength-checkOff {
|
||||
prevIndex := s.index - 1
|
||||
if prevIndex+prevLength < s.maxInsertIndex {
|
||||
end := min(lookahead, maxMatchLength+checkOff)
|
||||
end += prevIndex
|
||||
|
||||
// Hash at match end.
|
||||
h := hash4(d.window[prevIndex+prevLength:])
|
||||
ch2 := int(s.hashHead[h]) - s.hashOffset - prevLength
|
||||
if prevIndex-ch2 != prevOffset && ch2 > minIndex+checkOff {
|
||||
length := matchLen(d.window[prevIndex+checkOff:end], d.window[ch2+checkOff:])
|
||||
// It seems like a pure length metric is best.
|
||||
if length > prevLength {
|
||||
prevLength = length
|
||||
prevOffset = prevIndex - ch2
|
||||
|
||||
// Extend back...
|
||||
for i := checkOff - 1; i >= 0; i-- {
|
||||
if prevLength >= maxMatchLength || d.window[prevIndex+i] != d.window[ch2+i] {
|
||||
// Emit tokens we "owe"
|
||||
for j := 0; j <= i; j++ {
|
||||
d.tokens.AddLiteral(d.window[prevIndex+j])
|
||||
if d.tokens.n == maxFlateBlockTokens {
|
||||
// The block includes the current character
|
||||
if d.err = d.writeBlock(&d.tokens, s.index, false); d.err != nil {
|
||||
return
|
||||
}
|
||||
d.tokens.Reset()
|
||||
}
|
||||
s.index++
|
||||
if s.index < s.maxInsertIndex {
|
||||
h := hash4(d.window[s.index:])
|
||||
ch := s.hashHead[h]
|
||||
s.chainHead = int(ch)
|
||||
s.hashPrev[s.index&windowMask] = ch
|
||||
s.hashHead[h] = uint32(s.index + s.hashOffset)
|
||||
}
|
||||
}
|
||||
break
|
||||
} else {
|
||||
prevLength++
|
||||
}
|
||||
}
|
||||
} else if false {
|
||||
// Check one further ahead.
|
||||
// Only rarely better, disabled for now.
|
||||
prevIndex++
|
||||
h := hash4(d.window[prevIndex+prevLength:])
|
||||
ch2 := int(s.hashHead[h]) - s.hashOffset - prevLength
|
||||
if prevIndex-ch2 != prevOffset && ch2 > minIndex+checkOff {
|
||||
length := matchLen(d.window[prevIndex+checkOff:end], d.window[ch2+checkOff:])
|
||||
// It seems like a pure length metric is best.
|
||||
if length > prevLength+checkOff {
|
||||
prevLength = length
|
||||
prevOffset = prevIndex - ch2
|
||||
prevIndex--
|
||||
|
||||
// Extend back...
|
||||
for i := checkOff; i >= 0; i-- {
|
||||
if prevLength >= maxMatchLength || d.window[prevIndex+i] != d.window[ch2+i-1] {
|
||||
// Emit tokens we "owe"
|
||||
for j := 0; j <= i; j++ {
|
||||
d.tokens.AddLiteral(d.window[prevIndex+j])
|
||||
if d.tokens.n == maxFlateBlockTokens {
|
||||
// The block includes the current character
|
||||
if d.err = d.writeBlock(&d.tokens, s.index, false); d.err != nil {
|
||||
return
|
||||
}
|
||||
d.tokens.Reset()
|
||||
}
|
||||
s.index++
|
||||
if s.index < s.maxInsertIndex {
|
||||
h := hash4(d.window[s.index:])
|
||||
ch := s.hashHead[h]
|
||||
s.chainHead = int(ch)
|
||||
s.hashPrev[s.index&windowMask] = ch
|
||||
s.hashHead[h] = uint32(s.index + s.hashOffset)
|
||||
}
|
||||
}
|
||||
break
|
||||
} else {
|
||||
prevLength++
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
// There was a match at the previous step, and the current match is
|
||||
// not better. Output the previous match.
|
||||
d.tokens.AddMatch(uint32(prevLength-3), uint32(prevOffset-minOffsetSize))
|
||||
|
||||
// Insert in the hash table all strings up to the end of the match.
|
||||
// index and index-1 are already inserted. If there is not enough
|
||||
// lookahead, the last two strings are not inserted into the hash
|
||||
// table.
|
||||
newIndex := s.index + prevLength - 1
|
||||
// Calculate missing hashes
|
||||
end := min(newIndex, s.maxInsertIndex)
|
||||
end += minMatchLength - 1
|
||||
startindex := min(s.index+1, s.maxInsertIndex)
|
||||
tocheck := d.window[startindex:end]
|
||||
dstSize := len(tocheck) - minMatchLength + 1
|
||||
if dstSize > 0 {
|
||||
dst := s.hashMatch[:dstSize]
|
||||
bulkHash4(tocheck, dst)
|
||||
var newH uint32
|
||||
for i, val := range dst {
|
||||
di := i + startindex
|
||||
newH = val & hashMask
|
||||
// Get previous value with the same hash.
|
||||
// Our chain should point to the previous value.
|
||||
s.hashPrev[di&windowMask] = s.hashHead[newH]
|
||||
// Set the head of the hash chain to us.
|
||||
s.hashHead[newH] = uint32(di + s.hashOffset)
|
||||
}
|
||||
}
|
||||
|
||||
s.index = newIndex
|
||||
d.byteAvailable = false
|
||||
s.length = minMatchLength - 1
|
||||
if d.tokens.n == maxFlateBlockTokens {
|
||||
// The block includes the current character
|
||||
if d.err = d.writeBlock(&d.tokens, s.index, false); d.err != nil {
|
||||
return
|
||||
}
|
||||
d.tokens.Reset()
|
||||
}
|
||||
s.ii = 0
|
||||
} else {
|
||||
// Reset, if we got a match this run.
|
||||
if s.length >= minMatchLength {
|
||||
s.ii = 0
|
||||
}
|
||||
// We have a byte waiting. Emit it.
|
||||
if d.byteAvailable {
|
||||
s.ii++
|
||||
d.tokens.AddLiteral(d.window[s.index-1])
|
||||
if d.tokens.n == maxFlateBlockTokens {
|
||||
if d.err = d.writeBlock(&d.tokens, s.index, false); d.err != nil {
|
||||
return
|
||||
}
|
||||
d.tokens.Reset()
|
||||
}
|
||||
s.index++
|
||||
|
||||
// If we have a long run of no matches, skip additional bytes
|
||||
// Resets when s.ii overflows after 64KB.
|
||||
if n := int(s.ii) - d.chain; n > 0 {
|
||||
n = 1 + int(n>>6)
|
||||
for j := 0; j < n; j++ {
|
||||
if s.index >= d.windowEnd-1 {
|
||||
break
|
||||
}
|
||||
d.tokens.AddLiteral(d.window[s.index-1])
|
||||
if d.tokens.n == maxFlateBlockTokens {
|
||||
if d.err = d.writeBlock(&d.tokens, s.index, false); d.err != nil {
|
||||
return
|
||||
}
|
||||
d.tokens.Reset()
|
||||
}
|
||||
// Index...
|
||||
if s.index < s.maxInsertIndex {
|
||||
h := hash4(d.window[s.index:])
|
||||
ch := s.hashHead[h]
|
||||
s.chainHead = int(ch)
|
||||
s.hashPrev[s.index&windowMask] = ch
|
||||
s.hashHead[h] = uint32(s.index + s.hashOffset)
|
||||
}
|
||||
s.index++
|
||||
}
|
||||
// Flush last byte
|
||||
d.tokens.AddLiteral(d.window[s.index-1])
|
||||
d.byteAvailable = false
|
||||
// s.length = minMatchLength - 1 // not needed, since s.ii is reset above, so it should never be > minMatchLength
|
||||
if d.tokens.n == maxFlateBlockTokens {
|
||||
if d.err = d.writeBlock(&d.tokens, s.index, false); d.err != nil {
|
||||
return
|
||||
}
|
||||
d.tokens.Reset()
|
||||
}
|
||||
}
|
||||
} else {
|
||||
s.index++
|
||||
d.byteAvailable = true
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
func (d *compressor) store() {
|
||||
if d.windowEnd > 0 && (d.windowEnd == maxStoreBlockSize || d.sync) {
|
||||
d.err = d.writeStoredBlock(d.window[:d.windowEnd])
|
||||
d.windowEnd = 0
|
||||
}
|
||||
}
|
||||
|
||||
// fillWindow will fill the buffer with data for huffman-only compression.
|
||||
// The number of bytes copied is returned.
|
||||
func (d *compressor) fillBlock(b []byte) int {
|
||||
n := copy(d.window[d.windowEnd:], b)
|
||||
d.windowEnd += n
|
||||
return n
|
||||
}
|
||||
|
||||
// storeHuff will compress and store the currently added data,
|
||||
// if enough has been accumulated or we at the end of the stream.
|
||||
// Any error that occurred will be in d.err
|
||||
func (d *compressor) storeHuff() {
|
||||
if d.windowEnd < len(d.window) && !d.sync || d.windowEnd == 0 {
|
||||
return
|
||||
}
|
||||
d.w.writeBlockHuff(false, d.window[:d.windowEnd], d.sync)
|
||||
d.err = d.w.err
|
||||
d.windowEnd = 0
|
||||
}
|
||||
|
||||
// storeFast will compress and store the currently added data,
|
||||
// if enough has been accumulated or we at the end of the stream.
|
||||
// Any error that occurred will be in d.err
|
||||
func (d *compressor) storeFast() {
|
||||
// We only compress if we have maxStoreBlockSize.
|
||||
if d.windowEnd < len(d.window) {
|
||||
if !d.sync {
|
||||
return
|
||||
}
|
||||
// Handle extremely small sizes.
|
||||
if d.windowEnd < 128 {
|
||||
if d.windowEnd == 0 {
|
||||
return
|
||||
}
|
||||
if d.windowEnd <= 32 {
|
||||
d.err = d.writeStoredBlock(d.window[:d.windowEnd])
|
||||
} else {
|
||||
d.w.writeBlockHuff(false, d.window[:d.windowEnd], true)
|
||||
d.err = d.w.err
|
||||
}
|
||||
d.tokens.Reset()
|
||||
d.windowEnd = 0
|
||||
d.fast.Reset()
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
d.fast.Encode(&d.tokens, d.window[:d.windowEnd])
|
||||
// If we made zero matches, store the block as is.
|
||||
if d.tokens.n == 0 {
|
||||
d.err = d.writeStoredBlock(d.window[:d.windowEnd])
|
||||
// If we removed less than 1/16th, huffman compress the block.
|
||||
} else if int(d.tokens.n) > d.windowEnd-(d.windowEnd>>4) {
|
||||
d.w.writeBlockHuff(false, d.window[:d.windowEnd], d.sync)
|
||||
d.err = d.w.err
|
||||
} else {
|
||||
d.w.writeBlockDynamic(&d.tokens, false, d.window[:d.windowEnd], d.sync)
|
||||
d.err = d.w.err
|
||||
}
|
||||
d.tokens.Reset()
|
||||
d.windowEnd = 0
|
||||
}
|
||||
|
||||
// write will add input byte to the stream.
|
||||
// Unless an error occurs all bytes will be consumed.
|
||||
func (d *compressor) write(b []byte) (n int, err error) {
|
||||
if d.err != nil {
|
||||
return 0, d.err
|
||||
}
|
||||
n = len(b)
|
||||
for len(b) > 0 {
|
||||
if d.windowEnd == len(d.window) || d.sync {
|
||||
d.step(d)
|
||||
}
|
||||
b = b[d.fill(d, b):]
|
||||
if d.err != nil {
|
||||
return 0, d.err
|
||||
}
|
||||
}
|
||||
return n, d.err
|
||||
}
|
||||
|
||||
func (d *compressor) syncFlush() error {
|
||||
d.sync = true
|
||||
if d.err != nil {
|
||||
return d.err
|
||||
}
|
||||
d.step(d)
|
||||
if d.err == nil {
|
||||
d.w.writeStoredHeader(0, false)
|
||||
d.w.flush()
|
||||
d.err = d.w.err
|
||||
}
|
||||
d.sync = false
|
||||
return d.err
|
||||
}
|
||||
|
||||
func (d *compressor) init(w io.Writer, level int) (err error) {
|
||||
d.w = newHuffmanBitWriter(w)
|
||||
|
||||
switch {
|
||||
case level == NoCompression:
|
||||
d.window = make([]byte, maxStoreBlockSize)
|
||||
d.fill = (*compressor).fillBlock
|
||||
d.step = (*compressor).store
|
||||
case level == ConstantCompression:
|
||||
d.w.logNewTablePenalty = 10
|
||||
d.window = make([]byte, 32<<10)
|
||||
d.fill = (*compressor).fillBlock
|
||||
d.step = (*compressor).storeHuff
|
||||
case level == DefaultCompression:
|
||||
level = 5
|
||||
fallthrough
|
||||
case level >= 1 && level <= 6:
|
||||
d.w.logNewTablePenalty = 7
|
||||
d.fast = newFastEnc(level)
|
||||
d.window = make([]byte, maxStoreBlockSize)
|
||||
d.fill = (*compressor).fillBlock
|
||||
d.step = (*compressor).storeFast
|
||||
case 7 <= level && level <= 9:
|
||||
d.w.logNewTablePenalty = 8
|
||||
d.state = &advancedState{}
|
||||
d.compressionLevel = levels[level]
|
||||
d.initDeflate()
|
||||
d.fill = (*compressor).fillDeflate
|
||||
d.step = (*compressor).deflateLazy
|
||||
case -level >= MinCustomWindowSize && -level <= MaxCustomWindowSize:
|
||||
d.w.logNewTablePenalty = 7
|
||||
d.fast = &fastEncL5Window{maxOffset: int32(-level), cur: maxStoreBlockSize}
|
||||
d.window = make([]byte, maxStoreBlockSize)
|
||||
d.fill = (*compressor).fillBlock
|
||||
d.step = (*compressor).storeFast
|
||||
default:
|
||||
return fmt.Errorf("flate: invalid compression level %d: want value in range [-2, 9]", level)
|
||||
}
|
||||
d.level = level
|
||||
return nil
|
||||
}
|
||||
|
||||
// reset the state of the compressor.
|
||||
func (d *compressor) reset(w io.Writer) {
|
||||
d.w.reset(w)
|
||||
d.sync = false
|
||||
d.err = nil
|
||||
// We only need to reset a few things for Snappy.
|
||||
if d.fast != nil {
|
||||
d.fast.Reset()
|
||||
d.windowEnd = 0
|
||||
d.tokens.Reset()
|
||||
return
|
||||
}
|
||||
switch d.compressionLevel.chain {
|
||||
case 0:
|
||||
// level was NoCompression or ConstantCompression.
|
||||
d.windowEnd = 0
|
||||
default:
|
||||
s := d.state
|
||||
s.chainHead = -1
|
||||
for i := range s.hashHead {
|
||||
s.hashHead[i] = 0
|
||||
}
|
||||
for i := range s.hashPrev {
|
||||
s.hashPrev[i] = 0
|
||||
}
|
||||
s.hashOffset = 1
|
||||
s.index, d.windowEnd = 0, 0
|
||||
d.blockStart, d.byteAvailable = 0, false
|
||||
d.tokens.Reset()
|
||||
s.length = minMatchLength - 1
|
||||
s.offset = 0
|
||||
s.ii = 0
|
||||
s.maxInsertIndex = 0
|
||||
}
|
||||
}
|
||||
|
||||
func (d *compressor) close() error {
|
||||
if d.err != nil {
|
||||
return d.err
|
||||
}
|
||||
d.sync = true
|
||||
d.step(d)
|
||||
if d.err != nil {
|
||||
return d.err
|
||||
}
|
||||
if d.w.writeStoredHeader(0, true); d.w.err != nil {
|
||||
return d.w.err
|
||||
}
|
||||
d.w.flush()
|
||||
d.w.reset(nil)
|
||||
return d.w.err
|
||||
}
|
||||
|
||||
// NewWriter returns a new Writer compressing data at the given level.
|
||||
// Following zlib, levels range from 1 (BestSpeed) to 9 (BestCompression);
|
||||
// higher levels typically run slower but compress more.
|
||||
// Level 0 (NoCompression) does not attempt any compression; it only adds the
|
||||
// necessary DEFLATE framing.
|
||||
// Level -1 (DefaultCompression) uses the default compression level.
|
||||
// Level -2 (ConstantCompression) will use Huffman compression only, giving
|
||||
// a very fast compression for all types of input, but sacrificing considerable
|
||||
// compression efficiency.
|
||||
//
|
||||
// If level is in the range [-2, 9] then the error returned will be nil.
|
||||
// Otherwise the error returned will be non-nil.
|
||||
func NewWriter(w io.Writer, level int) (*Writer, error) {
|
||||
var dw Writer
|
||||
if err := dw.d.init(w, level); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
return &dw, nil
|
||||
}
|
||||
|
||||
// NewWriterDict is like NewWriter but initializes the new
|
||||
// Writer with a preset dictionary. The returned Writer behaves
|
||||
// as if the dictionary had been written to it without producing
|
||||
// any compressed output. The compressed data written to w
|
||||
// can only be decompressed by a Reader initialized with the
|
||||
// same dictionary.
|
||||
func NewWriterDict(w io.Writer, level int, dict []byte) (*Writer, error) {
|
||||
zw, err := NewWriter(w, level)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
zw.d.fillWindow(dict)
|
||||
zw.dict = append(zw.dict, dict...) // duplicate dictionary for Reset method.
|
||||
return zw, err
|
||||
}
|
||||
|
||||
// MinCustomWindowSize is the minimum window size that can be sent to NewWriterWindow.
|
||||
const MinCustomWindowSize = 32
|
||||
|
||||
// MaxCustomWindowSize is the maximum custom window that can be sent to NewWriterWindow.
|
||||
const MaxCustomWindowSize = windowSize
|
||||
|
||||
// NewWriterWindow returns a new Writer compressing data with a custom window size.
|
||||
// windowSize must be from MinCustomWindowSize to MaxCustomWindowSize.
|
||||
func NewWriterWindow(w io.Writer, windowSize int) (*Writer, error) {
|
||||
if windowSize < MinCustomWindowSize {
|
||||
return nil, errors.New("flate: requested window size less than MinWindowSize")
|
||||
}
|
||||
if windowSize > MaxCustomWindowSize {
|
||||
return nil, errors.New("flate: requested window size bigger than MaxCustomWindowSize")
|
||||
}
|
||||
var dw Writer
|
||||
if err := dw.d.init(w, -windowSize); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
return &dw, nil
|
||||
}
|
||||
|
||||
// A Writer takes data written to it and writes the compressed
|
||||
// form of that data to an underlying writer (see NewWriter).
|
||||
type Writer struct {
|
||||
d compressor
|
||||
dict []byte
|
||||
}
|
||||
|
||||
// Write writes data to w, which will eventually write the
|
||||
// compressed form of data to its underlying writer.
|
||||
func (w *Writer) Write(data []byte) (n int, err error) {
|
||||
return w.d.write(data)
|
||||
}
|
||||
|
||||
// Flush flushes any pending data to the underlying writer.
|
||||
// It is useful mainly in compressed network protocols, to ensure that
|
||||
// a remote reader has enough data to reconstruct a packet.
|
||||
// Flush does not return until the data has been written.
|
||||
// Calling Flush when there is no pending data still causes the Writer
|
||||
// to emit a sync marker of at least 4 bytes.
|
||||
// If the underlying writer returns an error, Flush returns that error.
|
||||
//
|
||||
// In the terminology of the zlib library, Flush is equivalent to Z_SYNC_FLUSH.
|
||||
func (w *Writer) Flush() error {
|
||||
// For more about flushing:
|
||||
// http://www.bolet.org/~pornin/deflate-flush.html
|
||||
return w.d.syncFlush()
|
||||
}
|
||||
|
||||
// Close flushes and closes the writer.
|
||||
func (w *Writer) Close() error {
|
||||
return w.d.close()
|
||||
}
|
||||
|
||||
// Reset discards the writer's state and makes it equivalent to
|
||||
// the result of NewWriter or NewWriterDict called with dst
|
||||
// and w's level and dictionary.
|
||||
func (w *Writer) Reset(dst io.Writer) {
|
||||
if len(w.dict) > 0 {
|
||||
// w was created with NewWriterDict
|
||||
w.d.reset(dst)
|
||||
if dst != nil {
|
||||
w.d.fillWindow(w.dict)
|
||||
}
|
||||
} else {
|
||||
// w was created with NewWriter
|
||||
w.d.reset(dst)
|
||||
}
|
||||
}
|
||||
|
||||
// ResetDict discards the writer's state and makes it equivalent to
|
||||
// the result of NewWriter or NewWriterDict called with dst
|
||||
// and w's level, but sets a specific dictionary.
|
||||
func (w *Writer) ResetDict(dst io.Writer, dict []byte) {
|
||||
w.dict = dict
|
||||
w.d.reset(dst)
|
||||
w.d.fillWindow(w.dict)
|
||||
}
|
||||
Generated
Vendored
-199
@@ -1,199 +0,0 @@
|
||||
// Copyright 2016 The Go Authors. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package flate
|
||||
|
||||
// dictDecoder implements the LZ77 sliding dictionary as used in decompression.
|
||||
// LZ77 decompresses data through sequences of two forms of commands:
|
||||
//
|
||||
// - Literal insertions: Runs of one or more symbols are inserted into the data
|
||||
// stream as is. This is accomplished through the writeByte method for a
|
||||
// single symbol, or combinations of writeSlice/writeMark for multiple symbols.
|
||||
// Any valid stream must start with a literal insertion if no preset dictionary
|
||||
// is used.
|
||||
//
|
||||
// - Backward copies: Runs of one or more symbols are copied from previously
|
||||
// emitted data. Backward copies come as the tuple (dist, length) where dist
|
||||
// determines how far back in the stream to copy from and length determines how
|
||||
// many bytes to copy. Note that it is valid for the length to be greater than
|
||||
// the distance. Since LZ77 uses forward copies, that situation is used to
|
||||
// perform a form of run-length encoding on repeated runs of symbols.
|
||||
// The writeCopy and tryWriteCopy are used to implement this command.
|
||||
//
|
||||
// For performance reasons, this implementation performs little to no sanity
|
||||
// checks about the arguments. As such, the invariants documented for each
|
||||
// method call must be respected.
|
||||
type dictDecoder struct {
|
||||
hist []byte // Sliding window history
|
||||
|
||||
// Invariant: 0 <= rdPos <= wrPos <= len(hist)
|
||||
wrPos int // Current output position in buffer
|
||||
rdPos int // Have emitted hist[:rdPos] already
|
||||
flushed int64 // Total bytes returned by readFlush since init
|
||||
full bool // Has a full window length been written yet?
|
||||
}
|
||||
|
||||
// init initializes dictDecoder to have a sliding window dictionary of the given
|
||||
// size. If a preset dict is provided, it will initialize the dictionary with
|
||||
// the contents of dict.
|
||||
func (dd *dictDecoder) init(size int, dict []byte) {
|
||||
*dd = dictDecoder{hist: dd.hist}
|
||||
|
||||
if cap(dd.hist) < size {
|
||||
dd.hist = make([]byte, size)
|
||||
}
|
||||
dd.hist = dd.hist[:size]
|
||||
|
||||
if len(dict) > len(dd.hist) {
|
||||
dict = dict[len(dict)-len(dd.hist):]
|
||||
}
|
||||
dd.wrPos = copy(dd.hist, dict)
|
||||
if dd.wrPos == len(dd.hist) {
|
||||
dd.wrPos = 0
|
||||
dd.full = true
|
||||
}
|
||||
dd.rdPos = dd.wrPos
|
||||
}
|
||||
|
||||
// histSize reports the total amount of historical data in the dictionary.
|
||||
func (dd *dictDecoder) histSize() int {
|
||||
if dd.full {
|
||||
return len(dd.hist)
|
||||
}
|
||||
return dd.wrPos
|
||||
}
|
||||
|
||||
// availRead reports the number of bytes that can be flushed by readFlush.
|
||||
func (dd *dictDecoder) availRead() int {
|
||||
return dd.wrPos - dd.rdPos
|
||||
}
|
||||
|
||||
// availWrite reports the available amount of output buffer space.
|
||||
func (dd *dictDecoder) availWrite() int {
|
||||
return len(dd.hist) - dd.wrPos
|
||||
}
|
||||
|
||||
// writeSlice returns a slice of the available buffer to write data to.
|
||||
//
|
||||
// This invariant will be kept: len(s) <= availWrite()
|
||||
func (dd *dictDecoder) writeSlice() []byte {
|
||||
return dd.hist[dd.wrPos:]
|
||||
}
|
||||
|
||||
// writeMark advances the writer pointer by cnt.
|
||||
//
|
||||
// This invariant must be kept: 0 <= cnt <= availWrite()
|
||||
func (dd *dictDecoder) writeMark(cnt int) {
|
||||
dd.wrPos += cnt
|
||||
}
|
||||
|
||||
// writeByte writes a single byte to the dictionary.
|
||||
//
|
||||
// This invariant must be kept: 0 < availWrite()
|
||||
func (dd *dictDecoder) writeByte(c byte) {
|
||||
dd.hist[dd.wrPos] = c
|
||||
dd.wrPos++
|
||||
}
|
||||
|
||||
// writeCopy copies a string at a given (dist, length) to the output.
|
||||
// This returns the number of bytes copied and may be less than the requested
|
||||
// length if the available space in the output buffer is too small.
|
||||
//
|
||||
// This invariant must be kept: 0 < dist <= histSize()
|
||||
func (dd *dictDecoder) writeCopy(dist, length int) int {
|
||||
dstBase := dd.wrPos
|
||||
dstPos := dstBase
|
||||
srcPos := dstPos - dist
|
||||
endPos := min(dstPos+length, len(dd.hist))
|
||||
|
||||
// Copy non-overlapping section after destination position.
|
||||
//
|
||||
// This section is non-overlapping in that the copy length for this section
|
||||
// is always less than or equal to the backwards distance. This can occur
|
||||
// if a distance refers to data that wraps-around in the buffer.
|
||||
// Thus, a backwards copy is performed here; that is, the exact bytes in
|
||||
// the source prior to the copy is placed in the destination.
|
||||
if srcPos < 0 {
|
||||
srcPos += len(dd.hist)
|
||||
dstPos += copy(dd.hist[dstPos:endPos], dd.hist[srcPos:])
|
||||
srcPos = 0
|
||||
}
|
||||
|
||||
// Copy possibly overlapping section before destination position.
|
||||
//
|
||||
// This section can overlap if the copy length for this section is larger
|
||||
// than the backwards distance. This is allowed by LZ77 so that repeated
|
||||
// strings can be succinctly represented using (dist, length) pairs.
|
||||
// Thus, a forwards copy is performed here; that is, the bytes copied is
|
||||
// possibly dependent on the resulting bytes in the destination as the copy
|
||||
// progresses along. This is functionally equivalent to the following:
|
||||
//
|
||||
// for i := 0; i < endPos-dstPos; i++ {
|
||||
// dd.hist[dstPos+i] = dd.hist[srcPos+i]
|
||||
// }
|
||||
// dstPos = endPos
|
||||
//
|
||||
for dstPos < endPos {
|
||||
dstPos += copy(dd.hist[dstPos:endPos], dd.hist[srcPos:dstPos])
|
||||
}
|
||||
|
||||
dd.wrPos = dstPos
|
||||
return dstPos - dstBase
|
||||
}
|
||||
|
||||
// tryWriteCopy tries to copy a string at a given (distance, length) to the
|
||||
// output. This specialized version is optimized for short distances.
|
||||
//
|
||||
// This method is designed to be inlined for performance reasons.
|
||||
//
|
||||
// This invariant must be kept: 0 < dist <= histSize()
|
||||
func (dd *dictDecoder) tryWriteCopy(dist, length int) int {
|
||||
dstPos := dd.wrPos
|
||||
endPos := dstPos + length
|
||||
if dstPos < dist || endPos > len(dd.hist) {
|
||||
return 0
|
||||
}
|
||||
dstBase := dstPos
|
||||
srcPos := dstPos - dist
|
||||
|
||||
// Copy possibly overlapping section before destination position.
|
||||
loop:
|
||||
dstPos += copy(dd.hist[dstPos:endPos], dd.hist[srcPos:dstPos])
|
||||
if dstPos < endPos {
|
||||
goto loop // Avoid for-loop so that this function can be inlined
|
||||
}
|
||||
|
||||
dd.wrPos = dstPos
|
||||
return dstPos - dstBase
|
||||
}
|
||||
|
||||
// appendWindow appends the current sliding window (up to len(hist) most recent
|
||||
// bytes, oldest first) to dst.
|
||||
func (dd *dictDecoder) appendWindow(dst []byte) []byte {
|
||||
if dd.full {
|
||||
dst = append(dst, dd.hist[dd.wrPos:]...)
|
||||
return append(dst, dd.hist[:dd.wrPos]...)
|
||||
}
|
||||
return append(dst, dd.hist[:dd.wrPos]...)
|
||||
}
|
||||
|
||||
// readFlush returns a slice of the historical buffer that is ready to be
|
||||
// emitted to the user. The data returned by readFlush must be fully consumed
|
||||
// before calling any other dictDecoder methods.
|
||||
func (dd *dictDecoder) readFlush() []byte {
|
||||
toRead := dd.hist[dd.rdPos:dd.wrPos]
|
||||
dd.flushed += int64(len(toRead))
|
||||
dd.rdPos = dd.wrPos
|
||||
if dd.wrPos == len(dd.hist) {
|
||||
dd.wrPos, dd.rdPos = 0, 0
|
||||
dd.full = true
|
||||
}
|
||||
return toRead
|
||||
}
|
||||
|
||||
// decoded reports the total number of bytes written into the dictionary since
|
||||
// init (i.e. excluding any preset dict bytes).
|
||||
func (dd *dictDecoder) decoded() int64 {
|
||||
return dd.flushed + int64(dd.wrPos-dd.rdPos)
|
||||
}
|
||||
Generated
Vendored
-190
@@ -1,190 +0,0 @@
|
||||
// Copyright 2011 The Snappy-Go Authors. All rights reserved.
|
||||
// Modified for deflate by Klaus Post (c) 2015.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package flate
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
|
||||
"github.com/klauspost/compress/internal/le"
|
||||
"github.com/klauspost/compress/internal/regmask"
|
||||
)
|
||||
|
||||
type fastEnc interface {
|
||||
Encode(dst *tokens, src []byte)
|
||||
Reset()
|
||||
}
|
||||
|
||||
func newFastEnc(level int) fastEnc {
|
||||
switch level {
|
||||
case 1:
|
||||
return &fastEncL1{fastGen: fastGen{cur: maxStoreBlockSize}}
|
||||
case 2:
|
||||
return &fastEncL2{fastGen: fastGen{cur: maxStoreBlockSize}}
|
||||
case 3:
|
||||
return &fastEncL3{fastGen: fastGen{cur: maxStoreBlockSize}}
|
||||
case 4:
|
||||
return &fastEncL4{fastGen: fastGen{cur: maxStoreBlockSize}}
|
||||
case 5:
|
||||
return &fastEncL5{fastGen: fastGen{cur: maxStoreBlockSize}}
|
||||
case 6:
|
||||
return &fastEncL6{fastGen: fastGen{cur: maxStoreBlockSize}}
|
||||
default:
|
||||
panic("invalid level specified")
|
||||
}
|
||||
}
|
||||
|
||||
const (
|
||||
tableBits = 15 // Bits used in the table
|
||||
tableSize = 1 << tableBits // Size of the table
|
||||
tableShift = 32 - tableBits // Right-shift to get the tableBits most significant bits of a uint32.
|
||||
baseMatchOffset = 1 // The smallest match offset
|
||||
baseMatchLength = 3 // The smallest match length per the RFC section 3.2.5
|
||||
maxMatchOffset = 1 << 15 // The largest match offset
|
||||
|
||||
bTableBits = 17 // Bits used in the big tables
|
||||
bTableSize = 1 << bTableBits // Size of the table
|
||||
allocHistory = maxStoreBlockSize * 5 // Size to preallocate for history.
|
||||
bufferReset = (1 << 31) - allocHistory - maxStoreBlockSize - 1 // Reset the buffer offset when reaching this.
|
||||
)
|
||||
|
||||
const (
|
||||
prime3bytes = 506832829
|
||||
prime4bytes = 2654435761
|
||||
prime5bytes = 889523592379
|
||||
prime6bytes = 227718039650203
|
||||
prime7bytes = 58295818150454627
|
||||
prime8bytes = 0xcf1bbcdcb7a56463
|
||||
)
|
||||
|
||||
func load3232(b []byte, i int32) uint32 {
|
||||
return le.Load32(b, i)
|
||||
}
|
||||
|
||||
func load6432(b []byte, i int32) uint64 {
|
||||
return le.Load64(b, i)
|
||||
}
|
||||
|
||||
type tableEntry struct {
|
||||
offset int32
|
||||
}
|
||||
|
||||
// fastGen maintains the table for matches,
|
||||
// and the previous byte block for level 2.
|
||||
// This is the generic implementation.
|
||||
type fastGen struct {
|
||||
hist []byte
|
||||
cur int32
|
||||
}
|
||||
|
||||
func (e *fastGen) addBlock(src []byte) int32 {
|
||||
// check if we have space already
|
||||
if len(e.hist)+len(src) > cap(e.hist) {
|
||||
if cap(e.hist) == 0 {
|
||||
e.hist = make([]byte, 0, allocHistory)
|
||||
} else {
|
||||
if cap(e.hist) < maxMatchOffset*2 {
|
||||
panic("unexpected buffer size")
|
||||
}
|
||||
// Move down
|
||||
offset := int32(len(e.hist)) - maxMatchOffset
|
||||
// copy(e.hist[0:maxMatchOffset], e.hist[offset:])
|
||||
*(*[maxMatchOffset]byte)(e.hist) = *(*[maxMatchOffset]byte)(e.hist[offset:])
|
||||
e.cur += offset
|
||||
e.hist = e.hist[:maxMatchOffset]
|
||||
}
|
||||
}
|
||||
s := int32(len(e.hist))
|
||||
e.hist = append(e.hist, src...)
|
||||
return s
|
||||
}
|
||||
|
||||
type tableEntryPrev struct {
|
||||
Cur tableEntry
|
||||
Prev tableEntry
|
||||
}
|
||||
|
||||
// hash7 returns the hash of the lowest 7 bytes of u to fit in a hash table with h bits.
|
||||
// Preferably h should be a constant and should always be <64.
|
||||
func hash7(u uint64, h uint8) uint32 {
|
||||
return uint32(((u << (64 - 56)) * prime7bytes) >> ((64 - h) & regmask.Shift64ByUint8))
|
||||
}
|
||||
|
||||
// hashLen returns a hash of the lowest mls bytes of with length output bits.
|
||||
// mls must be >=3 and <=8. Any other value will return hash for 4 bytes.
|
||||
// length should always be < 32.
|
||||
// Preferably length and mls should be a constant for inlining.
|
||||
func hashLen(u uint64, length, mls uint8) uint32 {
|
||||
switch mls {
|
||||
case 3:
|
||||
return (uint32(u<<8) * prime3bytes) >> (32 - length)
|
||||
case 5:
|
||||
return uint32(((u << (64 - 40)) * prime5bytes) >> (64 - length))
|
||||
case 6:
|
||||
return uint32(((u << (64 - 48)) * prime6bytes) >> (64 - length))
|
||||
case 7:
|
||||
return uint32(((u << (64 - 56)) * prime7bytes) >> (64 - length))
|
||||
case 8:
|
||||
return uint32((u * prime8bytes) >> (64 - length))
|
||||
default:
|
||||
return (uint32(u) * prime4bytes) >> (32 - length)
|
||||
}
|
||||
}
|
||||
|
||||
// matchlen will return the match length between offsets and t in src.
|
||||
// The maximum length returned is maxMatchLength - 4.
|
||||
// It is assumed that s > t, that t >=0 and s < len(src).
|
||||
func (e *fastGen) matchlen(s, t int, src []byte) int32 {
|
||||
if debugDeflate {
|
||||
if t >= s {
|
||||
panic(fmt.Sprint("t >=s:", t, s))
|
||||
}
|
||||
if int(s) >= len(src) {
|
||||
panic(fmt.Sprint("s >= len(src):", s, len(src)))
|
||||
}
|
||||
if t < 0 {
|
||||
panic(fmt.Sprint("t < 0:", t))
|
||||
}
|
||||
if s-t > maxMatchOffset {
|
||||
panic(fmt.Sprint(s, "-", t, "(", s-t, ") > maxMatchLength (", maxMatchOffset, ")"))
|
||||
}
|
||||
}
|
||||
a := src[s:min(s+maxMatchLength-4, len(src))]
|
||||
b := src[t:]
|
||||
return int32(matchLen(a, b))
|
||||
}
|
||||
|
||||
// matchlenLong will return the match length between offsets and t in src.
|
||||
// It is assumed that s > t, that t >=0 and s < len(src).
|
||||
func (e *fastGen) matchlenLong(s, t int, src []byte) int32 {
|
||||
if debugDeflate {
|
||||
if t >= s {
|
||||
panic(fmt.Sprint("t >=s:", t, s))
|
||||
}
|
||||
if int(s) >= len(src) {
|
||||
panic(fmt.Sprint("s >= len(src):", s, len(src)))
|
||||
}
|
||||
if t < 0 {
|
||||
panic(fmt.Sprint("t < 0:", t))
|
||||
}
|
||||
if s-t > maxMatchOffset {
|
||||
panic(fmt.Sprint(s, "-", t, "(", s-t, ") > maxMatchLength (", maxMatchOffset, ")"))
|
||||
}
|
||||
}
|
||||
return int32(matchLen(src[s:], src[t:]))
|
||||
}
|
||||
|
||||
// Reset the encoding table.
|
||||
func (e *fastGen) Reset() {
|
||||
if cap(e.hist) < allocHistory {
|
||||
e.hist = make([]byte, 0, allocHistory)
|
||||
}
|
||||
// We offset current position so everything will be out of reach.
|
||||
// If we are above the buffer reset it will be cleared anyway since len(hist) == 0.
|
||||
if e.cur <= bufferReset {
|
||||
e.cur += maxMatchOffset + int32(len(e.hist))
|
||||
}
|
||||
e.hist = e.hist[:0]
|
||||
}
|
||||
Generated
Vendored
-1174
File diff suppressed because it is too large
Load Diff
Generated
Vendored
-417
@@ -1,417 +0,0 @@
|
||||
// Copyright 2009 The Go Authors. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package flate
|
||||
|
||||
import (
|
||||
"math"
|
||||
"math/bits"
|
||||
)
|
||||
|
||||
const (
|
||||
maxBitsLimit = 16
|
||||
// number of valid literals
|
||||
literalCount = 286
|
||||
)
|
||||
|
||||
// hcode is a huffman code with a bit code and bit length.
|
||||
type hcode uint32
|
||||
|
||||
func (h hcode) len() uint8 {
|
||||
return uint8(h)
|
||||
}
|
||||
|
||||
func (h hcode) code64() uint64 {
|
||||
return uint64(h >> 8)
|
||||
}
|
||||
|
||||
func (h hcode) zero() bool {
|
||||
return h == 0
|
||||
}
|
||||
|
||||
type huffmanEncoder struct {
|
||||
codes []hcode
|
||||
bitCount [17]int32
|
||||
|
||||
// Allocate a reusable buffer with the longest possible frequency table.
|
||||
// Possible lengths are codegenCodeCount, offsetCodeCount and literalCount.
|
||||
// The largest of these is literalCount, so we allocate for that case.
|
||||
freqcache [literalCount + 1]literalNode
|
||||
}
|
||||
|
||||
type literalNode struct {
|
||||
literal uint16
|
||||
freq uint16
|
||||
}
|
||||
|
||||
// A levelInfo describes the state of the constructed tree for a given depth.
|
||||
type levelInfo struct {
|
||||
// Our level. for better printing
|
||||
level int32
|
||||
|
||||
// The frequency of the last node at this level
|
||||
lastFreq int32
|
||||
|
||||
// The frequency of the next character to add to this level
|
||||
nextCharFreq int32
|
||||
|
||||
// The frequency of the next pair (from level below) to add to this level.
|
||||
// Only valid if the "needed" value of the next lower level is 0.
|
||||
nextPairFreq int32
|
||||
|
||||
// The number of chains remaining to generate for this level before moving
|
||||
// up to the next level
|
||||
needed int32
|
||||
}
|
||||
|
||||
// set sets the code and length of an hcode.
|
||||
func (h *hcode) set(code uint16, length uint8) {
|
||||
*h = hcode(length) | (hcode(code) << 8)
|
||||
}
|
||||
|
||||
func newhcode(code uint16, length uint8) hcode {
|
||||
return hcode(length) | (hcode(code) << 8)
|
||||
}
|
||||
|
||||
func reverseBits(number uint16, bitLength byte) uint16 {
|
||||
return bits.Reverse16(number << ((16 - bitLength) & 15))
|
||||
}
|
||||
|
||||
func maxNode() literalNode { return literalNode{math.MaxUint16, math.MaxUint16} }
|
||||
|
||||
func newHuffmanEncoder(size int) *huffmanEncoder {
|
||||
// Make capacity to next power of two.
|
||||
c := uint(bits.Len32(uint32(size - 1)))
|
||||
return &huffmanEncoder{codes: make([]hcode, size, 1<<c)}
|
||||
}
|
||||
|
||||
// Generates a HuffmanCode corresponding to the fixed literal table
|
||||
func generateFixedLiteralEncoding() *huffmanEncoder {
|
||||
h := newHuffmanEncoder(literalCount)
|
||||
codes := h.codes
|
||||
var ch uint16
|
||||
for ch = range uint16(literalCount) {
|
||||
var bits uint16
|
||||
var size uint8
|
||||
switch {
|
||||
case ch < 144:
|
||||
// size 8, 000110000 .. 10111111
|
||||
bits = ch + 48
|
||||
size = 8
|
||||
case ch < 256:
|
||||
// size 9, 110010000 .. 111111111
|
||||
bits = ch + 400 - 144
|
||||
size = 9
|
||||
case ch < 280:
|
||||
// size 7, 0000000 .. 0010111
|
||||
bits = ch - 256
|
||||
size = 7
|
||||
default:
|
||||
// size 8, 11000000 .. 11000111
|
||||
bits = ch + 192 - 280
|
||||
size = 8
|
||||
}
|
||||
codes[ch] = newhcode(reverseBits(bits, size), size)
|
||||
}
|
||||
return h
|
||||
}
|
||||
|
||||
func generateFixedOffsetEncoding() *huffmanEncoder {
|
||||
h := newHuffmanEncoder(30)
|
||||
codes := h.codes
|
||||
for ch := range codes {
|
||||
codes[ch] = newhcode(reverseBits(uint16(ch), 5), 5)
|
||||
}
|
||||
return h
|
||||
}
|
||||
|
||||
var fixedLiteralEncoding = generateFixedLiteralEncoding()
|
||||
var fixedOffsetEncoding = generateFixedOffsetEncoding()
|
||||
|
||||
func (h *huffmanEncoder) bitLength(freq []uint16) int {
|
||||
var total int
|
||||
for i, f := range freq {
|
||||
if f != 0 {
|
||||
total += int(f) * int(h.codes[i].len())
|
||||
}
|
||||
}
|
||||
return total
|
||||
}
|
||||
|
||||
func (h *huffmanEncoder) bitLengthRaw(b []byte) int {
|
||||
var total int
|
||||
for _, f := range b {
|
||||
total += int(h.codes[f].len())
|
||||
}
|
||||
return total
|
||||
}
|
||||
|
||||
// canReuseBits returns the number of bits or math.MaxInt32 if the encoder cannot be reused.
|
||||
func (h *huffmanEncoder) canReuseBits(freq []uint16) int {
|
||||
var total int
|
||||
for i, f := range freq {
|
||||
if f != 0 {
|
||||
code := h.codes[i]
|
||||
if code.zero() {
|
||||
return math.MaxInt32
|
||||
}
|
||||
total += int(f) * int(code.len())
|
||||
}
|
||||
}
|
||||
return total
|
||||
}
|
||||
|
||||
// Return the number of literals assigned to each bit size in the Huffman encoding
|
||||
//
|
||||
// This method is only called when list.length >= 3
|
||||
// The cases of 0, 1, and 2 literals are handled by special case code.
|
||||
//
|
||||
// list An array of the literals with non-zero frequencies
|
||||
//
|
||||
// and their associated frequencies. The array is in order of increasing
|
||||
// frequency, and has as its last element a special element with frequency
|
||||
// MaxInt32
|
||||
//
|
||||
// maxBits The maximum number of bits that should be used to encode any literal.
|
||||
//
|
||||
// Must be less than 16.
|
||||
//
|
||||
// return An integer array in which array[i] indicates the number of literals
|
||||
//
|
||||
// that should be encoded in i bits.
|
||||
func (h *huffmanEncoder) bitCounts(list []literalNode, maxBits int32) []int32 {
|
||||
if maxBits >= maxBitsLimit {
|
||||
panic("flate: maxBits too large")
|
||||
}
|
||||
n := int32(len(list))
|
||||
list = list[0 : n+1]
|
||||
list[n] = maxNode()
|
||||
|
||||
// The tree can't have greater depth than n - 1, no matter what. This
|
||||
// saves a little bit of work in some small cases
|
||||
if maxBits > n-1 {
|
||||
maxBits = n - 1
|
||||
}
|
||||
|
||||
// Create information about each of the levels.
|
||||
// A bogus "Level 0" whose sole purpose is so that
|
||||
// level1.prev.needed==0. This makes level1.nextPairFreq
|
||||
// be a legitimate value that never gets chosen.
|
||||
var levels [maxBitsLimit]levelInfo
|
||||
// leafCounts[i] counts the number of literals at the left
|
||||
// of ancestors of the rightmost node at level i.
|
||||
// leafCounts[i][j] is the number of literals at the left
|
||||
// of the level j ancestor.
|
||||
var leafCounts [maxBitsLimit][maxBitsLimit]int32
|
||||
|
||||
// Descending to only have 1 bounds check.
|
||||
l2f := int32(list[2].freq)
|
||||
l1f := int32(list[1].freq)
|
||||
l0f := int32(list[0].freq) + int32(list[1].freq)
|
||||
|
||||
for level := int32(1); level <= maxBits; level++ {
|
||||
// For every level, the first two items are the first two characters.
|
||||
// We initialize the levels as if we had already figured this out.
|
||||
levels[level] = levelInfo{
|
||||
level: level,
|
||||
lastFreq: l1f,
|
||||
nextCharFreq: l2f,
|
||||
nextPairFreq: l0f,
|
||||
}
|
||||
leafCounts[level][level] = 2
|
||||
if level == 1 {
|
||||
levels[level].nextPairFreq = math.MaxInt32
|
||||
}
|
||||
}
|
||||
|
||||
// We need a total of 2*n - 2 items at top level and have already generated 2.
|
||||
levels[maxBits].needed = 2*n - 4
|
||||
|
||||
level := uint32(maxBits)
|
||||
for level < 16 {
|
||||
l := &levels[level]
|
||||
if l.nextPairFreq == math.MaxInt32 && l.nextCharFreq == math.MaxInt32 {
|
||||
// We've run out of both leafs and pairs.
|
||||
// End all calculations for this level.
|
||||
// To make sure we never come back to this level or any lower level,
|
||||
// set nextPairFreq impossibly large.
|
||||
l.needed = 0
|
||||
levels[level+1].nextPairFreq = math.MaxInt32
|
||||
level++
|
||||
continue
|
||||
}
|
||||
|
||||
prevFreq := l.lastFreq
|
||||
if l.nextCharFreq < l.nextPairFreq {
|
||||
// The next item on this row is a leaf node.
|
||||
n := leafCounts[level][level] + 1
|
||||
l.lastFreq = l.nextCharFreq
|
||||
// Lower leafCounts are the same of the previous node.
|
||||
leafCounts[level][level] = n
|
||||
e := list[n]
|
||||
if e.literal < math.MaxUint16 {
|
||||
l.nextCharFreq = int32(e.freq)
|
||||
} else {
|
||||
l.nextCharFreq = math.MaxInt32
|
||||
}
|
||||
} else {
|
||||
// The next item on this row is a pair from the previous row.
|
||||
// nextPairFreq isn't valid until we generate two
|
||||
// more values in the level below
|
||||
l.lastFreq = l.nextPairFreq
|
||||
// Take leaf counts from the lower level, except counts[level] remains the same.
|
||||
if true {
|
||||
save := leafCounts[level][level]
|
||||
leafCounts[level] = leafCounts[level-1]
|
||||
leafCounts[level][level] = save
|
||||
} else {
|
||||
copy(leafCounts[level][:level], leafCounts[level-1][:level])
|
||||
}
|
||||
levels[l.level-1].needed = 2
|
||||
}
|
||||
|
||||
if l.needed--; l.needed == 0 {
|
||||
// We've done everything we need to do for this level.
|
||||
// Continue calculating one level up. Fill in nextPairFreq
|
||||
// of that level with the sum of the two nodes we've just calculated on
|
||||
// this level.
|
||||
if l.level == maxBits {
|
||||
// All done!
|
||||
break
|
||||
}
|
||||
levels[l.level+1].nextPairFreq = prevFreq + l.lastFreq
|
||||
level++
|
||||
} else {
|
||||
// If we stole from below, move down temporarily to replenish it.
|
||||
for levels[level-1].needed > 0 {
|
||||
level--
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// Somethings is wrong if at the end, the top level is null or hasn't used
|
||||
// all of the leaves.
|
||||
if leafCounts[maxBits][maxBits] != n {
|
||||
panic("leafCounts[maxBits][maxBits] != n")
|
||||
}
|
||||
|
||||
bitCount := h.bitCount[:maxBits+1]
|
||||
bits := 1
|
||||
counts := &leafCounts[maxBits]
|
||||
for level := maxBits; level > 0; level-- {
|
||||
// chain.leafCount gives the number of literals requiring at least "bits"
|
||||
// bits to encode.
|
||||
bitCount[bits] = counts[level] - counts[level-1]
|
||||
bits++
|
||||
}
|
||||
return bitCount
|
||||
}
|
||||
|
||||
// Look at the leaves and assign them a bit count and an encoding as specified
|
||||
// in RFC 1951 3.2.2
|
||||
func (h *huffmanEncoder) assignEncodingAndSize(bitCount []int32, list []literalNode) {
|
||||
code := uint16(0)
|
||||
for n, bits := range bitCount {
|
||||
code <<= 1
|
||||
if n == 0 || bits == 0 {
|
||||
continue
|
||||
}
|
||||
// The literals list[len(list)-bits] .. list[len(list)-bits]
|
||||
// are encoded using "bits" bits, and get the values
|
||||
// code, code + 1, .... The code values are
|
||||
// assigned in literal order (not frequency order).
|
||||
chunk := list[len(list)-int(bits):]
|
||||
|
||||
sortByLiteral(chunk)
|
||||
for _, node := range chunk {
|
||||
h.codes[node.literal] = newhcode(reverseBits(code, uint8(n)), uint8(n))
|
||||
code++
|
||||
}
|
||||
list = list[0 : len(list)-int(bits)]
|
||||
}
|
||||
}
|
||||
|
||||
// Update this Huffman Code object to be the minimum code for the specified frequency count.
|
||||
//
|
||||
// freq An array of frequencies, in which frequency[i] gives the frequency of literal i.
|
||||
// maxBits The maximum number of bits to use for any literal.
|
||||
func (h *huffmanEncoder) generate(freq []uint16, maxBits int32) {
|
||||
list := h.freqcache[:len(freq)+1]
|
||||
codes := h.codes[:len(freq)]
|
||||
// Number of non-zero literals
|
||||
count := 0
|
||||
// Set list to be the set of all non-zero literals and their frequencies
|
||||
for i, f := range freq {
|
||||
if f != 0 {
|
||||
list[count] = literalNode{uint16(i), f}
|
||||
count++
|
||||
} else {
|
||||
codes[i] = 0
|
||||
}
|
||||
}
|
||||
list[count] = literalNode{}
|
||||
|
||||
list = list[:count]
|
||||
if count <= 2 {
|
||||
// Handle the small cases here, because they are awkward for the general case code. With
|
||||
// two or fewer literals, everything has bit length 1.
|
||||
for i, node := range list {
|
||||
// "list" is in order of increasing literal value.
|
||||
h.codes[node.literal].set(uint16(i), 1)
|
||||
}
|
||||
return
|
||||
}
|
||||
sortByFreq(list)
|
||||
|
||||
// Get the number of literals for each bit count
|
||||
bitCount := h.bitCounts(list, maxBits)
|
||||
// And do the assignment
|
||||
h.assignEncodingAndSize(bitCount, list)
|
||||
}
|
||||
|
||||
// atLeastOne clamps the result between 1 and 15.
|
||||
func atLeastOne(v float32) float32 {
|
||||
if v < 1 {
|
||||
return 1
|
||||
}
|
||||
if v > 15 {
|
||||
return 15
|
||||
}
|
||||
return v
|
||||
}
|
||||
|
||||
func histogram(b []byte, h []uint16) {
|
||||
if true && len(b) >= 8<<10 {
|
||||
// Split for bigger inputs
|
||||
histogramSplit(b, h)
|
||||
} else {
|
||||
h = h[:256]
|
||||
for _, t := range b {
|
||||
h[t]++
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
func histogramSplit(b []byte, h []uint16) {
|
||||
// Tested, and slightly faster than 2-way.
|
||||
// Writing to separate arrays and combining is also slightly slower.
|
||||
h = h[:256]
|
||||
for len(b)&3 != 0 {
|
||||
h[b[0]]++
|
||||
b = b[1:]
|
||||
}
|
||||
n := len(b) / 4
|
||||
x, y, z, w := b[:n], b[n:], b[n+n:], b[n+n+n:]
|
||||
y, z, w = y[:len(x)], z[:len(x)], w[:len(x)]
|
||||
for i, t := range x {
|
||||
v0 := &h[t]
|
||||
v1 := &h[y[i]]
|
||||
v2 := &h[z[i]]
|
||||
v3 := &h[w[i]]
|
||||
*v0++
|
||||
*v1++
|
||||
*v2++
|
||||
*v3++
|
||||
}
|
||||
}
|
||||
Generated
Vendored
-159
@@ -1,159 +0,0 @@
|
||||
// Copyright 2009 The Go Authors. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package flate
|
||||
|
||||
// Sort sorts data.
|
||||
// It makes one call to data.Len to determine n, and O(n*log(n)) calls to
|
||||
// data.Less and data.Swap. The sort is not guaranteed to be stable.
|
||||
func sortByFreq(data []literalNode) {
|
||||
n := len(data)
|
||||
quickSortByFreq(data, 0, n, maxDepth(n))
|
||||
}
|
||||
|
||||
func quickSortByFreq(data []literalNode, a, b, maxDepth int) {
|
||||
for b-a > 12 { // Use ShellSort for slices <= 12 elements
|
||||
if maxDepth == 0 {
|
||||
heapSort(data, a, b)
|
||||
return
|
||||
}
|
||||
maxDepth--
|
||||
mlo, mhi := doPivotByFreq(data, a, b)
|
||||
// Avoiding recursion on the larger subproblem guarantees
|
||||
// a stack depth of at most lg(b-a).
|
||||
if mlo-a < b-mhi {
|
||||
quickSortByFreq(data, a, mlo, maxDepth)
|
||||
a = mhi // i.e., quickSortByFreq(data, mhi, b)
|
||||
} else {
|
||||
quickSortByFreq(data, mhi, b, maxDepth)
|
||||
b = mlo // i.e., quickSortByFreq(data, a, mlo)
|
||||
}
|
||||
}
|
||||
if b-a > 1 {
|
||||
// Do ShellSort pass with gap 6
|
||||
// It could be written in this simplified form cause b-a <= 12
|
||||
for i := a + 6; i < b; i++ {
|
||||
if data[i].freq == data[i-6].freq && data[i].literal < data[i-6].literal || data[i].freq < data[i-6].freq {
|
||||
data[i], data[i-6] = data[i-6], data[i]
|
||||
}
|
||||
}
|
||||
insertionSortByFreq(data, a, b)
|
||||
}
|
||||
}
|
||||
|
||||
func doPivotByFreq(data []literalNode, lo, hi int) (midlo, midhi int) {
|
||||
m := int(uint(lo+hi) >> 1) // Written like this to avoid integer overflow.
|
||||
if hi-lo > 40 {
|
||||
// Tukey's ``Ninther,'' median of three medians of three.
|
||||
s := (hi - lo) / 8
|
||||
medianOfThreeSortByFreq(data, lo, lo+s, lo+2*s)
|
||||
medianOfThreeSortByFreq(data, m, m-s, m+s)
|
||||
medianOfThreeSortByFreq(data, hi-1, hi-1-s, hi-1-2*s)
|
||||
}
|
||||
medianOfThreeSortByFreq(data, lo, m, hi-1)
|
||||
|
||||
// Invariants are:
|
||||
// data[lo] = pivot (set up by ChoosePivot)
|
||||
// data[lo < i < a] < pivot
|
||||
// data[a <= i < b] <= pivot
|
||||
// data[b <= i < c] unexamined
|
||||
// data[c <= i < hi-1] > pivot
|
||||
// data[hi-1] >= pivot
|
||||
pivot := lo
|
||||
a, c := lo+1, hi-1
|
||||
|
||||
for ; a < c && (data[a].freq == data[pivot].freq && data[a].literal < data[pivot].literal || data[a].freq < data[pivot].freq); a++ {
|
||||
}
|
||||
b := a
|
||||
for {
|
||||
for ; b < c && (data[pivot].freq == data[b].freq && data[pivot].literal > data[b].literal || data[pivot].freq > data[b].freq); b++ { // data[b] <= pivot
|
||||
}
|
||||
for ; b < c && (data[pivot].freq == data[c-1].freq && data[pivot].literal < data[c-1].literal || data[pivot].freq < data[c-1].freq); c-- { // data[c-1] > pivot
|
||||
}
|
||||
if b >= c {
|
||||
break
|
||||
}
|
||||
// data[b] > pivot; data[c-1] <= pivot
|
||||
data[b], data[c-1] = data[c-1], data[b]
|
||||
b++
|
||||
c--
|
||||
}
|
||||
// If hi-c<3 then there are duplicates (by property of median of nine).
|
||||
// Let's be a bit more conservative, and set border to 5.
|
||||
protect := hi-c < 5
|
||||
if !protect && hi-c < (hi-lo)/4 {
|
||||
// Lets test some points for equality to pivot
|
||||
dups := 0
|
||||
if data[pivot].freq == data[hi-1].freq && data[pivot].literal > data[hi-1].literal || data[pivot].freq > data[hi-1].freq { // data[hi-1] = pivot
|
||||
data[c], data[hi-1] = data[hi-1], data[c]
|
||||
c++
|
||||
dups++
|
||||
}
|
||||
if data[b-1].freq == data[pivot].freq && data[b-1].literal > data[pivot].literal || data[b-1].freq > data[pivot].freq { // data[b-1] = pivot
|
||||
b--
|
||||
dups++
|
||||
}
|
||||
// m-lo = (hi-lo)/2 > 6
|
||||
// b-lo > (hi-lo)*3/4-1 > 8
|
||||
// ==> m < b ==> data[m] <= pivot
|
||||
if data[m].freq == data[pivot].freq && data[m].literal > data[pivot].literal || data[m].freq > data[pivot].freq { // data[m] = pivot
|
||||
data[m], data[b-1] = data[b-1], data[m]
|
||||
b--
|
||||
dups++
|
||||
}
|
||||
// if at least 2 points are equal to pivot, assume skewed distribution
|
||||
protect = dups > 1
|
||||
}
|
||||
if protect {
|
||||
// Protect against a lot of duplicates
|
||||
// Add invariant:
|
||||
// data[a <= i < b] unexamined
|
||||
// data[b <= i < c] = pivot
|
||||
for {
|
||||
for ; a < b && (data[b-1].freq == data[pivot].freq && data[b-1].literal > data[pivot].literal || data[b-1].freq > data[pivot].freq); b-- { // data[b] == pivot
|
||||
}
|
||||
for ; a < b && (data[a].freq == data[pivot].freq && data[a].literal < data[pivot].literal || data[a].freq < data[pivot].freq); a++ { // data[a] < pivot
|
||||
}
|
||||
if a >= b {
|
||||
break
|
||||
}
|
||||
// data[a] == pivot; data[b-1] < pivot
|
||||
data[a], data[b-1] = data[b-1], data[a]
|
||||
a++
|
||||
b--
|
||||
}
|
||||
}
|
||||
// Swap pivot into middle
|
||||
data[pivot], data[b-1] = data[b-1], data[pivot]
|
||||
return b - 1, c
|
||||
}
|
||||
|
||||
// Insertion sort
|
||||
func insertionSortByFreq(data []literalNode, a, b int) {
|
||||
for i := a + 1; i < b; i++ {
|
||||
for j := i; j > a && (data[j].freq == data[j-1].freq && data[j].literal < data[j-1].literal || data[j].freq < data[j-1].freq); j-- {
|
||||
data[j], data[j-1] = data[j-1], data[j]
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// quickSortByFreq, loosely following Bentley and McIlroy,
|
||||
// ``Engineering a Sort Function,'' SP&E November 1993.
|
||||
|
||||
// medianOfThreeSortByFreq moves the median of the three values data[m0], data[m1], data[m2] into data[m1].
|
||||
func medianOfThreeSortByFreq(data []literalNode, m1, m0, m2 int) {
|
||||
// sort 3 elements
|
||||
if data[m1].freq == data[m0].freq && data[m1].literal < data[m0].literal || data[m1].freq < data[m0].freq {
|
||||
data[m1], data[m0] = data[m0], data[m1]
|
||||
}
|
||||
// data[m0] <= data[m1]
|
||||
if data[m2].freq == data[m1].freq && data[m2].literal < data[m1].literal || data[m2].freq < data[m1].freq {
|
||||
data[m2], data[m1] = data[m1], data[m2]
|
||||
// data[m0] <= data[m2] && data[m1] < data[m2]
|
||||
if data[m1].freq == data[m0].freq && data[m1].literal < data[m0].literal || data[m1].freq < data[m0].freq {
|
||||
data[m1], data[m0] = data[m0], data[m1]
|
||||
}
|
||||
}
|
||||
// now data[m0] <= data[m1] <= data[m2]
|
||||
}
|
||||
Generated
Vendored
-201
@@ -1,201 +0,0 @@
|
||||
// Copyright 2009 The Go Authors. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package flate
|
||||
|
||||
// Sort sorts data.
|
||||
// It makes one call to data.Len to determine n, and O(n*log(n)) calls to
|
||||
// data.Less and data.Swap. The sort is not guaranteed to be stable.
|
||||
func sortByLiteral(data []literalNode) {
|
||||
n := len(data)
|
||||
quickSort(data, 0, n, maxDepth(n))
|
||||
}
|
||||
|
||||
func quickSort(data []literalNode, a, b, maxDepth int) {
|
||||
for b-a > 12 { // Use ShellSort for slices <= 12 elements
|
||||
if maxDepth == 0 {
|
||||
heapSort(data, a, b)
|
||||
return
|
||||
}
|
||||
maxDepth--
|
||||
mlo, mhi := doPivot(data, a, b)
|
||||
// Avoiding recursion on the larger subproblem guarantees
|
||||
// a stack depth of at most lg(b-a).
|
||||
if mlo-a < b-mhi {
|
||||
quickSort(data, a, mlo, maxDepth)
|
||||
a = mhi // i.e., quickSort(data, mhi, b)
|
||||
} else {
|
||||
quickSort(data, mhi, b, maxDepth)
|
||||
b = mlo // i.e., quickSort(data, a, mlo)
|
||||
}
|
||||
}
|
||||
if b-a > 1 {
|
||||
// Do ShellSort pass with gap 6
|
||||
// It could be written in this simplified form cause b-a <= 12
|
||||
for i := a + 6; i < b; i++ {
|
||||
if data[i].literal < data[i-6].literal {
|
||||
data[i], data[i-6] = data[i-6], data[i]
|
||||
}
|
||||
}
|
||||
insertionSort(data, a, b)
|
||||
}
|
||||
}
|
||||
func heapSort(data []literalNode, a, b int) {
|
||||
first := a
|
||||
lo := 0
|
||||
hi := b - a
|
||||
|
||||
// Build heap with greatest element at top.
|
||||
for i := (hi - 1) / 2; i >= 0; i-- {
|
||||
siftDown(data, i, hi, first)
|
||||
}
|
||||
|
||||
// Pop elements, largest first, into end of data.
|
||||
for i := hi - 1; i >= 0; i-- {
|
||||
data[first], data[first+i] = data[first+i], data[first]
|
||||
siftDown(data, lo, i, first)
|
||||
}
|
||||
}
|
||||
|
||||
// siftDown implements the heap property on data[lo, hi).
|
||||
// first is an offset into the array where the root of the heap lies.
|
||||
func siftDown(data []literalNode, lo, hi, first int) {
|
||||
root := lo
|
||||
for {
|
||||
child := 2*root + 1
|
||||
if child >= hi {
|
||||
break
|
||||
}
|
||||
if child+1 < hi && data[first+child].literal < data[first+child+1].literal {
|
||||
child++
|
||||
}
|
||||
if data[first+root].literal > data[first+child].literal {
|
||||
return
|
||||
}
|
||||
data[first+root], data[first+child] = data[first+child], data[first+root]
|
||||
root = child
|
||||
}
|
||||
}
|
||||
func doPivot(data []literalNode, lo, hi int) (midlo, midhi int) {
|
||||
m := int(uint(lo+hi) >> 1) // Written like this to avoid integer overflow.
|
||||
if hi-lo > 40 {
|
||||
// Tukey's ``Ninther,'' median of three medians of three.
|
||||
s := (hi - lo) / 8
|
||||
medianOfThree(data, lo, lo+s, lo+2*s)
|
||||
medianOfThree(data, m, m-s, m+s)
|
||||
medianOfThree(data, hi-1, hi-1-s, hi-1-2*s)
|
||||
}
|
||||
medianOfThree(data, lo, m, hi-1)
|
||||
|
||||
// Invariants are:
|
||||
// data[lo] = pivot (set up by ChoosePivot)
|
||||
// data[lo < i < a] < pivot
|
||||
// data[a <= i < b] <= pivot
|
||||
// data[b <= i < c] unexamined
|
||||
// data[c <= i < hi-1] > pivot
|
||||
// data[hi-1] >= pivot
|
||||
pivot := lo
|
||||
a, c := lo+1, hi-1
|
||||
|
||||
for ; a < c && data[a].literal < data[pivot].literal; a++ {
|
||||
}
|
||||
b := a
|
||||
for {
|
||||
for ; b < c && data[pivot].literal > data[b].literal; b++ { // data[b] <= pivot
|
||||
}
|
||||
for ; b < c && data[pivot].literal < data[c-1].literal; c-- { // data[c-1] > pivot
|
||||
}
|
||||
if b >= c {
|
||||
break
|
||||
}
|
||||
// data[b] > pivot; data[c-1] <= pivot
|
||||
data[b], data[c-1] = data[c-1], data[b]
|
||||
b++
|
||||
c--
|
||||
}
|
||||
// If hi-c<3 then there are duplicates (by property of median of nine).
|
||||
// Let's be a bit more conservative, and set border to 5.
|
||||
protect := hi-c < 5
|
||||
if !protect && hi-c < (hi-lo)/4 {
|
||||
// Lets test some points for equality to pivot
|
||||
dups := 0
|
||||
if data[pivot].literal > data[hi-1].literal { // data[hi-1] = pivot
|
||||
data[c], data[hi-1] = data[hi-1], data[c]
|
||||
c++
|
||||
dups++
|
||||
}
|
||||
if data[b-1].literal > data[pivot].literal { // data[b-1] = pivot
|
||||
b--
|
||||
dups++
|
||||
}
|
||||
// m-lo = (hi-lo)/2 > 6
|
||||
// b-lo > (hi-lo)*3/4-1 > 8
|
||||
// ==> m < b ==> data[m] <= pivot
|
||||
if data[m].literal > data[pivot].literal { // data[m] = pivot
|
||||
data[m], data[b-1] = data[b-1], data[m]
|
||||
b--
|
||||
dups++
|
||||
}
|
||||
// if at least 2 points are equal to pivot, assume skewed distribution
|
||||
protect = dups > 1
|
||||
}
|
||||
if protect {
|
||||
// Protect against a lot of duplicates
|
||||
// Add invariant:
|
||||
// data[a <= i < b] unexamined
|
||||
// data[b <= i < c] = pivot
|
||||
for {
|
||||
for ; a < b && data[b-1].literal > data[pivot].literal; b-- { // data[b] == pivot
|
||||
}
|
||||
for ; a < b && data[a].literal < data[pivot].literal; a++ { // data[a] < pivot
|
||||
}
|
||||
if a >= b {
|
||||
break
|
||||
}
|
||||
// data[a] == pivot; data[b-1] < pivot
|
||||
data[a], data[b-1] = data[b-1], data[a]
|
||||
a++
|
||||
b--
|
||||
}
|
||||
}
|
||||
// Swap pivot into middle
|
||||
data[pivot], data[b-1] = data[b-1], data[pivot]
|
||||
return b - 1, c
|
||||
}
|
||||
|
||||
// Insertion sort
|
||||
func insertionSort(data []literalNode, a, b int) {
|
||||
for i := a + 1; i < b; i++ {
|
||||
for j := i; j > a && data[j].literal < data[j-1].literal; j-- {
|
||||
data[j], data[j-1] = data[j-1], data[j]
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// maxDepth returns a threshold at which quicksort should switch
|
||||
// to heapsort. It returns 2*ceil(lg(n+1)).
|
||||
func maxDepth(n int) int {
|
||||
var depth int
|
||||
for i := n; i > 0; i >>= 1 {
|
||||
depth++
|
||||
}
|
||||
return depth * 2
|
||||
}
|
||||
|
||||
// medianOfThree moves the median of the three values data[m0], data[m1], data[m2] into data[m1].
|
||||
func medianOfThree(data []literalNode, m1, m0, m2 int) {
|
||||
// sort 3 elements
|
||||
if data[m1].literal < data[m0].literal {
|
||||
data[m1], data[m0] = data[m0], data[m1]
|
||||
}
|
||||
// data[m0] <= data[m1]
|
||||
if data[m2].literal < data[m1].literal {
|
||||
data[m2], data[m1] = data[m1], data[m2]
|
||||
// data[m0] <= data[m2] && data[m1] < data[m2]
|
||||
if data[m1].literal < data[m0].literal {
|
||||
data[m1], data[m0] = data[m0], data[m1]
|
||||
}
|
||||
}
|
||||
// now data[m0] <= data[m1] <= data[m2]
|
||||
}
|
||||
Generated
Vendored
-959
@@ -1,959 +0,0 @@
|
||||
// Copyright 2009 The Go Authors. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
// Package flate implements the DEFLATE compressed data format, described in
|
||||
// RFC 1951. The gzip and zlib packages implement access to DEFLATE-based file
|
||||
// formats.
|
||||
package flate
|
||||
|
||||
import (
|
||||
"bufio"
|
||||
"compress/flate"
|
||||
"fmt"
|
||||
"io"
|
||||
"math/bits"
|
||||
"sync"
|
||||
|
||||
"github.com/klauspost/compress/internal/regmask"
|
||||
)
|
||||
|
||||
const (
|
||||
maxCodeLen = 16 // max length of Huffman code
|
||||
maxCodeLenMask = 15 // mask for max length of Huffman code
|
||||
// The next three numbers come from the RFC section 3.2.7, with the
|
||||
// additional proviso in section 3.2.5 which implies that distance codes
|
||||
// 30 and 31 should never occur in compressed data.
|
||||
maxNumLit = 286
|
||||
maxNumDist = 30
|
||||
numCodes = 19 // number of codes in Huffman meta-code
|
||||
|
||||
debugDecode = false
|
||||
)
|
||||
|
||||
// Value of length - 3 and extra bits.
|
||||
type lengthExtra struct {
|
||||
length, extra uint8
|
||||
}
|
||||
|
||||
var decCodeToLen = [32]lengthExtra{{length: 0x0, extra: 0x0}, {length: 0x1, extra: 0x0}, {length: 0x2, extra: 0x0}, {length: 0x3, extra: 0x0}, {length: 0x4, extra: 0x0}, {length: 0x5, extra: 0x0}, {length: 0x6, extra: 0x0}, {length: 0x7, extra: 0x0}, {length: 0x8, extra: 0x1}, {length: 0xa, extra: 0x1}, {length: 0xc, extra: 0x1}, {length: 0xe, extra: 0x1}, {length: 0x10, extra: 0x2}, {length: 0x14, extra: 0x2}, {length: 0x18, extra: 0x2}, {length: 0x1c, extra: 0x2}, {length: 0x20, extra: 0x3}, {length: 0x28, extra: 0x3}, {length: 0x30, extra: 0x3}, {length: 0x38, extra: 0x3}, {length: 0x40, extra: 0x4}, {length: 0x50, extra: 0x4}, {length: 0x60, extra: 0x4}, {length: 0x70, extra: 0x4}, {length: 0x80, extra: 0x5}, {length: 0xa0, extra: 0x5}, {length: 0xc0, extra: 0x5}, {length: 0xe0, extra: 0x5}, {length: 0xff, extra: 0x0}, {length: 0x0, extra: 0x0}, {length: 0x0, extra: 0x0}, {length: 0x0, extra: 0x0}}
|
||||
|
||||
var bitMask32 = [32]uint32{
|
||||
0, 1, 3, 7, 0xF, 0x1F, 0x3F, 0x7F, 0xFF,
|
||||
0x1FF, 0x3FF, 0x7FF, 0xFFF, 0x1FFF, 0x3FFF, 0x7FFF, 0xFFFF,
|
||||
0x1ffff, 0x3ffff, 0x7FFFF, 0xfFFFF, 0x1fFFFF, 0x3fFFFF, 0x7fFFFF, 0xffFFFF,
|
||||
0x1ffFFFF, 0x3ffFFFF, 0x7ffFFFF, 0xfffFFFF, 0x1fffFFFF, 0x3fffFFFF, 0x7fffFFFF,
|
||||
} // up to 32 bits
|
||||
|
||||
// Initialize the fixedHuffmanDecoder only once upon first use.
|
||||
var fixedOnce sync.Once
|
||||
var fixedHuffmanDecoder huffmanDecoder
|
||||
|
||||
// A CorruptInputError reports the presence of corrupt input at a given offset.
|
||||
type CorruptInputError = flate.CorruptInputError
|
||||
|
||||
// An InternalError reports an error in the flate code itself.
|
||||
type InternalError string
|
||||
|
||||
func (e InternalError) Error() string { return "flate: internal error: " + string(e) }
|
||||
|
||||
// A ReadError reports an error encountered while reading input.
|
||||
//
|
||||
// Deprecated: No longer returned.
|
||||
type ReadError = flate.ReadError
|
||||
|
||||
// A WriteError reports an error encountered while writing output.
|
||||
//
|
||||
// Deprecated: No longer returned.
|
||||
type WriteError = flate.WriteError
|
||||
|
||||
// Resetter resets a ReadCloser returned by NewReader or NewReaderDict to
|
||||
// to switch to a new underlying Reader. This permits reusing a ReadCloser
|
||||
// instead of allocating a new one.
|
||||
type Resetter interface {
|
||||
// Reset discards any buffered data and resets the Resetter as if it was
|
||||
// newly initialized with the given reader.
|
||||
Reset(r io.Reader, dict []byte) error
|
||||
}
|
||||
|
||||
// The data structure for decoding Huffman tables is based on that of
|
||||
// zlib. There is a lookup table of a fixed bit width (huffmanChunkBits),
|
||||
// For codes smaller than the table width, there are multiple entries
|
||||
// (each combination of trailing bits has the same value). For codes
|
||||
// larger than the table width, the table contains a link to an overflow
|
||||
// table. The width of each entry in the link table is the maximum code
|
||||
// size minus the chunk width.
|
||||
//
|
||||
// Note that you can do a lookup in the table even without all bits
|
||||
// filled. Since the extra bits are zero, and the DEFLATE Huffman codes
|
||||
// have the property that shorter codes come before longer ones, the
|
||||
// bit length estimate in the result is a lower bound on the actual
|
||||
// number of bits.
|
||||
//
|
||||
// See the following:
|
||||
// http://www.gzip.org/algorithm.txt
|
||||
|
||||
// chunk & 15 is number of bits
|
||||
// chunk >> 4 is value, including table link
|
||||
|
||||
const (
|
||||
huffmanChunkBits = 9
|
||||
huffmanNumChunks = 1 << huffmanChunkBits
|
||||
huffmanCountMask = 15
|
||||
huffmanValueShift = 4
|
||||
)
|
||||
|
||||
type huffmanDecoder struct {
|
||||
maxRead int // the maximum number of bits we can read and not overread
|
||||
chunks *[huffmanNumChunks]uint16 // chunks as described above
|
||||
links [][]uint16 // overflow links
|
||||
linkMask uint32 // mask the width of the link table
|
||||
}
|
||||
|
||||
// Initialize Huffman decoding tables from array of code lengths.
|
||||
// Following this function, h is guaranteed to be initialized into a complete
|
||||
// tree (i.e., neither over-subscribed nor under-subscribed). The exception is a
|
||||
// degenerate case where the tree has only a single symbol with length 1. Empty
|
||||
// trees are permitted.
|
||||
func (h *huffmanDecoder) init(lengths []int) bool {
|
||||
// Sanity enables additional runtime tests during Huffman
|
||||
// table construction. It's intended to be used during
|
||||
// development to supplement the currently ad-hoc unit tests.
|
||||
const sanity = false
|
||||
|
||||
if h.chunks == nil {
|
||||
h.chunks = new([huffmanNumChunks]uint16)
|
||||
}
|
||||
|
||||
if h.maxRead != 0 {
|
||||
*h = huffmanDecoder{chunks: h.chunks, links: h.links}
|
||||
}
|
||||
|
||||
// Count number of codes of each length,
|
||||
// compute maxRead and max length.
|
||||
var count [maxCodeLen]int
|
||||
var min, max int
|
||||
for _, n := range lengths {
|
||||
if n == 0 {
|
||||
continue
|
||||
}
|
||||
if min == 0 || n < min {
|
||||
min = n
|
||||
}
|
||||
if n > max {
|
||||
max = n
|
||||
}
|
||||
count[n&maxCodeLenMask]++
|
||||
}
|
||||
|
||||
// Empty tree. The decompressor.huffSym function will fail later if the tree
|
||||
// is used. Technically, an empty tree is only valid for the HDIST tree and
|
||||
// not the HCLEN and HLIT tree. However, a stream with an empty HCLEN tree
|
||||
// is guaranteed to fail since it will attempt to use the tree to decode the
|
||||
// codes for the HLIT and HDIST trees. Similarly, an empty HLIT tree is
|
||||
// guaranteed to fail later since the compressed data section must be
|
||||
// composed of at least one symbol (the end-of-block marker).
|
||||
if max == 0 {
|
||||
return true
|
||||
}
|
||||
|
||||
code := 0
|
||||
var nextcode [maxCodeLen]int
|
||||
for i := min; i <= max; i++ {
|
||||
code <<= 1
|
||||
nextcode[i&maxCodeLenMask] = code
|
||||
code += count[i&maxCodeLenMask]
|
||||
}
|
||||
|
||||
// Check that the coding is complete (i.e., that we've
|
||||
// assigned all 2-to-the-max possible bit sequences).
|
||||
// Exception: To be compatible with zlib, we also need to
|
||||
// accept degenerate single-code codings. See also
|
||||
// TestDegenerateHuffmanCoding.
|
||||
if code != 1<<uint(max) && !(code == 1 && max == 1) {
|
||||
if debugDecode {
|
||||
fmt.Println("coding failed, code, max:", code, max, code == 1<<uint(max), code == 1 && max == 1, "(one should be true)")
|
||||
}
|
||||
return false
|
||||
}
|
||||
|
||||
h.maxRead = min
|
||||
|
||||
chunks := h.chunks[:]
|
||||
for i := range chunks {
|
||||
chunks[i] = 0
|
||||
}
|
||||
|
||||
if max > huffmanChunkBits {
|
||||
numLinks := 1 << (uint(max) - huffmanChunkBits)
|
||||
h.linkMask = uint32(numLinks - 1)
|
||||
|
||||
// create link tables
|
||||
link := nextcode[huffmanChunkBits+1] >> 1
|
||||
if cap(h.links) < huffmanNumChunks-link {
|
||||
h.links = make([][]uint16, huffmanNumChunks-link)
|
||||
} else {
|
||||
h.links = h.links[:huffmanNumChunks-link]
|
||||
}
|
||||
for j := uint(link); j < huffmanNumChunks; j++ {
|
||||
reverse := int(bits.Reverse16(uint16(j)))
|
||||
reverse >>= uint(16 - huffmanChunkBits)
|
||||
off := j - uint(link)
|
||||
if sanity && h.chunks[reverse] != 0 {
|
||||
panic("impossible: overwriting existing chunk")
|
||||
}
|
||||
h.chunks[reverse] = uint16(off<<huffmanValueShift | (huffmanChunkBits + 1))
|
||||
if cap(h.links[off]) < numLinks {
|
||||
h.links[off] = make([]uint16, numLinks)
|
||||
} else {
|
||||
h.links[off] = h.links[off][:numLinks]
|
||||
}
|
||||
}
|
||||
} else {
|
||||
h.links = h.links[:0]
|
||||
}
|
||||
|
||||
for i, n := range lengths {
|
||||
if n == 0 {
|
||||
continue
|
||||
}
|
||||
code := nextcode[n]
|
||||
nextcode[n]++
|
||||
chunk := uint16(i<<huffmanValueShift | n)
|
||||
reverse := int(bits.Reverse16(uint16(code)))
|
||||
reverse >>= uint(16 - n)
|
||||
if n <= huffmanChunkBits {
|
||||
for off := reverse; off < len(h.chunks); off += 1 << uint(n) {
|
||||
// We should never need to overwrite
|
||||
// an existing chunk. Also, 0 is
|
||||
// never a valid chunk, because the
|
||||
// lower 4 "count" bits should be
|
||||
// between 1 and 15.
|
||||
if sanity && h.chunks[off] != 0 {
|
||||
panic("impossible: overwriting existing chunk")
|
||||
}
|
||||
h.chunks[off] = chunk
|
||||
}
|
||||
} else {
|
||||
j := reverse & (huffmanNumChunks - 1)
|
||||
if sanity && h.chunks[j]&huffmanCountMask != huffmanChunkBits+1 {
|
||||
// Longer codes should have been
|
||||
// associated with a link table above.
|
||||
panic("impossible: not an indirect chunk")
|
||||
}
|
||||
value := h.chunks[j] >> huffmanValueShift
|
||||
linktab := h.links[value]
|
||||
reverse >>= huffmanChunkBits
|
||||
for off := reverse; off < len(linktab); off += 1 << uint(n-huffmanChunkBits) {
|
||||
if sanity && linktab[off] != 0 {
|
||||
panic("impossible: overwriting existing chunk")
|
||||
}
|
||||
linktab[off] = chunk
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
if sanity {
|
||||
// Above we've sanity checked that we never overwrote
|
||||
// an existing entry. Here we additionally check that
|
||||
// we filled the tables completely.
|
||||
for i, chunk := range h.chunks {
|
||||
if chunk == 0 {
|
||||
// As an exception, in the degenerate
|
||||
// single-code case, we allow odd
|
||||
// chunks to be missing.
|
||||
if code == 1 && i%2 == 1 {
|
||||
continue
|
||||
}
|
||||
panic("impossible: missing chunk")
|
||||
}
|
||||
}
|
||||
for _, linktab := range h.links {
|
||||
for _, chunk := range linktab {
|
||||
if chunk == 0 {
|
||||
panic("impossible: missing chunk")
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
return true
|
||||
}
|
||||
|
||||
// Reader is the actual read interface needed by NewReader.
|
||||
// If the passed in io.Reader does not also have ReadByte,
|
||||
// the NewReader will introduce its own buffering.
|
||||
type Reader interface {
|
||||
io.Reader
|
||||
io.ByteReader
|
||||
}
|
||||
|
||||
type step uint8
|
||||
|
||||
const (
|
||||
copyData step = iota + 1
|
||||
nextBlock
|
||||
huffmanBytesBuffer
|
||||
huffmanBytesReader
|
||||
huffmanBufioReader
|
||||
huffmanStringsReader
|
||||
huffmanGenericReader
|
||||
)
|
||||
|
||||
// flushMode tells decompressor when to return data
|
||||
type flushMode uint8
|
||||
|
||||
const (
|
||||
syncFlush flushMode = iota // return data after sync flush block
|
||||
partialFlush // return data after each block
|
||||
)
|
||||
|
||||
// Decompress state.
|
||||
type decompressor struct {
|
||||
// Input source.
|
||||
r Reader
|
||||
roffset int64
|
||||
|
||||
// Huffman decoders for literal/length, distance.
|
||||
h1, h2 huffmanDecoder
|
||||
|
||||
// Length arrays used to define Huffman codes.
|
||||
bits *[maxNumLit + maxNumDist]int
|
||||
codebits *[numCodes]int
|
||||
|
||||
// Output history, buffer.
|
||||
dict dictDecoder
|
||||
|
||||
// Next step in the decompression,
|
||||
// and decompression state.
|
||||
step step
|
||||
stepState int
|
||||
err error
|
||||
toRead []byte
|
||||
hl, hd *huffmanDecoder
|
||||
copyLen int
|
||||
copyDist int
|
||||
|
||||
// Temporary buffer (avoids repeated allocation).
|
||||
buf [4]byte
|
||||
|
||||
// Input bits, in top of b.
|
||||
b uint32
|
||||
|
||||
nb uint
|
||||
final bool
|
||||
|
||||
flushMode flushMode
|
||||
cb func(InflateCheckpoint)
|
||||
cp InflateCheckpoint
|
||||
hasCP bool // WithResumeFrom was supplied
|
||||
uncOffset int64 // baseline uncompressed offset (from a resume checkpoint)
|
||||
cpBuf []byte
|
||||
}
|
||||
|
||||
func (f *decompressor) nextBlock() {
|
||||
for f.nb < 1+2 {
|
||||
if f.err = f.moreBits(); f.err != nil {
|
||||
return
|
||||
}
|
||||
}
|
||||
f.final = f.b&1 == 1
|
||||
f.b >>= 1
|
||||
typ := f.b & 3
|
||||
f.b >>= 2
|
||||
f.nb -= 1 + 2
|
||||
switch typ {
|
||||
case 0:
|
||||
f.dataBlock()
|
||||
if debugDecode {
|
||||
fmt.Println("stored block")
|
||||
}
|
||||
case 1:
|
||||
// compressed, fixed Huffman tables
|
||||
f.hl = &fixedHuffmanDecoder
|
||||
f.hd = nil
|
||||
f.huffmanBlockDecoder()
|
||||
if debugDecode {
|
||||
fmt.Println("predefinied huffman block")
|
||||
}
|
||||
case 2:
|
||||
// compressed, dynamic Huffman tables
|
||||
if f.err = f.readHuffman(); f.err != nil {
|
||||
break
|
||||
}
|
||||
f.hl = &f.h1
|
||||
f.hd = &f.h2
|
||||
f.huffmanBlockDecoder()
|
||||
if debugDecode {
|
||||
fmt.Println("dynamic huffman block")
|
||||
}
|
||||
default:
|
||||
// 3 is reserved.
|
||||
if debugDecode {
|
||||
fmt.Println("reserved data block encountered")
|
||||
}
|
||||
f.err = CorruptInputError(f.roffset)
|
||||
}
|
||||
}
|
||||
|
||||
func (f *decompressor) Read(b []byte) (int, error) {
|
||||
for {
|
||||
if len(f.toRead) > 0 {
|
||||
n := copy(b, f.toRead)
|
||||
f.toRead = f.toRead[n:]
|
||||
if len(f.toRead) == 0 {
|
||||
return n, f.err
|
||||
}
|
||||
return n, nil
|
||||
}
|
||||
if f.err != nil {
|
||||
return 0, f.err
|
||||
}
|
||||
|
||||
f.doStep()
|
||||
|
||||
if f.err != nil && len(f.toRead) == 0 {
|
||||
f.toRead = f.dict.readFlush() // Flush what's left in case of error
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// WriteTo implements the io.WriteTo interface for io.Copy and friends.
|
||||
func (f *decompressor) WriteTo(w io.Writer) (int64, error) {
|
||||
total := int64(0)
|
||||
flushed := false
|
||||
for {
|
||||
if len(f.toRead) > 0 {
|
||||
n, err := w.Write(f.toRead)
|
||||
total += int64(n)
|
||||
if err != nil {
|
||||
f.err = err
|
||||
return total, err
|
||||
}
|
||||
if n != len(f.toRead) {
|
||||
return total, io.ErrShortWrite
|
||||
}
|
||||
f.toRead = f.toRead[:0]
|
||||
}
|
||||
if f.err != nil && flushed {
|
||||
if f.err == io.EOF {
|
||||
return total, nil
|
||||
}
|
||||
return total, f.err
|
||||
}
|
||||
if f.err == nil {
|
||||
f.doStep()
|
||||
}
|
||||
if len(f.toRead) == 0 && f.err != nil && !flushed {
|
||||
f.toRead = f.dict.readFlush() // Flush what's left in case of error
|
||||
flushed = true
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
func (f *decompressor) Close() error {
|
||||
if f.err == io.EOF {
|
||||
return nil
|
||||
}
|
||||
return f.err
|
||||
}
|
||||
|
||||
// RFC 1951 section 3.2.7.
|
||||
// Compression with dynamic Huffman codes
|
||||
|
||||
var codeOrder = [...]int{16, 17, 18, 0, 8, 7, 9, 6, 10, 5, 11, 4, 12, 3, 13, 2, 14, 1, 15}
|
||||
|
||||
func (f *decompressor) readHuffman() error {
|
||||
// HLIT[5], HDIST[5], HCLEN[4].
|
||||
for f.nb < 5+5+4 {
|
||||
if err := f.moreBits(); err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
nlit := int(f.b&0x1F) + 257
|
||||
if nlit > maxNumLit {
|
||||
if debugDecode {
|
||||
fmt.Println("nlit > maxNumLit", nlit)
|
||||
}
|
||||
return CorruptInputError(f.roffset)
|
||||
}
|
||||
f.b >>= 5
|
||||
ndist := int(f.b&0x1F) + 1
|
||||
if ndist > maxNumDist {
|
||||
if debugDecode {
|
||||
fmt.Println("ndist > maxNumDist", ndist)
|
||||
}
|
||||
return CorruptInputError(f.roffset)
|
||||
}
|
||||
f.b >>= 5
|
||||
nclen := int(f.b&0xF) + 4
|
||||
// numCodes is 19, so nclen is always valid.
|
||||
f.b >>= 4
|
||||
f.nb -= 5 + 5 + 4
|
||||
|
||||
// (HCLEN+4)*3 bits: code lengths in the magic codeOrder order.
|
||||
for i := range nclen {
|
||||
for f.nb < 3 {
|
||||
if err := f.moreBits(); err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
f.codebits[codeOrder[i]] = int(f.b & 0x7)
|
||||
f.b >>= 3
|
||||
f.nb -= 3
|
||||
}
|
||||
for i := nclen; i < len(codeOrder); i++ {
|
||||
f.codebits[codeOrder[i]] = 0
|
||||
}
|
||||
if !f.h1.init(f.codebits[0:]) {
|
||||
if debugDecode {
|
||||
fmt.Println("init codebits failed")
|
||||
}
|
||||
return CorruptInputError(f.roffset)
|
||||
}
|
||||
|
||||
// HLIT + 257 code lengths, HDIST + 1 code lengths,
|
||||
// using the code length Huffman code.
|
||||
for i, n := 0, nlit+ndist; i < n; {
|
||||
x, err := f.huffSym(&f.h1)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
if x < 16 {
|
||||
// Actual length.
|
||||
f.bits[i] = x
|
||||
i++
|
||||
continue
|
||||
}
|
||||
// Repeat previous length or zero.
|
||||
var rep int
|
||||
var nb uint
|
||||
var b int
|
||||
switch x {
|
||||
default:
|
||||
return InternalError("unexpected length code")
|
||||
case 16:
|
||||
rep = 3
|
||||
nb = 2
|
||||
if i == 0 {
|
||||
if debugDecode {
|
||||
fmt.Println("i==0")
|
||||
}
|
||||
return CorruptInputError(f.roffset)
|
||||
}
|
||||
b = f.bits[i-1]
|
||||
case 17:
|
||||
rep = 3
|
||||
nb = 3
|
||||
b = 0
|
||||
case 18:
|
||||
rep = 11
|
||||
nb = 7
|
||||
b = 0
|
||||
}
|
||||
for f.nb < nb {
|
||||
if err := f.moreBits(); err != nil {
|
||||
if debugDecode {
|
||||
fmt.Println("morebits:", err)
|
||||
}
|
||||
return err
|
||||
}
|
||||
}
|
||||
rep += int(f.b & uint32(1<<(nb®mask.Shift32ByUint)-1))
|
||||
f.b >>= nb & regmask.Shift32ByUint
|
||||
f.nb -= nb
|
||||
if i+rep > n {
|
||||
if debugDecode {
|
||||
fmt.Println("i+rep > n", i, rep, n)
|
||||
}
|
||||
return CorruptInputError(f.roffset)
|
||||
}
|
||||
for j := 0; j < rep; j++ {
|
||||
f.bits[i] = b
|
||||
i++
|
||||
}
|
||||
}
|
||||
|
||||
if !f.h1.init(f.bits[0:nlit]) || !f.h2.init(f.bits[nlit:nlit+ndist]) {
|
||||
if debugDecode {
|
||||
fmt.Println("init2 failed")
|
||||
}
|
||||
return CorruptInputError(f.roffset)
|
||||
}
|
||||
|
||||
// As an optimization, we can initialize the maxRead bits to read at a time
|
||||
// for the HLIT tree to the length of the EOB marker since we know that
|
||||
// every block must terminate with one. This preserves the property that
|
||||
// we never read any extra bytes after the end of the DEFLATE stream.
|
||||
if f.h1.maxRead < f.bits[endBlockMarker] {
|
||||
f.h1.maxRead = f.bits[endBlockMarker]
|
||||
}
|
||||
if !f.final {
|
||||
// If not the final block, the smallest block possible is
|
||||
// a predefined table, BTYPE=01, with a single EOB marker.
|
||||
// This will take up 3 + 7 bits.
|
||||
f.h1.maxRead += 10
|
||||
}
|
||||
|
||||
return nil
|
||||
}
|
||||
|
||||
// Copy a single uncompressed data block from input to output.
|
||||
func (f *decompressor) dataBlock() {
|
||||
// Uncompressed.
|
||||
// Discard current half-byte.
|
||||
left := (f.nb) & 7
|
||||
f.nb -= left
|
||||
f.b >>= left
|
||||
|
||||
offBytes := f.nb >> 3
|
||||
// Unfilled values will be overwritten.
|
||||
f.buf[0] = uint8(f.b)
|
||||
f.buf[1] = uint8(f.b >> 8)
|
||||
f.buf[2] = uint8(f.b >> 16)
|
||||
f.buf[3] = uint8(f.b >> 24)
|
||||
|
||||
f.roffset += int64(offBytes)
|
||||
f.nb, f.b = 0, 0
|
||||
|
||||
// Length then ones-complement of length.
|
||||
nr, err := io.ReadFull(f.r, f.buf[offBytes:4])
|
||||
f.roffset += int64(nr)
|
||||
if err != nil {
|
||||
f.err = noEOF(err)
|
||||
return
|
||||
}
|
||||
n := uint16(f.buf[0]) | uint16(f.buf[1])<<8
|
||||
nn := uint16(f.buf[2]) | uint16(f.buf[3])<<8
|
||||
if nn != ^n {
|
||||
if debugDecode {
|
||||
ncomp := ^n
|
||||
fmt.Println("uint16(nn) != uint16(^n)", nn, ncomp)
|
||||
}
|
||||
f.err = CorruptInputError(f.roffset)
|
||||
return
|
||||
}
|
||||
|
||||
if n == 0 {
|
||||
if f.flushMode == syncFlush {
|
||||
f.toRead = f.dict.readFlush()
|
||||
}
|
||||
|
||||
f.finishBlock()
|
||||
return
|
||||
}
|
||||
|
||||
f.copyLen = int(n)
|
||||
f.copyData()
|
||||
}
|
||||
|
||||
// copyData copies f.copyLen bytes from the underlying reader into f.hist.
|
||||
// It pauses for reads when f.hist is full.
|
||||
func (f *decompressor) copyData() {
|
||||
buf := f.dict.writeSlice()
|
||||
if len(buf) > f.copyLen {
|
||||
buf = buf[:f.copyLen]
|
||||
}
|
||||
|
||||
cnt, err := io.ReadFull(f.r, buf)
|
||||
f.roffset += int64(cnt)
|
||||
f.copyLen -= cnt
|
||||
f.dict.writeMark(cnt)
|
||||
if err != nil {
|
||||
f.err = noEOF(err)
|
||||
return
|
||||
}
|
||||
|
||||
if f.dict.availWrite() == 0 || f.copyLen > 0 {
|
||||
f.toRead = f.dict.readFlush()
|
||||
f.step = copyData
|
||||
return
|
||||
}
|
||||
f.finishBlock()
|
||||
}
|
||||
|
||||
func (f *decompressor) finishBlock() {
|
||||
if f.final {
|
||||
if f.dict.availRead() > 0 {
|
||||
f.toRead = f.dict.readFlush()
|
||||
}
|
||||
|
||||
f.err = io.EOF
|
||||
} else if f.flushMode == partialFlush && f.dict.availRead() > 0 {
|
||||
f.toRead = f.dict.readFlush()
|
||||
}
|
||||
|
||||
if f.cb != nil {
|
||||
bitPos := f.roffset*8 - int64(f.nb)
|
||||
f.cpBuf = f.dict.appendWindow(f.cpBuf[:0])
|
||||
f.cb(InflateCheckpoint{
|
||||
UncompressedOffset: f.uncOffset + f.dict.decoded(),
|
||||
CompressedOffset: bitPos / 8,
|
||||
Final: f.final,
|
||||
BitOffset: uint8(bitPos & 7),
|
||||
Window: f.cpBuf,
|
||||
})
|
||||
}
|
||||
|
||||
f.step = nextBlock
|
||||
}
|
||||
|
||||
func (f *decompressor) doStep() {
|
||||
switch f.step {
|
||||
case copyData:
|
||||
f.copyData()
|
||||
case nextBlock:
|
||||
f.nextBlock()
|
||||
case huffmanBytesBuffer:
|
||||
f.huffmanBytesBuffer()
|
||||
case huffmanBytesReader:
|
||||
f.huffmanBytesReader()
|
||||
case huffmanBufioReader:
|
||||
f.huffmanBufioReader()
|
||||
case huffmanStringsReader:
|
||||
f.huffmanStringsReader()
|
||||
case huffmanGenericReader:
|
||||
f.huffmanGenericReader()
|
||||
default:
|
||||
panic("BUG: unexpected step state")
|
||||
}
|
||||
}
|
||||
|
||||
// noEOF returns err, unless err == io.EOF, in which case it returns io.ErrUnexpectedEOF.
|
||||
func noEOF(e error) error {
|
||||
if e == io.EOF {
|
||||
return io.ErrUnexpectedEOF
|
||||
}
|
||||
return e
|
||||
}
|
||||
|
||||
func (f *decompressor) moreBits() error {
|
||||
c, err := f.r.ReadByte()
|
||||
if err != nil {
|
||||
return noEOF(err)
|
||||
}
|
||||
f.roffset++
|
||||
f.b |= uint32(c) << (f.nb & regmask.Shift32ByUint)
|
||||
f.nb += 8
|
||||
return nil
|
||||
}
|
||||
|
||||
// Read the next Huffman-encoded symbol from f according to h.
|
||||
func (f *decompressor) huffSym(h *huffmanDecoder) (int, error) {
|
||||
// Since a huffmanDecoder can be empty or be composed of a degenerate tree
|
||||
// with single element, huffSym must error on these two edge cases. In both
|
||||
// cases, the chunks slice will be 0 for the invalid sequence, leading it
|
||||
// satisfy the n == 0 check below.
|
||||
n := uint(h.maxRead)
|
||||
// Optimization. Compiler isn't smart enough to keep f.b,f.nb in registers,
|
||||
// but is smart enough to keep local variables in registers, so use nb and b,
|
||||
// inline call to moreBits and reassign b,nb back to f on return.
|
||||
nb, b := f.nb, f.b
|
||||
for {
|
||||
for nb < n {
|
||||
c, err := f.r.ReadByte()
|
||||
if err != nil {
|
||||
f.b = b
|
||||
f.nb = nb
|
||||
return 0, noEOF(err)
|
||||
}
|
||||
f.roffset++
|
||||
b |= uint32(c) << (nb & regmask.Shift32ByUint)
|
||||
nb += 8
|
||||
}
|
||||
chunk := h.chunks[b&(huffmanNumChunks-1)]
|
||||
n = uint(chunk & huffmanCountMask)
|
||||
if n > huffmanChunkBits {
|
||||
chunk = h.links[chunk>>huffmanValueShift][(b>>huffmanChunkBits)&h.linkMask]
|
||||
n = uint(chunk & huffmanCountMask)
|
||||
}
|
||||
if n <= nb {
|
||||
if n == 0 {
|
||||
f.b = b
|
||||
f.nb = nb
|
||||
if debugDecode {
|
||||
fmt.Println("huffsym: n==0")
|
||||
}
|
||||
f.err = CorruptInputError(f.roffset)
|
||||
return 0, f.err
|
||||
}
|
||||
f.b = b >> (n & regmask.Shift32ByUint)
|
||||
f.nb = nb - n
|
||||
return int(chunk >> huffmanValueShift), nil
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
func makeReader(r io.Reader) Reader {
|
||||
if rr, ok := r.(Reader); ok {
|
||||
return rr
|
||||
}
|
||||
return bufio.NewReader(r)
|
||||
}
|
||||
|
||||
func fixedHuffmanDecoderInit() {
|
||||
fixedOnce.Do(func() {
|
||||
// These come from the RFC section 3.2.6.
|
||||
var bits [288]int
|
||||
for i := range 144 {
|
||||
bits[i] = 8
|
||||
}
|
||||
for i := 144; i < 256; i++ {
|
||||
bits[i] = 9
|
||||
}
|
||||
for i := 256; i < 280; i++ {
|
||||
bits[i] = 7
|
||||
}
|
||||
for i := 280; i < 288; i++ {
|
||||
bits[i] = 8
|
||||
}
|
||||
fixedHuffmanDecoder.init(bits[:])
|
||||
})
|
||||
}
|
||||
|
||||
func (f *decompressor) Reset(r io.Reader, dict []byte) error {
|
||||
*f = decompressor{
|
||||
r: makeReader(r),
|
||||
bits: f.bits,
|
||||
codebits: f.codebits,
|
||||
h1: f.h1,
|
||||
h2: f.h2,
|
||||
dict: f.dict,
|
||||
step: nextBlock,
|
||||
}
|
||||
f.dict.init(maxMatchOffset, dict)
|
||||
return nil
|
||||
}
|
||||
|
||||
// ResetCP will adjust the input to the provided checkpoint.
|
||||
// It is assumed the input stream is forwarded to cp.CompressedOffset.
|
||||
func (f *decompressor) ResetCP(r io.Reader, cp InflateCheckpoint) error {
|
||||
*f = decompressor{
|
||||
r: makeReader(r),
|
||||
bits: f.bits,
|
||||
codebits: f.codebits,
|
||||
h1: f.h1,
|
||||
h2: f.h2,
|
||||
dict: f.dict,
|
||||
step: nextBlock,
|
||||
cpBuf: f.cpBuf,
|
||||
}
|
||||
return f.applyCP(cp)
|
||||
}
|
||||
|
||||
// applyCP seeds the decompressor state from a resume checkpoint:
|
||||
// loads the sliding window, sets the absolute compressed/uncompressed
|
||||
// offsets, and skips cp.BitOffset bits into the first input byte so
|
||||
// the next decode aligns with the start of a deflate block.
|
||||
func (f *decompressor) applyCP(cp InflateCheckpoint) error {
|
||||
f.dict.init(maxMatchOffset, cp.Window)
|
||||
f.roffset = cp.CompressedOffset
|
||||
f.uncOffset = cp.UncompressedOffset
|
||||
f.final = cp.Final
|
||||
f.b = 0
|
||||
f.nb = 0
|
||||
if cp.BitOffset > 0 {
|
||||
c, err := f.r.ReadByte()
|
||||
if err != nil {
|
||||
return noEOF(err)
|
||||
}
|
||||
f.roffset++
|
||||
f.b = uint32(c) >> cp.BitOffset
|
||||
f.nb = 8 - uint(cp.BitOffset)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
type ReaderOpt func(*decompressor)
|
||||
|
||||
// WithPartialBlock tells decompressor to return after each block,
|
||||
// so it can read data written with partial flush
|
||||
func WithPartialBlock() ReaderOpt {
|
||||
return func(f *decompressor) {
|
||||
f.flushMode = partialFlush
|
||||
}
|
||||
}
|
||||
|
||||
// WithDict initializes the reader with a preset dictionary
|
||||
func WithDict(dict []byte) ReaderOpt {
|
||||
return func(f *decompressor) {
|
||||
f.dict.init(maxMatchOffset, dict)
|
||||
}
|
||||
}
|
||||
|
||||
// InflateCheckpoint provides a resumable checkpoint for inflate.
|
||||
type InflateCheckpoint struct {
|
||||
UncompressedOffset int64 // Byte offset in the decompressed stream
|
||||
CompressedOffset int64 // Byte offset in the compressed stream
|
||||
Final bool // True if this is the final block
|
||||
BitOffset uint8 // 0-7 bits
|
||||
Window []byte // 32KB sliding window dictionary
|
||||
}
|
||||
|
||||
// WithEobCallback will call the provided function after each block
|
||||
// with the current gzip checkpoint.
|
||||
// After returning the provided window can no longer be referenced.
|
||||
// The callback will not be triggered after a block is marked "final".
|
||||
// The callback is not retained after Reset.
|
||||
func WithEobCallback(cb func(InflateCheckpoint)) ReaderOpt {
|
||||
return func(f *decompressor) {
|
||||
f.cb = cb
|
||||
}
|
||||
}
|
||||
|
||||
// WithResumeFrom will adjust the input to the provided checkpoint.
|
||||
// It is assumed the input stream is forwarded to the provided offset.
|
||||
// The checkpoint is removed when Reset is called.
|
||||
func WithResumeFrom(cp InflateCheckpoint) ReaderOpt {
|
||||
return func(f *decompressor) {
|
||||
f.cp = cp
|
||||
f.hasCP = true
|
||||
}
|
||||
}
|
||||
|
||||
// NewReaderOpts returns new reader with provided options
|
||||
func NewReaderOpts(r io.Reader, opts ...ReaderOpt) io.ReadCloser {
|
||||
fixedHuffmanDecoderInit()
|
||||
|
||||
var f decompressor
|
||||
f.r = makeReader(r)
|
||||
f.bits = new([maxNumLit + maxNumDist]int)
|
||||
f.codebits = new([numCodes]int)
|
||||
f.step = nextBlock
|
||||
f.dict.init(maxMatchOffset, nil)
|
||||
|
||||
for _, opt := range opts {
|
||||
opt(&f)
|
||||
}
|
||||
|
||||
if f.hasCP {
|
||||
if err := f.applyCP(f.cp); err != nil {
|
||||
f.err = err
|
||||
}
|
||||
}
|
||||
|
||||
return &f
|
||||
}
|
||||
|
||||
// NewReader returns a new ReadCloser that can be used
|
||||
// to read the uncompressed version of r.
|
||||
// If r does not also implement io.ByteReader,
|
||||
// the decompressor may read more data than necessary from r.
|
||||
// It is the caller's responsibility to call Close on the ReadCloser
|
||||
// when finished reading.
|
||||
//
|
||||
// The ReadCloser returned by NewReader also implements Resetter.
|
||||
func NewReader(r io.Reader) io.ReadCloser {
|
||||
return NewReaderOpts(r)
|
||||
}
|
||||
|
||||
// NewReaderDict is like NewReader but initializes the reader
|
||||
// with a preset dictionary. The returned Reader behaves as if
|
||||
// the uncompressed data stream started with the given dictionary,
|
||||
// which has already been read. NewReaderDict is typically used
|
||||
// to read data compressed by NewWriterDict.
|
||||
//
|
||||
// The ReadCloser returned by NewReader also implements Resetter.
|
||||
func NewReaderDict(r io.Reader, dict []byte) io.ReadCloser {
|
||||
return NewReaderOpts(r, WithDict(dict))
|
||||
}
|
||||
Generated
Vendored
-1339
File diff suppressed because it is too large
Load Diff
Generated
Vendored
-215
@@ -1,215 +0,0 @@
|
||||
package flate
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
|
||||
"github.com/klauspost/compress/internal/le"
|
||||
)
|
||||
|
||||
// fastGen maintains the table for matches,
|
||||
// and the previous byte block for level 2.
|
||||
// This is the generic implementation.
|
||||
type fastEncL1 struct {
|
||||
fastGen
|
||||
table [tableSize]tableEntry
|
||||
}
|
||||
|
||||
// EncodeL1 uses a similar algorithm to level 1
|
||||
func (e *fastEncL1) Encode(dst *tokens, src []byte) {
|
||||
const (
|
||||
inputMargin = 12 - 1
|
||||
minNonLiteralBlockSize = 1 + 1 + inputMargin
|
||||
hashBytes = 5
|
||||
)
|
||||
if debugDeflate && e.cur < 0 {
|
||||
panic(fmt.Sprint("e.cur < 0: ", e.cur))
|
||||
}
|
||||
|
||||
// Protect against e.cur wraparound.
|
||||
for e.cur >= bufferReset {
|
||||
if len(e.hist) == 0 {
|
||||
for i := range e.table[:] {
|
||||
e.table[i] = tableEntry{}
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
break
|
||||
}
|
||||
// Shift down everything in the table that isn't already too far away.
|
||||
minOff := e.cur + int32(len(e.hist)) - maxMatchOffset
|
||||
for i := range e.table[:] {
|
||||
v := e.table[i].offset
|
||||
if v <= minOff {
|
||||
v = 0
|
||||
} else {
|
||||
v = v - e.cur + maxMatchOffset
|
||||
}
|
||||
e.table[i].offset = v
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
}
|
||||
|
||||
s := e.addBlock(src)
|
||||
|
||||
// This check isn't in the Snappy implementation, but there, the caller
|
||||
// instead of the callee handles this case.
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
// We do not fill the token table.
|
||||
// This will be picked up by caller.
|
||||
dst.n = uint16(len(src))
|
||||
return
|
||||
}
|
||||
|
||||
// Override src
|
||||
src = e.hist
|
||||
nextEmit := s
|
||||
|
||||
// sLimit is when to stop looking for offset/length copies. The inputMargin
|
||||
// lets us use a fast path for emitLiteral in the main loop, while we are
|
||||
// looking for copies.
|
||||
sLimit := int32(len(src) - inputMargin)
|
||||
|
||||
// nextEmit is where in src the next emitLiteral should start from.
|
||||
cv := load6432(src, s)
|
||||
|
||||
for {
|
||||
const skipLog = 5
|
||||
const doEvery = 2
|
||||
|
||||
nextS := s
|
||||
var candidate tableEntry
|
||||
var t int32
|
||||
for {
|
||||
nextHash := hashLen(cv, tableBits, hashBytes)
|
||||
candidate = e.table[nextHash]
|
||||
nextS = s + doEvery + (s-nextEmit)>>skipLog
|
||||
if nextS > sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
now := load6432(src, nextS)
|
||||
e.table[nextHash] = tableEntry{offset: s + e.cur}
|
||||
nextHash = hashLen(now, tableBits, hashBytes)
|
||||
t = candidate.offset - e.cur
|
||||
if s-t < maxMatchOffset && uint32(cv) == load3232(src, t) {
|
||||
e.table[nextHash] = tableEntry{offset: nextS + e.cur}
|
||||
break
|
||||
}
|
||||
|
||||
// Do one right away...
|
||||
cv = now
|
||||
s = nextS
|
||||
nextS++
|
||||
candidate = e.table[nextHash]
|
||||
now >>= 8
|
||||
e.table[nextHash] = tableEntry{offset: s + e.cur}
|
||||
|
||||
t = candidate.offset - e.cur
|
||||
if s-t < maxMatchOffset && uint32(cv) == load3232(src, t) {
|
||||
e.table[nextHash] = tableEntry{offset: nextS + e.cur}
|
||||
break
|
||||
}
|
||||
cv = now
|
||||
s = nextS
|
||||
}
|
||||
|
||||
// A 4-byte match has been found. We'll later see if more than 4 bytes
|
||||
// match. But, prior to the match, src[nextEmit:s] are unmatched. Emit
|
||||
// them as literal bytes.
|
||||
for {
|
||||
// Invariant: we have a 4-byte match at s, and no need to emit any
|
||||
// literal bytes prior to s.
|
||||
|
||||
// Extend the 4-byte match as long as possible.
|
||||
l := e.matchlenLong(int(s+4), int(t+4), src) + 4
|
||||
|
||||
// Extend backwards
|
||||
for t > 0 && s > nextEmit && le.Load8(src, t-1) == le.Load8(src, s-1) {
|
||||
s--
|
||||
t--
|
||||
l++
|
||||
}
|
||||
if nextEmit < s {
|
||||
if false {
|
||||
emitLiteral(dst, src[nextEmit:s])
|
||||
} else {
|
||||
for _, v := range src[nextEmit:s] {
|
||||
dst.tokens[dst.n] = token(v)
|
||||
dst.litHist[v]++
|
||||
dst.n++
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// Save the match found
|
||||
if false {
|
||||
dst.AddMatchLong(l, uint32(s-t-baseMatchOffset))
|
||||
} else {
|
||||
// Inlined...
|
||||
xoffset := uint32(s - t - baseMatchOffset)
|
||||
xlength := l
|
||||
oc := offsetCode(xoffset)
|
||||
xoffset |= oc << 16
|
||||
for xlength > 0 {
|
||||
xl := xlength
|
||||
if xl > 258 {
|
||||
if xl > 258+baseMatchLength {
|
||||
xl = 258
|
||||
} else {
|
||||
xl = 258 - baseMatchLength
|
||||
}
|
||||
}
|
||||
xlength -= xl
|
||||
xl -= baseMatchLength
|
||||
dst.extraHist[lengthCodes1[uint8(xl)]]++
|
||||
dst.offHist[oc]++
|
||||
dst.tokens[dst.n] = token(matchType | uint32(xl)<<lengthShift | xoffset)
|
||||
dst.n++
|
||||
}
|
||||
}
|
||||
s += l
|
||||
nextEmit = s
|
||||
if nextS >= s {
|
||||
s = nextS + 1
|
||||
}
|
||||
if s >= sLimit {
|
||||
// Index first pair after match end.
|
||||
if int(s+l+8) < len(src) {
|
||||
cv := load6432(src, s)
|
||||
e.table[hashLen(cv, tableBits, hashBytes)] = tableEntry{offset: s + e.cur}
|
||||
}
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
// We could immediately start working at s now, but to improve
|
||||
// compression we first update the hash table at s-2 and at s. If
|
||||
// another emitCopy is not our next move, also calculate nextHash
|
||||
// at s+1. At least on GOARCH=amd64, these three hash calculations
|
||||
// are faster as one load64 call (with some shifts) instead of
|
||||
// three load32 calls.
|
||||
x := load6432(src, s-2)
|
||||
o := e.cur + s - 2
|
||||
prevHash := hashLen(x, tableBits, hashBytes)
|
||||
e.table[prevHash] = tableEntry{offset: o}
|
||||
x >>= 16
|
||||
currHash := hashLen(x, tableBits, hashBytes)
|
||||
candidate = e.table[currHash]
|
||||
e.table[currHash] = tableEntry{offset: o + 2}
|
||||
|
||||
t = candidate.offset - e.cur
|
||||
if s-t > maxMatchOffset || uint32(x) != load3232(src, t) {
|
||||
cv = x >> 8
|
||||
s++
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
emitRemainder:
|
||||
if int(nextEmit) < len(src) {
|
||||
// If nothing was added, don't encode literals.
|
||||
if dst.n == 0 {
|
||||
return
|
||||
}
|
||||
emitLiteral(dst, src[nextEmit:])
|
||||
}
|
||||
}
|
||||
Generated
Vendored
-214
@@ -1,214 +0,0 @@
|
||||
package flate
|
||||
|
||||
import "fmt"
|
||||
|
||||
// fastGen maintains the table for matches,
|
||||
// and the previous byte block for level 2.
|
||||
// This is the generic implementation.
|
||||
type fastEncL2 struct {
|
||||
fastGen
|
||||
table [bTableSize]tableEntry
|
||||
}
|
||||
|
||||
// EncodeL2 uses a similar algorithm to level 1, but is capable
|
||||
// of matching across blocks giving better compression at a small slowdown.
|
||||
func (e *fastEncL2) Encode(dst *tokens, src []byte) {
|
||||
const (
|
||||
inputMargin = 12 - 1
|
||||
minNonLiteralBlockSize = 1 + 1 + inputMargin
|
||||
hashBytes = 5
|
||||
)
|
||||
|
||||
if debugDeflate && e.cur < 0 {
|
||||
panic(fmt.Sprint("e.cur < 0: ", e.cur))
|
||||
}
|
||||
|
||||
// Protect against e.cur wraparound.
|
||||
for e.cur >= bufferReset {
|
||||
if len(e.hist) == 0 {
|
||||
for i := range e.table[:] {
|
||||
e.table[i] = tableEntry{}
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
break
|
||||
}
|
||||
// Shift down everything in the table that isn't already too far away.
|
||||
minOff := e.cur + int32(len(e.hist)) - maxMatchOffset
|
||||
for i := range e.table[:] {
|
||||
v := e.table[i].offset
|
||||
if v <= minOff {
|
||||
v = 0
|
||||
} else {
|
||||
v = v - e.cur + maxMatchOffset
|
||||
}
|
||||
e.table[i].offset = v
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
}
|
||||
|
||||
s := e.addBlock(src)
|
||||
|
||||
// This check isn't in the Snappy implementation, but there, the caller
|
||||
// instead of the callee handles this case.
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
// We do not fill the token table.
|
||||
// This will be picked up by caller.
|
||||
dst.n = uint16(len(src))
|
||||
return
|
||||
}
|
||||
|
||||
// Override src
|
||||
src = e.hist
|
||||
nextEmit := s
|
||||
|
||||
// sLimit is when to stop looking for offset/length copies. The inputMargin
|
||||
// lets us use a fast path for emitLiteral in the main loop, while we are
|
||||
// looking for copies.
|
||||
sLimit := int32(len(src) - inputMargin)
|
||||
|
||||
// nextEmit is where in src the next emitLiteral should start from.
|
||||
cv := load6432(src, s)
|
||||
for {
|
||||
// When should we start skipping if we haven't found matches in a long while.
|
||||
const skipLog = 5
|
||||
const doEvery = 2
|
||||
|
||||
nextS := s
|
||||
var candidate tableEntry
|
||||
for {
|
||||
nextHash := hashLen(cv, bTableBits, hashBytes)
|
||||
s = nextS
|
||||
nextS = s + doEvery + (s-nextEmit)>>skipLog
|
||||
if nextS > sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
candidate = e.table[nextHash]
|
||||
now := load6432(src, nextS)
|
||||
e.table[nextHash] = tableEntry{offset: s + e.cur}
|
||||
nextHash = hashLen(now, bTableBits, hashBytes)
|
||||
|
||||
offset := s - (candidate.offset - e.cur)
|
||||
if offset < maxMatchOffset && uint32(cv) == load3232(src, candidate.offset-e.cur) {
|
||||
e.table[nextHash] = tableEntry{offset: nextS + e.cur}
|
||||
break
|
||||
}
|
||||
|
||||
// Do one right away...
|
||||
cv = now
|
||||
s = nextS
|
||||
nextS++
|
||||
candidate = e.table[nextHash]
|
||||
now >>= 8
|
||||
e.table[nextHash] = tableEntry{offset: s + e.cur}
|
||||
|
||||
offset = s - (candidate.offset - e.cur)
|
||||
if offset < maxMatchOffset && uint32(cv) == load3232(src, candidate.offset-e.cur) {
|
||||
break
|
||||
}
|
||||
cv = now
|
||||
}
|
||||
|
||||
// A 4-byte match has been found. We'll later see if more than 4 bytes
|
||||
// match. But, prior to the match, src[nextEmit:s] are unmatched. Emit
|
||||
// them as literal bytes.
|
||||
|
||||
// Call emitCopy, and then see if another emitCopy could be our next
|
||||
// move. Repeat until we find no match for the input immediately after
|
||||
// what was consumed by the last emitCopy call.
|
||||
//
|
||||
// If we exit this loop normally then we need to call emitLiteral next,
|
||||
// though we don't yet know how big the literal will be. We handle that
|
||||
// by proceeding to the next iteration of the main loop. We also can
|
||||
// exit this loop via goto if we get close to exhausting the input.
|
||||
for {
|
||||
// Invariant: we have a 4-byte match at s, and no need to emit any
|
||||
// literal bytes prior to s.
|
||||
|
||||
// Extend the 4-byte match as long as possible.
|
||||
t := candidate.offset - e.cur
|
||||
l := e.matchlenLong(int(s+4), int(t+4), src) + 4
|
||||
|
||||
// Extend backwards
|
||||
for t > 0 && s > nextEmit && src[t-1] == src[s-1] {
|
||||
s--
|
||||
t--
|
||||
l++
|
||||
}
|
||||
if nextEmit < s {
|
||||
if false {
|
||||
emitLiteral(dst, src[nextEmit:s])
|
||||
} else {
|
||||
for _, v := range src[nextEmit:s] {
|
||||
dst.tokens[dst.n] = token(v)
|
||||
dst.litHist[v]++
|
||||
dst.n++
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
dst.AddMatchLong(l, uint32(s-t-baseMatchOffset))
|
||||
s += l
|
||||
nextEmit = s
|
||||
if nextS >= s {
|
||||
s = nextS + 1
|
||||
}
|
||||
|
||||
if s >= sLimit {
|
||||
// Index first pair after match end.
|
||||
if int(s+l+8) < len(src) {
|
||||
cv := load6432(src, s)
|
||||
e.table[hashLen(cv, bTableBits, hashBytes)] = tableEntry{offset: s + e.cur}
|
||||
}
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
// Store every second hash in-between, but offset by 1.
|
||||
for i := s - l + 2; i < s-5; i += 7 {
|
||||
x := load6432(src, i)
|
||||
nextHash := hashLen(x, bTableBits, hashBytes)
|
||||
e.table[nextHash] = tableEntry{offset: e.cur + i}
|
||||
// Skip one
|
||||
x >>= 16
|
||||
nextHash = hashLen(x, bTableBits, hashBytes)
|
||||
e.table[nextHash] = tableEntry{offset: e.cur + i + 2}
|
||||
// Skip one
|
||||
x >>= 16
|
||||
nextHash = hashLen(x, bTableBits, hashBytes)
|
||||
e.table[nextHash] = tableEntry{offset: e.cur + i + 4}
|
||||
}
|
||||
|
||||
// We could immediately start working at s now, but to improve
|
||||
// compression we first update the hash table at s-2 to s. If
|
||||
// another emitCopy is not our next move, also calculate nextHash
|
||||
// at s+1. At least on GOARCH=amd64, these three hash calculations
|
||||
// are faster as one load64 call (with some shifts) instead of
|
||||
// three load32 calls.
|
||||
x := load6432(src, s-2)
|
||||
o := e.cur + s - 2
|
||||
prevHash := hashLen(x, bTableBits, hashBytes)
|
||||
prevHash2 := hashLen(x>>8, bTableBits, hashBytes)
|
||||
e.table[prevHash] = tableEntry{offset: o}
|
||||
e.table[prevHash2] = tableEntry{offset: o + 1}
|
||||
currHash := hashLen(x>>16, bTableBits, hashBytes)
|
||||
candidate = e.table[currHash]
|
||||
e.table[currHash] = tableEntry{offset: o + 2}
|
||||
|
||||
offset := s - (candidate.offset - e.cur)
|
||||
if offset > maxMatchOffset || uint32(x>>16) != load3232(src, candidate.offset-e.cur) {
|
||||
cv = x >> 24
|
||||
s++
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
emitRemainder:
|
||||
if int(nextEmit) < len(src) {
|
||||
// If nothing was added, don't encode literals.
|
||||
if dst.n == 0 {
|
||||
return
|
||||
}
|
||||
|
||||
emitLiteral(dst, src[nextEmit:])
|
||||
}
|
||||
}
|
||||
Generated
Vendored
-241
@@ -1,241 +0,0 @@
|
||||
package flate
|
||||
|
||||
import "fmt"
|
||||
|
||||
// fastEncL3
|
||||
type fastEncL3 struct {
|
||||
fastGen
|
||||
table [1 << 16]tableEntryPrev
|
||||
}
|
||||
|
||||
// Encode uses a similar algorithm to level 2, will check up to two candidates.
|
||||
func (e *fastEncL3) Encode(dst *tokens, src []byte) {
|
||||
const (
|
||||
inputMargin = 12 - 1
|
||||
minNonLiteralBlockSize = 1 + 1 + inputMargin
|
||||
tableBits = 16
|
||||
tableSize = 1 << tableBits
|
||||
hashBytes = 5
|
||||
)
|
||||
|
||||
if debugDeflate && e.cur < 0 {
|
||||
panic(fmt.Sprint("e.cur < 0: ", e.cur))
|
||||
}
|
||||
|
||||
// Protect against e.cur wraparound.
|
||||
for e.cur >= bufferReset {
|
||||
if len(e.hist) == 0 {
|
||||
for i := range e.table[:] {
|
||||
e.table[i] = tableEntryPrev{}
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
break
|
||||
}
|
||||
// Shift down everything in the table that isn't already too far away.
|
||||
minOff := e.cur + int32(len(e.hist)) - maxMatchOffset
|
||||
for i := range e.table[:] {
|
||||
v := e.table[i]
|
||||
if v.Cur.offset <= minOff {
|
||||
v.Cur.offset = 0
|
||||
} else {
|
||||
v.Cur.offset = v.Cur.offset - e.cur + maxMatchOffset
|
||||
}
|
||||
if v.Prev.offset <= minOff {
|
||||
v.Prev.offset = 0
|
||||
} else {
|
||||
v.Prev.offset = v.Prev.offset - e.cur + maxMatchOffset
|
||||
}
|
||||
e.table[i] = v
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
}
|
||||
|
||||
s := e.addBlock(src)
|
||||
|
||||
// Skip if too small.
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
// We do not fill the token table.
|
||||
// This will be picked up by caller.
|
||||
dst.n = uint16(len(src))
|
||||
return
|
||||
}
|
||||
|
||||
// Override src
|
||||
src = e.hist
|
||||
nextEmit := s
|
||||
|
||||
// sLimit is when to stop looking for offset/length copies. The inputMargin
|
||||
// lets us use a fast path for emitLiteral in the main loop, while we are
|
||||
// looking for copies.
|
||||
sLimit := int32(len(src) - inputMargin)
|
||||
|
||||
// nextEmit is where in src the next emitLiteral should start from.
|
||||
cv := load6432(src, s)
|
||||
for {
|
||||
const skipLog = 7
|
||||
nextS := s
|
||||
var candidate tableEntry
|
||||
for {
|
||||
nextHash := hashLen(cv, tableBits, hashBytes)
|
||||
s = nextS
|
||||
nextS = s + 1 + (s-nextEmit)>>skipLog
|
||||
if nextS > sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
candidates := e.table[nextHash]
|
||||
now := load6432(src, nextS)
|
||||
|
||||
// Safe offset distance until s + 4...
|
||||
minOffset := e.cur + s - (maxMatchOffset - 4)
|
||||
e.table[nextHash] = tableEntryPrev{Prev: candidates.Cur, Cur: tableEntry{offset: s + e.cur}}
|
||||
|
||||
// Check both candidates
|
||||
candidate = candidates.Cur
|
||||
if candidate.offset < minOffset {
|
||||
cv = now
|
||||
// Previous will also be invalid, we have nothing.
|
||||
continue
|
||||
}
|
||||
|
||||
if uint32(cv) == load3232(src, candidate.offset-e.cur) {
|
||||
if candidates.Prev.offset < minOffset || uint32(cv) != load3232(src, candidates.Prev.offset-e.cur) {
|
||||
break
|
||||
}
|
||||
// Both match and are valid, pick longest.
|
||||
offset := s - (candidate.offset - e.cur)
|
||||
o2 := s - (candidates.Prev.offset - e.cur)
|
||||
l1, l2 := matchLen(src[s+4:], src[s-offset+4:]), matchLen(src[s+4:], src[s-o2+4:])
|
||||
if l2 > l1 {
|
||||
candidate = candidates.Prev
|
||||
}
|
||||
break
|
||||
} else {
|
||||
// We only check if value mismatches.
|
||||
// Offset will always be invalid in other cases.
|
||||
candidate = candidates.Prev
|
||||
if candidate.offset > minOffset && uint32(cv) == load3232(src, candidate.offset-e.cur) {
|
||||
break
|
||||
}
|
||||
}
|
||||
cv = now
|
||||
}
|
||||
|
||||
// Call emitCopy, and then see if another emitCopy could be our next
|
||||
// move. Repeat until we find no match for the input immediately after
|
||||
// what was consumed by the last emitCopy call.
|
||||
//
|
||||
// If we exit this loop normally then we need to call emitLiteral next,
|
||||
// though we don't yet know how big the literal will be. We handle that
|
||||
// by proceeding to the next iteration of the main loop. We also can
|
||||
// exit this loop via goto if we get close to exhausting the input.
|
||||
for {
|
||||
// Invariant: we have a 4-byte match at s, and no need to emit any
|
||||
// literal bytes prior to s.
|
||||
|
||||
// Extend the 4-byte match as long as possible.
|
||||
//
|
||||
t := candidate.offset - e.cur
|
||||
l := e.matchlenLong(int(s+4), int(t+4), src) + 4
|
||||
|
||||
// Extend backwards
|
||||
for t > 0 && s > nextEmit && src[t-1] == src[s-1] {
|
||||
s--
|
||||
t--
|
||||
l++
|
||||
}
|
||||
if nextEmit < s {
|
||||
if false {
|
||||
emitLiteral(dst, src[nextEmit:s])
|
||||
} else {
|
||||
for _, v := range src[nextEmit:s] {
|
||||
dst.tokens[dst.n] = token(v)
|
||||
dst.litHist[v]++
|
||||
dst.n++
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
dst.AddMatchLong(l, uint32(s-t-baseMatchOffset))
|
||||
s += l
|
||||
nextEmit = s
|
||||
if nextS >= s {
|
||||
s = nextS + 1
|
||||
}
|
||||
|
||||
if s >= sLimit {
|
||||
t += l
|
||||
// Index first pair after match end.
|
||||
if int(t+8) < len(src) && t > 0 {
|
||||
cv = load6432(src, t)
|
||||
nextHash := hashLen(cv, tableBits, hashBytes)
|
||||
e.table[nextHash] = tableEntryPrev{
|
||||
Prev: e.table[nextHash].Cur,
|
||||
Cur: tableEntry{offset: e.cur + t},
|
||||
}
|
||||
}
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
// Store every 5th hash in-between.
|
||||
for i := s - l + 2; i < s-5; i += 6 {
|
||||
nextHash := hashLen(load6432(src, i), tableBits, hashBytes)
|
||||
e.table[nextHash] = tableEntryPrev{
|
||||
Prev: e.table[nextHash].Cur,
|
||||
Cur: tableEntry{offset: e.cur + i}}
|
||||
}
|
||||
// We could immediately start working at s now, but to improve
|
||||
// compression we first update the hash table at s-2 to s.
|
||||
x := load6432(src, s-2)
|
||||
prevHash := hashLen(x, tableBits, hashBytes)
|
||||
|
||||
e.table[prevHash] = tableEntryPrev{
|
||||
Prev: e.table[prevHash].Cur,
|
||||
Cur: tableEntry{offset: e.cur + s - 2},
|
||||
}
|
||||
x >>= 8
|
||||
prevHash = hashLen(x, tableBits, hashBytes)
|
||||
|
||||
e.table[prevHash] = tableEntryPrev{
|
||||
Prev: e.table[prevHash].Cur,
|
||||
Cur: tableEntry{offset: e.cur + s - 1},
|
||||
}
|
||||
x >>= 8
|
||||
currHash := hashLen(x, tableBits, hashBytes)
|
||||
candidates := e.table[currHash]
|
||||
cv = x
|
||||
e.table[currHash] = tableEntryPrev{
|
||||
Prev: candidates.Cur,
|
||||
Cur: tableEntry{offset: s + e.cur},
|
||||
}
|
||||
|
||||
// Check both candidates
|
||||
candidate = candidates.Cur
|
||||
minOffset := e.cur + s - (maxMatchOffset - 4)
|
||||
|
||||
if candidate.offset > minOffset {
|
||||
if uint32(cv) == load3232(src, candidate.offset-e.cur) {
|
||||
// Found a match...
|
||||
continue
|
||||
}
|
||||
candidate = candidates.Prev
|
||||
if candidate.offset > minOffset && uint32(cv) == load3232(src, candidate.offset-e.cur) {
|
||||
// Match at prev...
|
||||
continue
|
||||
}
|
||||
}
|
||||
cv = x >> 8
|
||||
s++
|
||||
break
|
||||
}
|
||||
}
|
||||
|
||||
emitRemainder:
|
||||
if int(nextEmit) < len(src) {
|
||||
// If nothing was added, don't encode literals.
|
||||
if dst.n == 0 {
|
||||
return
|
||||
}
|
||||
|
||||
emitLiteral(dst, src[nextEmit:])
|
||||
}
|
||||
}
|
||||
Generated
Vendored
-221
@@ -1,221 +0,0 @@
|
||||
package flate
|
||||
|
||||
import "fmt"
|
||||
|
||||
type fastEncL4 struct {
|
||||
fastGen
|
||||
table [tableSize]tableEntry
|
||||
bTable [tableSize]tableEntry
|
||||
}
|
||||
|
||||
func (e *fastEncL4) Encode(dst *tokens, src []byte) {
|
||||
const (
|
||||
inputMargin = 12 - 1
|
||||
minNonLiteralBlockSize = 1 + 1 + inputMargin
|
||||
hashShortBytes = 4
|
||||
)
|
||||
if debugDeflate && e.cur < 0 {
|
||||
panic(fmt.Sprint("e.cur < 0: ", e.cur))
|
||||
}
|
||||
// Protect against e.cur wraparound.
|
||||
for e.cur >= bufferReset {
|
||||
if len(e.hist) == 0 {
|
||||
for i := range e.table[:] {
|
||||
e.table[i] = tableEntry{}
|
||||
}
|
||||
for i := range e.bTable[:] {
|
||||
e.bTable[i] = tableEntry{}
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
break
|
||||
}
|
||||
// Shift down everything in the table that isn't already too far away.
|
||||
minOff := e.cur + int32(len(e.hist)) - maxMatchOffset
|
||||
for i := range e.table[:] {
|
||||
v := e.table[i].offset
|
||||
if v <= minOff {
|
||||
v = 0
|
||||
} else {
|
||||
v = v - e.cur + maxMatchOffset
|
||||
}
|
||||
e.table[i].offset = v
|
||||
}
|
||||
for i := range e.bTable[:] {
|
||||
v := e.bTable[i].offset
|
||||
if v <= minOff {
|
||||
v = 0
|
||||
} else {
|
||||
v = v - e.cur + maxMatchOffset
|
||||
}
|
||||
e.bTable[i].offset = v
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
}
|
||||
|
||||
s := e.addBlock(src)
|
||||
|
||||
// This check isn't in the Snappy implementation, but there, the caller
|
||||
// instead of the callee handles this case.
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
// We do not fill the token table.
|
||||
// This will be picked up by caller.
|
||||
dst.n = uint16(len(src))
|
||||
return
|
||||
}
|
||||
|
||||
// Override src
|
||||
src = e.hist
|
||||
nextEmit := s
|
||||
|
||||
// sLimit is when to stop looking for offset/length copies. The inputMargin
|
||||
// lets us use a fast path for emitLiteral in the main loop, while we are
|
||||
// looking for copies.
|
||||
sLimit := int32(len(src) - inputMargin)
|
||||
|
||||
// nextEmit is where in src the next emitLiteral should start from.
|
||||
cv := load6432(src, s)
|
||||
for {
|
||||
const skipLog = 6
|
||||
const doEvery = 1
|
||||
|
||||
nextS := s
|
||||
var t int32
|
||||
for {
|
||||
nextHashS := hashLen(cv, tableBits, hashShortBytes)
|
||||
nextHashL := hash7(cv, tableBits)
|
||||
|
||||
s = nextS
|
||||
nextS = s + doEvery + (s-nextEmit)>>skipLog
|
||||
if nextS > sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
// Fetch a short+long candidate
|
||||
sCandidate := e.table[nextHashS]
|
||||
lCandidate := e.bTable[nextHashL]
|
||||
next := load6432(src, nextS)
|
||||
entry := tableEntry{offset: s + e.cur}
|
||||
e.table[nextHashS] = entry
|
||||
e.bTable[nextHashL] = entry
|
||||
|
||||
t = lCandidate.offset - e.cur
|
||||
if s-t < maxMatchOffset && uint32(cv) == load3232(src, t) {
|
||||
// We got a long match. Use that.
|
||||
break
|
||||
}
|
||||
|
||||
t = sCandidate.offset - e.cur
|
||||
if s-t < maxMatchOffset && uint32(cv) == load3232(src, t) {
|
||||
// Found a 4 match...
|
||||
lCandidate = e.bTable[hash7(next, tableBits)]
|
||||
|
||||
// If the next long is a candidate, check if we should use that instead...
|
||||
lOff := lCandidate.offset - e.cur
|
||||
if nextS-lOff < maxMatchOffset && load3232(src, lOff) == uint32(next) {
|
||||
l1, l2 := matchLen(src[s+4:], src[t+4:]), matchLen(src[nextS+4:], src[nextS-lOff+4:])
|
||||
if l2 > l1 {
|
||||
s = nextS
|
||||
t = lCandidate.offset - e.cur
|
||||
}
|
||||
}
|
||||
break
|
||||
}
|
||||
cv = next
|
||||
}
|
||||
|
||||
// A 4-byte match has been found. We'll later see if more than 4 bytes
|
||||
// match. But, prior to the match, src[nextEmit:s] are unmatched. Emit
|
||||
// them as literal bytes.
|
||||
|
||||
// Extend the 4-byte match as long as possible.
|
||||
l := e.matchlenLong(int(s+4), int(t+4), src) + 4
|
||||
|
||||
// Extend backwards
|
||||
for t > 0 && s > nextEmit && src[t-1] == src[s-1] {
|
||||
s--
|
||||
t--
|
||||
l++
|
||||
}
|
||||
if nextEmit < s {
|
||||
if false {
|
||||
emitLiteral(dst, src[nextEmit:s])
|
||||
} else {
|
||||
for _, v := range src[nextEmit:s] {
|
||||
dst.tokens[dst.n] = token(v)
|
||||
dst.litHist[v]++
|
||||
dst.n++
|
||||
}
|
||||
}
|
||||
}
|
||||
if debugDeflate {
|
||||
if t >= s {
|
||||
panic("s-t")
|
||||
}
|
||||
if (s - t) > maxMatchOffset {
|
||||
panic(fmt.Sprintln("mmo", t))
|
||||
}
|
||||
if l < baseMatchLength {
|
||||
panic("bml")
|
||||
}
|
||||
}
|
||||
|
||||
dst.AddMatchLong(l, uint32(s-t-baseMatchOffset))
|
||||
s += l
|
||||
nextEmit = s
|
||||
if nextS >= s {
|
||||
s = nextS + 1
|
||||
}
|
||||
|
||||
if s >= sLimit {
|
||||
// Index first pair after match end.
|
||||
if int(s+8) < len(src) {
|
||||
cv := load6432(src, s)
|
||||
e.table[hashLen(cv, tableBits, hashShortBytes)] = tableEntry{offset: s + e.cur}
|
||||
e.bTable[hash7(cv, tableBits)] = tableEntry{offset: s + e.cur}
|
||||
}
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
// Store every 3rd hash in-between
|
||||
if true {
|
||||
i := nextS
|
||||
if i < s-1 {
|
||||
cv := load6432(src, i)
|
||||
t := tableEntry{offset: i + e.cur}
|
||||
t2 := tableEntry{offset: t.offset + 1}
|
||||
e.bTable[hash7(cv, tableBits)] = t
|
||||
e.bTable[hash7(cv>>8, tableBits)] = t2
|
||||
e.table[hashLen(cv>>8, tableBits, hashShortBytes)] = t2
|
||||
|
||||
i += 3
|
||||
for ; i < s-1; i += 3 {
|
||||
cv := load6432(src, i)
|
||||
t := tableEntry{offset: i + e.cur}
|
||||
t2 := tableEntry{offset: t.offset + 1}
|
||||
e.bTable[hash7(cv, tableBits)] = t
|
||||
e.bTable[hash7(cv>>8, tableBits)] = t2
|
||||
e.table[hashLen(cv>>8, tableBits, hashShortBytes)] = t2
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// We could immediately start working at s now, but to improve
|
||||
// compression we first update the hash table at s-1 and at s.
|
||||
x := load6432(src, s-1)
|
||||
o := e.cur + s - 1
|
||||
prevHashS := hashLen(x, tableBits, hashShortBytes)
|
||||
prevHashL := hash7(x, tableBits)
|
||||
e.table[prevHashS] = tableEntry{offset: o}
|
||||
e.bTable[prevHashL] = tableEntry{offset: o}
|
||||
cv = x >> 8
|
||||
}
|
||||
|
||||
emitRemainder:
|
||||
if int(nextEmit) < len(src) {
|
||||
// If nothing was added, don't encode literals.
|
||||
if dst.n == 0 {
|
||||
return
|
||||
}
|
||||
|
||||
emitLiteral(dst, src[nextEmit:])
|
||||
}
|
||||
}
|
||||
Generated
Vendored
-705
@@ -1,705 +0,0 @@
|
||||
package flate
|
||||
|
||||
import "fmt"
|
||||
|
||||
type fastEncL5 struct {
|
||||
fastGen
|
||||
table [tableSize]tableEntry
|
||||
bTable [tableSize]tableEntryPrev
|
||||
}
|
||||
|
||||
func (e *fastEncL5) Encode(dst *tokens, src []byte) {
|
||||
const (
|
||||
inputMargin = 12 - 1
|
||||
minNonLiteralBlockSize = 1 + 1 + inputMargin
|
||||
hashShortBytes = 4
|
||||
)
|
||||
if debugDeflate && e.cur < 0 {
|
||||
panic(fmt.Sprint("e.cur < 0: ", e.cur))
|
||||
}
|
||||
|
||||
// Protect against e.cur wraparound.
|
||||
for e.cur >= bufferReset {
|
||||
if len(e.hist) == 0 {
|
||||
for i := range e.table[:] {
|
||||
e.table[i] = tableEntry{}
|
||||
}
|
||||
for i := range e.bTable[:] {
|
||||
e.bTable[i] = tableEntryPrev{}
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
break
|
||||
}
|
||||
// Shift down everything in the table that isn't already too far away.
|
||||
minOff := e.cur + int32(len(e.hist)) - maxMatchOffset
|
||||
for i := range e.table[:] {
|
||||
v := e.table[i].offset
|
||||
if v <= minOff {
|
||||
v = 0
|
||||
} else {
|
||||
v = v - e.cur + maxMatchOffset
|
||||
}
|
||||
e.table[i].offset = v
|
||||
}
|
||||
for i := range e.bTable[:] {
|
||||
v := e.bTable[i]
|
||||
if v.Cur.offset <= minOff {
|
||||
v.Cur.offset = 0
|
||||
v.Prev.offset = 0
|
||||
} else {
|
||||
v.Cur.offset = v.Cur.offset - e.cur + maxMatchOffset
|
||||
if v.Prev.offset <= minOff {
|
||||
v.Prev.offset = 0
|
||||
} else {
|
||||
v.Prev.offset = v.Prev.offset - e.cur + maxMatchOffset
|
||||
}
|
||||
}
|
||||
e.bTable[i] = v
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
}
|
||||
|
||||
s := e.addBlock(src)
|
||||
|
||||
// This check isn't in the Snappy implementation, but there, the caller
|
||||
// instead of the callee handles this case.
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
// We do not fill the token table.
|
||||
// This will be picked up by caller.
|
||||
dst.n = uint16(len(src))
|
||||
return
|
||||
}
|
||||
|
||||
// Override src
|
||||
src = e.hist
|
||||
nextEmit := s
|
||||
|
||||
// sLimit is when to stop looking for offset/length copies. The inputMargin
|
||||
// lets us use a fast path for emitLiteral in the main loop, while we are
|
||||
// looking for copies.
|
||||
sLimit := int32(len(src) - inputMargin)
|
||||
|
||||
// nextEmit is where in src the next emitLiteral should start from.
|
||||
cv := load6432(src, s)
|
||||
for {
|
||||
const skipLog = 6
|
||||
const doEvery = 1
|
||||
|
||||
nextS := s
|
||||
var l int32
|
||||
var t int32
|
||||
for {
|
||||
nextHashS := hashLen(cv, tableBits, hashShortBytes)
|
||||
nextHashL := hash7(cv, tableBits)
|
||||
|
||||
s = nextS
|
||||
nextS = s + doEvery + (s-nextEmit)>>skipLog
|
||||
if nextS > sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
// Fetch a short+long candidate
|
||||
sCandidate := e.table[nextHashS]
|
||||
lCandidate := e.bTable[nextHashL]
|
||||
next := load6432(src, nextS)
|
||||
entry := tableEntry{offset: s + e.cur}
|
||||
e.table[nextHashS] = entry
|
||||
eLong := &e.bTable[nextHashL]
|
||||
eLong.Cur, eLong.Prev = entry, eLong.Cur
|
||||
|
||||
nextHashS = hashLen(next, tableBits, hashShortBytes)
|
||||
nextHashL = hash7(next, tableBits)
|
||||
|
||||
t = lCandidate.Cur.offset - e.cur
|
||||
if s-t < maxMatchOffset {
|
||||
if uint32(cv) == load3232(src, t) {
|
||||
// Store the next match
|
||||
e.table[nextHashS] = tableEntry{offset: nextS + e.cur}
|
||||
eLong := &e.bTable[nextHashL]
|
||||
eLong.Cur, eLong.Prev = tableEntry{offset: nextS + e.cur}, eLong.Cur
|
||||
|
||||
t2 := lCandidate.Prev.offset - e.cur
|
||||
if s-t2 < maxMatchOffset && uint32(cv) == load3232(src, t2) {
|
||||
l = e.matchlen(int(s+4), int(t+4), src) + 4
|
||||
ml1 := e.matchlen(int(s+4), int(t2+4), src) + 4
|
||||
if ml1 > l {
|
||||
t = t2
|
||||
l = ml1
|
||||
break
|
||||
}
|
||||
}
|
||||
break
|
||||
}
|
||||
t = lCandidate.Prev.offset - e.cur
|
||||
if s-t < maxMatchOffset && uint32(cv) == load3232(src, t) {
|
||||
// Store the next match
|
||||
e.table[nextHashS] = tableEntry{offset: nextS + e.cur}
|
||||
eLong := &e.bTable[nextHashL]
|
||||
eLong.Cur, eLong.Prev = tableEntry{offset: nextS + e.cur}, eLong.Cur
|
||||
break
|
||||
}
|
||||
}
|
||||
|
||||
t = sCandidate.offset - e.cur
|
||||
if s-t < maxMatchOffset && uint32(cv) == load3232(src, t) {
|
||||
// Found a 4 match...
|
||||
l = e.matchlen(int(s+4), int(t+4), src) + 4
|
||||
lCandidate = e.bTable[nextHashL]
|
||||
// Store the next match
|
||||
|
||||
e.table[nextHashS] = tableEntry{offset: nextS + e.cur}
|
||||
eLong := &e.bTable[nextHashL]
|
||||
eLong.Cur, eLong.Prev = tableEntry{offset: nextS + e.cur}, eLong.Cur
|
||||
|
||||
// If the next long is a candidate, use that...
|
||||
t2 := lCandidate.Cur.offset - e.cur
|
||||
if nextS-t2 < maxMatchOffset {
|
||||
if load3232(src, t2) == uint32(next) {
|
||||
ml := e.matchlen(int(nextS+4), int(t2+4), src) + 4
|
||||
if ml > l {
|
||||
t = t2
|
||||
s = nextS
|
||||
l = ml
|
||||
break
|
||||
}
|
||||
}
|
||||
// If the previous long is a candidate, use that...
|
||||
t2 = lCandidate.Prev.offset - e.cur
|
||||
if nextS-t2 < maxMatchOffset && load3232(src, t2) == uint32(next) {
|
||||
ml := e.matchlen(int(nextS+4), int(t2+4), src) + 4
|
||||
if ml > l {
|
||||
t = t2
|
||||
s = nextS
|
||||
l = ml
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
break
|
||||
}
|
||||
cv = next
|
||||
}
|
||||
|
||||
// A 4-byte match has been found. We'll later see if more than 4 bytes
|
||||
// match. But, prior to the match, src[nextEmit:s] are unmatched. Emit
|
||||
// them as literal bytes.
|
||||
|
||||
if l == 0 {
|
||||
// Extend the 4-byte match as long as possible.
|
||||
l = e.matchlenLong(int(s+4), int(t+4), src) + 4
|
||||
} else if l == maxMatchLength {
|
||||
l += e.matchlenLong(int(s+l), int(t+l), src)
|
||||
}
|
||||
|
||||
// Try to locate a better match by checking the end of best match...
|
||||
if sAt := s + l; l < 30 && sAt < sLimit {
|
||||
// Allow some bytes at the beginning to mismatch.
|
||||
// Sweet spot is 2/3 bytes depending on input.
|
||||
// 3 is only a little better when it is but sometimes a lot worse.
|
||||
// The skipped bytes are tested in Extend backwards,
|
||||
// and still picked up as part of the match if they do.
|
||||
const skipBeginning = 2
|
||||
eLong := e.bTable[hash7(load6432(src, sAt), tableBits)].Cur.offset
|
||||
t2 := eLong - e.cur - l + skipBeginning
|
||||
s2 := s + skipBeginning
|
||||
off := s2 - t2
|
||||
if t2 >= 0 && off < maxMatchOffset && off > 0 {
|
||||
if l2 := e.matchlenLong(int(s2), int(t2), src); l2 > l {
|
||||
t = t2
|
||||
l = l2
|
||||
s = s2
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// Extend backwards
|
||||
for t > 0 && s > nextEmit && src[t-1] == src[s-1] {
|
||||
s--
|
||||
t--
|
||||
l++
|
||||
}
|
||||
if nextEmit < s {
|
||||
if false {
|
||||
emitLiteral(dst, src[nextEmit:s])
|
||||
} else {
|
||||
for _, v := range src[nextEmit:s] {
|
||||
dst.tokens[dst.n] = token(v)
|
||||
dst.litHist[v]++
|
||||
dst.n++
|
||||
}
|
||||
}
|
||||
}
|
||||
if debugDeflate {
|
||||
if t >= s {
|
||||
panic(fmt.Sprintln("s-t", s, t))
|
||||
}
|
||||
if (s - t) > maxMatchOffset {
|
||||
panic(fmt.Sprintln("mmo", s-t))
|
||||
}
|
||||
if l < baseMatchLength {
|
||||
panic("bml")
|
||||
}
|
||||
}
|
||||
|
||||
dst.AddMatchLong(l, uint32(s-t-baseMatchOffset))
|
||||
s += l
|
||||
nextEmit = s
|
||||
if nextS >= s {
|
||||
s = nextS + 1
|
||||
}
|
||||
|
||||
if s >= sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
// Store every 3rd hash in-between.
|
||||
if true {
|
||||
const hashEvery = 3
|
||||
i := s - l + 1
|
||||
if i < s-1 {
|
||||
cv := load6432(src, i)
|
||||
t := tableEntry{offset: i + e.cur}
|
||||
e.table[hashLen(cv, tableBits, hashShortBytes)] = t
|
||||
eLong := &e.bTable[hash7(cv, tableBits)]
|
||||
eLong.Cur, eLong.Prev = t, eLong.Cur
|
||||
|
||||
// Do an long at i+1
|
||||
cv >>= 8
|
||||
t = tableEntry{offset: t.offset + 1}
|
||||
eLong = &e.bTable[hash7(cv, tableBits)]
|
||||
eLong.Cur, eLong.Prev = t, eLong.Cur
|
||||
|
||||
// We only have enough bits for a short entry at i+2
|
||||
cv >>= 8
|
||||
t = tableEntry{offset: t.offset + 1}
|
||||
e.table[hashLen(cv, tableBits, hashShortBytes)] = t
|
||||
|
||||
// Skip one - otherwise we risk hitting 's'
|
||||
i += 4
|
||||
for ; i < s-1; i += hashEvery {
|
||||
cv := load6432(src, i)
|
||||
t := tableEntry{offset: i + e.cur}
|
||||
t2 := tableEntry{offset: t.offset + 1}
|
||||
eLong := &e.bTable[hash7(cv, tableBits)]
|
||||
eLong.Cur, eLong.Prev = t, eLong.Cur
|
||||
e.table[hashLen(cv>>8, tableBits, hashShortBytes)] = t2
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// We could immediately start working at s now, but to improve
|
||||
// compression we first update the hash table at s-1 and at s.
|
||||
x := load6432(src, s-1)
|
||||
o := e.cur + s - 1
|
||||
prevHashS := hashLen(x, tableBits, hashShortBytes)
|
||||
prevHashL := hash7(x, tableBits)
|
||||
e.table[prevHashS] = tableEntry{offset: o}
|
||||
eLong := &e.bTable[prevHashL]
|
||||
eLong.Cur, eLong.Prev = tableEntry{offset: o}, eLong.Cur
|
||||
cv = x >> 8
|
||||
}
|
||||
|
||||
emitRemainder:
|
||||
if int(nextEmit) < len(src) {
|
||||
// If nothing was added, don't encode literals.
|
||||
if dst.n == 0 {
|
||||
return
|
||||
}
|
||||
|
||||
emitLiteral(dst, src[nextEmit:])
|
||||
}
|
||||
}
|
||||
|
||||
// fastEncL5Window is a level 5 encoder,
|
||||
// but with a custom window size.
|
||||
type fastEncL5Window struct {
|
||||
hist []byte
|
||||
cur int32
|
||||
maxOffset int32
|
||||
table [tableSize]tableEntry
|
||||
bTable [tableSize]tableEntryPrev
|
||||
}
|
||||
|
||||
func (e *fastEncL5Window) Encode(dst *tokens, src []byte) {
|
||||
const (
|
||||
inputMargin = 12 - 1
|
||||
minNonLiteralBlockSize = 1 + 1 + inputMargin
|
||||
hashShortBytes = 4
|
||||
)
|
||||
maxMatchOffset := e.maxOffset
|
||||
if debugDeflate && e.cur < 0 {
|
||||
panic(fmt.Sprint("e.cur < 0: ", e.cur))
|
||||
}
|
||||
|
||||
// Protect against e.cur wraparound.
|
||||
for e.cur >= bufferReset {
|
||||
if len(e.hist) == 0 {
|
||||
for i := range e.table[:] {
|
||||
e.table[i] = tableEntry{}
|
||||
}
|
||||
for i := range e.bTable[:] {
|
||||
e.bTable[i] = tableEntryPrev{}
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
break
|
||||
}
|
||||
// Shift down everything in the table that isn't already too far away.
|
||||
minOff := e.cur + int32(len(e.hist)) - maxMatchOffset
|
||||
for i := range e.table[:] {
|
||||
v := e.table[i].offset
|
||||
if v <= minOff {
|
||||
v = 0
|
||||
} else {
|
||||
v = v - e.cur + maxMatchOffset
|
||||
}
|
||||
e.table[i].offset = v
|
||||
}
|
||||
for i := range e.bTable[:] {
|
||||
v := e.bTable[i]
|
||||
if v.Cur.offset <= minOff {
|
||||
v.Cur.offset = 0
|
||||
v.Prev.offset = 0
|
||||
} else {
|
||||
v.Cur.offset = v.Cur.offset - e.cur + maxMatchOffset
|
||||
if v.Prev.offset <= minOff {
|
||||
v.Prev.offset = 0
|
||||
} else {
|
||||
v.Prev.offset = v.Prev.offset - e.cur + maxMatchOffset
|
||||
}
|
||||
}
|
||||
e.bTable[i] = v
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
}
|
||||
|
||||
s := e.addBlock(src)
|
||||
|
||||
// This check isn't in the Snappy implementation, but there, the caller
|
||||
// instead of the callee handles this case.
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
// We do not fill the token table.
|
||||
// This will be picked up by caller.
|
||||
dst.n = uint16(len(src))
|
||||
return
|
||||
}
|
||||
|
||||
// Override src
|
||||
src = e.hist
|
||||
nextEmit := s
|
||||
|
||||
// sLimit is when to stop looking for offset/length copies. The inputMargin
|
||||
// lets us use a fast path for emitLiteral in the main loop, while we are
|
||||
// looking for copies.
|
||||
sLimit := int32(len(src) - inputMargin)
|
||||
|
||||
// nextEmit is where in src the next emitLiteral should start from.
|
||||
cv := load6432(src, s)
|
||||
for {
|
||||
const skipLog = 6
|
||||
const doEvery = 1
|
||||
|
||||
nextS := s
|
||||
var l int32
|
||||
var t int32
|
||||
for {
|
||||
nextHashS := hashLen(cv, tableBits, hashShortBytes)
|
||||
nextHashL := hash7(cv, tableBits)
|
||||
|
||||
s = nextS
|
||||
nextS = s + doEvery + (s-nextEmit)>>skipLog
|
||||
if nextS > sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
// Fetch a short+long candidate
|
||||
sCandidate := e.table[nextHashS]
|
||||
lCandidate := e.bTable[nextHashL]
|
||||
next := load6432(src, nextS)
|
||||
entry := tableEntry{offset: s + e.cur}
|
||||
e.table[nextHashS] = entry
|
||||
eLong := &e.bTable[nextHashL]
|
||||
eLong.Cur, eLong.Prev = entry, eLong.Cur
|
||||
|
||||
nextHashS = hashLen(next, tableBits, hashShortBytes)
|
||||
nextHashL = hash7(next, tableBits)
|
||||
|
||||
t = lCandidate.Cur.offset - e.cur
|
||||
if s-t < maxMatchOffset {
|
||||
if uint32(cv) == load3232(src, t) {
|
||||
// Store the next match
|
||||
e.table[nextHashS] = tableEntry{offset: nextS + e.cur}
|
||||
eLong := &e.bTable[nextHashL]
|
||||
eLong.Cur, eLong.Prev = tableEntry{offset: nextS + e.cur}, eLong.Cur
|
||||
|
||||
t2 := lCandidate.Prev.offset - e.cur
|
||||
if s-t2 < maxMatchOffset && uint32(cv) == load3232(src, t2) {
|
||||
l = e.matchlen(s+4, t+4, src) + 4
|
||||
ml1 := e.matchlen(s+4, t2+4, src) + 4
|
||||
if ml1 > l {
|
||||
t = t2
|
||||
l = ml1
|
||||
break
|
||||
}
|
||||
}
|
||||
break
|
||||
}
|
||||
t = lCandidate.Prev.offset - e.cur
|
||||
if s-t < maxMatchOffset && uint32(cv) == load3232(src, t) {
|
||||
// Store the next match
|
||||
e.table[nextHashS] = tableEntry{offset: nextS + e.cur}
|
||||
eLong := &e.bTable[nextHashL]
|
||||
eLong.Cur, eLong.Prev = tableEntry{offset: nextS + e.cur}, eLong.Cur
|
||||
break
|
||||
}
|
||||
}
|
||||
|
||||
t = sCandidate.offset - e.cur
|
||||
if s-t < maxMatchOffset && uint32(cv) == load3232(src, t) {
|
||||
// Found a 4 match...
|
||||
l = e.matchlen(s+4, t+4, src) + 4
|
||||
lCandidate = e.bTable[nextHashL]
|
||||
// Store the next match
|
||||
|
||||
e.table[nextHashS] = tableEntry{offset: nextS + e.cur}
|
||||
eLong := &e.bTable[nextHashL]
|
||||
eLong.Cur, eLong.Prev = tableEntry{offset: nextS + e.cur}, eLong.Cur
|
||||
|
||||
// If the next long is a candidate, use that...
|
||||
t2 := lCandidate.Cur.offset - e.cur
|
||||
if nextS-t2 < maxMatchOffset {
|
||||
if load3232(src, t2) == uint32(next) {
|
||||
ml := e.matchlen(nextS+4, t2+4, src) + 4
|
||||
if ml > l {
|
||||
t = t2
|
||||
s = nextS
|
||||
l = ml
|
||||
break
|
||||
}
|
||||
}
|
||||
// If the previous long is a candidate, use that...
|
||||
t2 = lCandidate.Prev.offset - e.cur
|
||||
if nextS-t2 < maxMatchOffset && load3232(src, t2) == uint32(next) {
|
||||
ml := e.matchlen(nextS+4, t2+4, src) + 4
|
||||
if ml > l {
|
||||
t = t2
|
||||
s = nextS
|
||||
l = ml
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
break
|
||||
}
|
||||
cv = next
|
||||
}
|
||||
|
||||
// A 4-byte match has been found. We'll later see if more than 4 bytes
|
||||
// match. But, prior to the match, src[nextEmit:s] are unmatched. Emit
|
||||
// them as literal bytes.
|
||||
|
||||
if l == 0 {
|
||||
// Extend the 4-byte match as long as possible.
|
||||
l = e.matchlenLong(s+4, t+4, src) + 4
|
||||
} else if l == maxMatchLength {
|
||||
l += e.matchlenLong(s+l, t+l, src)
|
||||
}
|
||||
|
||||
// Try to locate a better match by checking the end of best match...
|
||||
if sAt := s + l; l < 30 && sAt < sLimit {
|
||||
// Allow some bytes at the beginning to mismatch.
|
||||
// Sweet spot is 2/3 bytes depending on input.
|
||||
// 3 is only a little better when it is but sometimes a lot worse.
|
||||
// The skipped bytes are tested in Extend backwards,
|
||||
// and still picked up as part of the match if they do.
|
||||
const skipBeginning = 2
|
||||
eLong := e.bTable[hash7(load6432(src, sAt), tableBits)].Cur.offset
|
||||
t2 := eLong - e.cur - l + skipBeginning
|
||||
s2 := s + skipBeginning
|
||||
off := s2 - t2
|
||||
if t2 >= 0 && off < maxMatchOffset && off > 0 {
|
||||
if l2 := e.matchlenLong(s2, t2, src); l2 > l {
|
||||
t = t2
|
||||
l = l2
|
||||
s = s2
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// Extend backwards
|
||||
for t > 0 && s > nextEmit && src[t-1] == src[s-1] {
|
||||
s--
|
||||
t--
|
||||
l++
|
||||
}
|
||||
if nextEmit < s {
|
||||
if false {
|
||||
emitLiteral(dst, src[nextEmit:s])
|
||||
} else {
|
||||
for _, v := range src[nextEmit:s] {
|
||||
dst.tokens[dst.n] = token(v)
|
||||
dst.litHist[v]++
|
||||
dst.n++
|
||||
}
|
||||
}
|
||||
}
|
||||
if debugDeflate {
|
||||
if t >= s {
|
||||
panic(fmt.Sprintln("s-t", s, t))
|
||||
}
|
||||
if (s - t) > maxMatchOffset {
|
||||
panic(fmt.Sprintln("mmo", s-t))
|
||||
}
|
||||
if l < baseMatchLength {
|
||||
panic("bml")
|
||||
}
|
||||
}
|
||||
|
||||
dst.AddMatchLong(l, uint32(s-t-baseMatchOffset))
|
||||
s += l
|
||||
nextEmit = s
|
||||
if nextS >= s {
|
||||
s = nextS + 1
|
||||
}
|
||||
|
||||
if s >= sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
// Store every 3rd hash in-between.
|
||||
if true {
|
||||
const hashEvery = 3
|
||||
i := s - l + 1
|
||||
if i < s-1 {
|
||||
cv := load6432(src, i)
|
||||
t := tableEntry{offset: i + e.cur}
|
||||
e.table[hashLen(cv, tableBits, hashShortBytes)] = t
|
||||
eLong := &e.bTable[hash7(cv, tableBits)]
|
||||
eLong.Cur, eLong.Prev = t, eLong.Cur
|
||||
|
||||
// Do an long at i+1
|
||||
cv >>= 8
|
||||
t = tableEntry{offset: t.offset + 1}
|
||||
eLong = &e.bTable[hash7(cv, tableBits)]
|
||||
eLong.Cur, eLong.Prev = t, eLong.Cur
|
||||
|
||||
// We only have enough bits for a short entry at i+2
|
||||
cv >>= 8
|
||||
t = tableEntry{offset: t.offset + 1}
|
||||
e.table[hashLen(cv, tableBits, hashShortBytes)] = t
|
||||
|
||||
// Skip one - otherwise we risk hitting 's'
|
||||
i += 4
|
||||
for ; i < s-1; i += hashEvery {
|
||||
cv := load6432(src, i)
|
||||
t := tableEntry{offset: i + e.cur}
|
||||
t2 := tableEntry{offset: t.offset + 1}
|
||||
eLong := &e.bTable[hash7(cv, tableBits)]
|
||||
eLong.Cur, eLong.Prev = t, eLong.Cur
|
||||
e.table[hashLen(cv>>8, tableBits, hashShortBytes)] = t2
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// We could immediately start working at s now, but to improve
|
||||
// compression we first update the hash table at s-1 and at s.
|
||||
x := load6432(src, s-1)
|
||||
o := e.cur + s - 1
|
||||
prevHashS := hashLen(x, tableBits, hashShortBytes)
|
||||
prevHashL := hash7(x, tableBits)
|
||||
e.table[prevHashS] = tableEntry{offset: o}
|
||||
eLong := &e.bTable[prevHashL]
|
||||
eLong.Cur, eLong.Prev = tableEntry{offset: o}, eLong.Cur
|
||||
cv = x >> 8
|
||||
}
|
||||
|
||||
emitRemainder:
|
||||
if int(nextEmit) < len(src) {
|
||||
// If nothing was added, don't encode literals.
|
||||
if dst.n == 0 {
|
||||
return
|
||||
}
|
||||
|
||||
emitLiteral(dst, src[nextEmit:])
|
||||
}
|
||||
}
|
||||
|
||||
// Reset the encoding table.
|
||||
func (e *fastEncL5Window) Reset() {
|
||||
// We keep the same allocs, since we are compressing the same block sizes.
|
||||
if cap(e.hist) < allocHistory {
|
||||
e.hist = make([]byte, 0, allocHistory)
|
||||
}
|
||||
|
||||
// We offset current position so everything will be out of reach.
|
||||
// If we are above the buffer reset it will be cleared anyway since len(hist) == 0.
|
||||
if e.cur <= int32(bufferReset) {
|
||||
e.cur += e.maxOffset + int32(len(e.hist))
|
||||
}
|
||||
e.hist = e.hist[:0]
|
||||
}
|
||||
|
||||
func (e *fastEncL5Window) addBlock(src []byte) int32 {
|
||||
// check if we have space already
|
||||
maxMatchOffset := e.maxOffset
|
||||
|
||||
if len(e.hist)+len(src) > cap(e.hist) {
|
||||
if cap(e.hist) == 0 {
|
||||
e.hist = make([]byte, 0, allocHistory)
|
||||
} else {
|
||||
if cap(e.hist) < int(maxMatchOffset*2) {
|
||||
panic("unexpected buffer size")
|
||||
}
|
||||
// Move down
|
||||
offset := int32(len(e.hist)) - maxMatchOffset
|
||||
copy(e.hist[0:maxMatchOffset], e.hist[offset:])
|
||||
e.cur += offset
|
||||
e.hist = e.hist[:maxMatchOffset]
|
||||
}
|
||||
}
|
||||
s := int32(len(e.hist))
|
||||
e.hist = append(e.hist, src...)
|
||||
return s
|
||||
}
|
||||
|
||||
// matchlen will return the match length between offsets and t in src.
|
||||
// The maximum length returned is maxMatchLength - 4.
|
||||
// It is assumed that s > t, that t >=0 and s < len(src).
|
||||
func (e *fastEncL5Window) matchlen(s, t int32, src []byte) int32 {
|
||||
if debugDecode {
|
||||
if t >= s {
|
||||
panic(fmt.Sprint("t >=s:", t, s))
|
||||
}
|
||||
if int(s) >= len(src) {
|
||||
panic(fmt.Sprint("s >= len(src):", s, len(src)))
|
||||
}
|
||||
if t < 0 {
|
||||
panic(fmt.Sprint("t < 0:", t))
|
||||
}
|
||||
if s-t > e.maxOffset {
|
||||
panic(fmt.Sprint(s, "-", t, "(", s-t, ") > maxMatchLength (", maxMatchOffset, ")"))
|
||||
}
|
||||
}
|
||||
s1 := min(int(s)+maxMatchLength-4, len(src))
|
||||
|
||||
// Extend the match to be as long as possible.
|
||||
return int32(matchLen(src[s:s1], src[t:]))
|
||||
}
|
||||
|
||||
// matchlenLong will return the match length between offsets and t in src.
|
||||
// It is assumed that s > t, that t >=0 and s < len(src).
|
||||
func (e *fastEncL5Window) matchlenLong(s, t int32, src []byte) int32 {
|
||||
if debugDeflate {
|
||||
if t >= s {
|
||||
panic(fmt.Sprint("t >=s:", t, s))
|
||||
}
|
||||
if int(s) >= len(src) {
|
||||
panic(fmt.Sprint("s >= len(src):", s, len(src)))
|
||||
}
|
||||
if t < 0 {
|
||||
panic(fmt.Sprint("t < 0:", t))
|
||||
}
|
||||
if s-t > e.maxOffset {
|
||||
panic(fmt.Sprint(s, "-", t, "(", s-t, ") > maxMatchLength (", maxMatchOffset, ")"))
|
||||
}
|
||||
}
|
||||
// Extend the match to be as long as possible.
|
||||
return int32(matchLen(src[s:], src[t:]))
|
||||
}
|
||||
Generated
Vendored
-325
@@ -1,325 +0,0 @@
|
||||
package flate
|
||||
|
||||
import "fmt"
|
||||
|
||||
type fastEncL6 struct {
|
||||
fastGen
|
||||
table [tableSize]tableEntry
|
||||
bTable [tableSize]tableEntryPrev
|
||||
}
|
||||
|
||||
func (e *fastEncL6) Encode(dst *tokens, src []byte) {
|
||||
const (
|
||||
inputMargin = 12 - 1
|
||||
minNonLiteralBlockSize = 1 + 1 + inputMargin
|
||||
hashShortBytes = 4
|
||||
)
|
||||
if debugDeflate && e.cur < 0 {
|
||||
panic(fmt.Sprint("e.cur < 0: ", e.cur))
|
||||
}
|
||||
|
||||
// Protect against e.cur wraparound.
|
||||
for e.cur >= bufferReset {
|
||||
if len(e.hist) == 0 {
|
||||
for i := range e.table[:] {
|
||||
e.table[i] = tableEntry{}
|
||||
}
|
||||
for i := range e.bTable[:] {
|
||||
e.bTable[i] = tableEntryPrev{}
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
break
|
||||
}
|
||||
// Shift down everything in the table that isn't already too far away.
|
||||
minOff := e.cur + int32(len(e.hist)) - maxMatchOffset
|
||||
for i := range e.table[:] {
|
||||
v := e.table[i].offset
|
||||
if v <= minOff {
|
||||
v = 0
|
||||
} else {
|
||||
v = v - e.cur + maxMatchOffset
|
||||
}
|
||||
e.table[i].offset = v
|
||||
}
|
||||
for i := range e.bTable[:] {
|
||||
v := e.bTable[i]
|
||||
if v.Cur.offset <= minOff {
|
||||
v.Cur.offset = 0
|
||||
v.Prev.offset = 0
|
||||
} else {
|
||||
v.Cur.offset = v.Cur.offset - e.cur + maxMatchOffset
|
||||
if v.Prev.offset <= minOff {
|
||||
v.Prev.offset = 0
|
||||
} else {
|
||||
v.Prev.offset = v.Prev.offset - e.cur + maxMatchOffset
|
||||
}
|
||||
}
|
||||
e.bTable[i] = v
|
||||
}
|
||||
e.cur = maxMatchOffset
|
||||
}
|
||||
|
||||
s := e.addBlock(src)
|
||||
|
||||
// This check isn't in the Snappy implementation, but there, the caller
|
||||
// instead of the callee handles this case.
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
// We do not fill the token table.
|
||||
// This will be picked up by caller.
|
||||
dst.n = uint16(len(src))
|
||||
return
|
||||
}
|
||||
|
||||
// Override src
|
||||
src = e.hist
|
||||
nextEmit := s
|
||||
|
||||
// sLimit is when to stop looking for offset/length copies. The inputMargin
|
||||
// lets us use a fast path for emitLiteral in the main loop, while we are
|
||||
// looking for copies.
|
||||
sLimit := int32(len(src) - inputMargin)
|
||||
|
||||
// nextEmit is where in src the next emitLiteral should start from.
|
||||
cv := load6432(src, s)
|
||||
// Repeat MUST be > 1 and within range
|
||||
repeat := int32(1)
|
||||
for {
|
||||
const skipLog = 7
|
||||
const doEvery = 1
|
||||
|
||||
nextS := s
|
||||
var l int32
|
||||
var t int32
|
||||
for {
|
||||
nextHashS := hashLen(cv, tableBits, hashShortBytes)
|
||||
nextHashL := hash7(cv, tableBits)
|
||||
s = nextS
|
||||
nextS = s + doEvery + (s-nextEmit)>>skipLog
|
||||
if nextS > sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
// Fetch a short+long candidate
|
||||
sCandidate := e.table[nextHashS]
|
||||
lCandidate := e.bTable[nextHashL]
|
||||
next := load6432(src, nextS)
|
||||
entry := tableEntry{offset: s + e.cur}
|
||||
e.table[nextHashS] = entry
|
||||
eLong := &e.bTable[nextHashL]
|
||||
eLong.Cur, eLong.Prev = entry, eLong.Cur
|
||||
|
||||
// Calculate hashes of 'next'
|
||||
nextHashS = hashLen(next, tableBits, hashShortBytes)
|
||||
nextHashL = hash7(next, tableBits)
|
||||
|
||||
t = lCandidate.Cur.offset - e.cur
|
||||
if s-t < maxMatchOffset {
|
||||
if uint32(cv) == load3232(src, t) {
|
||||
// Long candidate matches at least 4 bytes.
|
||||
|
||||
// Store the next match
|
||||
e.table[nextHashS] = tableEntry{offset: nextS + e.cur}
|
||||
eLong := &e.bTable[nextHashL]
|
||||
eLong.Cur, eLong.Prev = tableEntry{offset: nextS + e.cur}, eLong.Cur
|
||||
|
||||
// Check the previous long candidate as well.
|
||||
t2 := lCandidate.Prev.offset - e.cur
|
||||
if s-t2 < maxMatchOffset && uint32(cv) == load3232(src, t2) {
|
||||
l = e.matchlen(int(s+4), int(t+4), src) + 4
|
||||
ml1 := e.matchlen(int(s+4), int(t2+4), src) + 4
|
||||
if ml1 > l {
|
||||
t = t2
|
||||
l = ml1
|
||||
break
|
||||
}
|
||||
}
|
||||
break
|
||||
}
|
||||
// Current value did not match, but check if previous long value does.
|
||||
t = lCandidate.Prev.offset - e.cur
|
||||
if s-t < maxMatchOffset && uint32(cv) == load3232(src, t) {
|
||||
// Store the next match
|
||||
e.table[nextHashS] = tableEntry{offset: nextS + e.cur}
|
||||
eLong := &e.bTable[nextHashL]
|
||||
eLong.Cur, eLong.Prev = tableEntry{offset: nextS + e.cur}, eLong.Cur
|
||||
break
|
||||
}
|
||||
}
|
||||
|
||||
t = sCandidate.offset - e.cur
|
||||
if s-t < maxMatchOffset && uint32(cv) == load3232(src, t) {
|
||||
// Found a 4 match...
|
||||
l = e.matchlen(int(s+4), int(t+4), src) + 4
|
||||
|
||||
// Look up next long candidate (at nextS)
|
||||
lCandidate = e.bTable[nextHashL]
|
||||
|
||||
// Store the next match
|
||||
e.table[nextHashS] = tableEntry{offset: nextS + e.cur}
|
||||
eLong := &e.bTable[nextHashL]
|
||||
eLong.Cur, eLong.Prev = tableEntry{offset: nextS + e.cur}, eLong.Cur
|
||||
|
||||
// Check repeat at s + repOff
|
||||
const repOff = 1
|
||||
t2 := s - repeat + repOff
|
||||
if load3232(src, t2) == uint32(cv>>(8*repOff)) {
|
||||
ml := e.matchlen(int(s+4+repOff), int(t2+4), src) + 4
|
||||
if ml > l {
|
||||
t = t2
|
||||
l = ml
|
||||
s += repOff
|
||||
// Not worth checking more.
|
||||
break
|
||||
}
|
||||
}
|
||||
|
||||
// If the next long is a candidate, use that...
|
||||
t2 = lCandidate.Cur.offset - e.cur
|
||||
if nextS-t2 < maxMatchOffset {
|
||||
if load3232(src, t2) == uint32(next) {
|
||||
ml := e.matchlen(int(nextS+4), int(t2+4), src) + 4
|
||||
if ml > l {
|
||||
t = t2
|
||||
s = nextS
|
||||
l = ml
|
||||
// This is ok, but check previous as well.
|
||||
}
|
||||
}
|
||||
// If the previous long is a candidate, use that...
|
||||
t2 = lCandidate.Prev.offset - e.cur
|
||||
if nextS-t2 < maxMatchOffset && load3232(src, t2) == uint32(next) {
|
||||
ml := e.matchlen(int(nextS+4), int(t2+4), src) + 4
|
||||
if ml > l {
|
||||
t = t2
|
||||
s = nextS
|
||||
l = ml
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
break
|
||||
}
|
||||
cv = next
|
||||
}
|
||||
|
||||
// A 4-byte match has been found. We'll later see if more than 4 bytes
|
||||
// match. But, prior to the match, src[nextEmit:s] are unmatched. Emit
|
||||
// them as literal bytes.
|
||||
|
||||
// Extend the 4-byte match as long as possible.
|
||||
if l == 0 {
|
||||
l = e.matchlenLong(int(s+4), int(t+4), src) + 4
|
||||
} else if l == maxMatchLength {
|
||||
l += e.matchlenLong(int(s+l), int(t+l), src)
|
||||
}
|
||||
|
||||
// Try to locate a better match by checking the end-of-match...
|
||||
if sAt := s + l; sAt < sLimit {
|
||||
// Allow some bytes at the beginning to mismatch.
|
||||
// Sweet spot is 2/3 bytes depending on input.
|
||||
// 3 is only a little better when it is but sometimes a lot worse.
|
||||
// The skipped bytes are tested in Extend backwards,
|
||||
// and still picked up as part of the match if they do.
|
||||
const skipBeginning = 2
|
||||
eLong := &e.bTable[hash7(load6432(src, sAt), tableBits)]
|
||||
// Test current
|
||||
t2 := eLong.Cur.offset - e.cur - l + skipBeginning
|
||||
s2 := s + skipBeginning
|
||||
off := s2 - t2
|
||||
if off < maxMatchOffset {
|
||||
if off > 0 && t2 >= 0 {
|
||||
if l2 := e.matchlenLong(int(s2), int(t2), src); l2 > l {
|
||||
t = t2
|
||||
l = l2
|
||||
s = s2
|
||||
}
|
||||
}
|
||||
// Test next:
|
||||
t2 = eLong.Prev.offset - e.cur - l + skipBeginning
|
||||
off := s2 - t2
|
||||
if off > 0 && off < maxMatchOffset && t2 >= 0 {
|
||||
if l2 := e.matchlenLong(int(s2), int(t2), src); l2 > l {
|
||||
t = t2
|
||||
l = l2
|
||||
s = s2
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// Extend backwards
|
||||
for t > 0 && s > nextEmit && src[t-1] == src[s-1] {
|
||||
s--
|
||||
t--
|
||||
l++
|
||||
}
|
||||
if nextEmit < s {
|
||||
if false {
|
||||
emitLiteral(dst, src[nextEmit:s])
|
||||
} else {
|
||||
for _, v := range src[nextEmit:s] {
|
||||
dst.tokens[dst.n] = token(v)
|
||||
dst.litHist[v]++
|
||||
dst.n++
|
||||
}
|
||||
}
|
||||
}
|
||||
if false {
|
||||
if t >= s {
|
||||
panic(fmt.Sprintln("s-t", s, t))
|
||||
}
|
||||
if (s - t) > maxMatchOffset {
|
||||
panic(fmt.Sprintln("mmo", s-t))
|
||||
}
|
||||
if l < baseMatchLength {
|
||||
panic("bml")
|
||||
}
|
||||
}
|
||||
|
||||
dst.AddMatchLong(l, uint32(s-t-baseMatchOffset))
|
||||
repeat = s - t
|
||||
s += l
|
||||
nextEmit = s
|
||||
if nextS >= s {
|
||||
s = nextS + 1
|
||||
}
|
||||
|
||||
if s >= sLimit {
|
||||
// Index after match end.
|
||||
for i := nextS + 1; i < int32(len(src))-8; i += 2 {
|
||||
cv := load6432(src, i)
|
||||
e.table[hashLen(cv, tableBits, hashShortBytes)] = tableEntry{offset: i + e.cur}
|
||||
eLong := &e.bTable[hash7(cv, tableBits)]
|
||||
eLong.Cur, eLong.Prev = tableEntry{offset: i + e.cur}, eLong.Cur
|
||||
}
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
// Store every long hash in-between and every second short.
|
||||
if true {
|
||||
for i := nextS + 1; i < s-1; i += 2 {
|
||||
cv := load6432(src, i)
|
||||
t := tableEntry{offset: i + e.cur}
|
||||
t2 := tableEntry{offset: t.offset + 1}
|
||||
eLong := &e.bTable[hash7(cv, tableBits)]
|
||||
eLong2 := &e.bTable[hash7(cv>>8, tableBits)]
|
||||
e.table[hashLen(cv, tableBits, hashShortBytes)] = t
|
||||
eLong.Cur, eLong.Prev = t, eLong.Cur
|
||||
eLong2.Cur, eLong2.Prev = t2, eLong2.Cur
|
||||
}
|
||||
}
|
||||
|
||||
// We could immediately start working at s now, but to improve
|
||||
// compression we first update the hash table at s-1 and at s.
|
||||
cv = load6432(src, s)
|
||||
}
|
||||
|
||||
emitRemainder:
|
||||
if int(nextEmit) < len(src) {
|
||||
// If nothing was added, don't encode literals.
|
||||
if dst.n == 0 {
|
||||
return
|
||||
}
|
||||
|
||||
emitLiteral(dst, src[nextEmit:])
|
||||
}
|
||||
}
|
||||
Generated
Vendored
-34
@@ -1,34 +0,0 @@
|
||||
// Copyright 2019+ Klaus Post. All rights reserved.
|
||||
// License information can be found in the LICENSE file.
|
||||
|
||||
package flate
|
||||
|
||||
import (
|
||||
"math/bits"
|
||||
|
||||
"github.com/klauspost/compress/internal/le"
|
||||
)
|
||||
|
||||
// matchLen returns the maximum common prefix length of a and b.
|
||||
// a must be the shortest of the two.
|
||||
func matchLen(a, b []byte) (n int) {
|
||||
left := len(a)
|
||||
for left >= 8 {
|
||||
diff := le.Load64(a, n) ^ le.Load64(b, n)
|
||||
if diff != 0 {
|
||||
return n + bits.TrailingZeros64(diff)>>3
|
||||
}
|
||||
n += 8
|
||||
left -= 8
|
||||
}
|
||||
|
||||
a = a[n:]
|
||||
b = b[n:]
|
||||
for i := range a {
|
||||
if a[i] != b[i] {
|
||||
break
|
||||
}
|
||||
n++
|
||||
}
|
||||
return n
|
||||
}
|
||||
Generated
Vendored
-325
@@ -1,325 +0,0 @@
|
||||
package flate
|
||||
|
||||
import (
|
||||
"io"
|
||||
"math"
|
||||
"sync"
|
||||
|
||||
"github.com/klauspost/compress/internal/le"
|
||||
)
|
||||
|
||||
const (
|
||||
maxStatelessBlock = math.MaxInt16
|
||||
// dictionary will be taken from maxStatelessBlock, so limit it.
|
||||
maxStatelessDict = 8 << 10
|
||||
|
||||
slTableBits = 13
|
||||
slTableSize = 1 << slTableBits
|
||||
slTableShift = 32 - slTableBits
|
||||
)
|
||||
|
||||
type statelessWriter struct {
|
||||
dst io.Writer
|
||||
closed bool
|
||||
}
|
||||
|
||||
func (s *statelessWriter) Close() error {
|
||||
if s.closed {
|
||||
return nil
|
||||
}
|
||||
s.closed = true
|
||||
// Emit EOF block
|
||||
return StatelessDeflate(s.dst, nil, true, nil)
|
||||
}
|
||||
|
||||
func (s *statelessWriter) Write(p []byte) (n int, err error) {
|
||||
err = StatelessDeflate(s.dst, p, false, nil)
|
||||
if err != nil {
|
||||
return 0, err
|
||||
}
|
||||
return len(p), nil
|
||||
}
|
||||
|
||||
func (s *statelessWriter) Reset(w io.Writer) {
|
||||
s.dst = w
|
||||
s.closed = false
|
||||
}
|
||||
|
||||
// NewStatelessWriter will do compression but without maintaining any state
|
||||
// between Write calls.
|
||||
// There will be no memory kept between Write calls,
|
||||
// but compression and speed will be suboptimal.
|
||||
// Because of this, the size of actual Write calls will affect output size.
|
||||
func NewStatelessWriter(dst io.Writer) io.WriteCloser {
|
||||
return &statelessWriter{dst: dst}
|
||||
}
|
||||
|
||||
// bitWriterPool contains bit writers that can be reused.
|
||||
var bitWriterPool = sync.Pool{
|
||||
New: func() any {
|
||||
return newHuffmanBitWriter(nil)
|
||||
},
|
||||
}
|
||||
|
||||
// tokensPool contains tokens struct objects that can be reused
|
||||
var tokensPool = sync.Pool{
|
||||
New: func() any {
|
||||
return &tokens{}
|
||||
},
|
||||
}
|
||||
|
||||
// StatelessDeflate allows compressing directly to a Writer without retaining state.
|
||||
// When returning everything will be flushed.
|
||||
// Up to 8KB of an optional dictionary can be given which is presumed to precede the block.
|
||||
// Longer dictionaries will be truncated and will still produce valid output.
|
||||
// Sending nil dictionary is perfectly fine.
|
||||
func StatelessDeflate(out io.Writer, in []byte, eof bool, dict []byte) error {
|
||||
bw := bitWriterPool.Get().(*huffmanBitWriter)
|
||||
bw.reset(out)
|
||||
defer func() {
|
||||
// don't keep a reference to our output
|
||||
bw.reset(nil)
|
||||
bitWriterPool.Put(bw)
|
||||
}()
|
||||
if eof && len(in) == 0 {
|
||||
// Just write an EOF block.
|
||||
// Could be faster...
|
||||
bw.writeStoredHeader(0, true)
|
||||
bw.flush()
|
||||
return bw.err
|
||||
}
|
||||
|
||||
// Truncate dict
|
||||
if len(dict) > maxStatelessDict {
|
||||
dict = dict[len(dict)-maxStatelessDict:]
|
||||
}
|
||||
|
||||
// For subsequent loops, keep shallow dict reference to avoid alloc+copy.
|
||||
var inDict []byte
|
||||
|
||||
dst := tokensPool.Get().(*tokens)
|
||||
dst.Reset()
|
||||
defer func() {
|
||||
tokensPool.Put(dst)
|
||||
}()
|
||||
|
||||
for len(in) > 0 {
|
||||
todo := in
|
||||
if len(inDict) > 0 {
|
||||
if len(todo) > maxStatelessBlock-maxStatelessDict {
|
||||
todo = todo[:maxStatelessBlock-maxStatelessDict]
|
||||
}
|
||||
} else if len(todo) > maxStatelessBlock-len(dict) {
|
||||
todo = todo[:maxStatelessBlock-len(dict)]
|
||||
}
|
||||
inOrg := in
|
||||
in = in[len(todo):]
|
||||
uncompressed := todo
|
||||
if len(dict) > 0 {
|
||||
// combine dict and source
|
||||
bufLen := len(todo) + len(dict)
|
||||
combined := make([]byte, bufLen)
|
||||
copy(combined, dict)
|
||||
copy(combined[len(dict):], todo)
|
||||
todo = combined
|
||||
}
|
||||
// Compress
|
||||
if len(inDict) == 0 {
|
||||
statelessEnc(dst, todo, int16(len(dict)))
|
||||
} else {
|
||||
statelessEnc(dst, inDict[:maxStatelessDict+len(todo)], maxStatelessDict)
|
||||
}
|
||||
isEof := eof && len(in) == 0
|
||||
|
||||
if dst.n == 0 {
|
||||
bw.writeStoredHeader(len(uncompressed), isEof)
|
||||
if bw.err != nil {
|
||||
return bw.err
|
||||
}
|
||||
bw.writeBytes(uncompressed)
|
||||
} else if int(dst.n) > len(uncompressed)-len(uncompressed)>>4 {
|
||||
// If we removed less than 1/16th, huffman compress the block.
|
||||
bw.writeBlockHuff(isEof, uncompressed, len(in) == 0)
|
||||
} else {
|
||||
bw.writeBlockDynamic(dst, isEof, uncompressed, len(in) == 0)
|
||||
}
|
||||
if len(in) > 0 {
|
||||
// Retain a dict if we have more
|
||||
inDict = inOrg[len(uncompressed)-maxStatelessDict:]
|
||||
dict = nil
|
||||
dst.Reset()
|
||||
}
|
||||
if bw.err != nil {
|
||||
return bw.err
|
||||
}
|
||||
}
|
||||
if !eof {
|
||||
// Align, only a stored block can do that.
|
||||
bw.writeStoredHeader(0, false)
|
||||
}
|
||||
bw.flush()
|
||||
return bw.err
|
||||
}
|
||||
|
||||
func hashSL(u uint32) uint32 {
|
||||
return (u * 0x1e35a7bd) >> slTableShift
|
||||
}
|
||||
|
||||
func load3216(b []byte, i int16) uint32 {
|
||||
return le.Load32(b, i)
|
||||
}
|
||||
|
||||
func load6416(b []byte, i int16) uint64 {
|
||||
return le.Load64(b, i)
|
||||
}
|
||||
|
||||
func statelessEnc(dst *tokens, src []byte, startAt int16) {
|
||||
const (
|
||||
inputMargin = 12 - 1
|
||||
minNonLiteralBlockSize = 1 + 1 + inputMargin
|
||||
)
|
||||
|
||||
type tableEntry struct {
|
||||
offset int16
|
||||
}
|
||||
|
||||
var table [slTableSize]tableEntry
|
||||
|
||||
// This check isn't in the Snappy implementation, but there, the caller
|
||||
// instead of the callee handles this case.
|
||||
if len(src)-int(startAt) < minNonLiteralBlockSize {
|
||||
// We do not fill the token table.
|
||||
// This will be picked up by caller.
|
||||
dst.n = 0
|
||||
return
|
||||
}
|
||||
// Index until startAt
|
||||
if startAt > 0 {
|
||||
cv := load3232(src, 0)
|
||||
for i := range startAt {
|
||||
table[hashSL(cv)] = tableEntry{offset: i}
|
||||
cv = (cv >> 8) | (uint32(src[i+4]) << 24)
|
||||
}
|
||||
}
|
||||
|
||||
s := startAt + 1
|
||||
nextEmit := startAt
|
||||
// sLimit is when to stop looking for offset/length copies. The inputMargin
|
||||
// lets us use a fast path for emitLiteral in the main loop, while we are
|
||||
// looking for copies.
|
||||
sLimit := int16(len(src) - inputMargin)
|
||||
|
||||
// nextEmit is where in src the next emitLiteral should start from.
|
||||
cv := load3216(src, s)
|
||||
|
||||
for {
|
||||
const skipLog = 5
|
||||
const doEvery = 2
|
||||
|
||||
nextS := s
|
||||
var candidate tableEntry
|
||||
for {
|
||||
nextHash := hashSL(cv)
|
||||
candidate = table[nextHash]
|
||||
nextS = s + doEvery + (s-nextEmit)>>skipLog
|
||||
if nextS > sLimit || nextS <= 0 {
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
now := load6416(src, nextS)
|
||||
table[nextHash] = tableEntry{offset: s}
|
||||
nextHash = hashSL(uint32(now))
|
||||
|
||||
if cv == load3216(src, candidate.offset) {
|
||||
table[nextHash] = tableEntry{offset: nextS}
|
||||
break
|
||||
}
|
||||
|
||||
// Do one right away...
|
||||
cv = uint32(now)
|
||||
s = nextS
|
||||
nextS++
|
||||
candidate = table[nextHash]
|
||||
now >>= 8
|
||||
table[nextHash] = tableEntry{offset: s}
|
||||
|
||||
if cv == load3216(src, candidate.offset) {
|
||||
table[nextHash] = tableEntry{offset: nextS}
|
||||
break
|
||||
}
|
||||
cv = uint32(now)
|
||||
s = nextS
|
||||
}
|
||||
|
||||
// A 4-byte match has been found. We'll later see if more than 4 bytes
|
||||
// match. But, prior to the match, src[nextEmit:s] are unmatched. Emit
|
||||
// them as literal bytes.
|
||||
for {
|
||||
// Invariant: we have a 4-byte match at s, and no need to emit any
|
||||
// literal bytes prior to s.
|
||||
|
||||
// Extend the 4-byte match as long as possible.
|
||||
t := candidate.offset
|
||||
l := int16(matchLen(src[s+4:], src[t+4:]) + 4)
|
||||
|
||||
// Extend backwards
|
||||
for t > 0 && s > nextEmit && src[t-1] == src[s-1] {
|
||||
s--
|
||||
t--
|
||||
l++
|
||||
}
|
||||
if nextEmit < s {
|
||||
if false {
|
||||
emitLiteral(dst, src[nextEmit:s])
|
||||
} else {
|
||||
for _, v := range src[nextEmit:s] {
|
||||
dst.tokens[dst.n] = token(v)
|
||||
dst.litHist[v]++
|
||||
dst.n++
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// Save the match found
|
||||
dst.AddMatchLong(int32(l), uint32(s-t-baseMatchOffset))
|
||||
s += l
|
||||
nextEmit = s
|
||||
if nextS >= s {
|
||||
s = nextS + 1
|
||||
}
|
||||
if s >= sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
// We could immediately start working at s now, but to improve
|
||||
// compression we first update the hash table at s-2 and at s. If
|
||||
// another emitCopy is not our next move, also calculate nextHash
|
||||
// at s+1. At least on GOARCH=amd64, these three hash calculations
|
||||
// are faster as one load64 call (with some shifts) instead of
|
||||
// three load32 calls.
|
||||
x := load6416(src, s-2)
|
||||
o := s - 2
|
||||
prevHash := hashSL(uint32(x))
|
||||
table[prevHash] = tableEntry{offset: o}
|
||||
x >>= 16
|
||||
currHash := hashSL(uint32(x))
|
||||
candidate = table[currHash]
|
||||
table[currHash] = tableEntry{offset: o + 2}
|
||||
|
||||
if uint32(x) != load3216(src, candidate.offset) {
|
||||
cv = uint32(x >> 8)
|
||||
s++
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
emitRemainder:
|
||||
if int(nextEmit) < len(src) {
|
||||
// If nothing was added, don't encode literals.
|
||||
if dst.n == 0 {
|
||||
return
|
||||
}
|
||||
emitLiteral(dst, src[nextEmit:])
|
||||
}
|
||||
}
|
||||
Generated
Vendored
-379
@@ -1,379 +0,0 @@
|
||||
// Copyright 2009 The Go Authors. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package flate
|
||||
|
||||
import (
|
||||
"bytes"
|
||||
"encoding/binary"
|
||||
"fmt"
|
||||
"io"
|
||||
"math"
|
||||
)
|
||||
|
||||
const (
|
||||
// bits 0-16 xoffset = offset - MIN_OFFSET_SIZE, or literal - 16 bits
|
||||
// bits 16-22 offsetcode - 5 bits
|
||||
// bits 22-30 xlength = length - MIN_MATCH_LENGTH - 8 bits
|
||||
// bits 30-32 type 0 = literal 1=EOF 2=Match 3=Unused - 2 bits
|
||||
lengthShift = 22
|
||||
offsetMask = 1<<lengthShift - 1
|
||||
typeMask = 3 << 30
|
||||
literalType = 0 << 30
|
||||
matchType = 1 << 30
|
||||
matchOffsetOnlyMask = 0xffff
|
||||
)
|
||||
|
||||
// The length code for length X (MIN_MATCH_LENGTH <= X <= MAX_MATCH_LENGTH)
|
||||
// is lengthCodes[length - MIN_MATCH_LENGTH]
|
||||
var lengthCodes = [256]uint8{
|
||||
0, 1, 2, 3, 4, 5, 6, 7, 8, 8,
|
||||
9, 9, 10, 10, 11, 11, 12, 12, 12, 12,
|
||||
13, 13, 13, 13, 14, 14, 14, 14, 15, 15,
|
||||
15, 15, 16, 16, 16, 16, 16, 16, 16, 16,
|
||||
17, 17, 17, 17, 17, 17, 17, 17, 18, 18,
|
||||
18, 18, 18, 18, 18, 18, 19, 19, 19, 19,
|
||||
19, 19, 19, 19, 20, 20, 20, 20, 20, 20,
|
||||
20, 20, 20, 20, 20, 20, 20, 20, 20, 20,
|
||||
21, 21, 21, 21, 21, 21, 21, 21, 21, 21,
|
||||
21, 21, 21, 21, 21, 21, 22, 22, 22, 22,
|
||||
22, 22, 22, 22, 22, 22, 22, 22, 22, 22,
|
||||
22, 22, 23, 23, 23, 23, 23, 23, 23, 23,
|
||||
23, 23, 23, 23, 23, 23, 23, 23, 24, 24,
|
||||
24, 24, 24, 24, 24, 24, 24, 24, 24, 24,
|
||||
24, 24, 24, 24, 24, 24, 24, 24, 24, 24,
|
||||
24, 24, 24, 24, 24, 24, 24, 24, 24, 24,
|
||||
25, 25, 25, 25, 25, 25, 25, 25, 25, 25,
|
||||
25, 25, 25, 25, 25, 25, 25, 25, 25, 25,
|
||||
25, 25, 25, 25, 25, 25, 25, 25, 25, 25,
|
||||
25, 25, 26, 26, 26, 26, 26, 26, 26, 26,
|
||||
26, 26, 26, 26, 26, 26, 26, 26, 26, 26,
|
||||
26, 26, 26, 26, 26, 26, 26, 26, 26, 26,
|
||||
26, 26, 26, 26, 27, 27, 27, 27, 27, 27,
|
||||
27, 27, 27, 27, 27, 27, 27, 27, 27, 27,
|
||||
27, 27, 27, 27, 27, 27, 27, 27, 27, 27,
|
||||
27, 27, 27, 27, 27, 28,
|
||||
}
|
||||
|
||||
// lengthCodes1 is length codes, but starting at 1.
|
||||
var lengthCodes1 = [256]uint8{
|
||||
1, 2, 3, 4, 5, 6, 7, 8, 9, 9,
|
||||
10, 10, 11, 11, 12, 12, 13, 13, 13, 13,
|
||||
14, 14, 14, 14, 15, 15, 15, 15, 16, 16,
|
||||
16, 16, 17, 17, 17, 17, 17, 17, 17, 17,
|
||||
18, 18, 18, 18, 18, 18, 18, 18, 19, 19,
|
||||
19, 19, 19, 19, 19, 19, 20, 20, 20, 20,
|
||||
20, 20, 20, 20, 21, 21, 21, 21, 21, 21,
|
||||
21, 21, 21, 21, 21, 21, 21, 21, 21, 21,
|
||||
22, 22, 22, 22, 22, 22, 22, 22, 22, 22,
|
||||
22, 22, 22, 22, 22, 22, 23, 23, 23, 23,
|
||||
23, 23, 23, 23, 23, 23, 23, 23, 23, 23,
|
||||
23, 23, 24, 24, 24, 24, 24, 24, 24, 24,
|
||||
24, 24, 24, 24, 24, 24, 24, 24, 25, 25,
|
||||
25, 25, 25, 25, 25, 25, 25, 25, 25, 25,
|
||||
25, 25, 25, 25, 25, 25, 25, 25, 25, 25,
|
||||
25, 25, 25, 25, 25, 25, 25, 25, 25, 25,
|
||||
26, 26, 26, 26, 26, 26, 26, 26, 26, 26,
|
||||
26, 26, 26, 26, 26, 26, 26, 26, 26, 26,
|
||||
26, 26, 26, 26, 26, 26, 26, 26, 26, 26,
|
||||
26, 26, 27, 27, 27, 27, 27, 27, 27, 27,
|
||||
27, 27, 27, 27, 27, 27, 27, 27, 27, 27,
|
||||
27, 27, 27, 27, 27, 27, 27, 27, 27, 27,
|
||||
27, 27, 27, 27, 28, 28, 28, 28, 28, 28,
|
||||
28, 28, 28, 28, 28, 28, 28, 28, 28, 28,
|
||||
28, 28, 28, 28, 28, 28, 28, 28, 28, 28,
|
||||
28, 28, 28, 28, 28, 29,
|
||||
}
|
||||
|
||||
var offsetCodes = [256]uint32{
|
||||
0, 1, 2, 3, 4, 4, 5, 5, 6, 6, 6, 6, 7, 7, 7, 7,
|
||||
8, 8, 8, 8, 8, 8, 8, 8, 9, 9, 9, 9, 9, 9, 9, 9,
|
||||
10, 10, 10, 10, 10, 10, 10, 10, 10, 10, 10, 10, 10, 10, 10, 10,
|
||||
11, 11, 11, 11, 11, 11, 11, 11, 11, 11, 11, 11, 11, 11, 11, 11,
|
||||
12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12,
|
||||
12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12,
|
||||
13, 13, 13, 13, 13, 13, 13, 13, 13, 13, 13, 13, 13, 13, 13, 13,
|
||||
13, 13, 13, 13, 13, 13, 13, 13, 13, 13, 13, 13, 13, 13, 13, 13,
|
||||
14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14,
|
||||
14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14,
|
||||
14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14,
|
||||
14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14, 14,
|
||||
15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15,
|
||||
15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15,
|
||||
15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15,
|
||||
15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15,
|
||||
}
|
||||
|
||||
// offsetCodes14 are offsetCodes, but with 14 added.
|
||||
var offsetCodes14 = [256]uint32{
|
||||
14, 15, 16, 17, 18, 18, 19, 19, 20, 20, 20, 20, 21, 21, 21, 21,
|
||||
22, 22, 22, 22, 22, 22, 22, 22, 23, 23, 23, 23, 23, 23, 23, 23,
|
||||
24, 24, 24, 24, 24, 24, 24, 24, 24, 24, 24, 24, 24, 24, 24, 24,
|
||||
25, 25, 25, 25, 25, 25, 25, 25, 25, 25, 25, 25, 25, 25, 25, 25,
|
||||
26, 26, 26, 26, 26, 26, 26, 26, 26, 26, 26, 26, 26, 26, 26, 26,
|
||||
26, 26, 26, 26, 26, 26, 26, 26, 26, 26, 26, 26, 26, 26, 26, 26,
|
||||
27, 27, 27, 27, 27, 27, 27, 27, 27, 27, 27, 27, 27, 27, 27, 27,
|
||||
27, 27, 27, 27, 27, 27, 27, 27, 27, 27, 27, 27, 27, 27, 27, 27,
|
||||
28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28,
|
||||
28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28,
|
||||
28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28,
|
||||
28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28, 28,
|
||||
29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29,
|
||||
29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29,
|
||||
29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29,
|
||||
29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29, 29,
|
||||
}
|
||||
|
||||
type token uint32
|
||||
|
||||
type tokens struct {
|
||||
extraHist [32]uint16 // codes 256->maxnumlit
|
||||
offHist [32]uint16 // offset codes
|
||||
litHist [256]uint16 // codes 0->255
|
||||
nFilled int
|
||||
n uint16 // Must be able to contain maxStoreBlockSize
|
||||
tokens [maxStoreBlockSize + 1]token
|
||||
}
|
||||
|
||||
func (t *tokens) Reset() {
|
||||
if t.n == 0 {
|
||||
return
|
||||
}
|
||||
t.n = 0
|
||||
t.nFilled = 0
|
||||
for i := range t.litHist[:] {
|
||||
t.litHist[i] = 0
|
||||
}
|
||||
for i := range t.extraHist[:] {
|
||||
t.extraHist[i] = 0
|
||||
}
|
||||
for i := range t.offHist[:] {
|
||||
t.offHist[i] = 0
|
||||
}
|
||||
}
|
||||
|
||||
func (t *tokens) Fill() {
|
||||
if t.n == 0 {
|
||||
return
|
||||
}
|
||||
for i, v := range t.litHist[:] {
|
||||
if v == 0 {
|
||||
t.litHist[i] = 1
|
||||
t.nFilled++
|
||||
}
|
||||
}
|
||||
for i, v := range t.extraHist[:literalCount-256] {
|
||||
if v == 0 {
|
||||
t.nFilled++
|
||||
t.extraHist[i] = 1
|
||||
}
|
||||
}
|
||||
for i, v := range t.offHist[:offsetCodeCount] {
|
||||
if v == 0 {
|
||||
t.offHist[i] = 1
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
func indexTokens(in []token) tokens {
|
||||
var t tokens
|
||||
t.indexTokens(in)
|
||||
return t
|
||||
}
|
||||
|
||||
func (t *tokens) indexTokens(in []token) {
|
||||
t.Reset()
|
||||
for _, tok := range in {
|
||||
if tok < matchType {
|
||||
t.AddLiteral(tok.literal())
|
||||
continue
|
||||
}
|
||||
t.AddMatch(uint32(tok.length()), tok.offset()&matchOffsetOnlyMask)
|
||||
}
|
||||
}
|
||||
|
||||
// emitLiteral writes a literal chunk and returns the number of bytes written.
|
||||
func emitLiteral(dst *tokens, lit []byte) {
|
||||
for _, v := range lit {
|
||||
dst.tokens[dst.n] = token(v)
|
||||
dst.litHist[v]++
|
||||
dst.n++
|
||||
}
|
||||
}
|
||||
|
||||
func (t *tokens) AddLiteral(lit byte) {
|
||||
t.tokens[t.n] = token(lit)
|
||||
t.litHist[lit]++
|
||||
t.n++
|
||||
}
|
||||
|
||||
// from https://stackoverflow.com/a/28730362
|
||||
func mFastLog2(val float32) float32 {
|
||||
ux := int32(math.Float32bits(val))
|
||||
log2 := (float32)(((ux >> 23) & 255) - 128)
|
||||
ux &= -0x7f800001
|
||||
ux += 127 << 23
|
||||
uval := math.Float32frombits(uint32(ux))
|
||||
log2 += ((-0.34484843)*uval+2.02466578)*uval - 0.67487759
|
||||
return log2
|
||||
}
|
||||
|
||||
// EstimatedBits will return an minimum size estimated by an *optimal*
|
||||
// compression of the block.
|
||||
// The size of the block
|
||||
func (t *tokens) EstimatedBits() int {
|
||||
shannon := float32(0)
|
||||
bits := int(0)
|
||||
nMatches := 0
|
||||
total := int(t.n) + t.nFilled
|
||||
if total > 0 {
|
||||
invTotal := 1.0 / float32(total)
|
||||
for _, v := range t.litHist[:] {
|
||||
if v > 0 {
|
||||
n := float32(v)
|
||||
shannon += atLeastOne(-mFastLog2(n*invTotal)) * n
|
||||
}
|
||||
}
|
||||
// Just add 15 for EOB
|
||||
shannon += 15
|
||||
for i, v := range t.extraHist[1 : literalCount-256] {
|
||||
if v > 0 {
|
||||
n := float32(v)
|
||||
shannon += atLeastOne(-mFastLog2(n*invTotal)) * n
|
||||
bits += int(lengthExtraBits[i&31]) * int(v)
|
||||
nMatches += int(v)
|
||||
}
|
||||
}
|
||||
}
|
||||
if nMatches > 0 {
|
||||
invTotal := 1.0 / float32(nMatches)
|
||||
for i, v := range t.offHist[:offsetCodeCount] {
|
||||
if v > 0 {
|
||||
n := float32(v)
|
||||
shannon += atLeastOne(-mFastLog2(n*invTotal)) * n
|
||||
bits += int(offsetExtraBits[i&31]) * int(v)
|
||||
}
|
||||
}
|
||||
}
|
||||
return int(shannon) + bits
|
||||
}
|
||||
|
||||
// AddMatch adds a match to the tokens.
|
||||
// This function is very sensitive to inlining and right on the border.
|
||||
func (t *tokens) AddMatch(xlength uint32, xoffset uint32) {
|
||||
if debugDeflate {
|
||||
if xlength >= maxMatchLength+baseMatchLength {
|
||||
panic(fmt.Errorf("invalid length: %v", xlength))
|
||||
}
|
||||
if xoffset >= maxMatchOffset+baseMatchOffset {
|
||||
panic(fmt.Errorf("invalid offset: %v", xoffset))
|
||||
}
|
||||
}
|
||||
oCode := offsetCode(xoffset)
|
||||
xoffset |= oCode << 16
|
||||
|
||||
t.extraHist[lengthCodes1[uint8(xlength)]]++
|
||||
t.offHist[oCode&31]++
|
||||
t.tokens[t.n] = token(matchType | xlength<<lengthShift | xoffset)
|
||||
t.n++
|
||||
}
|
||||
|
||||
// AddMatchLong adds a match to the tokens, potentially longer than max match length.
|
||||
// Length should NOT have the base subtracted, only offset should.
|
||||
func (t *tokens) AddMatchLong(xlength int32, xoffset uint32) {
|
||||
if debugDeflate {
|
||||
if xoffset >= maxMatchOffset+baseMatchOffset {
|
||||
panic(fmt.Errorf("invalid offset: %v", xoffset))
|
||||
}
|
||||
}
|
||||
oc := offsetCode(xoffset)
|
||||
xoffset |= oc << 16
|
||||
for xlength > 0 {
|
||||
xl := xlength
|
||||
if xl > 258 {
|
||||
// We need to have at least baseMatchLength left over for next loop.
|
||||
if xl > 258+baseMatchLength {
|
||||
xl = 258
|
||||
} else {
|
||||
xl = 258 - baseMatchLength
|
||||
}
|
||||
}
|
||||
xlength -= xl
|
||||
xl -= baseMatchLength
|
||||
t.extraHist[lengthCodes1[uint8(xl)]]++
|
||||
t.offHist[oc&31]++
|
||||
t.tokens[t.n] = token(matchType | uint32(xl)<<lengthShift | xoffset)
|
||||
t.n++
|
||||
}
|
||||
}
|
||||
|
||||
func (t *tokens) AddEOB() {
|
||||
t.tokens[t.n] = token(endBlockMarker)
|
||||
t.extraHist[0]++
|
||||
t.n++
|
||||
}
|
||||
|
||||
func (t *tokens) Slice() []token {
|
||||
return t.tokens[:t.n]
|
||||
}
|
||||
|
||||
// VarInt returns the tokens as varint encoded bytes.
|
||||
func (t *tokens) VarInt() []byte {
|
||||
var b = make([]byte, binary.MaxVarintLen32*int(t.n))
|
||||
var off int
|
||||
for _, v := range t.tokens[:t.n] {
|
||||
off += binary.PutUvarint(b[off:], uint64(v))
|
||||
}
|
||||
return b[:off]
|
||||
}
|
||||
|
||||
// FromVarInt restores t to the varint encoded tokens provided.
|
||||
// Any data in t is removed.
|
||||
func (t *tokens) FromVarInt(b []byte) error {
|
||||
var buf = bytes.NewReader(b)
|
||||
var toks []token
|
||||
for {
|
||||
r, err := binary.ReadUvarint(buf)
|
||||
if err == io.EOF {
|
||||
break
|
||||
}
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
toks = append(toks, token(r))
|
||||
}
|
||||
t.indexTokens(toks)
|
||||
return nil
|
||||
}
|
||||
|
||||
// Returns the type of a token
|
||||
func (t token) typ() uint32 { return uint32(t) & typeMask }
|
||||
|
||||
// Returns the literal of a literal token
|
||||
func (t token) literal() uint8 { return uint8(t) }
|
||||
|
||||
// Returns the extra offset of a match token
|
||||
func (t token) offset() uint32 { return uint32(t) & offsetMask }
|
||||
|
||||
func (t token) length() uint8 { return uint8(t >> lengthShift) }
|
||||
|
||||
// Convert length to code.
|
||||
func lengthCode(len uint8) uint8 { return lengthCodes[len] }
|
||||
|
||||
// Returns the offset code corresponding to a specific offset
|
||||
func offsetCode(off uint32) uint32 {
|
||||
if false {
|
||||
if off < uint32(len(offsetCodes)) {
|
||||
return offsetCodes[off&255]
|
||||
} else if off>>7 < uint32(len(offsetCodes)) {
|
||||
return offsetCodes[(off>>7)&255] + 14
|
||||
} else {
|
||||
return offsetCodes[(off>>14)&255] + 28
|
||||
}
|
||||
}
|
||||
if off < uint32(len(offsetCodes)) {
|
||||
return offsetCodes[uint8(off)]
|
||||
}
|
||||
return offsetCodes14[uint8(off>>7)]
|
||||
}
|
||||
Generated
Vendored
-5
@@ -1,5 +0,0 @@
|
||||
package le
|
||||
|
||||
type Indexer interface {
|
||||
int | int8 | int16 | int32 | int64 | uint | uint8 | uint16 | uint32 | uint64
|
||||
}
|
||||
Generated
Vendored
-42
@@ -1,42 +0,0 @@
|
||||
//go:build !(amd64 || arm64 || ppc64le || riscv64) || nounsafe || purego || appengine
|
||||
|
||||
package le
|
||||
|
||||
import (
|
||||
"encoding/binary"
|
||||
)
|
||||
|
||||
// Load8 will load from b at index i.
|
||||
func Load8[I Indexer](b []byte, i I) byte {
|
||||
return b[i]
|
||||
}
|
||||
|
||||
// Load16 will load from b at index i.
|
||||
func Load16[I Indexer](b []byte, i I) uint16 {
|
||||
return binary.LittleEndian.Uint16(b[i:])
|
||||
}
|
||||
|
||||
// Load32 will load from b at index i.
|
||||
func Load32[I Indexer](b []byte, i I) uint32 {
|
||||
return binary.LittleEndian.Uint32(b[i:])
|
||||
}
|
||||
|
||||
// Load64 will load from b at index i.
|
||||
func Load64[I Indexer](b []byte, i I) uint64 {
|
||||
return binary.LittleEndian.Uint64(b[i:])
|
||||
}
|
||||
|
||||
// Store16 will store v at b.
|
||||
func Store16(b []byte, v uint16) {
|
||||
binary.LittleEndian.PutUint16(b, v)
|
||||
}
|
||||
|
||||
// Store32 will store v at b.
|
||||
func Store32(b []byte, v uint32) {
|
||||
binary.LittleEndian.PutUint32(b, v)
|
||||
}
|
||||
|
||||
// Store64 will store v at b.
|
||||
func Store64[I Indexer](b []byte, i I, v uint64) {
|
||||
binary.LittleEndian.PutUint64(b[i:], v)
|
||||
}
|
||||
Generated
Vendored
-52
@@ -1,52 +0,0 @@
|
||||
// We enable 64 bit LE platforms:
|
||||
|
||||
//go:build (amd64 || arm64 || ppc64le || riscv64) && !nounsafe && !purego && !appengine
|
||||
|
||||
package le
|
||||
|
||||
import (
|
||||
"unsafe"
|
||||
)
|
||||
|
||||
// Load8 will load from b at index i.
|
||||
func Load8[I Indexer](b []byte, i I) byte {
|
||||
//return binary.LittleEndian.Uint16(b[i:])
|
||||
//return *(*uint16)(unsafe.Pointer(&b[i]))
|
||||
return *(*byte)(unsafe.Add(unsafe.Pointer(unsafe.SliceData(b)), i))
|
||||
}
|
||||
|
||||
// Load16 will load from b at index i.
|
||||
func Load16[I Indexer](b []byte, i I) uint16 {
|
||||
//return binary.LittleEndian.Uint16(b[i:])
|
||||
//return *(*uint16)(unsafe.Pointer(&b[i]))
|
||||
return *(*uint16)(unsafe.Add(unsafe.Pointer(unsafe.SliceData(b)), i))
|
||||
}
|
||||
|
||||
// Load32 will load from b at index i.
|
||||
func Load32[I Indexer](b []byte, i I) uint32 {
|
||||
//return binary.LittleEndian.Uint32(b[i:])
|
||||
//return *(*uint32)(unsafe.Pointer(&b[i]))
|
||||
return *(*uint32)(unsafe.Add(unsafe.Pointer(unsafe.SliceData(b)), i))
|
||||
}
|
||||
|
||||
// Load64 will load from b at index i.
|
||||
func Load64[I Indexer](b []byte, i I) uint64 {
|
||||
//return binary.LittleEndian.Uint64(b[i:])
|
||||
//return *(*uint64)(unsafe.Pointer(&b[i]))
|
||||
return *(*uint64)(unsafe.Add(unsafe.Pointer(unsafe.SliceData(b)), i))
|
||||
}
|
||||
|
||||
// Store16 will store v at b.
|
||||
func Store16(b []byte, v uint16) {
|
||||
*(*uint16)(unsafe.Pointer(unsafe.SliceData(b))) = v
|
||||
}
|
||||
|
||||
// Store32 will store v at b.
|
||||
func Store32(b []byte, v uint32) {
|
||||
*(*uint32)(unsafe.Pointer(unsafe.SliceData(b))) = v
|
||||
}
|
||||
|
||||
// Store64 will store v at b[i:].
|
||||
func Store64[I Indexer](b []byte, i I, v uint64) {
|
||||
*(*uint64)(unsafe.Add(unsafe.Pointer(unsafe.SliceData(b)), i)) = v
|
||||
}
|
||||
Generated
Vendored
-13
@@ -1,13 +0,0 @@
|
||||
// Copyright 2015 The Go Authors. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
//go:build !race
|
||||
|
||||
package race
|
||||
|
||||
func ReadSlice[T any](s []T) {
|
||||
}
|
||||
|
||||
func WriteSlice[T any](s []T) {
|
||||
}
|
||||
Generated
Vendored
-26
@@ -1,26 +0,0 @@
|
||||
// Copyright 2015 The Go Authors. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
//go:build race
|
||||
|
||||
package race
|
||||
|
||||
import (
|
||||
"runtime"
|
||||
"unsafe"
|
||||
)
|
||||
|
||||
func ReadSlice[T any](s []T) {
|
||||
if len(s) == 0 {
|
||||
return
|
||||
}
|
||||
runtime.RaceReadRange(unsafe.Pointer(&s[0]), len(s)*int(unsafe.Sizeof(s[0])))
|
||||
}
|
||||
|
||||
func WriteSlice[T any](s []T) {
|
||||
if len(s) == 0 {
|
||||
return
|
||||
}
|
||||
runtime.RaceWriteRange(unsafe.Pointer(&s[0]), len(s)*int(unsafe.Sizeof(s[0])))
|
||||
}
|
||||
Generated
Vendored
-50
@@ -1,50 +0,0 @@
|
||||
//go:build !386
|
||||
|
||||
// Package regmask provides masks for variable shift counts.
|
||||
//
|
||||
// Go defines a shift by more than the width of the shifted value as producing
|
||||
// zero, so the compiler has to guard every variable shift against that: on
|
||||
// amd64 with a CMP and an SBB, on arm64 with a CMP and a CSEL, and so on. When
|
||||
// the count is known to be smaller than the width anyway, masking it with the
|
||||
// width minus one lets the compiler drop the guard. The mask itself costs
|
||||
// nothing on the architectures whose shift instructions already use only the
|
||||
// low bits of the count, which the compiler knows about.
|
||||
//
|
||||
// Each constant is named for the width of the value being shifted and the type
|
||||
// of the shift count, and may only be used where the count is always smaller
|
||||
// than that width:
|
||||
//
|
||||
// x := y >> (n & regmask.Shift64ByUint) // y is 64 bits, n is a uint below 64
|
||||
package regmask
|
||||
|
||||
const (
|
||||
// ShiftNByUint8 - shifting an N bit value by a uint8
|
||||
Shift8ByUint8 = 7
|
||||
Shift16ByUint8 = 15
|
||||
Shift32ByUint8 = 31
|
||||
Shift64ByUint8 = 63
|
||||
|
||||
// ShiftNByUint16 - shifting an N bit value by a uint16
|
||||
Shift8ByUint16 = Shift8ByUint8
|
||||
Shift16ByUint16 = Shift16ByUint8
|
||||
Shift32ByUint16 = Shift32ByUint8
|
||||
Shift64ByUint16 = Shift64ByUint8
|
||||
|
||||
// ShiftNByUint32 - shifting an N bit value by a uint32
|
||||
Shift8ByUint32 = Shift8ByUint8
|
||||
Shift16ByUint32 = Shift16ByUint8
|
||||
Shift32ByUint32 = Shift32ByUint8
|
||||
Shift64ByUint32 = Shift64ByUint8
|
||||
|
||||
// ShiftNByUint64 - shifting an N bit value by a uint64
|
||||
Shift8ByUint64 = Shift8ByUint8
|
||||
Shift16ByUint64 = Shift16ByUint8
|
||||
Shift32ByUint64 = Shift32ByUint8
|
||||
Shift64ByUint64 = Shift64ByUint8
|
||||
|
||||
// ShiftNByUint - shifting an N bit value by a uint
|
||||
Shift8ByUint = Shift8ByUint8
|
||||
Shift16ByUint = Shift16ByUint8
|
||||
Shift32ByUint = Shift32ByUint8
|
||||
Shift64ByUint = Shift64ByUint8
|
||||
)
|
||||
Generated
Vendored
-39
@@ -1,39 +0,0 @@
|
||||
//go:build 386
|
||||
|
||||
package regmask
|
||||
|
||||
// A 64 bit shift on 386 is synthesized from 32 bit instructions, and masking its
|
||||
// count makes the compiler emit more code rather than less, so those masks are
|
||||
// no-ops here: each is the largest value its count type can hold, which the
|
||||
// compiler folds away. Shifts of narrower values behave as elsewhere.
|
||||
const (
|
||||
// ShiftNByUint8 - shifting an N bit value by a uint8
|
||||
Shift8ByUint8 = 7
|
||||
Shift16ByUint8 = 15
|
||||
Shift32ByUint8 = 31
|
||||
Shift64ByUint8 = 0xff
|
||||
|
||||
// ShiftNByUint16 - shifting an N bit value by a uint16
|
||||
Shift8ByUint16 = Shift8ByUint8
|
||||
Shift16ByUint16 = Shift16ByUint8
|
||||
Shift32ByUint16 = Shift32ByUint8
|
||||
Shift64ByUint16 = 0xffff
|
||||
|
||||
// ShiftNByUint32 - shifting an N bit value by a uint32
|
||||
Shift8ByUint32 = Shift8ByUint8
|
||||
Shift16ByUint32 = Shift16ByUint8
|
||||
Shift32ByUint32 = Shift32ByUint8
|
||||
Shift64ByUint32 = 0xffffffff
|
||||
|
||||
// ShiftNByUint64 - shifting an N bit value by a uint64
|
||||
Shift8ByUint64 = Shift8ByUint8
|
||||
Shift16ByUint64 = Shift16ByUint8
|
||||
Shift32ByUint64 = Shift32ByUint8
|
||||
Shift64ByUint64 = 0xffffffffffffffff
|
||||
|
||||
// ShiftNByUint - shifting an N bit value by a uint
|
||||
Shift8ByUint = Shift8ByUint8
|
||||
Shift16ByUint = Shift16ByUint8
|
||||
Shift32ByUint = Shift32ByUint8
|
||||
Shift64ByUint = ^uint(0)
|
||||
)
|
||||
-15
@@ -1,15 +0,0 @@
|
||||
testdata/bench
|
||||
|
||||
# These explicitly listed benchmark data files are for an obsolete version of
|
||||
# snappy_test.go.
|
||||
testdata/alice29.txt
|
||||
testdata/asyoulik.txt
|
||||
testdata/fireworks.jpeg
|
||||
testdata/geo.protodata
|
||||
testdata/html
|
||||
testdata/html_x_4
|
||||
testdata/kppkn.gtb
|
||||
testdata/lcet10.txt
|
||||
testdata/paper-100k.pdf
|
||||
testdata/plrabn12.txt
|
||||
testdata/urls.10K
|
||||
Generated
Vendored
-28
@@ -1,28 +0,0 @@
|
||||
Copyright (c) 2011 The Snappy-Go Authors. All rights reserved.
|
||||
Copyright (c) 2019 Klaus Post. All rights reserved.
|
||||
|
||||
Redistribution and use in source and binary forms, with or without
|
||||
modification, are permitted provided that the following conditions are
|
||||
met:
|
||||
|
||||
* Redistributions of source code must retain the above copyright
|
||||
notice, this list of conditions and the following disclaimer.
|
||||
* Redistributions in binary form must reproduce the above
|
||||
copyright notice, this list of conditions and the following disclaimer
|
||||
in the documentation and/or other materials provided with the
|
||||
distribution.
|
||||
* Neither the name of Google Inc. nor the names of its
|
||||
contributors may be used to endorse or promote products derived from
|
||||
this software without specific prior written permission.
|
||||
|
||||
THIS SOFTWARE IS PROVIDED BY THE COPYRIGHT HOLDERS AND CONTRIBUTORS
|
||||
"AS IS" AND ANY EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT
|
||||
LIMITED TO, THE IMPLIED WARRANTIES OF MERCHANTABILITY AND FITNESS FOR
|
||||
A PARTICULAR PURPOSE ARE DISCLAIMED. IN NO EVENT SHALL THE COPYRIGHT
|
||||
OWNER OR CONTRIBUTORS BE LIABLE FOR ANY DIRECT, INDIRECT, INCIDENTAL,
|
||||
SPECIAL, EXEMPLARY, OR CONSEQUENTIAL DAMAGES (INCLUDING, BUT NOT
|
||||
LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR SERVICES; LOSS OF USE,
|
||||
DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER CAUSED AND ON ANY
|
||||
THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY, OR TORT
|
||||
(INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE
|
||||
OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
|
||||
Generated
Vendored
-1134
File diff suppressed because it is too large
Load Diff
Generated
Vendored
-443
@@ -1,443 +0,0 @@
|
||||
// Copyright 2011 The Snappy-Go Authors. All rights reserved.
|
||||
// Copyright (c) 2019 Klaus Post. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package s2
|
||||
|
||||
import (
|
||||
"encoding/binary"
|
||||
"errors"
|
||||
"fmt"
|
||||
"strconv"
|
||||
|
||||
"github.com/klauspost/compress/internal/race"
|
||||
)
|
||||
|
||||
var (
|
||||
// ErrCorrupt reports that the input is invalid.
|
||||
ErrCorrupt = errors.New("s2: corrupt input")
|
||||
// ErrCRC reports that the input failed CRC validation (streams only)
|
||||
ErrCRC = errors.New("s2: corrupt input, crc mismatch")
|
||||
// ErrTooLarge reports that the uncompressed length is too large.
|
||||
ErrTooLarge = errors.New("s2: decoded block is too large")
|
||||
// ErrUnsupported reports that the input isn't supported.
|
||||
ErrUnsupported = errors.New("s2: unsupported input")
|
||||
)
|
||||
|
||||
// DecodedLen returns the length of the decoded block.
|
||||
func DecodedLen(src []byte) (int, error) {
|
||||
v, _, err := decodedLen(src)
|
||||
return v, err
|
||||
}
|
||||
|
||||
// decodedLen returns the length of the decoded block and the number of bytes
|
||||
// that the length header occupied.
|
||||
func decodedLen(src []byte) (blockLen, headerLen int, err error) {
|
||||
v, n := binary.Uvarint(src)
|
||||
if n <= 0 || n > 5 || v > 0xffffffff {
|
||||
return 0, 0, ErrCorrupt
|
||||
}
|
||||
|
||||
const wordSize = 32 << (^uint(0) >> 32 & 1)
|
||||
if wordSize == 32 && v > 0x7fffffff {
|
||||
return 0, 0, ErrTooLarge
|
||||
}
|
||||
return int(v), n, nil
|
||||
}
|
||||
|
||||
const (
|
||||
decodeErrCodeCorrupt = 1
|
||||
)
|
||||
|
||||
// Decode returns the decoded form of src. The returned slice may be a sub-
|
||||
// slice of dst if dst was large enough to hold the entire decoded block.
|
||||
// Otherwise, a newly allocated slice will be returned.
|
||||
//
|
||||
// The dst and src must not overlap. It is valid to pass a nil dst.
|
||||
func Decode(dst, src []byte) ([]byte, error) {
|
||||
dLen, s, err := decodedLen(src)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
if dLen <= cap(dst) {
|
||||
dst = dst[:dLen]
|
||||
} else {
|
||||
dst = make([]byte, dLen)
|
||||
}
|
||||
|
||||
race.WriteSlice(dst)
|
||||
race.ReadSlice(src[s:])
|
||||
|
||||
if s2Decode(dst, src[s:]) != 0 {
|
||||
return nil, ErrCorrupt
|
||||
}
|
||||
return dst, nil
|
||||
}
|
||||
|
||||
// s2DecodeDict writes the decoding of src to dst. It assumes that the varint-encoded
|
||||
// length of the decompressed bytes has already been read, and that len(dst)
|
||||
// equals that length.
|
||||
//
|
||||
// It returns 0 on success or a decodeErrCodeXxx error code on failure.
|
||||
func s2DecodeDict(dst, src []byte, dict *Dict) int {
|
||||
if dict == nil {
|
||||
return s2Decode(dst, src)
|
||||
}
|
||||
const debug = false
|
||||
const debugErrs = debug
|
||||
|
||||
if debug {
|
||||
fmt.Println("Starting decode, dst len:", len(dst))
|
||||
}
|
||||
var d, s, length int
|
||||
offset := len(dict.dict) - dict.repeat
|
||||
|
||||
// As long as we can read at least 5 bytes...
|
||||
for s < len(src)-5 {
|
||||
// Removing bounds checks is SLOWER, when if doing
|
||||
// in := src[s:s+5]
|
||||
// Checked on Go 1.18
|
||||
switch src[s] & 0x03 {
|
||||
case tagLiteral:
|
||||
x := uint32(src[s] >> 2)
|
||||
switch {
|
||||
case x < 60:
|
||||
s++
|
||||
case x == 60:
|
||||
s += 2
|
||||
x = uint32(src[s-1])
|
||||
case x == 61:
|
||||
in := src[s : s+3]
|
||||
x = uint32(in[1]) | uint32(in[2])<<8
|
||||
s += 3
|
||||
case x == 62:
|
||||
in := src[s : s+4]
|
||||
// Load as 32 bit and shift down.
|
||||
x = uint32(in[0]) | uint32(in[1])<<8 | uint32(in[2])<<16 | uint32(in[3])<<24
|
||||
x >>= 8
|
||||
s += 4
|
||||
case x == 63:
|
||||
in := src[s : s+5]
|
||||
x = uint32(in[1]) | uint32(in[2])<<8 | uint32(in[3])<<16 | uint32(in[4])<<24
|
||||
s += 5
|
||||
}
|
||||
length = int(x) + 1
|
||||
if debug {
|
||||
fmt.Println("literals, length:", length, "d-after:", d+length)
|
||||
}
|
||||
if length > len(dst)-d || length > len(src)-s || (strconv.IntSize == 32 && length <= 0) {
|
||||
if debugErrs {
|
||||
fmt.Println("corrupt literal: length:", length, "d-left:", len(dst)-d, "src-left:", len(src)-s)
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
|
||||
copy(dst[d:], src[s:s+length])
|
||||
d += length
|
||||
s += length
|
||||
continue
|
||||
|
||||
case tagCopy1:
|
||||
s += 2
|
||||
toffset := int(uint32(src[s-2])&0xe0<<3 | uint32(src[s-1]))
|
||||
length = int(src[s-2]) >> 2 & 0x7
|
||||
if toffset == 0 {
|
||||
if debug {
|
||||
fmt.Print("(repeat) ")
|
||||
}
|
||||
// keep last offset
|
||||
switch length {
|
||||
case 5:
|
||||
length = int(src[s]) + 4
|
||||
s += 1
|
||||
case 6:
|
||||
in := src[s : s+2]
|
||||
length = int(uint32(in[0])|(uint32(in[1])<<8)) + (1 << 8)
|
||||
s += 2
|
||||
case 7:
|
||||
in := src[s : s+3]
|
||||
length = int((uint32(in[2])<<16)|(uint32(in[1])<<8)|uint32(in[0])) + (1 << 16)
|
||||
s += 3
|
||||
default: // 0-> 4
|
||||
}
|
||||
} else {
|
||||
offset = toffset
|
||||
}
|
||||
length += 4
|
||||
case tagCopy2:
|
||||
in := src[s : s+3]
|
||||
offset = int(uint32(in[1]) | uint32(in[2])<<8)
|
||||
length = 1 + int(in[0])>>2
|
||||
s += 3
|
||||
|
||||
case tagCopy4:
|
||||
in := src[s : s+5]
|
||||
offset = int(uint32(in[1]) | uint32(in[2])<<8 | uint32(in[3])<<16 | uint32(in[4])<<24)
|
||||
length = 1 + int(in[0])>>2
|
||||
s += 5
|
||||
}
|
||||
|
||||
if offset <= 0 || length > len(dst)-d {
|
||||
if debugErrs {
|
||||
fmt.Println("match error; offset:", offset, "length:", length, "dst-left:", len(dst)-d)
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
|
||||
// copy from dict
|
||||
if d < offset {
|
||||
if d > MaxDictSrcOffset {
|
||||
if debugErrs {
|
||||
fmt.Println("dict after", MaxDictSrcOffset, "d:", d, "offset:", offset, "length:", length)
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
startOff := len(dict.dict) - offset + d
|
||||
if startOff < 0 || startOff+length > len(dict.dict) {
|
||||
if debugErrs {
|
||||
fmt.Printf("offset (%d) + length (%d) bigger than dict (%d)\n", offset, length, len(dict.dict))
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
if debug {
|
||||
fmt.Println("dict copy, length:", length, "offset:", offset, "d-after:", d+length, "dict start offset:", startOff)
|
||||
}
|
||||
copy(dst[d:d+length], dict.dict[startOff:])
|
||||
d += length
|
||||
continue
|
||||
}
|
||||
|
||||
if debug {
|
||||
fmt.Println("copy, length:", length, "offset:", offset, "d-after:", d+length)
|
||||
}
|
||||
|
||||
// Copy from an earlier sub-slice of dst to a later sub-slice.
|
||||
// If no overlap, use the built-in copy:
|
||||
if offset > length {
|
||||
copy(dst[d:d+length], dst[d-offset:])
|
||||
d += length
|
||||
continue
|
||||
}
|
||||
|
||||
// Unlike the built-in copy function, this byte-by-byte copy always runs
|
||||
// forwards, even if the slices overlap. Conceptually, this is:
|
||||
//
|
||||
// d += forwardCopy(dst[d:d+length], dst[d-offset:])
|
||||
//
|
||||
// We align the slices into a and b and show the compiler they are the same size.
|
||||
// This allows the loop to run without bounds checks.
|
||||
a := dst[d : d+length]
|
||||
b := dst[d-offset:]
|
||||
b = b[:len(a)]
|
||||
for i := range a {
|
||||
a[i] = b[i]
|
||||
}
|
||||
d += length
|
||||
}
|
||||
|
||||
// Remaining with extra checks...
|
||||
for s < len(src) {
|
||||
switch src[s] & 0x03 {
|
||||
case tagLiteral:
|
||||
x := uint32(src[s] >> 2)
|
||||
switch {
|
||||
case x < 60:
|
||||
s++
|
||||
case x == 60:
|
||||
s += 2
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
if debugErrs {
|
||||
fmt.Println("src went oob")
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
x = uint32(src[s-1])
|
||||
case x == 61:
|
||||
s += 3
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
if debugErrs {
|
||||
fmt.Println("src went oob")
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
x = uint32(src[s-2]) | uint32(src[s-1])<<8
|
||||
case x == 62:
|
||||
s += 4
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
if debugErrs {
|
||||
fmt.Println("src went oob")
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
x = uint32(src[s-3]) | uint32(src[s-2])<<8 | uint32(src[s-1])<<16
|
||||
case x == 63:
|
||||
s += 5
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
if debugErrs {
|
||||
fmt.Println("src went oob")
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
x = uint32(src[s-4]) | uint32(src[s-3])<<8 | uint32(src[s-2])<<16 | uint32(src[s-1])<<24
|
||||
}
|
||||
length = int(x) + 1
|
||||
if length > len(dst)-d || length > len(src)-s || (strconv.IntSize == 32 && length <= 0) {
|
||||
if debugErrs {
|
||||
fmt.Println("corrupt literal: length:", length, "d-left:", len(dst)-d, "src-left:", len(src)-s)
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
if debug {
|
||||
fmt.Println("literals, length:", length, "d-after:", d+length)
|
||||
}
|
||||
|
||||
copy(dst[d:], src[s:s+length])
|
||||
d += length
|
||||
s += length
|
||||
continue
|
||||
|
||||
case tagCopy1:
|
||||
s += 2
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
if debugErrs {
|
||||
fmt.Println("src went oob")
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
length = int(src[s-2]) >> 2 & 0x7
|
||||
toffset := int(uint32(src[s-2])&0xe0<<3 | uint32(src[s-1]))
|
||||
if toffset == 0 {
|
||||
if debug {
|
||||
fmt.Print("(repeat) ")
|
||||
}
|
||||
// keep last offset
|
||||
switch length {
|
||||
case 5:
|
||||
s += 1
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
if debugErrs {
|
||||
fmt.Println("src went oob")
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
length = int(uint32(src[s-1])) + 4
|
||||
case 6:
|
||||
s += 2
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
if debugErrs {
|
||||
fmt.Println("src went oob")
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
length = int(uint32(src[s-2])|(uint32(src[s-1])<<8)) + (1 << 8)
|
||||
case 7:
|
||||
s += 3
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
if debugErrs {
|
||||
fmt.Println("src went oob")
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
length = int(uint32(src[s-3])|(uint32(src[s-2])<<8)|(uint32(src[s-1])<<16)) + (1 << 16)
|
||||
default: // 0-> 4
|
||||
}
|
||||
} else {
|
||||
offset = toffset
|
||||
}
|
||||
length += 4
|
||||
case tagCopy2:
|
||||
s += 3
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
if debugErrs {
|
||||
fmt.Println("src went oob")
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
length = 1 + int(src[s-3])>>2
|
||||
offset = int(uint32(src[s-2]) | uint32(src[s-1])<<8)
|
||||
|
||||
case tagCopy4:
|
||||
s += 5
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
if debugErrs {
|
||||
fmt.Println("src went oob")
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
length = 1 + int(src[s-5])>>2
|
||||
offset = int(uint32(src[s-4]) | uint32(src[s-3])<<8 | uint32(src[s-2])<<16 | uint32(src[s-1])<<24)
|
||||
}
|
||||
|
||||
if offset <= 0 || length > len(dst)-d {
|
||||
if debugErrs {
|
||||
fmt.Println("match error; offset:", offset, "length:", length, "dst-left:", len(dst)-d)
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
|
||||
// copy from dict
|
||||
if d < offset {
|
||||
if d > MaxDictSrcOffset {
|
||||
if debugErrs {
|
||||
fmt.Println("dict after", MaxDictSrcOffset, "d:", d, "offset:", offset, "length:", length)
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
rOff := len(dict.dict) - (offset - d)
|
||||
if debug {
|
||||
fmt.Println("starting dict entry from dict offset", len(dict.dict)-rOff)
|
||||
}
|
||||
if rOff+length > len(dict.dict) {
|
||||
if debugErrs {
|
||||
fmt.Println("err: END offset", rOff+length, "bigger than dict", len(dict.dict), "dict offset:", rOff, "length:", length)
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
if rOff < 0 {
|
||||
if debugErrs {
|
||||
fmt.Println("err: START offset", rOff, "less than 0", len(dict.dict), "dict offset:", rOff, "length:", length)
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
copy(dst[d:d+length], dict.dict[rOff:])
|
||||
d += length
|
||||
continue
|
||||
}
|
||||
|
||||
if debug {
|
||||
fmt.Println("copy, length:", length, "offset:", offset, "d-after:", d+length)
|
||||
}
|
||||
|
||||
// Copy from an earlier sub-slice of dst to a later sub-slice.
|
||||
// If no overlap, use the built-in copy:
|
||||
if offset > length {
|
||||
copy(dst[d:d+length], dst[d-offset:])
|
||||
d += length
|
||||
continue
|
||||
}
|
||||
|
||||
// Unlike the built-in copy function, this byte-by-byte copy always runs
|
||||
// forwards, even if the slices overlap. Conceptually, this is:
|
||||
//
|
||||
// d += forwardCopy(dst[d:d+length], dst[d-offset:])
|
||||
//
|
||||
// We align the slices into a and b and show the compiler they are the same size.
|
||||
// This allows the loop to run without bounds checks.
|
||||
a := dst[d : d+length]
|
||||
b := dst[d-offset:]
|
||||
b = b[:len(a)]
|
||||
for i := range a {
|
||||
a[i] = b[i]
|
||||
}
|
||||
d += length
|
||||
}
|
||||
|
||||
if d != len(dst) {
|
||||
if debugErrs {
|
||||
fmt.Println("wanted length", len(dst), "got", d)
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
return 0
|
||||
}
|
||||
Generated
Vendored
-568
@@ -1,568 +0,0 @@
|
||||
// Copyright 2016 The Go Authors. All rights reserved.
|
||||
// Copyright (c) 2019 Klaus Post. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
// +build !appengine
|
||||
// +build gc
|
||||
// +build !noasm
|
||||
|
||||
#include "textflag.h"
|
||||
|
||||
#define R_TMP0 AX
|
||||
#define R_TMP1 BX
|
||||
#define R_LEN CX
|
||||
#define R_OFF DX
|
||||
#define R_SRC SI
|
||||
#define R_DST DI
|
||||
#define R_DBASE R8
|
||||
#define R_DLEN R9
|
||||
#define R_DEND R10
|
||||
#define R_SBASE R11
|
||||
#define R_SLEN R12
|
||||
#define R_SEND R13
|
||||
#define R_TMP2 R14
|
||||
#define R_TMP3 R15
|
||||
|
||||
// The asm code generally follows the pure Go code in decode_other.go, except
|
||||
// where marked with a "!!!".
|
||||
|
||||
// func decode(dst, src []byte) int
|
||||
//
|
||||
// All local variables fit into registers. The non-zero stack size is only to
|
||||
// spill registers and push args when issuing a CALL. The register allocation:
|
||||
// - R_TMP0 scratch
|
||||
// - R_TMP1 scratch
|
||||
// - R_LEN length or x (shared)
|
||||
// - R_OFF offset
|
||||
// - R_SRC &src[s]
|
||||
// - R_DST &dst[d]
|
||||
// + R_DBASE dst_base
|
||||
// + R_DLEN dst_len
|
||||
// + R_DEND dst_base + dst_len
|
||||
// + R_SBASE src_base
|
||||
// + R_SLEN src_len
|
||||
// + R_SEND src_base + src_len
|
||||
// - R_TMP2 used by doCopy
|
||||
// - R_TMP3 used by doCopy
|
||||
//
|
||||
// The registers R_DBASE-R_SEND (marked with a "+") are set at the start of the
|
||||
// function, and after a CALL returns, and are not otherwise modified.
|
||||
//
|
||||
// The d variable is implicitly R_DST - R_DBASE, and len(dst)-d is R_DEND - R_DST.
|
||||
// The s variable is implicitly R_SRC - R_SBASE, and len(src)-s is R_SEND - R_SRC.
|
||||
TEXT ·s2Decode(SB), NOSPLIT, $56-56
|
||||
// Initialize R_SRC, R_DST and R_DBASE-R_SEND.
|
||||
MOVQ dst_base+0(FP), R_DBASE
|
||||
MOVQ dst_len+8(FP), R_DLEN
|
||||
MOVQ R_DBASE, R_DST
|
||||
MOVQ R_DBASE, R_DEND
|
||||
ADDQ R_DLEN, R_DEND
|
||||
MOVQ src_base+24(FP), R_SBASE
|
||||
MOVQ src_len+32(FP), R_SLEN
|
||||
MOVQ R_SBASE, R_SRC
|
||||
MOVQ R_SBASE, R_SEND
|
||||
ADDQ R_SLEN, R_SEND
|
||||
XORQ R_OFF, R_OFF
|
||||
|
||||
loop:
|
||||
// for s < len(src)
|
||||
CMPQ R_SRC, R_SEND
|
||||
JEQ end
|
||||
|
||||
// R_LEN = uint32(src[s])
|
||||
//
|
||||
// switch src[s] & 0x03
|
||||
MOVBLZX (R_SRC), R_LEN
|
||||
MOVL R_LEN, R_TMP1
|
||||
ANDL $3, R_TMP1
|
||||
CMPL R_TMP1, $1
|
||||
JAE tagCopy
|
||||
|
||||
// ----------------------------------------
|
||||
// The code below handles literal tags.
|
||||
|
||||
// case tagLiteral:
|
||||
// x := uint32(src[s] >> 2)
|
||||
// switch
|
||||
SHRL $2, R_LEN
|
||||
CMPL R_LEN, $60
|
||||
JAE tagLit60Plus
|
||||
|
||||
// case x < 60:
|
||||
// s++
|
||||
INCQ R_SRC
|
||||
|
||||
doLit:
|
||||
// This is the end of the inner "switch", when we have a literal tag.
|
||||
//
|
||||
// We assume that R_LEN == x and x fits in a uint32, where x is the variable
|
||||
// used in the pure Go decode_other.go code.
|
||||
|
||||
// length = int(x) + 1
|
||||
//
|
||||
// Unlike the pure Go code, we don't need to check if length <= 0 because
|
||||
// R_LEN can hold 64 bits, so the increment cannot overflow.
|
||||
INCQ R_LEN
|
||||
|
||||
// Prepare to check if copying length bytes will run past the end of dst or
|
||||
// src.
|
||||
//
|
||||
// R_TMP0 = len(dst) - d
|
||||
// R_TMP1 = len(src) - s
|
||||
MOVQ R_DEND, R_TMP0
|
||||
SUBQ R_DST, R_TMP0
|
||||
MOVQ R_SEND, R_TMP1
|
||||
SUBQ R_SRC, R_TMP1
|
||||
|
||||
// !!! Try a faster technique for short (16 or fewer bytes) copies.
|
||||
//
|
||||
// if length > 16 || len(dst)-d < 16 || len(src)-s < 16 {
|
||||
// goto callMemmove // Fall back on calling runtime·memmove.
|
||||
// }
|
||||
//
|
||||
// The C++ snappy code calls this TryFastAppend. It also checks len(src)-s
|
||||
// against 21 instead of 16, because it cannot assume that all of its input
|
||||
// is contiguous in memory and so it needs to leave enough source bytes to
|
||||
// read the next tag without refilling buffers, but Go's Decode assumes
|
||||
// contiguousness (the src argument is a []byte).
|
||||
CMPQ R_LEN, $16
|
||||
JGT callMemmove
|
||||
CMPQ R_TMP0, $16
|
||||
JLT callMemmove
|
||||
CMPQ R_TMP1, $16
|
||||
JLT callMemmove
|
||||
|
||||
// !!! Implement the copy from src to dst as a 16-byte load and store.
|
||||
// (Decode's documentation says that dst and src must not overlap.)
|
||||
//
|
||||
// This always copies 16 bytes, instead of only length bytes, but that's
|
||||
// OK. If the input is a valid Snappy encoding then subsequent iterations
|
||||
// will fix up the overrun. Otherwise, Decode returns a nil []byte (and a
|
||||
// non-nil error), so the overrun will be ignored.
|
||||
//
|
||||
// Note that on amd64, it is legal and cheap to issue unaligned 8-byte or
|
||||
// 16-byte loads and stores. This technique probably wouldn't be as
|
||||
// effective on architectures that are fussier about alignment.
|
||||
MOVOU 0(R_SRC), X0
|
||||
MOVOU X0, 0(R_DST)
|
||||
|
||||
// d += length
|
||||
// s += length
|
||||
ADDQ R_LEN, R_DST
|
||||
ADDQ R_LEN, R_SRC
|
||||
JMP loop
|
||||
|
||||
callMemmove:
|
||||
// if length > len(dst)-d || length > len(src)-s { etc }
|
||||
CMPQ R_LEN, R_TMP0
|
||||
JGT errCorrupt
|
||||
CMPQ R_LEN, R_TMP1
|
||||
JGT errCorrupt
|
||||
|
||||
// copy(dst[d:], src[s:s+length])
|
||||
//
|
||||
// This means calling runtime·memmove(&dst[d], &src[s], length), so we push
|
||||
// R_DST, R_SRC and R_LEN as arguments. Coincidentally, we also need to spill those
|
||||
// three registers to the stack, to save local variables across the CALL.
|
||||
MOVQ R_DST, 0(SP)
|
||||
MOVQ R_SRC, 8(SP)
|
||||
MOVQ R_LEN, 16(SP)
|
||||
MOVQ R_DST, 24(SP)
|
||||
MOVQ R_SRC, 32(SP)
|
||||
MOVQ R_LEN, 40(SP)
|
||||
MOVQ R_OFF, 48(SP)
|
||||
CALL runtime·memmove(SB)
|
||||
|
||||
// Restore local variables: unspill registers from the stack and
|
||||
// re-calculate R_DBASE-R_SEND.
|
||||
MOVQ 24(SP), R_DST
|
||||
MOVQ 32(SP), R_SRC
|
||||
MOVQ 40(SP), R_LEN
|
||||
MOVQ 48(SP), R_OFF
|
||||
MOVQ dst_base+0(FP), R_DBASE
|
||||
MOVQ dst_len+8(FP), R_DLEN
|
||||
MOVQ R_DBASE, R_DEND
|
||||
ADDQ R_DLEN, R_DEND
|
||||
MOVQ src_base+24(FP), R_SBASE
|
||||
MOVQ src_len+32(FP), R_SLEN
|
||||
MOVQ R_SBASE, R_SEND
|
||||
ADDQ R_SLEN, R_SEND
|
||||
|
||||
// d += length
|
||||
// s += length
|
||||
ADDQ R_LEN, R_DST
|
||||
ADDQ R_LEN, R_SRC
|
||||
JMP loop
|
||||
|
||||
tagLit60Plus:
|
||||
// !!! This fragment does the
|
||||
//
|
||||
// s += x - 58; if uint(s) > uint(len(src)) { etc }
|
||||
//
|
||||
// checks. In the asm version, we code it once instead of once per switch case.
|
||||
ADDQ R_LEN, R_SRC
|
||||
SUBQ $58, R_SRC
|
||||
CMPQ R_SRC, R_SEND
|
||||
JA errCorrupt
|
||||
|
||||
// case x == 60:
|
||||
CMPL R_LEN, $61
|
||||
JEQ tagLit61
|
||||
JA tagLit62Plus
|
||||
|
||||
// x = uint32(src[s-1])
|
||||
MOVBLZX -1(R_SRC), R_LEN
|
||||
JMP doLit
|
||||
|
||||
tagLit61:
|
||||
// case x == 61:
|
||||
// x = uint32(src[s-2]) | uint32(src[s-1])<<8
|
||||
MOVWLZX -2(R_SRC), R_LEN
|
||||
JMP doLit
|
||||
|
||||
tagLit62Plus:
|
||||
CMPL R_LEN, $62
|
||||
JA tagLit63
|
||||
|
||||
// case x == 62:
|
||||
// x = uint32(src[s-3]) | uint32(src[s-2])<<8 | uint32(src[s-1])<<16
|
||||
// We read one byte, safe to read one back, since we are just reading tag.
|
||||
// x = binary.LittleEndian.Uint32(src[s-1:]) >> 8
|
||||
MOVL -4(R_SRC), R_LEN
|
||||
SHRL $8, R_LEN
|
||||
JMP doLit
|
||||
|
||||
tagLit63:
|
||||
// case x == 63:
|
||||
// x = uint32(src[s-4]) | uint32(src[s-3])<<8 | uint32(src[s-2])<<16 | uint32(src[s-1])<<24
|
||||
MOVL -4(R_SRC), R_LEN
|
||||
JMP doLit
|
||||
|
||||
// The code above handles literal tags.
|
||||
// ----------------------------------------
|
||||
// The code below handles copy tags.
|
||||
|
||||
tagCopy4:
|
||||
// case tagCopy4:
|
||||
// s += 5
|
||||
ADDQ $5, R_SRC
|
||||
|
||||
// if uint(s) > uint(len(src)) { etc }
|
||||
CMPQ R_SRC, R_SEND
|
||||
JA errCorrupt
|
||||
|
||||
// length = 1 + int(src[s-5])>>2
|
||||
SHRQ $2, R_LEN
|
||||
INCQ R_LEN
|
||||
|
||||
// offset = int(uint32(src[s-4]) | uint32(src[s-3])<<8 | uint32(src[s-2])<<16 | uint32(src[s-1])<<24)
|
||||
MOVLQZX -4(R_SRC), R_OFF
|
||||
JMP doCopy
|
||||
|
||||
tagCopy2:
|
||||
// case tagCopy2:
|
||||
// s += 3
|
||||
ADDQ $3, R_SRC
|
||||
|
||||
// if uint(s) > uint(len(src)) { etc }
|
||||
CMPQ R_SRC, R_SEND
|
||||
JA errCorrupt
|
||||
|
||||
// length = 1 + int(src[s-3])>>2
|
||||
SHRQ $2, R_LEN
|
||||
INCQ R_LEN
|
||||
|
||||
// offset = int(uint32(src[s-2]) | uint32(src[s-1])<<8)
|
||||
MOVWQZX -2(R_SRC), R_OFF
|
||||
JMP doCopy
|
||||
|
||||
tagCopy:
|
||||
// We have a copy tag. We assume that:
|
||||
// - R_TMP1 == src[s] & 0x03
|
||||
// - R_LEN == src[s]
|
||||
CMPQ R_TMP1, $2
|
||||
JEQ tagCopy2
|
||||
JA tagCopy4
|
||||
|
||||
// case tagCopy1:
|
||||
// s += 2
|
||||
ADDQ $2, R_SRC
|
||||
|
||||
// if uint(s) > uint(len(src)) { etc }
|
||||
CMPQ R_SRC, R_SEND
|
||||
JA errCorrupt
|
||||
|
||||
// offset = int(uint32(src[s-2])&0xe0<<3 | uint32(src[s-1]))
|
||||
// length = 4 + int(src[s-2])>>2&0x7
|
||||
MOVBQZX -1(R_SRC), R_TMP1
|
||||
MOVQ R_LEN, R_TMP0
|
||||
SHRQ $2, R_LEN
|
||||
ANDQ $0xe0, R_TMP0
|
||||
ANDQ $7, R_LEN
|
||||
SHLQ $3, R_TMP0
|
||||
ADDQ $4, R_LEN
|
||||
ORQ R_TMP1, R_TMP0
|
||||
|
||||
// check if repeat code, ZF set by ORQ.
|
||||
JZ repeatCode
|
||||
|
||||
// This is a regular copy, transfer our temporary value to R_OFF (length)
|
||||
MOVQ R_TMP0, R_OFF
|
||||
JMP doCopy
|
||||
|
||||
// This is a repeat code.
|
||||
repeatCode:
|
||||
// If length < 9, reuse last offset, with the length already calculated.
|
||||
CMPQ R_LEN, $9
|
||||
JL doCopyRepeat
|
||||
|
||||
// Read additional bytes for length.
|
||||
JE repeatLen1
|
||||
|
||||
// Rare, so the extra branch shouldn't hurt too much.
|
||||
CMPQ R_LEN, $10
|
||||
JE repeatLen2
|
||||
JMP repeatLen3
|
||||
|
||||
// Read repeat lengths.
|
||||
repeatLen1:
|
||||
// s ++
|
||||
ADDQ $1, R_SRC
|
||||
|
||||
// if uint(s) > uint(len(src)) { etc }
|
||||
CMPQ R_SRC, R_SEND
|
||||
JA errCorrupt
|
||||
|
||||
// length = src[s-1] + 8
|
||||
MOVBQZX -1(R_SRC), R_LEN
|
||||
ADDL $8, R_LEN
|
||||
JMP doCopyRepeat
|
||||
|
||||
repeatLen2:
|
||||
// s +=2
|
||||
ADDQ $2, R_SRC
|
||||
|
||||
// if uint(s) > uint(len(src)) { etc }
|
||||
CMPQ R_SRC, R_SEND
|
||||
JA errCorrupt
|
||||
|
||||
// length = uint32(src[s-2]) | (uint32(src[s-1])<<8) + (1 << 8)
|
||||
MOVWQZX -2(R_SRC), R_LEN
|
||||
ADDL $260, R_LEN
|
||||
JMP doCopyRepeat
|
||||
|
||||
repeatLen3:
|
||||
// s +=3
|
||||
ADDQ $3, R_SRC
|
||||
|
||||
// if uint(s) > uint(len(src)) { etc }
|
||||
CMPQ R_SRC, R_SEND
|
||||
JA errCorrupt
|
||||
|
||||
// length = uint32(src[s-3]) | (uint32(src[s-2])<<8) | (uint32(src[s-1])<<16) + (1 << 16)
|
||||
// Read one byte further back (just part of the tag, shifted out)
|
||||
MOVL -4(R_SRC), R_LEN
|
||||
SHRL $8, R_LEN
|
||||
ADDL $65540, R_LEN
|
||||
JMP doCopyRepeat
|
||||
|
||||
doCopy:
|
||||
// This is the end of the outer "switch", when we have a copy tag.
|
||||
//
|
||||
// We assume that:
|
||||
// - R_LEN == length && R_LEN > 0
|
||||
// - R_OFF == offset
|
||||
|
||||
// if d < offset { etc }
|
||||
MOVQ R_DST, R_TMP1
|
||||
SUBQ R_DBASE, R_TMP1
|
||||
CMPQ R_TMP1, R_OFF
|
||||
JLT errCorrupt
|
||||
|
||||
// Repeat values can skip the test above, since any offset > 0 will be in dst.
|
||||
doCopyRepeat:
|
||||
// if offset <= 0 { etc }
|
||||
CMPQ R_OFF, $0
|
||||
JLE errCorrupt
|
||||
|
||||
// if length > len(dst)-d { etc }
|
||||
MOVQ R_DEND, R_TMP1
|
||||
SUBQ R_DST, R_TMP1
|
||||
CMPQ R_LEN, R_TMP1
|
||||
JGT errCorrupt
|
||||
|
||||
// forwardCopy(dst[d:d+length], dst[d-offset:]); d += length
|
||||
//
|
||||
// Set:
|
||||
// - R_TMP2 = len(dst)-d
|
||||
// - R_TMP3 = &dst[d-offset]
|
||||
MOVQ R_DEND, R_TMP2
|
||||
SUBQ R_DST, R_TMP2
|
||||
MOVQ R_DST, R_TMP3
|
||||
SUBQ R_OFF, R_TMP3
|
||||
|
||||
// !!! Try a faster technique for short (16 or fewer bytes) forward copies.
|
||||
//
|
||||
// First, try using two 8-byte load/stores, similar to the doLit technique
|
||||
// above. Even if dst[d:d+length] and dst[d-offset:] can overlap, this is
|
||||
// still OK if offset >= 8. Note that this has to be two 8-byte load/stores
|
||||
// and not one 16-byte load/store, and the first store has to be before the
|
||||
// second load, due to the overlap if offset is in the range [8, 16).
|
||||
//
|
||||
// if length > 16 || offset < 8 || len(dst)-d < 16 {
|
||||
// goto slowForwardCopy
|
||||
// }
|
||||
// copy 16 bytes
|
||||
// d += length
|
||||
CMPQ R_LEN, $16
|
||||
JGT slowForwardCopy
|
||||
CMPQ R_OFF, $8
|
||||
JLT slowForwardCopy
|
||||
CMPQ R_TMP2, $16
|
||||
JLT slowForwardCopy
|
||||
MOVQ 0(R_TMP3), R_TMP0
|
||||
MOVQ R_TMP0, 0(R_DST)
|
||||
MOVQ 8(R_TMP3), R_TMP1
|
||||
MOVQ R_TMP1, 8(R_DST)
|
||||
ADDQ R_LEN, R_DST
|
||||
JMP loop
|
||||
|
||||
slowForwardCopy:
|
||||
// !!! If the forward copy is longer than 16 bytes, or if offset < 8, we
|
||||
// can still try 8-byte load stores, provided we can overrun up to 10 extra
|
||||
// bytes. As above, the overrun will be fixed up by subsequent iterations
|
||||
// of the outermost loop.
|
||||
//
|
||||
// The C++ snappy code calls this technique IncrementalCopyFastPath. Its
|
||||
// commentary says:
|
||||
//
|
||||
// ----
|
||||
//
|
||||
// The main part of this loop is a simple copy of eight bytes at a time
|
||||
// until we've copied (at least) the requested amount of bytes. However,
|
||||
// if d and d-offset are less than eight bytes apart (indicating a
|
||||
// repeating pattern of length < 8), we first need to expand the pattern in
|
||||
// order to get the correct results. For instance, if the buffer looks like
|
||||
// this, with the eight-byte <d-offset> and <d> patterns marked as
|
||||
// intervals:
|
||||
//
|
||||
// abxxxxxxxxxxxx
|
||||
// [------] d-offset
|
||||
// [------] d
|
||||
//
|
||||
// a single eight-byte copy from <d-offset> to <d> will repeat the pattern
|
||||
// once, after which we can move <d> two bytes without moving <d-offset>:
|
||||
//
|
||||
// ababxxxxxxxxxx
|
||||
// [------] d-offset
|
||||
// [------] d
|
||||
//
|
||||
// and repeat the exercise until the two no longer overlap.
|
||||
//
|
||||
// This allows us to do very well in the special case of one single byte
|
||||
// repeated many times, without taking a big hit for more general cases.
|
||||
//
|
||||
// The worst case of extra writing past the end of the match occurs when
|
||||
// offset == 1 and length == 1; the last copy will read from byte positions
|
||||
// [0..7] and write to [4..11], whereas it was only supposed to write to
|
||||
// position 1. Thus, ten excess bytes.
|
||||
//
|
||||
// ----
|
||||
//
|
||||
// That "10 byte overrun" worst case is confirmed by Go's
|
||||
// TestSlowForwardCopyOverrun, which also tests the fixUpSlowForwardCopy
|
||||
// and finishSlowForwardCopy algorithm.
|
||||
//
|
||||
// if length > len(dst)-d-10 {
|
||||
// goto verySlowForwardCopy
|
||||
// }
|
||||
SUBQ $10, R_TMP2
|
||||
CMPQ R_LEN, R_TMP2
|
||||
JGT verySlowForwardCopy
|
||||
|
||||
// We want to keep the offset, so we use R_TMP2 from here.
|
||||
MOVQ R_OFF, R_TMP2
|
||||
|
||||
makeOffsetAtLeast8:
|
||||
// !!! As above, expand the pattern so that offset >= 8 and we can use
|
||||
// 8-byte load/stores.
|
||||
//
|
||||
// for offset < 8 {
|
||||
// copy 8 bytes from dst[d-offset:] to dst[d:]
|
||||
// length -= offset
|
||||
// d += offset
|
||||
// offset += offset
|
||||
// // The two previous lines together means that d-offset, and therefore
|
||||
// // R_TMP3, is unchanged.
|
||||
// }
|
||||
CMPQ R_TMP2, $8
|
||||
JGE fixUpSlowForwardCopy
|
||||
MOVQ (R_TMP3), R_TMP1
|
||||
MOVQ R_TMP1, (R_DST)
|
||||
SUBQ R_TMP2, R_LEN
|
||||
ADDQ R_TMP2, R_DST
|
||||
ADDQ R_TMP2, R_TMP2
|
||||
JMP makeOffsetAtLeast8
|
||||
|
||||
fixUpSlowForwardCopy:
|
||||
// !!! Add length (which might be negative now) to d (implied by R_DST being
|
||||
// &dst[d]) so that d ends up at the right place when we jump back to the
|
||||
// top of the loop. Before we do that, though, we save R_DST to R_TMP0 so that, if
|
||||
// length is positive, copying the remaining length bytes will write to the
|
||||
// right place.
|
||||
MOVQ R_DST, R_TMP0
|
||||
ADDQ R_LEN, R_DST
|
||||
|
||||
finishSlowForwardCopy:
|
||||
// !!! Repeat 8-byte load/stores until length <= 0. Ending with a negative
|
||||
// length means that we overrun, but as above, that will be fixed up by
|
||||
// subsequent iterations of the outermost loop.
|
||||
CMPQ R_LEN, $0
|
||||
JLE loop
|
||||
MOVQ (R_TMP3), R_TMP1
|
||||
MOVQ R_TMP1, (R_TMP0)
|
||||
ADDQ $8, R_TMP3
|
||||
ADDQ $8, R_TMP0
|
||||
SUBQ $8, R_LEN
|
||||
JMP finishSlowForwardCopy
|
||||
|
||||
verySlowForwardCopy:
|
||||
// verySlowForwardCopy is a simple implementation of forward copy. In C
|
||||
// parlance, this is a do/while loop instead of a while loop, since we know
|
||||
// that length > 0. In Go syntax:
|
||||
//
|
||||
// for {
|
||||
// dst[d] = dst[d - offset]
|
||||
// d++
|
||||
// length--
|
||||
// if length == 0 {
|
||||
// break
|
||||
// }
|
||||
// }
|
||||
MOVB (R_TMP3), R_TMP1
|
||||
MOVB R_TMP1, (R_DST)
|
||||
INCQ R_TMP3
|
||||
INCQ R_DST
|
||||
DECQ R_LEN
|
||||
JNZ verySlowForwardCopy
|
||||
JMP loop
|
||||
|
||||
// The code above handles copy tags.
|
||||
// ----------------------------------------
|
||||
|
||||
end:
|
||||
// This is the end of the "for s < len(src)".
|
||||
//
|
||||
// if d != len(dst) { etc }
|
||||
CMPQ R_DST, R_DEND
|
||||
JNE errCorrupt
|
||||
|
||||
// return 0
|
||||
MOVQ $0, ret+48(FP)
|
||||
RET
|
||||
|
||||
errCorrupt:
|
||||
// return decodeErrCodeCorrupt
|
||||
MOVQ $1, ret+48(FP)
|
||||
RET
|
||||
Generated
Vendored
-574
@@ -1,574 +0,0 @@
|
||||
// Copyright 2020 The Go Authors. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
// +build !appengine
|
||||
// +build gc
|
||||
// +build !noasm
|
||||
|
||||
#include "textflag.h"
|
||||
|
||||
#define R_TMP0 R2
|
||||
#define R_TMP1 R3
|
||||
#define R_LEN R4
|
||||
#define R_OFF R5
|
||||
#define R_SRC R6
|
||||
#define R_DST R7
|
||||
#define R_DBASE R8
|
||||
#define R_DLEN R9
|
||||
#define R_DEND R10
|
||||
#define R_SBASE R11
|
||||
#define R_SLEN R12
|
||||
#define R_SEND R13
|
||||
#define R_TMP2 R14
|
||||
#define R_TMP3 R15
|
||||
|
||||
// TEST_SRC will check if R_SRC is <= SRC_END
|
||||
#define TEST_SRC() \
|
||||
CMP R_SEND, R_SRC \
|
||||
BGT errCorrupt
|
||||
|
||||
// MOVD R_SRC, R_TMP1
|
||||
// SUB R_SBASE, R_TMP1, R_TMP1
|
||||
// CMP R_SLEN, R_TMP1
|
||||
// BGT errCorrupt
|
||||
|
||||
// The asm code generally follows the pure Go code in decode_other.go, except
|
||||
// where marked with a "!!!".
|
||||
|
||||
// func decode(dst, src []byte) int
|
||||
//
|
||||
// All local variables fit into registers. The non-zero stack size is only to
|
||||
// spill registers and push args when issuing a CALL. The register allocation:
|
||||
// - R_TMP0 scratch
|
||||
// - R_TMP1 scratch
|
||||
// - R_LEN length or x
|
||||
// - R_OFF offset
|
||||
// - R_SRC &src[s]
|
||||
// - R_DST &dst[d]
|
||||
// + R_DBASE dst_base
|
||||
// + R_DLEN dst_len
|
||||
// + R_DEND dst_base + dst_len
|
||||
// + R_SBASE src_base
|
||||
// + R_SLEN src_len
|
||||
// + R_SEND src_base + src_len
|
||||
// - R_TMP2 used by doCopy
|
||||
// - R_TMP3 used by doCopy
|
||||
//
|
||||
// The registers R_DBASE-R_SEND (marked with a "+") are set at the start of the
|
||||
// function, and after a CALL returns, and are not otherwise modified.
|
||||
//
|
||||
// The d variable is implicitly R_DST - R_DBASE, and len(dst)-d is R_DEND - R_DST.
|
||||
// The s variable is implicitly R_SRC - R_SBASE, and len(src)-s is R_SEND - R_SRC.
|
||||
TEXT ·s2Decode(SB), NOSPLIT, $56-56
|
||||
// Initialize R_SRC, R_DST and R_DBASE-R_SEND.
|
||||
MOVD dst_base+0(FP), R_DBASE
|
||||
MOVD dst_len+8(FP), R_DLEN
|
||||
MOVD R_DBASE, R_DST
|
||||
MOVD R_DBASE, R_DEND
|
||||
ADD R_DLEN, R_DEND, R_DEND
|
||||
MOVD src_base+24(FP), R_SBASE
|
||||
MOVD src_len+32(FP), R_SLEN
|
||||
MOVD R_SBASE, R_SRC
|
||||
MOVD R_SBASE, R_SEND
|
||||
ADD R_SLEN, R_SEND, R_SEND
|
||||
MOVD $0, R_OFF
|
||||
|
||||
loop:
|
||||
// for s < len(src)
|
||||
CMP R_SEND, R_SRC
|
||||
BEQ end
|
||||
|
||||
// R_LEN = uint32(src[s])
|
||||
//
|
||||
// switch src[s] & 0x03
|
||||
MOVBU (R_SRC), R_LEN
|
||||
MOVW R_LEN, R_TMP1
|
||||
ANDW $3, R_TMP1
|
||||
MOVW $1, R1
|
||||
CMPW R1, R_TMP1
|
||||
BGE tagCopy
|
||||
|
||||
// ----------------------------------------
|
||||
// The code below handles literal tags.
|
||||
|
||||
// case tagLiteral:
|
||||
// x := uint32(src[s] >> 2)
|
||||
// switch
|
||||
MOVW $60, R1
|
||||
LSRW $2, R_LEN, R_LEN
|
||||
CMPW R_LEN, R1
|
||||
BLS tagLit60Plus
|
||||
|
||||
// case x < 60:
|
||||
// s++
|
||||
ADD $1, R_SRC, R_SRC
|
||||
|
||||
doLit:
|
||||
// This is the end of the inner "switch", when we have a literal tag.
|
||||
//
|
||||
// We assume that R_LEN == x and x fits in a uint32, where x is the variable
|
||||
// used in the pure Go decode_other.go code.
|
||||
|
||||
// length = int(x) + 1
|
||||
//
|
||||
// Unlike the pure Go code, we don't need to check if length <= 0 because
|
||||
// R_LEN can hold 64 bits, so the increment cannot overflow.
|
||||
ADD $1, R_LEN, R_LEN
|
||||
|
||||
// Prepare to check if copying length bytes will run past the end of dst or
|
||||
// src.
|
||||
//
|
||||
// R_TMP0 = len(dst) - d
|
||||
// R_TMP1 = len(src) - s
|
||||
MOVD R_DEND, R_TMP0
|
||||
SUB R_DST, R_TMP0, R_TMP0
|
||||
MOVD R_SEND, R_TMP1
|
||||
SUB R_SRC, R_TMP1, R_TMP1
|
||||
|
||||
// !!! Try a faster technique for short (16 or fewer bytes) copies.
|
||||
//
|
||||
// if length > 16 || len(dst)-d < 16 || len(src)-s < 16 {
|
||||
// goto callMemmove // Fall back on calling runtime·memmove.
|
||||
// }
|
||||
//
|
||||
// The C++ snappy code calls this TryFastAppend. It also checks len(src)-s
|
||||
// against 21 instead of 16, because it cannot assume that all of its input
|
||||
// is contiguous in memory and so it needs to leave enough source bytes to
|
||||
// read the next tag without refilling buffers, but Go's Decode assumes
|
||||
// contiguousness (the src argument is a []byte).
|
||||
CMP $16, R_LEN
|
||||
BGT callMemmove
|
||||
CMP $16, R_TMP0
|
||||
BLT callMemmove
|
||||
CMP $16, R_TMP1
|
||||
BLT callMemmove
|
||||
|
||||
// !!! Implement the copy from src to dst as a 16-byte load and store.
|
||||
// (Decode's documentation says that dst and src must not overlap.)
|
||||
//
|
||||
// This always copies 16 bytes, instead of only length bytes, but that's
|
||||
// OK. If the input is a valid Snappy encoding then subsequent iterations
|
||||
// will fix up the overrun. Otherwise, Decode returns a nil []byte (and a
|
||||
// non-nil error), so the overrun will be ignored.
|
||||
//
|
||||
// Note that on arm64, it is legal and cheap to issue unaligned 8-byte or
|
||||
// 16-byte loads and stores. This technique probably wouldn't be as
|
||||
// effective on architectures that are fussier about alignment.
|
||||
LDP 0(R_SRC), (R_TMP2, R_TMP3)
|
||||
STP (R_TMP2, R_TMP3), 0(R_DST)
|
||||
|
||||
// d += length
|
||||
// s += length
|
||||
ADD R_LEN, R_DST, R_DST
|
||||
ADD R_LEN, R_SRC, R_SRC
|
||||
B loop
|
||||
|
||||
callMemmove:
|
||||
// if length > len(dst)-d || length > len(src)-s { etc }
|
||||
CMP R_TMP0, R_LEN
|
||||
BGT errCorrupt
|
||||
CMP R_TMP1, R_LEN
|
||||
BGT errCorrupt
|
||||
|
||||
// copy(dst[d:], src[s:s+length])
|
||||
//
|
||||
// This means calling runtime·memmove(&dst[d], &src[s], length), so we push
|
||||
// R_DST, R_SRC and R_LEN as arguments. Coincidentally, we also need to spill those
|
||||
// three registers to the stack, to save local variables across the CALL.
|
||||
MOVD R_DST, 8(RSP)
|
||||
MOVD R_SRC, 16(RSP)
|
||||
MOVD R_LEN, 24(RSP)
|
||||
MOVD R_DST, 32(RSP)
|
||||
MOVD R_SRC, 40(RSP)
|
||||
MOVD R_LEN, 48(RSP)
|
||||
MOVD R_OFF, 56(RSP)
|
||||
CALL runtime·memmove(SB)
|
||||
|
||||
// Restore local variables: unspill registers from the stack and
|
||||
// re-calculate R_DBASE-R_SEND.
|
||||
MOVD 32(RSP), R_DST
|
||||
MOVD 40(RSP), R_SRC
|
||||
MOVD 48(RSP), R_LEN
|
||||
MOVD 56(RSP), R_OFF
|
||||
MOVD dst_base+0(FP), R_DBASE
|
||||
MOVD dst_len+8(FP), R_DLEN
|
||||
MOVD R_DBASE, R_DEND
|
||||
ADD R_DLEN, R_DEND, R_DEND
|
||||
MOVD src_base+24(FP), R_SBASE
|
||||
MOVD src_len+32(FP), R_SLEN
|
||||
MOVD R_SBASE, R_SEND
|
||||
ADD R_SLEN, R_SEND, R_SEND
|
||||
|
||||
// d += length
|
||||
// s += length
|
||||
ADD R_LEN, R_DST, R_DST
|
||||
ADD R_LEN, R_SRC, R_SRC
|
||||
B loop
|
||||
|
||||
tagLit60Plus:
|
||||
// !!! This fragment does the
|
||||
//
|
||||
// s += x - 58; if uint(s) > uint(len(src)) { etc }
|
||||
//
|
||||
// checks. In the asm version, we code it once instead of once per switch case.
|
||||
ADD R_LEN, R_SRC, R_SRC
|
||||
SUB $58, R_SRC, R_SRC
|
||||
TEST_SRC()
|
||||
|
||||
// case x == 60:
|
||||
MOVW $61, R1
|
||||
CMPW R1, R_LEN
|
||||
BEQ tagLit61
|
||||
BGT tagLit62Plus
|
||||
|
||||
// x = uint32(src[s-1])
|
||||
MOVBU -1(R_SRC), R_LEN
|
||||
B doLit
|
||||
|
||||
tagLit61:
|
||||
// case x == 61:
|
||||
// x = uint32(src[s-2]) | uint32(src[s-1])<<8
|
||||
MOVHU -2(R_SRC), R_LEN
|
||||
B doLit
|
||||
|
||||
tagLit62Plus:
|
||||
CMPW $62, R_LEN
|
||||
BHI tagLit63
|
||||
|
||||
// case x == 62:
|
||||
// x = uint32(src[s-3]) | uint32(src[s-2])<<8 | uint32(src[s-1])<<16
|
||||
MOVHU -3(R_SRC), R_LEN
|
||||
MOVBU -1(R_SRC), R_TMP1
|
||||
ORR R_TMP1<<16, R_LEN
|
||||
B doLit
|
||||
|
||||
tagLit63:
|
||||
// case x == 63:
|
||||
// x = uint32(src[s-4]) | uint32(src[s-3])<<8 | uint32(src[s-2])<<16 | uint32(src[s-1])<<24
|
||||
MOVWU -4(R_SRC), R_LEN
|
||||
B doLit
|
||||
|
||||
// The code above handles literal tags.
|
||||
// ----------------------------------------
|
||||
// The code below handles copy tags.
|
||||
|
||||
tagCopy4:
|
||||
// case tagCopy4:
|
||||
// s += 5
|
||||
ADD $5, R_SRC, R_SRC
|
||||
|
||||
// if uint(s) > uint(len(src)) { etc }
|
||||
MOVD R_SRC, R_TMP1
|
||||
SUB R_SBASE, R_TMP1, R_TMP1
|
||||
CMP R_SLEN, R_TMP1
|
||||
BGT errCorrupt
|
||||
|
||||
// length = 1 + int(src[s-5])>>2
|
||||
MOVD $1, R1
|
||||
ADD R_LEN>>2, R1, R_LEN
|
||||
|
||||
// offset = int(uint32(src[s-4]) | uint32(src[s-3])<<8 | uint32(src[s-2])<<16 | uint32(src[s-1])<<24)
|
||||
MOVWU -4(R_SRC), R_OFF
|
||||
B doCopy
|
||||
|
||||
tagCopy2:
|
||||
// case tagCopy2:
|
||||
// s += 3
|
||||
ADD $3, R_SRC, R_SRC
|
||||
|
||||
// if uint(s) > uint(len(src)) { etc }
|
||||
TEST_SRC()
|
||||
|
||||
// length = 1 + int(src[s-3])>>2
|
||||
MOVD $1, R1
|
||||
ADD R_LEN>>2, R1, R_LEN
|
||||
|
||||
// offset = int(uint32(src[s-2]) | uint32(src[s-1])<<8)
|
||||
MOVHU -2(R_SRC), R_OFF
|
||||
B doCopy
|
||||
|
||||
tagCopy:
|
||||
// We have a copy tag. We assume that:
|
||||
// - R_TMP1 == src[s] & 0x03
|
||||
// - R_LEN == src[s]
|
||||
CMP $2, R_TMP1
|
||||
BEQ tagCopy2
|
||||
BGT tagCopy4
|
||||
|
||||
// case tagCopy1:
|
||||
// s += 2
|
||||
ADD $2, R_SRC, R_SRC
|
||||
|
||||
// if uint(s) > uint(len(src)) { etc }
|
||||
TEST_SRC()
|
||||
|
||||
// offset = int(uint32(src[s-2])&0xe0<<3 | uint32(src[s-1]))
|
||||
// Calculate offset in R_TMP0 in case it is a repeat.
|
||||
MOVD R_LEN, R_TMP0
|
||||
AND $0xe0, R_TMP0
|
||||
MOVBU -1(R_SRC), R_TMP1
|
||||
ORR R_TMP0<<3, R_TMP1, R_TMP0
|
||||
|
||||
// length = 4 + int(src[s-2])>>2&0x7
|
||||
MOVD $7, R1
|
||||
AND R_LEN>>2, R1, R_LEN
|
||||
ADD $4, R_LEN, R_LEN
|
||||
|
||||
// check if repeat code with offset 0.
|
||||
CMP $0, R_TMP0
|
||||
BEQ repeatCode
|
||||
|
||||
// This is a regular copy, transfer our temporary value to R_OFF (offset)
|
||||
MOVD R_TMP0, R_OFF
|
||||
B doCopy
|
||||
|
||||
// This is a repeat code.
|
||||
repeatCode:
|
||||
// If length < 9, reuse last offset, with the length already calculated.
|
||||
CMP $9, R_LEN
|
||||
BLT doCopyRepeat
|
||||
BEQ repeatLen1
|
||||
CMP $10, R_LEN
|
||||
BEQ repeatLen2
|
||||
|
||||
repeatLen3:
|
||||
// s +=3
|
||||
ADD $3, R_SRC, R_SRC
|
||||
|
||||
// if uint(s) > uint(len(src)) { etc }
|
||||
TEST_SRC()
|
||||
|
||||
// length = uint32(src[s-3]) | (uint32(src[s-2])<<8) | (uint32(src[s-1])<<16) + 65540
|
||||
MOVBU -1(R_SRC), R_TMP0
|
||||
MOVHU -3(R_SRC), R_LEN
|
||||
ORR R_TMP0<<16, R_LEN, R_LEN
|
||||
ADD $65540, R_LEN, R_LEN
|
||||
B doCopyRepeat
|
||||
|
||||
repeatLen2:
|
||||
// s +=2
|
||||
ADD $2, R_SRC, R_SRC
|
||||
|
||||
// if uint(s) > uint(len(src)) { etc }
|
||||
TEST_SRC()
|
||||
|
||||
// length = uint32(src[s-2]) | (uint32(src[s-1])<<8) + 260
|
||||
MOVHU -2(R_SRC), R_LEN
|
||||
ADD $260, R_LEN, R_LEN
|
||||
B doCopyRepeat
|
||||
|
||||
repeatLen1:
|
||||
// s +=1
|
||||
ADD $1, R_SRC, R_SRC
|
||||
|
||||
// if uint(s) > uint(len(src)) { etc }
|
||||
TEST_SRC()
|
||||
|
||||
// length = src[s-1] + 8
|
||||
MOVBU -1(R_SRC), R_LEN
|
||||
ADD $8, R_LEN, R_LEN
|
||||
B doCopyRepeat
|
||||
|
||||
doCopy:
|
||||
// This is the end of the outer "switch", when we have a copy tag.
|
||||
//
|
||||
// We assume that:
|
||||
// - R_LEN == length && R_LEN > 0
|
||||
// - R_OFF == offset
|
||||
|
||||
// if d < offset { etc }
|
||||
MOVD R_DST, R_TMP1
|
||||
SUB R_DBASE, R_TMP1, R_TMP1
|
||||
CMP R_OFF, R_TMP1
|
||||
BLT errCorrupt
|
||||
|
||||
// Repeat values can skip the test above, since any offset > 0 will be in dst.
|
||||
doCopyRepeat:
|
||||
|
||||
// if offset <= 0 { etc }
|
||||
CMP $0, R_OFF
|
||||
BLE errCorrupt
|
||||
|
||||
// if length > len(dst)-d { etc }
|
||||
MOVD R_DEND, R_TMP1
|
||||
SUB R_DST, R_TMP1, R_TMP1
|
||||
CMP R_TMP1, R_LEN
|
||||
BGT errCorrupt
|
||||
|
||||
// forwardCopy(dst[d:d+length], dst[d-offset:]); d += length
|
||||
//
|
||||
// Set:
|
||||
// - R_TMP2 = len(dst)-d
|
||||
// - R_TMP3 = &dst[d-offset]
|
||||
MOVD R_DEND, R_TMP2
|
||||
SUB R_DST, R_TMP2, R_TMP2
|
||||
MOVD R_DST, R_TMP3
|
||||
SUB R_OFF, R_TMP3, R_TMP3
|
||||
|
||||
// !!! Try a faster technique for short (16 or fewer bytes) forward copies.
|
||||
//
|
||||
// First, try using two 8-byte load/stores, similar to the doLit technique
|
||||
// above. Even if dst[d:d+length] and dst[d-offset:] can overlap, this is
|
||||
// still OK if offset >= 8. Note that this has to be two 8-byte load/stores
|
||||
// and not one 16-byte load/store, and the first store has to be before the
|
||||
// second load, due to the overlap if offset is in the range [8, 16).
|
||||
//
|
||||
// if length > 16 || offset < 8 || len(dst)-d < 16 {
|
||||
// goto slowForwardCopy
|
||||
// }
|
||||
// copy 16 bytes
|
||||
// d += length
|
||||
CMP $16, R_LEN
|
||||
BGT slowForwardCopy
|
||||
CMP $8, R_OFF
|
||||
BLT slowForwardCopy
|
||||
CMP $16, R_TMP2
|
||||
BLT slowForwardCopy
|
||||
MOVD 0(R_TMP3), R_TMP0
|
||||
MOVD R_TMP0, 0(R_DST)
|
||||
MOVD 8(R_TMP3), R_TMP1
|
||||
MOVD R_TMP1, 8(R_DST)
|
||||
ADD R_LEN, R_DST, R_DST
|
||||
B loop
|
||||
|
||||
slowForwardCopy:
|
||||
// !!! If the forward copy is longer than 16 bytes, or if offset < 8, we
|
||||
// can still try 8-byte load stores, provided we can overrun up to 10 extra
|
||||
// bytes. As above, the overrun will be fixed up by subsequent iterations
|
||||
// of the outermost loop.
|
||||
//
|
||||
// The C++ snappy code calls this technique IncrementalCopyFastPath. Its
|
||||
// commentary says:
|
||||
//
|
||||
// ----
|
||||
//
|
||||
// The main part of this loop is a simple copy of eight bytes at a time
|
||||
// until we've copied (at least) the requested amount of bytes. However,
|
||||
// if d and d-offset are less than eight bytes apart (indicating a
|
||||
// repeating pattern of length < 8), we first need to expand the pattern in
|
||||
// order to get the correct results. For instance, if the buffer looks like
|
||||
// this, with the eight-byte <d-offset> and <d> patterns marked as
|
||||
// intervals:
|
||||
//
|
||||
// abxxxxxxxxxxxx
|
||||
// [------] d-offset
|
||||
// [------] d
|
||||
//
|
||||
// a single eight-byte copy from <d-offset> to <d> will repeat the pattern
|
||||
// once, after which we can move <d> two bytes without moving <d-offset>:
|
||||
//
|
||||
// ababxxxxxxxxxx
|
||||
// [------] d-offset
|
||||
// [------] d
|
||||
//
|
||||
// and repeat the exercise until the two no longer overlap.
|
||||
//
|
||||
// This allows us to do very well in the special case of one single byte
|
||||
// repeated many times, without taking a big hit for more general cases.
|
||||
//
|
||||
// The worst case of extra writing past the end of the match occurs when
|
||||
// offset == 1 and length == 1; the last copy will read from byte positions
|
||||
// [0..7] and write to [4..11], whereas it was only supposed to write to
|
||||
// position 1. Thus, ten excess bytes.
|
||||
//
|
||||
// ----
|
||||
//
|
||||
// That "10 byte overrun" worst case is confirmed by Go's
|
||||
// TestSlowForwardCopyOverrun, which also tests the fixUpSlowForwardCopy
|
||||
// and finishSlowForwardCopy algorithm.
|
||||
//
|
||||
// if length > len(dst)-d-10 {
|
||||
// goto verySlowForwardCopy
|
||||
// }
|
||||
SUB $10, R_TMP2, R_TMP2
|
||||
CMP R_TMP2, R_LEN
|
||||
BGT verySlowForwardCopy
|
||||
|
||||
// We want to keep the offset, so we use R_TMP2 from here.
|
||||
MOVD R_OFF, R_TMP2
|
||||
|
||||
makeOffsetAtLeast8:
|
||||
// !!! As above, expand the pattern so that offset >= 8 and we can use
|
||||
// 8-byte load/stores.
|
||||
//
|
||||
// for offset < 8 {
|
||||
// copy 8 bytes from dst[d-offset:] to dst[d:]
|
||||
// length -= offset
|
||||
// d += offset
|
||||
// offset += offset
|
||||
// // The two previous lines together means that d-offset, and therefore
|
||||
// // R_TMP3, is unchanged.
|
||||
// }
|
||||
CMP $8, R_TMP2
|
||||
BGE fixUpSlowForwardCopy
|
||||
MOVD (R_TMP3), R_TMP1
|
||||
MOVD R_TMP1, (R_DST)
|
||||
SUB R_TMP2, R_LEN, R_LEN
|
||||
ADD R_TMP2, R_DST, R_DST
|
||||
ADD R_TMP2, R_TMP2, R_TMP2
|
||||
B makeOffsetAtLeast8
|
||||
|
||||
fixUpSlowForwardCopy:
|
||||
// !!! Add length (which might be negative now) to d (implied by R_DST being
|
||||
// &dst[d]) so that d ends up at the right place when we jump back to the
|
||||
// top of the loop. Before we do that, though, we save R_DST to R_TMP0 so that, if
|
||||
// length is positive, copying the remaining length bytes will write to the
|
||||
// right place.
|
||||
MOVD R_DST, R_TMP0
|
||||
ADD R_LEN, R_DST, R_DST
|
||||
|
||||
finishSlowForwardCopy:
|
||||
// !!! Repeat 8-byte load/stores until length <= 0. Ending with a negative
|
||||
// length means that we overrun, but as above, that will be fixed up by
|
||||
// subsequent iterations of the outermost loop.
|
||||
MOVD $0, R1
|
||||
CMP R1, R_LEN
|
||||
BLE loop
|
||||
MOVD (R_TMP3), R_TMP1
|
||||
MOVD R_TMP1, (R_TMP0)
|
||||
ADD $8, R_TMP3, R_TMP3
|
||||
ADD $8, R_TMP0, R_TMP0
|
||||
SUB $8, R_LEN, R_LEN
|
||||
B finishSlowForwardCopy
|
||||
|
||||
verySlowForwardCopy:
|
||||
// verySlowForwardCopy is a simple implementation of forward copy. In C
|
||||
// parlance, this is a do/while loop instead of a while loop, since we know
|
||||
// that length > 0. In Go syntax:
|
||||
//
|
||||
// for {
|
||||
// dst[d] = dst[d - offset]
|
||||
// d++
|
||||
// length--
|
||||
// if length == 0 {
|
||||
// break
|
||||
// }
|
||||
// }
|
||||
MOVB (R_TMP3), R_TMP1
|
||||
MOVB R_TMP1, (R_DST)
|
||||
ADD $1, R_TMP3, R_TMP3
|
||||
ADD $1, R_DST, R_DST
|
||||
SUB $1, R_LEN, R_LEN
|
||||
CBNZ R_LEN, verySlowForwardCopy
|
||||
B loop
|
||||
|
||||
// The code above handles copy tags.
|
||||
// ----------------------------------------
|
||||
|
||||
end:
|
||||
// This is the end of the "for s < len(src)".
|
||||
//
|
||||
// if d != len(dst) { etc }
|
||||
CMP R_DEND, R_DST
|
||||
BNE errCorrupt
|
||||
|
||||
// return 0
|
||||
MOVD $0, ret+48(FP)
|
||||
RET
|
||||
|
||||
errCorrupt:
|
||||
// return decodeErrCodeCorrupt
|
||||
MOVD $1, R_TMP0
|
||||
MOVD R_TMP0, ret+48(FP)
|
||||
RET
|
||||
Generated
Vendored
-17
@@ -1,17 +0,0 @@
|
||||
// Copyright 2016 The Snappy-Go Authors. All rights reserved.
|
||||
// Copyright (c) 2019 Klaus Post. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
//go:build (amd64 || arm64) && !appengine && gc && !noasm
|
||||
// +build amd64 arm64
|
||||
// +build !appengine
|
||||
// +build gc
|
||||
// +build !noasm
|
||||
|
||||
package s2
|
||||
|
||||
// decode has the same semantics as in decode_other.go.
|
||||
//
|
||||
//go:noescape
|
||||
func s2Decode(dst, src []byte) int
|
||||
Generated
Vendored
-287
@@ -1,287 +0,0 @@
|
||||
// Copyright 2016 The Snappy-Go Authors. All rights reserved.
|
||||
// Copyright (c) 2019 Klaus Post. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
//go:build (!amd64 && !arm64) || appengine || !gc || noasm
|
||||
|
||||
package s2
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"strconv"
|
||||
|
||||
"github.com/klauspost/compress/internal/le"
|
||||
)
|
||||
|
||||
// decode writes the decoding of src to dst. It assumes that the varint-encoded
|
||||
// length of the decompressed bytes has already been read, and that len(dst)
|
||||
// equals that length.
|
||||
//
|
||||
// It returns 0 on success or a decodeErrCodeXxx error code on failure.
|
||||
func s2Decode(dst, src []byte) int {
|
||||
const debug = false
|
||||
if debug {
|
||||
fmt.Println("Starting decode, dst len:", len(dst))
|
||||
}
|
||||
var d, s, length int
|
||||
offset := 0
|
||||
|
||||
// As long as we can read at least 5 bytes...
|
||||
for s < len(src)-5 {
|
||||
// Removing bounds checks is SLOWER, when if doing
|
||||
// in := src[s:s+5]
|
||||
// Checked on Go 1.18
|
||||
switch src[s] & 0x03 {
|
||||
case tagLiteral:
|
||||
x := uint32(src[s] >> 2)
|
||||
switch {
|
||||
case x < 60:
|
||||
s++
|
||||
case x == 60:
|
||||
x = uint32(src[s+1])
|
||||
s += 2
|
||||
case x == 61:
|
||||
x = uint32(le.Load16(src, s+1))
|
||||
s += 3
|
||||
case x == 62:
|
||||
// Load as 32 bit and shift down.
|
||||
x = le.Load32(src, s)
|
||||
x >>= 8
|
||||
s += 4
|
||||
case x == 63:
|
||||
x = le.Load32(src, s+1)
|
||||
s += 5
|
||||
}
|
||||
length = int(x) + 1
|
||||
if length > len(dst)-d || length > len(src)-s || (strconv.IntSize == 32 && length <= 0) {
|
||||
if debug {
|
||||
fmt.Println("corrupt: lit size", length)
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
if debug {
|
||||
fmt.Println("literals, length:", length, "d-after:", d+length)
|
||||
}
|
||||
|
||||
copy(dst[d:], src[s:s+length])
|
||||
d += length
|
||||
s += length
|
||||
continue
|
||||
|
||||
case tagCopy1:
|
||||
s += 2
|
||||
toffset := int(uint32(src[s-2])&0xe0<<3 | uint32(src[s-1]))
|
||||
length = int(src[s-2]) >> 2 & 0x7
|
||||
if toffset == 0 {
|
||||
if debug {
|
||||
fmt.Print("(repeat) ")
|
||||
}
|
||||
// keep last offset
|
||||
switch length {
|
||||
case 5:
|
||||
length = int(src[s]) + 4
|
||||
s += 1
|
||||
case 6:
|
||||
length = int(le.Load16(src, s)) + 1<<8
|
||||
s += 2
|
||||
case 7:
|
||||
in := src[s : s+3]
|
||||
length = int((uint32(in[2])<<16)|(uint32(in[1])<<8)|uint32(in[0])) + (1 << 16)
|
||||
s += 3
|
||||
default: // 0-> 4
|
||||
}
|
||||
} else {
|
||||
offset = toffset
|
||||
}
|
||||
length += 4
|
||||
case tagCopy2:
|
||||
offset = int(le.Load16(src, s+1))
|
||||
length = 1 + int(src[s])>>2
|
||||
s += 3
|
||||
|
||||
case tagCopy4:
|
||||
offset = int(le.Load32(src, s+1))
|
||||
length = 1 + int(src[s])>>2
|
||||
s += 5
|
||||
}
|
||||
|
||||
if offset <= 0 || d < offset || length > len(dst)-d {
|
||||
if debug {
|
||||
fmt.Println("corrupt: match, length", length, "offset:", offset, "dst avail:", len(dst)-d, "dst pos:", d)
|
||||
}
|
||||
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
|
||||
if debug {
|
||||
fmt.Println("copy, length:", length, "offset:", offset, "d-after:", d+length)
|
||||
}
|
||||
|
||||
// Copy from an earlier sub-slice of dst to a later sub-slice.
|
||||
// If no overlap, use the built-in copy:
|
||||
if offset > length {
|
||||
copy(dst[d:d+length], dst[d-offset:])
|
||||
d += length
|
||||
continue
|
||||
}
|
||||
|
||||
// Unlike the built-in copy function, this byte-by-byte copy always runs
|
||||
// forwards, even if the slices overlap. Conceptually, this is:
|
||||
//
|
||||
// d += forwardCopy(dst[d:d+length], dst[d-offset:])
|
||||
//
|
||||
// We align the slices into a and b and show the compiler they are the same size.
|
||||
// This allows the loop to run without bounds checks.
|
||||
a := dst[d : d+length]
|
||||
b := dst[d-offset:]
|
||||
b = b[:len(a)]
|
||||
for i := range a {
|
||||
a[i] = b[i]
|
||||
}
|
||||
d += length
|
||||
}
|
||||
|
||||
// Remaining with extra checks...
|
||||
for s < len(src) {
|
||||
switch src[s] & 0x03 {
|
||||
case tagLiteral:
|
||||
x := uint32(src[s] >> 2)
|
||||
switch {
|
||||
case x < 60:
|
||||
s++
|
||||
case x == 60:
|
||||
s += 2
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
x = uint32(src[s-1])
|
||||
case x == 61:
|
||||
s += 3
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
x = uint32(src[s-2]) | uint32(src[s-1])<<8
|
||||
case x == 62:
|
||||
s += 4
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
x = uint32(src[s-3]) | uint32(src[s-2])<<8 | uint32(src[s-1])<<16
|
||||
case x == 63:
|
||||
s += 5
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
x = uint32(src[s-4]) | uint32(src[s-3])<<8 | uint32(src[s-2])<<16 | uint32(src[s-1])<<24
|
||||
}
|
||||
length = int(x) + 1
|
||||
if length > len(dst)-d || length > len(src)-s || (strconv.IntSize == 32 && length <= 0) {
|
||||
if debug {
|
||||
fmt.Println("corrupt: lit size", length)
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
if debug {
|
||||
fmt.Println("literals, length:", length, "d-after:", d+length)
|
||||
}
|
||||
|
||||
copy(dst[d:], src[s:s+length])
|
||||
d += length
|
||||
s += length
|
||||
continue
|
||||
|
||||
case tagCopy1:
|
||||
s += 2
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
length = int(src[s-2]) >> 2 & 0x7
|
||||
toffset := int(uint32(src[s-2])&0xe0<<3 | uint32(src[s-1]))
|
||||
if toffset == 0 {
|
||||
if debug {
|
||||
fmt.Print("(repeat) ")
|
||||
}
|
||||
// keep last offset
|
||||
switch length {
|
||||
case 5:
|
||||
s += 1
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
length = int(uint32(src[s-1])) + 4
|
||||
case 6:
|
||||
s += 2
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
length = int(uint32(src[s-2])|(uint32(src[s-1])<<8)) + (1 << 8)
|
||||
case 7:
|
||||
s += 3
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
length = int(uint32(src[s-3])|(uint32(src[s-2])<<8)|(uint32(src[s-1])<<16)) + (1 << 16)
|
||||
default: // 0-> 4
|
||||
}
|
||||
} else {
|
||||
offset = toffset
|
||||
}
|
||||
length += 4
|
||||
case tagCopy2:
|
||||
s += 3
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
length = 1 + int(src[s-3])>>2
|
||||
offset = int(uint32(src[s-2]) | uint32(src[s-1])<<8)
|
||||
|
||||
case tagCopy4:
|
||||
s += 5
|
||||
if uint(s) > uint(len(src)) { // The uint conversions catch overflow from the previous line.
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
length = 1 + int(src[s-5])>>2
|
||||
offset = int(uint32(src[s-4]) | uint32(src[s-3])<<8 | uint32(src[s-2])<<16 | uint32(src[s-1])<<24)
|
||||
}
|
||||
|
||||
if offset <= 0 || d < offset || length > len(dst)-d {
|
||||
if debug {
|
||||
fmt.Println("corrupt: match, length", length, "offset:", offset, "dst avail:", len(dst)-d, "dst pos:", d)
|
||||
}
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
|
||||
if debug {
|
||||
fmt.Println("copy, length:", length, "offset:", offset, "d-after:", d+length)
|
||||
}
|
||||
|
||||
// Copy from an earlier sub-slice of dst to a later sub-slice.
|
||||
// If no overlap, use the built-in copy:
|
||||
if offset > length {
|
||||
copy(dst[d:d+length], dst[d-offset:])
|
||||
d += length
|
||||
continue
|
||||
}
|
||||
|
||||
// Unlike the built-in copy function, this byte-by-byte copy always runs
|
||||
// forwards, even if the slices overlap. Conceptually, this is:
|
||||
//
|
||||
// d += forwardCopy(dst[d:d+length], dst[d-offset:])
|
||||
//
|
||||
// We align the slices into a and b and show the compiler they are the same size.
|
||||
// This allows the loop to run without bounds checks.
|
||||
a := dst[d : d+length]
|
||||
b := dst[d-offset:]
|
||||
b = b[:len(a)]
|
||||
for i := range a {
|
||||
a[i] = b[i]
|
||||
}
|
||||
d += length
|
||||
}
|
||||
|
||||
if d != len(dst) {
|
||||
return decodeErrCodeCorrupt
|
||||
}
|
||||
return 0
|
||||
}
|
||||
Generated
Vendored
-352
@@ -1,352 +0,0 @@
|
||||
// Copyright (c) 2022+ Klaus Post. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package s2
|
||||
|
||||
import (
|
||||
"bytes"
|
||||
"encoding/binary"
|
||||
"sync"
|
||||
)
|
||||
|
||||
const (
|
||||
// MinDictSize is the minimum dictionary size when repeat has been read.
|
||||
MinDictSize = 16
|
||||
|
||||
// MaxDictSize is the maximum dictionary size when repeat has been read.
|
||||
MaxDictSize = 65536
|
||||
|
||||
// MaxDictSrcOffset is the maximum offset where a dictionary entry can start.
|
||||
MaxDictSrcOffset = 65535
|
||||
)
|
||||
|
||||
// Dict contains a dictionary that can be used for encoding and decoding s2
|
||||
type Dict struct {
|
||||
dict []byte
|
||||
repeat int // Repeat as index of dict
|
||||
|
||||
fast, better, best sync.Once
|
||||
fastTable *[1 << 14]uint16
|
||||
|
||||
betterTableShort *[1 << 14]uint16
|
||||
betterTableLong *[1 << 17]uint16
|
||||
|
||||
bestTableShort *[1 << 16]uint32
|
||||
bestTableLong *[1 << 19]uint32
|
||||
}
|
||||
|
||||
// NewDict will read a dictionary.
|
||||
// It will return nil if the dictionary is invalid.
|
||||
func NewDict(dict []byte) *Dict {
|
||||
if len(dict) == 0 {
|
||||
return nil
|
||||
}
|
||||
var d Dict
|
||||
// Repeat is the first value of the dict
|
||||
r, n := binary.Uvarint(dict)
|
||||
if n <= 0 {
|
||||
return nil
|
||||
}
|
||||
dict = dict[n:]
|
||||
d.dict = dict
|
||||
if cap(d.dict) < len(d.dict)+16 {
|
||||
d.dict = append(make([]byte, 0, len(d.dict)+16), d.dict...)
|
||||
}
|
||||
if len(dict) < MinDictSize || len(dict) > MaxDictSize {
|
||||
return nil
|
||||
}
|
||||
// Compare as uint64: int(r) would wrap negative for r > MaxInt64,
|
||||
// slipping past the bounds check and causing an OOB read in encode.
|
||||
if r > uint64(len(dict)) {
|
||||
return nil
|
||||
}
|
||||
d.repeat = int(r)
|
||||
return &d
|
||||
}
|
||||
|
||||
// Bytes will return a serialized version of the dictionary.
|
||||
// The output can be sent to NewDict.
|
||||
func (d *Dict) Bytes() []byte {
|
||||
dst := make([]byte, binary.MaxVarintLen16+len(d.dict))
|
||||
return append(dst[:binary.PutUvarint(dst, uint64(d.repeat))], d.dict...)
|
||||
}
|
||||
|
||||
// MakeDict will create a dictionary.
|
||||
// 'data' must be at least MinDictSize.
|
||||
// If data is longer than MaxDictSize only the last MaxDictSize bytes will be used.
|
||||
// If searchStart is set the start repeat value will be set to the last
|
||||
// match of this content.
|
||||
// If no matches are found, it will attempt to find shorter matches.
|
||||
// This content should match the typical start of a block.
|
||||
// If at least 4 bytes cannot be matched, repeat is set to start of block.
|
||||
func MakeDict(data []byte, searchStart []byte) *Dict {
|
||||
if len(data) == 0 {
|
||||
return nil
|
||||
}
|
||||
if len(data) > MaxDictSize {
|
||||
data = data[len(data)-MaxDictSize:]
|
||||
}
|
||||
var d Dict
|
||||
dict := data
|
||||
d.dict = dict
|
||||
if cap(d.dict) < len(d.dict)+16 {
|
||||
d.dict = append(make([]byte, 0, len(d.dict)+16), d.dict...)
|
||||
}
|
||||
if len(dict) < MinDictSize {
|
||||
return nil
|
||||
}
|
||||
|
||||
// Find the longest match possible, last entry if multiple.
|
||||
for s := len(searchStart); s > 4; s-- {
|
||||
if idx := bytes.LastIndex(data, searchStart[:s]); idx >= 0 && idx <= len(data)-8 {
|
||||
d.repeat = idx
|
||||
break
|
||||
}
|
||||
}
|
||||
|
||||
return &d
|
||||
}
|
||||
|
||||
// MakeDictManual will create a dictionary.
|
||||
// 'data' must be at least MinDictSize and less than or equal to MaxDictSize.
|
||||
// A manual first repeat index into data must be provided.
|
||||
// It must be less than len(data)-8.
|
||||
func MakeDictManual(data []byte, firstIdx uint16) *Dict {
|
||||
if len(data) < MinDictSize || int(firstIdx) >= len(data)-8 || len(data) > MaxDictSize {
|
||||
return nil
|
||||
}
|
||||
var d Dict
|
||||
dict := data
|
||||
d.dict = dict
|
||||
if cap(d.dict) < len(d.dict)+16 {
|
||||
d.dict = append(make([]byte, 0, len(d.dict)+16), d.dict...)
|
||||
}
|
||||
|
||||
d.repeat = int(firstIdx)
|
||||
return &d
|
||||
}
|
||||
|
||||
// Encode returns the encoded form of src. The returned slice may be a sub-
|
||||
// slice of dst if dst was large enough to hold the entire encoded block.
|
||||
// Otherwise, a newly allocated slice will be returned.
|
||||
//
|
||||
// The dst and src must not overlap. It is valid to pass a nil dst.
|
||||
//
|
||||
// The blocks will require the same amount of memory to decode as encoding,
|
||||
// and does not make for concurrent decoding.
|
||||
// Also note that blocks do not contain CRC information, so corruption may be undetected.
|
||||
//
|
||||
// If you need to encode larger amounts of data, consider using
|
||||
// the streaming interface which gives all of these features.
|
||||
func (d *Dict) Encode(dst, src []byte) []byte {
|
||||
if n := MaxEncodedLen(len(src)); n < 0 {
|
||||
panic(ErrTooLarge)
|
||||
} else if cap(dst) < n {
|
||||
dst = make([]byte, n)
|
||||
} else {
|
||||
dst = dst[:n]
|
||||
}
|
||||
|
||||
// The block starts with the varint-encoded length of the decompressed bytes.
|
||||
dstP := binary.PutUvarint(dst, uint64(len(src)))
|
||||
|
||||
if len(src) == 0 {
|
||||
return dst[:dstP]
|
||||
}
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
dstP += emitLiteral(dst[dstP:], src)
|
||||
return dst[:dstP]
|
||||
}
|
||||
n := encodeBlockDictGo(dst[dstP:], src, d)
|
||||
if n > 0 {
|
||||
dstP += n
|
||||
return dst[:dstP]
|
||||
}
|
||||
// Not compressible
|
||||
dstP += emitLiteral(dst[dstP:], src)
|
||||
return dst[:dstP]
|
||||
}
|
||||
|
||||
// EncodeBetter returns the encoded form of src. The returned slice may be a sub-
|
||||
// slice of dst if dst was large enough to hold the entire encoded block.
|
||||
// Otherwise, a newly allocated slice will be returned.
|
||||
//
|
||||
// EncodeBetter compresses better than Encode but typically with a
|
||||
// 10-40% speed decrease on both compression and decompression.
|
||||
//
|
||||
// The dst and src must not overlap. It is valid to pass a nil dst.
|
||||
//
|
||||
// The blocks will require the same amount of memory to decode as encoding,
|
||||
// and does not make for concurrent decoding.
|
||||
// Also note that blocks do not contain CRC information, so corruption may be undetected.
|
||||
//
|
||||
// If you need to encode larger amounts of data, consider using
|
||||
// the streaming interface which gives all of these features.
|
||||
func (d *Dict) EncodeBetter(dst, src []byte) []byte {
|
||||
if n := MaxEncodedLen(len(src)); n < 0 {
|
||||
panic(ErrTooLarge)
|
||||
} else if len(dst) < n {
|
||||
dst = make([]byte, n)
|
||||
}
|
||||
|
||||
// The block starts with the varint-encoded length of the decompressed bytes.
|
||||
dstP := binary.PutUvarint(dst, uint64(len(src)))
|
||||
|
||||
if len(src) == 0 {
|
||||
return dst[:dstP]
|
||||
}
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
dstP += emitLiteral(dst[dstP:], src)
|
||||
return dst[:dstP]
|
||||
}
|
||||
n := encodeBlockBetterDict(dst[dstP:], src, d)
|
||||
if n > 0 {
|
||||
dstP += n
|
||||
return dst[:dstP]
|
||||
}
|
||||
// Not compressible
|
||||
dstP += emitLiteral(dst[dstP:], src)
|
||||
return dst[:dstP]
|
||||
}
|
||||
|
||||
// EncodeBest returns the encoded form of src. The returned slice may be a sub-
|
||||
// slice of dst if dst was large enough to hold the entire encoded block.
|
||||
// Otherwise, a newly allocated slice will be returned.
|
||||
//
|
||||
// EncodeBest compresses as good as reasonably possible but with a
|
||||
// big speed decrease.
|
||||
//
|
||||
// The dst and src must not overlap. It is valid to pass a nil dst.
|
||||
//
|
||||
// The blocks will require the same amount of memory to decode as encoding,
|
||||
// and does not make for concurrent decoding.
|
||||
// Also note that blocks do not contain CRC information, so corruption may be undetected.
|
||||
//
|
||||
// If you need to encode larger amounts of data, consider using
|
||||
// the streaming interface which gives all of these features.
|
||||
func (d *Dict) EncodeBest(dst, src []byte) []byte {
|
||||
if n := MaxEncodedLen(len(src)); n < 0 {
|
||||
panic(ErrTooLarge)
|
||||
} else if len(dst) < n {
|
||||
dst = make([]byte, n)
|
||||
}
|
||||
|
||||
// The block starts with the varint-encoded length of the decompressed bytes.
|
||||
dstP := binary.PutUvarint(dst, uint64(len(src)))
|
||||
|
||||
if len(src) == 0 {
|
||||
return dst[:dstP]
|
||||
}
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
dstP += emitLiteral(dst[dstP:], src)
|
||||
return dst[:dstP]
|
||||
}
|
||||
n := encodeBlockBest(dst[dstP:], src, d)
|
||||
if n > 0 {
|
||||
dstP += n
|
||||
return dst[:dstP]
|
||||
}
|
||||
// Not compressible
|
||||
dstP += emitLiteral(dst[dstP:], src)
|
||||
return dst[:dstP]
|
||||
}
|
||||
|
||||
// Decode returns the decoded form of src. The returned slice may be a sub-
|
||||
// slice of dst if dst was large enough to hold the entire decoded block.
|
||||
// Otherwise, a newly allocated slice will be returned.
|
||||
//
|
||||
// The dst and src must not overlap. It is valid to pass a nil dst.
|
||||
func (d *Dict) Decode(dst, src []byte) ([]byte, error) {
|
||||
dLen, s, err := decodedLen(src)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
if dLen <= cap(dst) {
|
||||
dst = dst[:dLen]
|
||||
} else {
|
||||
dst = make([]byte, dLen)
|
||||
}
|
||||
if s2DecodeDict(dst, src[s:], d) != 0 {
|
||||
return nil, ErrCorrupt
|
||||
}
|
||||
return dst, nil
|
||||
}
|
||||
|
||||
func (d *Dict) initFast() {
|
||||
d.fast.Do(func() {
|
||||
const (
|
||||
tableBits = 14
|
||||
maxTableSize = 1 << tableBits
|
||||
)
|
||||
|
||||
var table [maxTableSize]uint16
|
||||
// We stop so any entry of length 8 can always be read.
|
||||
for i := 0; i < len(d.dict)-8-2; i += 3 {
|
||||
x0 := load64(d.dict, i)
|
||||
h0 := hash6(x0, tableBits)
|
||||
h1 := hash6(x0>>8, tableBits)
|
||||
h2 := hash6(x0>>16, tableBits)
|
||||
table[h0] = uint16(i)
|
||||
table[h1] = uint16(i + 1)
|
||||
table[h2] = uint16(i + 2)
|
||||
}
|
||||
d.fastTable = &table
|
||||
})
|
||||
}
|
||||
|
||||
func (d *Dict) initBetter() {
|
||||
d.better.Do(func() {
|
||||
const (
|
||||
// Long hash matches.
|
||||
lTableBits = 17
|
||||
maxLTableSize = 1 << lTableBits
|
||||
|
||||
// Short hash matches.
|
||||
sTableBits = 14
|
||||
maxSTableSize = 1 << sTableBits
|
||||
)
|
||||
|
||||
var lTable [maxLTableSize]uint16
|
||||
var sTable [maxSTableSize]uint16
|
||||
|
||||
// We stop so any entry of length 8 can always be read.
|
||||
for i := 0; i < len(d.dict)-8; i++ {
|
||||
cv := load64(d.dict, i)
|
||||
lTable[hash7(cv, lTableBits)] = uint16(i)
|
||||
sTable[hash4(cv, sTableBits)] = uint16(i)
|
||||
}
|
||||
d.betterTableShort = &sTable
|
||||
d.betterTableLong = &lTable
|
||||
})
|
||||
}
|
||||
|
||||
func (d *Dict) initBest() {
|
||||
d.best.Do(func() {
|
||||
const (
|
||||
// Long hash matches.
|
||||
lTableBits = 19
|
||||
maxLTableSize = 1 << lTableBits
|
||||
|
||||
// Short hash matches.
|
||||
sTableBits = 16
|
||||
maxSTableSize = 1 << sTableBits
|
||||
)
|
||||
|
||||
var lTable [maxLTableSize]uint32
|
||||
var sTable [maxSTableSize]uint32
|
||||
|
||||
// We stop so any entry of length 8 can always be read.
|
||||
for i := 0; i < len(d.dict)-8; i++ {
|
||||
cv := load64(d.dict, i)
|
||||
hashL := hash8(cv, lTableBits)
|
||||
hashS := hash4(cv, sTableBits)
|
||||
candidateL := lTable[hashL]
|
||||
candidateS := sTable[hashS]
|
||||
lTable[hashL] = uint32(i) | candidateL<<16
|
||||
sTable[hashS] = uint32(i) | candidateS<<16
|
||||
}
|
||||
d.bestTableShort = &sTable
|
||||
d.bestTableLong = &lTable
|
||||
})
|
||||
}
|
||||
Generated
Vendored
-418
@@ -1,418 +0,0 @@
|
||||
// Copyright 2011 The Snappy-Go Authors. All rights reserved.
|
||||
// Copyright (c) 2019 Klaus Post. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package s2
|
||||
|
||||
import (
|
||||
"encoding/binary"
|
||||
"math"
|
||||
"math/bits"
|
||||
"sync"
|
||||
|
||||
"github.com/klauspost/compress/internal/race"
|
||||
)
|
||||
|
||||
// Encode returns the encoded form of src. The returned slice may be a sub-
|
||||
// slice of dst if dst was large enough to hold the entire encoded block.
|
||||
// Otherwise, a newly allocated slice will be returned.
|
||||
//
|
||||
// The dst and src must not overlap. It is valid to pass a nil dst.
|
||||
//
|
||||
// The blocks will require the same amount of memory to decode as encoding,
|
||||
// and does not make for concurrent decoding.
|
||||
// Also note that blocks do not contain CRC information, so corruption may be undetected.
|
||||
//
|
||||
// If you need to encode larger amounts of data, consider using
|
||||
// the streaming interface which gives all of these features.
|
||||
func Encode(dst, src []byte) []byte {
|
||||
if n := MaxEncodedLen(len(src)); n < 0 {
|
||||
panic(ErrTooLarge)
|
||||
} else if cap(dst) < n {
|
||||
dst = make([]byte, n)
|
||||
} else {
|
||||
dst = dst[:n]
|
||||
}
|
||||
|
||||
// The block starts with the varint-encoded length of the decompressed bytes.
|
||||
d := binary.PutUvarint(dst, uint64(len(src)))
|
||||
|
||||
if len(src) == 0 {
|
||||
return dst[:d]
|
||||
}
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
d += emitLiteral(dst[d:], src)
|
||||
return dst[:d]
|
||||
}
|
||||
n := encodeBlock(dst[d:], src)
|
||||
if n > 0 {
|
||||
d += n
|
||||
return dst[:d]
|
||||
}
|
||||
// Not compressible
|
||||
d += emitLiteral(dst[d:], src)
|
||||
return dst[:d]
|
||||
}
|
||||
|
||||
var estblockPool [2]sync.Pool
|
||||
|
||||
// EstimateBlockSize will perform a very fast compression
|
||||
// without outputting the result and return the compressed output size.
|
||||
// The function returns -1 if no improvement could be achieved.
|
||||
// Using actual compression will most often produce better compression than the estimate.
|
||||
func EstimateBlockSize(src []byte) (d int) {
|
||||
if len(src) <= inputMargin || int64(len(src)) > 0xffffffff {
|
||||
return -1
|
||||
}
|
||||
if len(src) <= 1024 {
|
||||
const sz, pool = 2048, 0
|
||||
tmp, ok := estblockPool[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer estblockPool[pool].Put(tmp)
|
||||
|
||||
d = calcBlockSizeSmall(src, tmp)
|
||||
} else {
|
||||
const sz, pool = 32768, 1
|
||||
tmp, ok := estblockPool[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer estblockPool[pool].Put(tmp)
|
||||
|
||||
d = calcBlockSize(src, tmp)
|
||||
}
|
||||
|
||||
if d == 0 {
|
||||
return -1
|
||||
}
|
||||
// Size of the varint encoded block size.
|
||||
d += (bits.Len64(uint64(len(src))) + 7) / 7
|
||||
|
||||
if d >= len(src) {
|
||||
return -1
|
||||
}
|
||||
return d
|
||||
}
|
||||
|
||||
// EncodeBetter returns the encoded form of src. The returned slice may be a sub-
|
||||
// slice of dst if dst was large enough to hold the entire encoded block.
|
||||
// Otherwise, a newly allocated slice will be returned.
|
||||
//
|
||||
// EncodeBetter compresses better than Encode but typically with a
|
||||
// 10-40% speed decrease on both compression and decompression.
|
||||
//
|
||||
// The dst and src must not overlap. It is valid to pass a nil dst.
|
||||
//
|
||||
// The blocks will require the same amount of memory to decode as encoding,
|
||||
// and does not make for concurrent decoding.
|
||||
// Also note that blocks do not contain CRC information, so corruption may be undetected.
|
||||
//
|
||||
// If you need to encode larger amounts of data, consider using
|
||||
// the streaming interface which gives all of these features.
|
||||
func EncodeBetter(dst, src []byte) []byte {
|
||||
if n := MaxEncodedLen(len(src)); n < 0 {
|
||||
panic(ErrTooLarge)
|
||||
} else if cap(dst) < n {
|
||||
dst = make([]byte, n)
|
||||
} else {
|
||||
dst = dst[:n]
|
||||
}
|
||||
|
||||
// The block starts with the varint-encoded length of the decompressed bytes.
|
||||
d := binary.PutUvarint(dst, uint64(len(src)))
|
||||
|
||||
if len(src) == 0 {
|
||||
return dst[:d]
|
||||
}
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
d += emitLiteral(dst[d:], src)
|
||||
return dst[:d]
|
||||
}
|
||||
n := encodeBlockBetter(dst[d:], src)
|
||||
if n > 0 {
|
||||
d += n
|
||||
return dst[:d]
|
||||
}
|
||||
// Not compressible
|
||||
d += emitLiteral(dst[d:], src)
|
||||
return dst[:d]
|
||||
}
|
||||
|
||||
// EncodeBest returns the encoded form of src. The returned slice may be a sub-
|
||||
// slice of dst if dst was large enough to hold the entire encoded block.
|
||||
// Otherwise, a newly allocated slice will be returned.
|
||||
//
|
||||
// EncodeBest compresses as good as reasonably possible but with a
|
||||
// big speed decrease.
|
||||
//
|
||||
// The dst and src must not overlap. It is valid to pass a nil dst.
|
||||
//
|
||||
// The blocks will require the same amount of memory to decode as encoding,
|
||||
// and does not make for concurrent decoding.
|
||||
// Also note that blocks do not contain CRC information, so corruption may be undetected.
|
||||
//
|
||||
// If you need to encode larger amounts of data, consider using
|
||||
// the streaming interface which gives all of these features.
|
||||
func EncodeBest(dst, src []byte) []byte {
|
||||
if n := MaxEncodedLen(len(src)); n < 0 {
|
||||
panic(ErrTooLarge)
|
||||
} else if cap(dst) < n {
|
||||
dst = make([]byte, n)
|
||||
} else {
|
||||
dst = dst[:n]
|
||||
}
|
||||
|
||||
// The block starts with the varint-encoded length of the decompressed bytes.
|
||||
d := binary.PutUvarint(dst, uint64(len(src)))
|
||||
|
||||
if len(src) == 0 {
|
||||
return dst[:d]
|
||||
}
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
d += emitLiteral(dst[d:], src)
|
||||
return dst[:d]
|
||||
}
|
||||
n := encodeBlockBest(dst[d:], src, nil)
|
||||
if n > 0 {
|
||||
d += n
|
||||
return dst[:d]
|
||||
}
|
||||
// Not compressible
|
||||
d += emitLiteral(dst[d:], src)
|
||||
return dst[:d]
|
||||
}
|
||||
|
||||
// EncodeSnappy returns the encoded form of src. The returned slice may be a sub-
|
||||
// slice of dst if dst was large enough to hold the entire encoded block.
|
||||
// Otherwise, a newly allocated slice will be returned.
|
||||
//
|
||||
// The output is Snappy compatible and will likely decompress faster.
|
||||
//
|
||||
// The dst and src must not overlap. It is valid to pass a nil dst.
|
||||
//
|
||||
// The blocks will require the same amount of memory to decode as encoding,
|
||||
// and does not make for concurrent decoding.
|
||||
// Also note that blocks do not contain CRC information, so corruption may be undetected.
|
||||
//
|
||||
// If you need to encode larger amounts of data, consider using
|
||||
// the streaming interface which gives all of these features.
|
||||
func EncodeSnappy(dst, src []byte) []byte {
|
||||
if n := MaxEncodedLen(len(src)); n < 0 {
|
||||
panic(ErrTooLarge)
|
||||
} else if cap(dst) < n {
|
||||
dst = make([]byte, n)
|
||||
} else {
|
||||
dst = dst[:n]
|
||||
}
|
||||
|
||||
// The block starts with the varint-encoded length of the decompressed bytes.
|
||||
d := binary.PutUvarint(dst, uint64(len(src)))
|
||||
|
||||
if len(src) == 0 {
|
||||
return dst[:d]
|
||||
}
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
d += emitLiteral(dst[d:], src)
|
||||
return dst[:d]
|
||||
}
|
||||
|
||||
n := encodeBlockSnappy(dst[d:], src)
|
||||
if n > 0 {
|
||||
d += n
|
||||
return dst[:d]
|
||||
}
|
||||
// Not compressible
|
||||
d += emitLiteral(dst[d:], src)
|
||||
return dst[:d]
|
||||
}
|
||||
|
||||
// EncodeSnappyBetter returns the encoded form of src. The returned slice may be a sub-
|
||||
// slice of dst if dst was large enough to hold the entire encoded block.
|
||||
// Otherwise, a newly allocated slice will be returned.
|
||||
//
|
||||
// The output is Snappy compatible and will likely decompress faster.
|
||||
//
|
||||
// The dst and src must not overlap. It is valid to pass a nil dst.
|
||||
//
|
||||
// The blocks will require the same amount of memory to decode as encoding,
|
||||
// and does not make for concurrent decoding.
|
||||
// Also note that blocks do not contain CRC information, so corruption may be undetected.
|
||||
//
|
||||
// If you need to encode larger amounts of data, consider using
|
||||
// the streaming interface which gives all of these features.
|
||||
func EncodeSnappyBetter(dst, src []byte) []byte {
|
||||
if n := MaxEncodedLen(len(src)); n < 0 {
|
||||
panic(ErrTooLarge)
|
||||
} else if cap(dst) < n {
|
||||
dst = make([]byte, n)
|
||||
} else {
|
||||
dst = dst[:n]
|
||||
}
|
||||
|
||||
// The block starts with the varint-encoded length of the decompressed bytes.
|
||||
d := binary.PutUvarint(dst, uint64(len(src)))
|
||||
|
||||
if len(src) == 0 {
|
||||
return dst[:d]
|
||||
}
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
d += emitLiteral(dst[d:], src)
|
||||
return dst[:d]
|
||||
}
|
||||
|
||||
n := encodeBlockBetterSnappy(dst[d:], src)
|
||||
if n > 0 {
|
||||
d += n
|
||||
return dst[:d]
|
||||
}
|
||||
// Not compressible
|
||||
d += emitLiteral(dst[d:], src)
|
||||
return dst[:d]
|
||||
}
|
||||
|
||||
// EncodeSnappyBest returns the encoded form of src. The returned slice may be a sub-
|
||||
// slice of dst if dst was large enough to hold the entire encoded block.
|
||||
// Otherwise, a newly allocated slice will be returned.
|
||||
//
|
||||
// The output is Snappy compatible and will likely decompress faster.
|
||||
//
|
||||
// The dst and src must not overlap. It is valid to pass a nil dst.
|
||||
//
|
||||
// The blocks will require the same amount of memory to decode as encoding,
|
||||
// and does not make for concurrent decoding.
|
||||
// Also note that blocks do not contain CRC information, so corruption may be undetected.
|
||||
//
|
||||
// If you need to encode larger amounts of data, consider using
|
||||
// the streaming interface which gives all of these features.
|
||||
func EncodeSnappyBest(dst, src []byte) []byte {
|
||||
if n := MaxEncodedLen(len(src)); n < 0 {
|
||||
panic(ErrTooLarge)
|
||||
} else if cap(dst) < n {
|
||||
dst = make([]byte, n)
|
||||
} else {
|
||||
dst = dst[:n]
|
||||
}
|
||||
|
||||
// The block starts with the varint-encoded length of the decompressed bytes.
|
||||
d := binary.PutUvarint(dst, uint64(len(src)))
|
||||
|
||||
if len(src) == 0 {
|
||||
return dst[:d]
|
||||
}
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
d += emitLiteral(dst[d:], src)
|
||||
return dst[:d]
|
||||
}
|
||||
|
||||
n := encodeBlockBestSnappy(dst[d:], src)
|
||||
if n > 0 {
|
||||
d += n
|
||||
return dst[:d]
|
||||
}
|
||||
// Not compressible
|
||||
d += emitLiteral(dst[d:], src)
|
||||
return dst[:d]
|
||||
}
|
||||
|
||||
// ConcatBlocks will concatenate the supplied blocks and append them to the supplied destination.
|
||||
// If the destination is nil or too small, a new will be allocated.
|
||||
// The blocks are not validated, so garbage in = garbage out.
|
||||
// dst may not overlap block data.
|
||||
// Any data in dst is preserved as is, so it will not be considered a block.
|
||||
func ConcatBlocks(dst []byte, blocks ...[]byte) ([]byte, error) {
|
||||
totalSize := uint64(0)
|
||||
compSize := 0
|
||||
for _, b := range blocks {
|
||||
l, hdr, err := decodedLen(b)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
totalSize += uint64(l)
|
||||
compSize += len(b) - hdr
|
||||
}
|
||||
if totalSize == 0 {
|
||||
dst = append(dst, 0)
|
||||
return dst, nil
|
||||
}
|
||||
if totalSize > math.MaxUint32 {
|
||||
return nil, ErrTooLarge
|
||||
}
|
||||
var tmp [binary.MaxVarintLen32]byte
|
||||
hdrSize := binary.PutUvarint(tmp[:], totalSize)
|
||||
wantSize := hdrSize + compSize
|
||||
|
||||
if cap(dst)-len(dst) < wantSize {
|
||||
dst = append(make([]byte, 0, wantSize+len(dst)), dst...)
|
||||
}
|
||||
dst = append(dst, tmp[:hdrSize]...)
|
||||
for _, b := range blocks {
|
||||
_, hdr, err := decodedLen(b)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
dst = append(dst, b[hdr:]...)
|
||||
}
|
||||
return dst, nil
|
||||
}
|
||||
|
||||
// inputMargin is the minimum number of extra input bytes to keep, inside
|
||||
// encodeBlock's inner loop. On some architectures, this margin lets us
|
||||
// implement a fast path for emitLiteral, where the copy of short (<= 16 byte)
|
||||
// literals can be implemented as a single load to and store from a 16-byte
|
||||
// register. That literal's actual length can be as short as 1 byte, so this
|
||||
// can copy up to 15 bytes too much, but that's OK as subsequent iterations of
|
||||
// the encoding loop will fix up the copy overrun, and this inputMargin ensures
|
||||
// that we don't overrun the dst and src buffers.
|
||||
const inputMargin = 8
|
||||
|
||||
// minNonLiteralBlockSize is the minimum size of the input to encodeBlock that
|
||||
// will be accepted by the encoder.
|
||||
const minNonLiteralBlockSize = 32
|
||||
|
||||
const intReduction = 2 - (1 << (^uint(0) >> 63)) // 1 (32 bits) or 0 (64 bits)
|
||||
|
||||
// MaxBlockSize is the maximum value where MaxEncodedLen will return a valid block size.
|
||||
// Blocks this big are highly discouraged, though.
|
||||
// Half the size on 32 bit systems.
|
||||
const MaxBlockSize = (1<<(32-intReduction) - 1) - binary.MaxVarintLen32 - 5
|
||||
|
||||
// MaxEncodedLen returns the maximum length of a snappy block, given its
|
||||
// uncompressed length.
|
||||
//
|
||||
// It will return a negative value if srcLen is too large to encode.
|
||||
// 32 bit platforms will have lower thresholds for rejecting big content.
|
||||
func MaxEncodedLen(srcLen int) int {
|
||||
n := uint64(srcLen)
|
||||
if intReduction == 1 {
|
||||
// 32 bits
|
||||
if n > math.MaxInt32 {
|
||||
// Also includes negative.
|
||||
return -1
|
||||
}
|
||||
} else if n > 0xffffffff {
|
||||
// 64 bits
|
||||
// Also includes negative.
|
||||
return -1
|
||||
}
|
||||
// Size of the varint encoded block size.
|
||||
n = n + uint64((bits.Len64(n)+7)/7)
|
||||
|
||||
// Add maximum size of encoding block as literals.
|
||||
n += uint64(literalExtraSize(int64(srcLen)))
|
||||
if intReduction == 1 {
|
||||
// 32 bits
|
||||
if n > math.MaxInt32 {
|
||||
return -1
|
||||
}
|
||||
} else if n > 0xffffffff {
|
||||
// 64 bits
|
||||
// Also includes negative.
|
||||
return -1
|
||||
}
|
||||
return int(n)
|
||||
}
|
||||
Generated
Vendored
-1477
File diff suppressed because it is too large
Load Diff
Generated
Vendored
-316
@@ -1,316 +0,0 @@
|
||||
//go:build (amd64 || arm64) && !appengine && !noasm && gc
|
||||
|
||||
package s2
|
||||
|
||||
import (
|
||||
"sync"
|
||||
|
||||
"github.com/klauspost/compress/internal/race"
|
||||
)
|
||||
|
||||
const hasAsm = true
|
||||
|
||||
var encPools [4]sync.Pool
|
||||
|
||||
// encodeBlock encodes a non-empty src to a guaranteed-large-enough dst. It
|
||||
// assumes that the varint-encoded length of the decompressed bytes has already
|
||||
// been written.
|
||||
//
|
||||
// It also assumes that:
|
||||
//
|
||||
// len(dst) >= MaxEncodedLen(len(src)) &&
|
||||
// minNonLiteralBlockSize <= len(src) && len(src) <= maxBlockSize
|
||||
func encodeBlock(dst, src []byte) (d int) {
|
||||
race.ReadSlice(src)
|
||||
race.WriteSlice(dst)
|
||||
|
||||
const (
|
||||
// Use 12 bit table when less than...
|
||||
limit12B = 16 << 10
|
||||
// Use 10 bit table when less than...
|
||||
limit10B = 4 << 10
|
||||
// Use 8 bit table when less than...
|
||||
limit8B = 512
|
||||
)
|
||||
|
||||
if len(src) >= 4<<20 {
|
||||
const sz, pool = 65536, 0
|
||||
tmp, ok := encPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encPools[pool].Put(tmp)
|
||||
return encodeBlockAsm(dst, src, tmp)
|
||||
}
|
||||
if len(src) >= limit12B {
|
||||
const sz, pool = 65536, 0
|
||||
tmp, ok := encPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encPools[pool].Put(tmp)
|
||||
return encodeBlockAsm4MB(dst, src, tmp)
|
||||
}
|
||||
if len(src) >= limit10B {
|
||||
const sz, pool = 16384, 1
|
||||
tmp, ok := encPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encPools[pool].Put(tmp)
|
||||
return encodeBlockAsm12B(dst, src, tmp)
|
||||
}
|
||||
if len(src) >= limit8B {
|
||||
const sz, pool = 4096, 2
|
||||
tmp, ok := encPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encPools[pool].Put(tmp)
|
||||
return encodeBlockAsm10B(dst, src, tmp)
|
||||
}
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
return 0
|
||||
}
|
||||
const sz, pool = 1024, 3
|
||||
tmp, ok := encPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encPools[pool].Put(tmp)
|
||||
return encodeBlockAsm8B(dst, src, tmp)
|
||||
}
|
||||
|
||||
var encBetterPools [5]sync.Pool
|
||||
|
||||
// encodeBlockBetter encodes a non-empty src to a guaranteed-large-enough dst. It
|
||||
// assumes that the varint-encoded length of the decompressed bytes has already
|
||||
// been written.
|
||||
//
|
||||
// It also assumes that:
|
||||
//
|
||||
// len(dst) >= MaxEncodedLen(len(src)) &&
|
||||
// minNonLiteralBlockSize <= len(src) && len(src) <= maxBlockSize
|
||||
func encodeBlockBetter(dst, src []byte) (d int) {
|
||||
race.ReadSlice(src)
|
||||
race.WriteSlice(dst)
|
||||
|
||||
const (
|
||||
// Use 12 bit table when less than...
|
||||
limit12B = 16 << 10
|
||||
// Use 10 bit table when less than...
|
||||
limit10B = 4 << 10
|
||||
// Use 8 bit table when less than...
|
||||
limit8B = 512
|
||||
)
|
||||
|
||||
if len(src) > 4<<20 {
|
||||
const sz, pool = 589824, 0
|
||||
tmp, ok := encBetterPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encBetterPools[pool].Put(tmp)
|
||||
return encodeBetterBlockAsm(dst, src, tmp)
|
||||
}
|
||||
if len(src) >= limit12B {
|
||||
const sz, pool = 589824, 0
|
||||
tmp, ok := encBetterPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encBetterPools[pool].Put(tmp)
|
||||
|
||||
return encodeBetterBlockAsm4MB(dst, src, tmp)
|
||||
}
|
||||
if len(src) >= limit10B {
|
||||
const sz, pool = 81920, 0
|
||||
tmp, ok := encBetterPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encBetterPools[pool].Put(tmp)
|
||||
|
||||
return encodeBetterBlockAsm12B(dst, src, tmp)
|
||||
}
|
||||
if len(src) >= limit8B {
|
||||
const sz, pool = 20480, 1
|
||||
tmp, ok := encBetterPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encBetterPools[pool].Put(tmp)
|
||||
return encodeBetterBlockAsm10B(dst, src, tmp)
|
||||
}
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
return 0
|
||||
}
|
||||
|
||||
const sz, pool = 5120, 2
|
||||
tmp, ok := encBetterPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encBetterPools[pool].Put(tmp)
|
||||
return encodeBetterBlockAsm8B(dst, src, tmp)
|
||||
}
|
||||
|
||||
// encodeBlockSnappy encodes a non-empty src to a guaranteed-large-enough dst. It
|
||||
// assumes that the varint-encoded length of the decompressed bytes has already
|
||||
// been written.
|
||||
//
|
||||
// It also assumes that:
|
||||
//
|
||||
// len(dst) >= MaxEncodedLen(len(src)) &&
|
||||
// minNonLiteralBlockSize <= len(src) && len(src) <= maxBlockSize
|
||||
func encodeBlockSnappy(dst, src []byte) (d int) {
|
||||
race.ReadSlice(src)
|
||||
race.WriteSlice(dst)
|
||||
|
||||
const (
|
||||
// Use 12 bit table when less than...
|
||||
limit12B = 16 << 10
|
||||
// Use 10 bit table when less than...
|
||||
limit10B = 4 << 10
|
||||
// Use 8 bit table when less than...
|
||||
limit8B = 512
|
||||
)
|
||||
if len(src) > 65536 {
|
||||
const sz, pool = 65536, 0
|
||||
tmp, ok := encPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encPools[pool].Put(tmp)
|
||||
return encodeSnappyBlockAsm(dst, src, tmp)
|
||||
}
|
||||
if len(src) >= limit12B {
|
||||
const sz, pool = 65536, 0
|
||||
tmp, ok := encPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encPools[pool].Put(tmp)
|
||||
return encodeSnappyBlockAsm64K(dst, src, tmp)
|
||||
}
|
||||
if len(src) >= limit10B {
|
||||
const sz, pool = 16384, 1
|
||||
tmp, ok := encPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encPools[pool].Put(tmp)
|
||||
return encodeSnappyBlockAsm12B(dst, src, tmp)
|
||||
}
|
||||
if len(src) >= limit8B {
|
||||
const sz, pool = 4096, 2
|
||||
tmp, ok := encPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encPools[pool].Put(tmp)
|
||||
return encodeSnappyBlockAsm10B(dst, src, tmp)
|
||||
}
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
return 0
|
||||
}
|
||||
const sz, pool = 1024, 3
|
||||
tmp, ok := encPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encPools[pool].Put(tmp)
|
||||
return encodeSnappyBlockAsm8B(dst, src, tmp)
|
||||
}
|
||||
|
||||
// encodeBlockSnappy encodes a non-empty src to a guaranteed-large-enough dst. It
|
||||
// assumes that the varint-encoded length of the decompressed bytes has already
|
||||
// been written.
|
||||
//
|
||||
// It also assumes that:
|
||||
//
|
||||
// len(dst) >= MaxEncodedLen(len(src)) &&
|
||||
// minNonLiteralBlockSize <= len(src) && len(src) <= maxBlockSize
|
||||
func encodeBlockBetterSnappy(dst, src []byte) (d int) {
|
||||
race.ReadSlice(src)
|
||||
race.WriteSlice(dst)
|
||||
|
||||
const (
|
||||
// Use 12 bit table when less than...
|
||||
limit12B = 16 << 10
|
||||
// Use 10 bit table when less than...
|
||||
limit10B = 4 << 10
|
||||
// Use 8 bit table when less than...
|
||||
limit8B = 512
|
||||
)
|
||||
if len(src) > 65536 {
|
||||
const sz, pool = 589824, 0
|
||||
tmp, ok := encBetterPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encBetterPools[pool].Put(tmp)
|
||||
return encodeSnappyBetterBlockAsm(dst, src, tmp)
|
||||
}
|
||||
|
||||
if len(src) >= limit12B {
|
||||
const sz, pool = 294912, 4
|
||||
tmp, ok := encBetterPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encBetterPools[pool].Put(tmp)
|
||||
|
||||
return encodeSnappyBetterBlockAsm64K(dst, src, tmp)
|
||||
}
|
||||
if len(src) >= limit10B {
|
||||
const sz, pool = 81920, 0
|
||||
tmp, ok := encBetterPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encBetterPools[pool].Put(tmp)
|
||||
|
||||
return encodeSnappyBetterBlockAsm12B(dst, src, tmp)
|
||||
}
|
||||
if len(src) >= limit8B {
|
||||
const sz, pool = 20480, 1
|
||||
tmp, ok := encBetterPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encBetterPools[pool].Put(tmp)
|
||||
return encodeSnappyBetterBlockAsm10B(dst, src, tmp)
|
||||
}
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
return 0
|
||||
}
|
||||
|
||||
const sz, pool = 5120, 2
|
||||
tmp, ok := encBetterPools[pool].Get().(*[sz]byte)
|
||||
if !ok {
|
||||
tmp = &[sz]byte{}
|
||||
}
|
||||
race.WriteSlice(tmp[:])
|
||||
defer encBetterPools[pool].Put(tmp)
|
||||
return encodeSnappyBetterBlockAsm8B(dst, src, tmp)
|
||||
}
|
||||
Generated
Vendored
-797
@@ -1,797 +0,0 @@
|
||||
// Copyright 2016 The Snappy-Go Authors. All rights reserved.
|
||||
// Copyright (c) 2019 Klaus Post. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package s2
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"math"
|
||||
"math/bits"
|
||||
)
|
||||
|
||||
// encodeBlockBest encodes a non-empty src to a guaranteed-large-enough dst. It
|
||||
// assumes that the varint-encoded length of the decompressed bytes has already
|
||||
// been written.
|
||||
//
|
||||
// It also assumes that:
|
||||
//
|
||||
// len(dst) >= MaxEncodedLen(len(src)) &&
|
||||
// minNonLiteralBlockSize <= len(src) && len(src) <= maxBlockSize
|
||||
func encodeBlockBest(dst, src []byte, dict *Dict) (d int) {
|
||||
// Initialize the hash tables.
|
||||
const (
|
||||
// Long hash matches.
|
||||
lTableBits = bestLongTableBits
|
||||
maxLTableSize = bestLongTableSize
|
||||
|
||||
// Short hash matches.
|
||||
sTableBits = bestShortTableBits
|
||||
maxSTableSize = bestShortTableSize
|
||||
|
||||
inputMargin = 8 + 2
|
||||
|
||||
debug = false
|
||||
)
|
||||
|
||||
// sLimit is when to stop looking for offset/length copies. The inputMargin
|
||||
// lets us use a fast path for emitLiteral in the main loop, while we are
|
||||
// looking for copies.
|
||||
sLimit := len(src) - inputMargin
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
return 0
|
||||
}
|
||||
sLimitDict := min(len(src)-inputMargin, MaxDictSrcOffset-inputMargin)
|
||||
|
||||
tbl := getBestTables()
|
||||
lTable := &tbl.lTable
|
||||
sTable := &tbl.sTable
|
||||
defer bestTablePool.Put(tbl)
|
||||
|
||||
// Bail if we can't compress to at least this.
|
||||
dstLimit := len(src) - 5
|
||||
|
||||
// nextEmit is where in src the next emitLiteral should start from.
|
||||
nextEmit := 0
|
||||
|
||||
// The encoded form must start with a literal, as there are no previous
|
||||
// bytes to copy, so we start looking for hash matches at s == 1.
|
||||
s := 1
|
||||
repeat := 1
|
||||
if dict != nil {
|
||||
dict.initBest()
|
||||
s = 0
|
||||
repeat = len(dict.dict) - dict.repeat
|
||||
}
|
||||
cv := load64(src, s)
|
||||
|
||||
// We search for a repeat at -1, but don't output repeats when nextEmit == 0
|
||||
const lowbitMask = 0xffffffff
|
||||
getCur := func(x uint64) int {
|
||||
return int(x & lowbitMask)
|
||||
}
|
||||
getPrev := func(x uint64) int {
|
||||
return int(x >> 32)
|
||||
}
|
||||
const maxSkip = 64
|
||||
|
||||
for {
|
||||
type match struct {
|
||||
offset int
|
||||
s int
|
||||
length int
|
||||
score int
|
||||
rep, dict bool
|
||||
}
|
||||
var best match
|
||||
for {
|
||||
// Next src position to check
|
||||
nextS := (s-nextEmit)>>8 + 1
|
||||
if nextS > maxSkip {
|
||||
nextS = s + maxSkip
|
||||
} else {
|
||||
nextS += s
|
||||
}
|
||||
if nextS > sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
if dict != nil && s >= MaxDictSrcOffset {
|
||||
dict = nil
|
||||
if repeat > s {
|
||||
repeat = math.MinInt32
|
||||
}
|
||||
}
|
||||
hashL := hash8(cv, lTableBits)
|
||||
hashS := hash4(cv, sTableBits)
|
||||
candidateL := lTable[hashL]
|
||||
candidateS := sTable[hashS]
|
||||
|
||||
score := func(m match) int {
|
||||
// Matches that are longer forward are penalized since we must emit it as a literal.
|
||||
score := m.length - m.s
|
||||
if nextEmit == m.s {
|
||||
// If we do not have to emit literals, we save 1 byte
|
||||
score++
|
||||
}
|
||||
offset := m.s - m.offset
|
||||
if m.rep {
|
||||
return score - emitRepeatSize(offset, m.length)
|
||||
}
|
||||
return score - emitCopySize(offset, m.length)
|
||||
}
|
||||
|
||||
matchAt := func(offset, s int, first uint32, rep bool) match {
|
||||
if best.length != 0 && best.s-best.offset == s-offset {
|
||||
// Don't retest if we have the same offset.
|
||||
return match{offset: offset, s: s}
|
||||
}
|
||||
if load32(src, offset) != first {
|
||||
return match{offset: offset, s: s}
|
||||
}
|
||||
m := match{offset: offset, s: s, length: 4 + offset, rep: rep}
|
||||
s += 4
|
||||
for s < len(src) {
|
||||
if len(src)-s < 8 {
|
||||
if src[s] == src[m.length] {
|
||||
m.length++
|
||||
s++
|
||||
continue
|
||||
}
|
||||
break
|
||||
}
|
||||
if diff := load64(src, s) ^ load64(src, m.length); diff != 0 {
|
||||
m.length += bits.TrailingZeros64(diff) >> 3
|
||||
break
|
||||
}
|
||||
s += 8
|
||||
m.length += 8
|
||||
}
|
||||
m.length -= offset
|
||||
m.score = score(m)
|
||||
if m.score <= -m.s {
|
||||
// Eliminate if no savings, we might find a better one.
|
||||
m.length = 0
|
||||
}
|
||||
return m
|
||||
}
|
||||
matchDict := func(candidate, s int, first uint32, rep bool) match {
|
||||
if s >= MaxDictSrcOffset {
|
||||
return match{offset: candidate, s: s}
|
||||
}
|
||||
// Calculate offset as if in continuous array with s
|
||||
offset := -len(dict.dict) + candidate
|
||||
if best.length != 0 && best.s-best.offset == s-offset && !rep {
|
||||
// Don't retest if we have the same offset.
|
||||
return match{offset: offset, s: s}
|
||||
}
|
||||
|
||||
if load32(dict.dict, candidate) != first {
|
||||
return match{offset: offset, s: s}
|
||||
}
|
||||
m := match{offset: offset, s: s, length: 4 + candidate, rep: rep, dict: true}
|
||||
s += 4
|
||||
if !rep {
|
||||
for s < sLimitDict && m.length < len(dict.dict) {
|
||||
if len(src)-s < 8 || len(dict.dict)-m.length < 8 {
|
||||
if src[s] == dict.dict[m.length] {
|
||||
m.length++
|
||||
s++
|
||||
continue
|
||||
}
|
||||
break
|
||||
}
|
||||
if diff := load64(src, s) ^ load64(dict.dict, m.length); diff != 0 {
|
||||
m.length += bits.TrailingZeros64(diff) >> 3
|
||||
break
|
||||
}
|
||||
s += 8
|
||||
m.length += 8
|
||||
}
|
||||
} else {
|
||||
for s < len(src) && m.length < len(dict.dict) {
|
||||
if len(src)-s < 8 || len(dict.dict)-m.length < 8 {
|
||||
if src[s] == dict.dict[m.length] {
|
||||
m.length++
|
||||
s++
|
||||
continue
|
||||
}
|
||||
break
|
||||
}
|
||||
if diff := load64(src, s) ^ load64(dict.dict, m.length); diff != 0 {
|
||||
m.length += bits.TrailingZeros64(diff) >> 3
|
||||
break
|
||||
}
|
||||
s += 8
|
||||
m.length += 8
|
||||
}
|
||||
}
|
||||
m.length -= candidate
|
||||
m.score = score(m)
|
||||
if m.score <= -m.s {
|
||||
// Eliminate if no savings, we might find a better one.
|
||||
m.length = 0
|
||||
}
|
||||
return m
|
||||
}
|
||||
|
||||
bestOf := func(a, b match) match {
|
||||
if b.length == 0 {
|
||||
return a
|
||||
}
|
||||
if a.length == 0 {
|
||||
return b
|
||||
}
|
||||
as := a.score + b.s
|
||||
bs := b.score + a.s
|
||||
if as >= bs {
|
||||
return a
|
||||
}
|
||||
return b
|
||||
}
|
||||
|
||||
if s > 0 {
|
||||
best = bestOf(matchAt(getCur(candidateL), s, uint32(cv), false), matchAt(getPrev(candidateL), s, uint32(cv), false))
|
||||
best = bestOf(best, matchAt(getCur(candidateS), s, uint32(cv), false))
|
||||
best = bestOf(best, matchAt(getPrev(candidateS), s, uint32(cv), false))
|
||||
}
|
||||
if dict != nil {
|
||||
candidateL := dict.bestTableLong[hashL]
|
||||
candidateS := dict.bestTableShort[hashS]
|
||||
best = bestOf(best, matchDict(int(candidateL&0xffff), s, uint32(cv), false))
|
||||
best = bestOf(best, matchDict(int(candidateL>>16), s, uint32(cv), false))
|
||||
best = bestOf(best, matchDict(int(candidateS&0xffff), s, uint32(cv), false))
|
||||
best = bestOf(best, matchDict(int(candidateS>>16), s, uint32(cv), false))
|
||||
}
|
||||
{
|
||||
if (dict == nil || repeat <= s) && repeat > 0 {
|
||||
best = bestOf(best, matchAt(s-repeat+1, s+1, uint32(cv>>8), true))
|
||||
} else if s-repeat < -4 && dict != nil {
|
||||
candidate := len(dict.dict) - (repeat - s)
|
||||
best = bestOf(best, matchDict(candidate, s, uint32(cv), true))
|
||||
candidate++
|
||||
best = bestOf(best, matchDict(candidate, s+1, uint32(cv>>8), true))
|
||||
}
|
||||
|
||||
if best.length > 0 {
|
||||
hashS := hash4(cv>>8, sTableBits)
|
||||
// s+1
|
||||
nextShort := sTable[hashS]
|
||||
s := s + 1
|
||||
cv := load64(src, s)
|
||||
hashL := hash8(cv, lTableBits)
|
||||
nextLong := lTable[hashL]
|
||||
best = bestOf(best, matchAt(getCur(nextShort), s, uint32(cv), false))
|
||||
best = bestOf(best, matchAt(getPrev(nextShort), s, uint32(cv), false))
|
||||
best = bestOf(best, matchAt(getCur(nextLong), s, uint32(cv), false))
|
||||
best = bestOf(best, matchAt(getPrev(nextLong), s, uint32(cv), false))
|
||||
|
||||
// Dict at + 1
|
||||
if dict != nil {
|
||||
candidateL := dict.bestTableLong[hashL]
|
||||
candidateS := dict.bestTableShort[hashS]
|
||||
|
||||
best = bestOf(best, matchDict(int(candidateL&0xffff), s, uint32(cv), false))
|
||||
best = bestOf(best, matchDict(int(candidateS&0xffff), s, uint32(cv), false))
|
||||
}
|
||||
|
||||
// s+2
|
||||
if true {
|
||||
hashS := hash4(cv>>8, sTableBits)
|
||||
|
||||
nextShort = sTable[hashS]
|
||||
s++
|
||||
cv = load64(src, s)
|
||||
hashL := hash8(cv, lTableBits)
|
||||
nextLong = lTable[hashL]
|
||||
|
||||
if (dict == nil || repeat <= s) && repeat > 0 {
|
||||
// Repeat at + 2
|
||||
best = bestOf(best, matchAt(s-repeat, s, uint32(cv), true))
|
||||
} else if repeat-s > 4 && dict != nil {
|
||||
candidate := len(dict.dict) - (repeat - s)
|
||||
best = bestOf(best, matchDict(candidate, s, uint32(cv), true))
|
||||
}
|
||||
best = bestOf(best, matchAt(getCur(nextShort), s, uint32(cv), false))
|
||||
best = bestOf(best, matchAt(getPrev(nextShort), s, uint32(cv), false))
|
||||
best = bestOf(best, matchAt(getCur(nextLong), s, uint32(cv), false))
|
||||
best = bestOf(best, matchAt(getPrev(nextLong), s, uint32(cv), false))
|
||||
|
||||
// Dict at +2
|
||||
// Very small gain
|
||||
if dict != nil {
|
||||
candidateL := dict.bestTableLong[hashL]
|
||||
candidateS := dict.bestTableShort[hashS]
|
||||
|
||||
best = bestOf(best, matchDict(int(candidateL&0xffff), s, uint32(cv), false))
|
||||
best = bestOf(best, matchDict(int(candidateS&0xffff), s, uint32(cv), false))
|
||||
}
|
||||
}
|
||||
// Search for a match at best match end, see if that is better.
|
||||
// Allow some bytes at the beginning to mismatch.
|
||||
// Sweet spot is around 1-2 bytes, but depends on input.
|
||||
// The skipped bytes are tested in Extend backwards,
|
||||
// and still picked up as part of the match if they do.
|
||||
const skipBeginning = 2
|
||||
const skipEnd = 1
|
||||
if sAt := best.s + best.length - skipEnd; sAt < sLimit {
|
||||
|
||||
sBack := best.s + skipBeginning - skipEnd
|
||||
backL := best.length - skipBeginning
|
||||
// Load initial values
|
||||
cv = load64(src, sBack)
|
||||
|
||||
// Grab candidates...
|
||||
next := lTable[hash8(load64(src, sAt), lTableBits)]
|
||||
|
||||
if checkAt := getCur(next) - backL; checkAt > 0 {
|
||||
best = bestOf(best, matchAt(checkAt, sBack, uint32(cv), false))
|
||||
}
|
||||
if checkAt := getPrev(next) - backL; checkAt > 0 {
|
||||
best = bestOf(best, matchAt(checkAt, sBack, uint32(cv), false))
|
||||
}
|
||||
// Disabled: Extremely small gain
|
||||
if false {
|
||||
next = sTable[hash4(load64(src, sAt), sTableBits)]
|
||||
if checkAt := getCur(next) - backL; checkAt > 0 {
|
||||
best = bestOf(best, matchAt(checkAt, sBack, uint32(cv), false))
|
||||
}
|
||||
if checkAt := getPrev(next) - backL; checkAt > 0 {
|
||||
best = bestOf(best, matchAt(checkAt, sBack, uint32(cv), false))
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// Update table
|
||||
lTable[hashL] = uint64(s) | candidateL<<32
|
||||
sTable[hashS] = uint64(s) | candidateS<<32
|
||||
|
||||
if best.length > 0 {
|
||||
break
|
||||
}
|
||||
|
||||
cv = load64(src, nextS)
|
||||
s = nextS
|
||||
}
|
||||
|
||||
// Extend backwards, not needed for repeats...
|
||||
s = best.s
|
||||
if !best.rep && !best.dict {
|
||||
for best.offset > 0 && s > nextEmit && src[best.offset-1] == src[s-1] {
|
||||
best.offset--
|
||||
best.length++
|
||||
s--
|
||||
}
|
||||
}
|
||||
if false && best.offset >= s {
|
||||
panic(fmt.Errorf("t %d >= s %d", best.offset, s))
|
||||
}
|
||||
// Bail if we exceed the maximum size.
|
||||
if d+(s-nextEmit) > dstLimit {
|
||||
return 0
|
||||
}
|
||||
|
||||
base := s
|
||||
offset := s - best.offset
|
||||
s += best.length
|
||||
|
||||
if offset > 65535 && s-base <= 5 && !best.rep {
|
||||
// Bail if the match is equal or worse to the encoding.
|
||||
s = best.s + 1
|
||||
if s >= sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
cv = load64(src, s)
|
||||
continue
|
||||
}
|
||||
if debug && nextEmit != base {
|
||||
fmt.Println("EMIT", base-nextEmit, "literals. base-after:", base)
|
||||
}
|
||||
d += emitLiteral(dst[d:], src[nextEmit:base])
|
||||
if best.rep {
|
||||
if nextEmit > 0 || best.dict {
|
||||
if debug {
|
||||
fmt.Println("REPEAT, length", best.length, "offset:", offset, "s-after:", s, "dict:", best.dict, "best:", best)
|
||||
}
|
||||
// same as `add := emitCopy(dst[d:], repeat, s-base)` but skips storing offset.
|
||||
d += emitRepeat(dst[d:], offset, best.length)
|
||||
} else {
|
||||
// First match without dict cannot be a repeat.
|
||||
if debug {
|
||||
fmt.Println("COPY, length", best.length, "offset:", offset, "s-after:", s, "dict:", best.dict, "best:", best)
|
||||
}
|
||||
d += emitCopy(dst[d:], offset, best.length)
|
||||
}
|
||||
} else {
|
||||
if debug {
|
||||
fmt.Println("COPY, length", best.length, "offset:", offset, "s-after:", s, "dict:", best.dict, "best:", best)
|
||||
}
|
||||
d += emitCopy(dst[d:], offset, best.length)
|
||||
}
|
||||
repeat = offset
|
||||
|
||||
nextEmit = s
|
||||
if s >= sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
if d > dstLimit {
|
||||
// Do we have space for more, if not bail.
|
||||
return 0
|
||||
}
|
||||
// Fill tables...
|
||||
for i := best.s + 1; i < s; i++ {
|
||||
cv0 := load64(src, i)
|
||||
long0 := hash8(cv0, lTableBits)
|
||||
short0 := hash4(cv0, sTableBits)
|
||||
lTable[long0] = uint64(i) | lTable[long0]<<32
|
||||
sTable[short0] = uint64(i) | sTable[short0]<<32
|
||||
}
|
||||
cv = load64(src, s)
|
||||
}
|
||||
|
||||
emitRemainder:
|
||||
if nextEmit < len(src) {
|
||||
// Bail if we exceed the maximum size.
|
||||
if d+len(src)-nextEmit > dstLimit {
|
||||
return 0
|
||||
}
|
||||
if debug && nextEmit != s {
|
||||
fmt.Println("emitted ", len(src)-nextEmit, "literals")
|
||||
}
|
||||
d += emitLiteral(dst[d:], src[nextEmit:])
|
||||
}
|
||||
return d
|
||||
}
|
||||
|
||||
// encodeBlockBestSnappy encodes a non-empty src to a guaranteed-large-enough dst. It
|
||||
// assumes that the varint-encoded length of the decompressed bytes has already
|
||||
// been written.
|
||||
//
|
||||
// It also assumes that:
|
||||
//
|
||||
// len(dst) >= MaxEncodedLen(len(src)) &&
|
||||
// minNonLiteralBlockSize <= len(src) && len(src) <= maxBlockSize
|
||||
func encodeBlockBestSnappy(dst, src []byte) (d int) {
|
||||
// Initialize the hash tables.
|
||||
const (
|
||||
// Long hash matches.
|
||||
lTableBits = bestLongTableBits
|
||||
maxLTableSize = bestLongTableSize
|
||||
|
||||
// Short hash matches.
|
||||
sTableBits = bestShortTableBits
|
||||
maxSTableSize = bestShortTableSize
|
||||
|
||||
inputMargin = 8 + 2
|
||||
)
|
||||
|
||||
// sLimit is when to stop looking for offset/length copies. The inputMargin
|
||||
// lets us use a fast path for emitLiteral in the main loop, while we are
|
||||
// looking for copies.
|
||||
sLimit := len(src) - inputMargin
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
return 0
|
||||
}
|
||||
|
||||
tbl := getBestTables()
|
||||
lTable := &tbl.lTable
|
||||
sTable := &tbl.sTable
|
||||
defer bestTablePool.Put(tbl)
|
||||
|
||||
// Bail if we can't compress to at least this.
|
||||
dstLimit := len(src) - 5
|
||||
|
||||
// nextEmit is where in src the next emitLiteral should start from.
|
||||
nextEmit := 0
|
||||
|
||||
// The encoded form must start with a literal, as there are no previous
|
||||
// bytes to copy, so we start looking for hash matches at s == 1.
|
||||
s := 1
|
||||
cv := load64(src, s)
|
||||
|
||||
// We search for a repeat at -1, but don't output repeats when nextEmit == 0
|
||||
repeat := 1
|
||||
const lowbitMask = 0xffffffff
|
||||
getCur := func(x uint64) int {
|
||||
return int(x & lowbitMask)
|
||||
}
|
||||
getPrev := func(x uint64) int {
|
||||
return int(x >> 32)
|
||||
}
|
||||
const maxSkip = 64
|
||||
|
||||
for {
|
||||
type match struct {
|
||||
offset int
|
||||
s int
|
||||
length int
|
||||
score int
|
||||
}
|
||||
var best match
|
||||
for {
|
||||
// Next src position to check
|
||||
nextS := (s-nextEmit)>>8 + 1
|
||||
if nextS > maxSkip {
|
||||
nextS = s + maxSkip
|
||||
} else {
|
||||
nextS += s
|
||||
}
|
||||
if nextS > sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
hashL := hash8(cv, lTableBits)
|
||||
hashS := hash4(cv, sTableBits)
|
||||
candidateL := lTable[hashL]
|
||||
candidateS := sTable[hashS]
|
||||
|
||||
score := func(m match) int {
|
||||
// Matches that are longer forward are penalized since we must emit it as a literal.
|
||||
score := m.length - m.s
|
||||
if nextEmit == m.s {
|
||||
// If we do not have to emit literals, we save 1 byte
|
||||
score++
|
||||
}
|
||||
offset := m.s - m.offset
|
||||
|
||||
return score - emitCopyNoRepeatSize(offset, m.length)
|
||||
}
|
||||
|
||||
matchAt := func(offset, s int, first uint32) match {
|
||||
if best.length != 0 && best.s-best.offset == s-offset {
|
||||
// Don't retest if we have the same offset.
|
||||
return match{offset: offset, s: s}
|
||||
}
|
||||
if load32(src, offset) != first {
|
||||
return match{offset: offset, s: s}
|
||||
}
|
||||
m := match{offset: offset, s: s, length: 4 + offset}
|
||||
s += 4
|
||||
for s <= sLimit {
|
||||
if diff := load64(src, s) ^ load64(src, m.length); diff != 0 {
|
||||
m.length += bits.TrailingZeros64(diff) >> 3
|
||||
break
|
||||
}
|
||||
s += 8
|
||||
m.length += 8
|
||||
}
|
||||
m.length -= offset
|
||||
m.score = score(m)
|
||||
if m.score <= -m.s {
|
||||
// Eliminate if no savings, we might find a better one.
|
||||
m.length = 0
|
||||
}
|
||||
return m
|
||||
}
|
||||
|
||||
bestOf := func(a, b match) match {
|
||||
if b.length == 0 {
|
||||
return a
|
||||
}
|
||||
if a.length == 0 {
|
||||
return b
|
||||
}
|
||||
as := a.score + b.s
|
||||
bs := b.score + a.s
|
||||
if as >= bs {
|
||||
return a
|
||||
}
|
||||
return b
|
||||
}
|
||||
|
||||
best = bestOf(matchAt(getCur(candidateL), s, uint32(cv)), matchAt(getPrev(candidateL), s, uint32(cv)))
|
||||
best = bestOf(best, matchAt(getCur(candidateS), s, uint32(cv)))
|
||||
best = bestOf(best, matchAt(getPrev(candidateS), s, uint32(cv)))
|
||||
|
||||
{
|
||||
best = bestOf(best, matchAt(s-repeat+1, s+1, uint32(cv>>8)))
|
||||
if best.length > 0 {
|
||||
// s+1
|
||||
nextShort := sTable[hash4(cv>>8, sTableBits)]
|
||||
s := s + 1
|
||||
cv := load64(src, s)
|
||||
nextLong := lTable[hash8(cv, lTableBits)]
|
||||
best = bestOf(best, matchAt(getCur(nextShort), s, uint32(cv)))
|
||||
best = bestOf(best, matchAt(getPrev(nextShort), s, uint32(cv)))
|
||||
best = bestOf(best, matchAt(getCur(nextLong), s, uint32(cv)))
|
||||
best = bestOf(best, matchAt(getPrev(nextLong), s, uint32(cv)))
|
||||
// Repeat at + 2
|
||||
best = bestOf(best, matchAt(s-repeat+1, s+1, uint32(cv>>8)))
|
||||
|
||||
// s+2
|
||||
if true {
|
||||
nextShort = sTable[hash4(cv>>8, sTableBits)]
|
||||
s++
|
||||
cv = load64(src, s)
|
||||
nextLong = lTable[hash8(cv, lTableBits)]
|
||||
best = bestOf(best, matchAt(getCur(nextShort), s, uint32(cv)))
|
||||
best = bestOf(best, matchAt(getPrev(nextShort), s, uint32(cv)))
|
||||
best = bestOf(best, matchAt(getCur(nextLong), s, uint32(cv)))
|
||||
best = bestOf(best, matchAt(getPrev(nextLong), s, uint32(cv)))
|
||||
}
|
||||
// Search for a match at best match end, see if that is better.
|
||||
if sAt := best.s + best.length; sAt < sLimit {
|
||||
sBack := best.s
|
||||
backL := best.length
|
||||
// Load initial values
|
||||
cv = load64(src, sBack)
|
||||
// Search for mismatch
|
||||
next := lTable[hash8(load64(src, sAt), lTableBits)]
|
||||
//next := sTable[hash4(load64(src, sAt), sTableBits)]
|
||||
|
||||
if checkAt := getCur(next) - backL; checkAt > 0 {
|
||||
best = bestOf(best, matchAt(checkAt, sBack, uint32(cv)))
|
||||
}
|
||||
if checkAt := getPrev(next) - backL; checkAt > 0 {
|
||||
best = bestOf(best, matchAt(checkAt, sBack, uint32(cv)))
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// Update table
|
||||
lTable[hashL] = uint64(s) | candidateL<<32
|
||||
sTable[hashS] = uint64(s) | candidateS<<32
|
||||
|
||||
if best.length > 0 {
|
||||
break
|
||||
}
|
||||
|
||||
cv = load64(src, nextS)
|
||||
s = nextS
|
||||
}
|
||||
|
||||
// Extend backwards, not needed for repeats...
|
||||
s = best.s
|
||||
if true {
|
||||
for best.offset > 0 && s > nextEmit && src[best.offset-1] == src[s-1] {
|
||||
best.offset--
|
||||
best.length++
|
||||
s--
|
||||
}
|
||||
}
|
||||
if false && best.offset >= s {
|
||||
panic(fmt.Errorf("t %d >= s %d", best.offset, s))
|
||||
}
|
||||
// Bail if we exceed the maximum size.
|
||||
if d+(s-nextEmit) > dstLimit {
|
||||
return 0
|
||||
}
|
||||
|
||||
base := s
|
||||
offset := s - best.offset
|
||||
|
||||
s += best.length
|
||||
|
||||
if offset > 65535 && s-base <= 5 {
|
||||
// Bail if the match is equal or worse to the encoding.
|
||||
s = best.s + 1
|
||||
if s >= sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
cv = load64(src, s)
|
||||
continue
|
||||
}
|
||||
d += emitLiteral(dst[d:], src[nextEmit:base])
|
||||
d += emitCopyNoRepeat(dst[d:], offset, best.length)
|
||||
repeat = offset
|
||||
|
||||
nextEmit = s
|
||||
if s >= sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
if d > dstLimit {
|
||||
// Do we have space for more, if not bail.
|
||||
return 0
|
||||
}
|
||||
// Fill tables...
|
||||
for i := best.s + 1; i < s; i++ {
|
||||
cv0 := load64(src, i)
|
||||
long0 := hash8(cv0, lTableBits)
|
||||
short0 := hash4(cv0, sTableBits)
|
||||
lTable[long0] = uint64(i) | lTable[long0]<<32
|
||||
sTable[short0] = uint64(i) | sTable[short0]<<32
|
||||
}
|
||||
cv = load64(src, s)
|
||||
}
|
||||
|
||||
emitRemainder:
|
||||
if nextEmit < len(src) {
|
||||
// Bail if we exceed the maximum size.
|
||||
if d+len(src)-nextEmit > dstLimit {
|
||||
return 0
|
||||
}
|
||||
d += emitLiteral(dst[d:], src[nextEmit:])
|
||||
}
|
||||
return d
|
||||
}
|
||||
|
||||
// emitCopySize returns the size to encode the offset+length
|
||||
//
|
||||
// It assumes that:
|
||||
//
|
||||
// 1 <= offset && offset <= math.MaxUint32
|
||||
// 4 <= length && length <= 1 << 24
|
||||
func emitCopySize(offset, length int) int {
|
||||
if offset >= 65536 {
|
||||
i := 0
|
||||
if length > 64 {
|
||||
length -= 64
|
||||
if length >= 4 {
|
||||
// Emit remaining as repeats
|
||||
return 5 + emitRepeatSize(offset, length)
|
||||
}
|
||||
i = 5
|
||||
}
|
||||
if length == 0 {
|
||||
return i
|
||||
}
|
||||
return i + 5
|
||||
}
|
||||
|
||||
// Offset no more than 2 bytes.
|
||||
if length > 64 {
|
||||
if offset < 2048 {
|
||||
// Emit 8 bytes, then rest as repeats...
|
||||
return 2 + emitRepeatSize(offset, length-8)
|
||||
}
|
||||
// Emit remaining as repeats, at least 4 bytes remain.
|
||||
return 3 + emitRepeatSize(offset, length-60)
|
||||
}
|
||||
if length >= 12 || offset >= 2048 {
|
||||
return 3
|
||||
}
|
||||
// Emit the remaining copy, encoded as 2 bytes.
|
||||
return 2
|
||||
}
|
||||
|
||||
// emitCopyNoRepeatSize returns the size to encode the offset+length
|
||||
//
|
||||
// It assumes that:
|
||||
//
|
||||
// 1 <= offset && offset <= math.MaxUint32
|
||||
// 4 <= length && length <= 1 << 24
|
||||
func emitCopyNoRepeatSize(offset, length int) int {
|
||||
if offset >= 65536 {
|
||||
return 5 + 5*(length/64)
|
||||
}
|
||||
|
||||
// Offset no more than 2 bytes.
|
||||
if length > 64 {
|
||||
// Emit remaining as repeats, at least 4 bytes remain.
|
||||
return 3 + 3*(length/60)
|
||||
}
|
||||
if length >= 12 || offset >= 2048 {
|
||||
return 3
|
||||
}
|
||||
// Emit the remaining copy, encoded as 2 bytes.
|
||||
return 2
|
||||
}
|
||||
|
||||
// emitRepeatSize returns the number of bytes required to encode a repeat.
|
||||
// Length must be at least 4 and < 1<<24
|
||||
func emitRepeatSize(offset, length int) int {
|
||||
// Repeat offset, make length cheaper
|
||||
if length <= 4+4 || (length < 8+4 && offset < 2048) {
|
||||
return 2
|
||||
}
|
||||
if length < (1<<8)+4+4 {
|
||||
return 3
|
||||
}
|
||||
if length < (1<<16)+(1<<8)+4 {
|
||||
return 4
|
||||
}
|
||||
const maxRepeat = (1 << 24) - 1
|
||||
length -= (1 << 16) - 4
|
||||
left := 0
|
||||
if length > maxRepeat {
|
||||
left = length - maxRepeat + 4
|
||||
}
|
||||
if left > 0 {
|
||||
return 5 + emitRepeatSize(offset, left)
|
||||
}
|
||||
return 5
|
||||
}
|
||||
Generated
Vendored
-1519
File diff suppressed because it is too large
Load Diff
Generated
Vendored
-740
@@ -1,740 +0,0 @@
|
||||
//go:build (!amd64 && !arm64) || appengine || !gc || noasm
|
||||
|
||||
package s2
|
||||
|
||||
import (
|
||||
"bytes"
|
||||
"math/bits"
|
||||
)
|
||||
|
||||
const hasAsm = false
|
||||
|
||||
// encodeBlock encodes a non-empty src to a guaranteed-large-enough dst. It
|
||||
// assumes that the varint-encoded length of the decompressed bytes has already
|
||||
// been written.
|
||||
//
|
||||
// It also assumes that:
|
||||
//
|
||||
// len(dst) >= MaxEncodedLen(len(src))
|
||||
func encodeBlock(dst, src []byte) (d int) {
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
return 0
|
||||
}
|
||||
if len(src) <= 64<<10 {
|
||||
return encodeBlockGo64K(dst, src)
|
||||
}
|
||||
return encodeBlockGo(dst, src)
|
||||
}
|
||||
|
||||
// encodeBlockBetter encodes a non-empty src to a guaranteed-large-enough dst. It
|
||||
// assumes that the varint-encoded length of the decompressed bytes has already
|
||||
// been written.
|
||||
//
|
||||
// It also assumes that:
|
||||
//
|
||||
// len(dst) >= MaxEncodedLen(len(src))
|
||||
func encodeBlockBetter(dst, src []byte) (d int) {
|
||||
if len(src) <= 64<<10 {
|
||||
return encodeBlockBetterGo64K(dst, src)
|
||||
}
|
||||
return encodeBlockBetterGo(dst, src)
|
||||
}
|
||||
|
||||
// encodeBlockBetter encodes a non-empty src to a guaranteed-large-enough dst. It
|
||||
// assumes that the varint-encoded length of the decompressed bytes has already
|
||||
// been written.
|
||||
//
|
||||
// It also assumes that:
|
||||
//
|
||||
// len(dst) >= MaxEncodedLen(len(src))
|
||||
func encodeBlockBetterSnappy(dst, src []byte) (d int) {
|
||||
if len(src) <= 64<<10 {
|
||||
return encodeBlockBetterSnappyGo64K(dst, src)
|
||||
}
|
||||
return encodeBlockBetterSnappyGo(dst, src)
|
||||
}
|
||||
|
||||
// encodeBlock encodes a non-empty src to a guaranteed-large-enough dst. It
|
||||
// assumes that the varint-encoded length of the decompressed bytes has already
|
||||
// been written.
|
||||
//
|
||||
// It also assumes that:
|
||||
//
|
||||
// len(dst) >= MaxEncodedLen(len(src))
|
||||
func encodeBlockSnappy(dst, src []byte) (d int) {
|
||||
if len(src) < minNonLiteralBlockSize {
|
||||
return 0
|
||||
}
|
||||
if len(src) <= 64<<10 {
|
||||
return encodeBlockSnappyGo64K(dst, src)
|
||||
}
|
||||
return encodeBlockSnappyGo(dst, src)
|
||||
}
|
||||
|
||||
// emitLiteral writes a literal chunk and returns the number of bytes written.
|
||||
//
|
||||
// It assumes that:
|
||||
//
|
||||
// dst is long enough to hold the encoded bytes
|
||||
// 0 <= len(lit) && len(lit) <= math.MaxUint32
|
||||
func emitLiteral(dst, lit []byte) int {
|
||||
if len(lit) == 0 {
|
||||
return 0
|
||||
}
|
||||
const num = 63<<2 | tagLiteral
|
||||
i, n := 0, uint(len(lit)-1)
|
||||
switch {
|
||||
case n < 60:
|
||||
dst[0] = uint8(n)<<2 | tagLiteral
|
||||
i = 1
|
||||
case n < 1<<8:
|
||||
dst[1] = uint8(n)
|
||||
dst[0] = 60<<2 | tagLiteral
|
||||
i = 2
|
||||
case n < 1<<16:
|
||||
dst[2] = uint8(n >> 8)
|
||||
dst[1] = uint8(n)
|
||||
dst[0] = 61<<2 | tagLiteral
|
||||
i = 3
|
||||
case n < 1<<24:
|
||||
dst[3] = uint8(n >> 16)
|
||||
dst[2] = uint8(n >> 8)
|
||||
dst[1] = uint8(n)
|
||||
dst[0] = 62<<2 | tagLiteral
|
||||
i = 4
|
||||
default:
|
||||
dst[4] = uint8(n >> 24)
|
||||
dst[3] = uint8(n >> 16)
|
||||
dst[2] = uint8(n >> 8)
|
||||
dst[1] = uint8(n)
|
||||
dst[0] = 63<<2 | tagLiteral
|
||||
i = 5
|
||||
}
|
||||
return i + copy(dst[i:], lit)
|
||||
}
|
||||
|
||||
// emitRepeat writes a repeat chunk and returns the number of bytes written.
|
||||
// Length must be at least 4 and < 1<<24
|
||||
func emitRepeat(dst []byte, offset, length int) int {
|
||||
// Repeat offset, make length cheaper
|
||||
length -= 4
|
||||
if length <= 4 {
|
||||
dst[0] = uint8(length)<<2 | tagCopy1
|
||||
dst[1] = 0
|
||||
return 2
|
||||
}
|
||||
if length < 8 && offset < 2048 {
|
||||
// Encode WITH offset
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(offset>>8)<<5 | uint8(length)<<2 | tagCopy1
|
||||
return 2
|
||||
}
|
||||
if length < (1<<8)+4 {
|
||||
length -= 4
|
||||
dst[2] = uint8(length)
|
||||
dst[1] = 0
|
||||
dst[0] = 5<<2 | tagCopy1
|
||||
return 3
|
||||
}
|
||||
if length < (1<<16)+(1<<8) {
|
||||
length -= 1 << 8
|
||||
dst[3] = uint8(length >> 8)
|
||||
dst[2] = uint8(length >> 0)
|
||||
dst[1] = 0
|
||||
dst[0] = 6<<2 | tagCopy1
|
||||
return 4
|
||||
}
|
||||
const maxRepeat = (1 << 24) - 1
|
||||
length -= 1 << 16
|
||||
left := 0
|
||||
if length > maxRepeat {
|
||||
left = length - maxRepeat + 4
|
||||
length = maxRepeat - 4
|
||||
}
|
||||
dst[4] = uint8(length >> 16)
|
||||
dst[3] = uint8(length >> 8)
|
||||
dst[2] = uint8(length >> 0)
|
||||
dst[1] = 0
|
||||
dst[0] = 7<<2 | tagCopy1
|
||||
if left > 0 {
|
||||
return 5 + emitRepeat(dst[5:], offset, left)
|
||||
}
|
||||
return 5
|
||||
}
|
||||
|
||||
// emitCopy writes a copy chunk and returns the number of bytes written.
|
||||
//
|
||||
// It assumes that:
|
||||
//
|
||||
// dst is long enough to hold the encoded bytes
|
||||
// 1 <= offset && offset <= math.MaxUint32
|
||||
// 4 <= length && length <= 1 << 24
|
||||
func emitCopy(dst []byte, offset, length int) int {
|
||||
if offset >= 65536 {
|
||||
i := 0
|
||||
if length > 64 {
|
||||
// Emit a length 64 copy, encoded as 5 bytes.
|
||||
dst[4] = uint8(offset >> 24)
|
||||
dst[3] = uint8(offset >> 16)
|
||||
dst[2] = uint8(offset >> 8)
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = 63<<2 | tagCopy4
|
||||
length -= 64
|
||||
if length >= 4 {
|
||||
// Emit remaining as repeats
|
||||
return 5 + emitRepeat(dst[5:], offset, length)
|
||||
}
|
||||
i = 5
|
||||
}
|
||||
if length == 0 {
|
||||
return i
|
||||
}
|
||||
// Emit a copy, offset encoded as 4 bytes.
|
||||
dst[i+0] = uint8(length-1)<<2 | tagCopy4
|
||||
dst[i+1] = uint8(offset)
|
||||
dst[i+2] = uint8(offset >> 8)
|
||||
dst[i+3] = uint8(offset >> 16)
|
||||
dst[i+4] = uint8(offset >> 24)
|
||||
return i + 5
|
||||
}
|
||||
|
||||
// Offset no more than 2 bytes.
|
||||
if length > 64 {
|
||||
off := 3
|
||||
if offset < 2048 {
|
||||
// emit 8 bytes as tagCopy1, rest as repeats.
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(offset>>8)<<5 | uint8(8-4)<<2 | tagCopy1
|
||||
length -= 8
|
||||
off = 2
|
||||
} else {
|
||||
// Emit a length 60 copy, encoded as 3 bytes.
|
||||
// Emit remaining as repeat value (minimum 4 bytes).
|
||||
dst[2] = uint8(offset >> 8)
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = 59<<2 | tagCopy2
|
||||
length -= 60
|
||||
}
|
||||
// Emit remaining as repeats, at least 4 bytes remain.
|
||||
return off + emitRepeat(dst[off:], offset, length)
|
||||
}
|
||||
if length >= 12 || offset >= 2048 {
|
||||
// Emit the remaining copy, encoded as 3 bytes.
|
||||
dst[2] = uint8(offset >> 8)
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(length-1)<<2 | tagCopy2
|
||||
return 3
|
||||
}
|
||||
// Emit the remaining copy, encoded as 2 bytes.
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(offset>>8)<<5 | uint8(length-4)<<2 | tagCopy1
|
||||
return 2
|
||||
}
|
||||
|
||||
// emitCopyNoRepeat writes a copy chunk and returns the number of bytes written.
|
||||
//
|
||||
// It assumes that:
|
||||
//
|
||||
// dst is long enough to hold the encoded bytes
|
||||
// 1 <= offset && offset <= math.MaxUint32
|
||||
// 4 <= length && length <= 1 << 24
|
||||
func emitCopyNoRepeat(dst []byte, offset, length int) int {
|
||||
if offset >= 65536 {
|
||||
i := 0
|
||||
if length > 64 {
|
||||
// Emit a length 64 copy, encoded as 5 bytes.
|
||||
dst[4] = uint8(offset >> 24)
|
||||
dst[3] = uint8(offset >> 16)
|
||||
dst[2] = uint8(offset >> 8)
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = 63<<2 | tagCopy4
|
||||
length -= 64
|
||||
if length >= 4 {
|
||||
// Emit remaining as repeats
|
||||
return 5 + emitCopyNoRepeat(dst[5:], offset, length)
|
||||
}
|
||||
i = 5
|
||||
}
|
||||
if length == 0 {
|
||||
return i
|
||||
}
|
||||
// Emit a copy, offset encoded as 4 bytes.
|
||||
dst[i+0] = uint8(length-1)<<2 | tagCopy4
|
||||
dst[i+1] = uint8(offset)
|
||||
dst[i+2] = uint8(offset >> 8)
|
||||
dst[i+3] = uint8(offset >> 16)
|
||||
dst[i+4] = uint8(offset >> 24)
|
||||
return i + 5
|
||||
}
|
||||
|
||||
// Offset no more than 2 bytes.
|
||||
if length > 64 {
|
||||
// Emit a length 60 copy, encoded as 3 bytes.
|
||||
// Emit remaining as repeat value (minimum 4 bytes).
|
||||
dst[2] = uint8(offset >> 8)
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = 59<<2 | tagCopy2
|
||||
length -= 60
|
||||
// Emit remaining as repeats, at least 4 bytes remain.
|
||||
return 3 + emitCopyNoRepeat(dst[3:], offset, length)
|
||||
}
|
||||
if length >= 12 || offset >= 2048 {
|
||||
// Emit the remaining copy, encoded as 3 bytes.
|
||||
dst[2] = uint8(offset >> 8)
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(length-1)<<2 | tagCopy2
|
||||
return 3
|
||||
}
|
||||
// Emit the remaining copy, encoded as 2 bytes.
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(offset>>8)<<5 | uint8(length-4)<<2 | tagCopy1
|
||||
return 2
|
||||
}
|
||||
|
||||
// matchLen returns how many bytes match in a and b
|
||||
//
|
||||
// It assumes that:
|
||||
//
|
||||
// len(a) <= len(b)
|
||||
func matchLen(a []byte, b []byte) int {
|
||||
b = b[:len(a)]
|
||||
var checked int
|
||||
if len(a) > 4 {
|
||||
// Try 4 bytes first
|
||||
if diff := load32(a, 0) ^ load32(b, 0); diff != 0 {
|
||||
return bits.TrailingZeros32(diff) >> 3
|
||||
}
|
||||
// Switch to 8 byte matching.
|
||||
checked = 4
|
||||
a = a[4:]
|
||||
b = b[4:]
|
||||
for len(a) >= 8 {
|
||||
b = b[:len(a)]
|
||||
if diff := load64(a, 0) ^ load64(b, 0); diff != 0 {
|
||||
return checked + (bits.TrailingZeros64(diff) >> 3)
|
||||
}
|
||||
checked += 8
|
||||
a = a[8:]
|
||||
b = b[8:]
|
||||
}
|
||||
}
|
||||
b = b[:len(a)]
|
||||
for i := range a {
|
||||
if a[i] != b[i] {
|
||||
return int(i) + checked
|
||||
}
|
||||
}
|
||||
return len(a) + checked
|
||||
}
|
||||
|
||||
// input must be > inputMargin
|
||||
func calcBlockSize(src []byte, _ *[32768]byte) (d int) {
|
||||
// Initialize the hash table.
|
||||
const (
|
||||
tableBits = 13
|
||||
maxTableSize = 1 << tableBits
|
||||
)
|
||||
|
||||
var table [maxTableSize]uint32
|
||||
|
||||
// sLimit is when to stop looking for offset/length copies. The inputMargin
|
||||
// lets us use a fast path for emitLiteral in the main loop, while we are
|
||||
// looking for copies.
|
||||
sLimit := len(src) - inputMargin
|
||||
|
||||
// Bail if we can't compress to at least this.
|
||||
dstLimit := len(src) - len(src)>>5 - 5
|
||||
|
||||
// nextEmit is where in src the next emitLiteral should start from.
|
||||
nextEmit := 0
|
||||
|
||||
// The encoded form must start with a literal, as there are no previous
|
||||
// bytes to copy, so we start looking for hash matches at s == 1.
|
||||
s := 1
|
||||
cv := load64(src, s)
|
||||
|
||||
// We search for a repeat at -1, but don't output repeats when nextEmit == 0
|
||||
repeat := 1
|
||||
|
||||
for {
|
||||
candidate := 0
|
||||
for {
|
||||
// Next src position to check
|
||||
nextS := s + (s-nextEmit)>>6 + 4
|
||||
if nextS > sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
hash0 := hash6(cv, tableBits)
|
||||
hash1 := hash6(cv>>8, tableBits)
|
||||
candidate = int(table[hash0])
|
||||
candidate2 := int(table[hash1])
|
||||
table[hash0] = uint32(s)
|
||||
table[hash1] = uint32(s + 1)
|
||||
hash2 := hash6(cv>>16, tableBits)
|
||||
|
||||
// Check repeat at offset checkRep.
|
||||
const checkRep = 1
|
||||
if uint32(cv>>(checkRep*8)) == load32(src, s-repeat+checkRep) {
|
||||
base := s + checkRep
|
||||
// Extend back
|
||||
for i := base - repeat; base > nextEmit && i > 0 && src[i-1] == src[base-1]; {
|
||||
i--
|
||||
base--
|
||||
}
|
||||
d += emitLiteralSize(src[nextEmit:base])
|
||||
|
||||
// Extend forward
|
||||
candidate := s - repeat + 4 + checkRep
|
||||
s += 4 + checkRep
|
||||
for s <= sLimit {
|
||||
if diff := load64(src, s) ^ load64(src, candidate); diff != 0 {
|
||||
s += bits.TrailingZeros64(diff) >> 3
|
||||
break
|
||||
}
|
||||
s += 8
|
||||
candidate += 8
|
||||
}
|
||||
|
||||
d += emitCopyNoRepeatSize(repeat, s-base)
|
||||
nextEmit = s
|
||||
if s >= sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
cv = load64(src, s)
|
||||
continue
|
||||
}
|
||||
|
||||
if uint32(cv) == load32(src, candidate) {
|
||||
break
|
||||
}
|
||||
candidate = int(table[hash2])
|
||||
if uint32(cv>>8) == load32(src, candidate2) {
|
||||
table[hash2] = uint32(s + 2)
|
||||
candidate = candidate2
|
||||
s++
|
||||
break
|
||||
}
|
||||
table[hash2] = uint32(s + 2)
|
||||
if uint32(cv>>16) == load32(src, candidate) {
|
||||
s += 2
|
||||
break
|
||||
}
|
||||
|
||||
cv = load64(src, nextS)
|
||||
s = nextS
|
||||
}
|
||||
|
||||
// Extend backwards
|
||||
for candidate > 0 && s > nextEmit && src[candidate-1] == src[s-1] {
|
||||
candidate--
|
||||
s--
|
||||
}
|
||||
|
||||
// Bail if we exceed the maximum size.
|
||||
if d+(s-nextEmit) > dstLimit {
|
||||
return 0
|
||||
}
|
||||
|
||||
// A 4-byte match has been found. We'll later see if more than 4 bytes
|
||||
// match. But, prior to the match, src[nextEmit:s] are unmatched. Emit
|
||||
// them as literal bytes.
|
||||
|
||||
d += emitLiteralSize(src[nextEmit:s])
|
||||
|
||||
// Call emitCopy, and then see if another emitCopy could be our next
|
||||
// move. Repeat until we find no match for the input immediately after
|
||||
// what was consumed by the last emitCopy call.
|
||||
//
|
||||
// If we exit this loop normally then we need to call emitLiteral next,
|
||||
// though we don't yet know how big the literal will be. We handle that
|
||||
// by proceeding to the next iteration of the main loop. We also can
|
||||
// exit this loop via goto if we get close to exhausting the input.
|
||||
for {
|
||||
// Invariant: we have a 4-byte match at s, and no need to emit any
|
||||
// literal bytes prior to s.
|
||||
base := s
|
||||
repeat = base - candidate
|
||||
|
||||
// Extend the 4-byte match as long as possible.
|
||||
s += 4
|
||||
candidate += 4
|
||||
for s <= len(src)-8 {
|
||||
if diff := load64(src, s) ^ load64(src, candidate); diff != 0 {
|
||||
s += bits.TrailingZeros64(diff) >> 3
|
||||
break
|
||||
}
|
||||
s += 8
|
||||
candidate += 8
|
||||
}
|
||||
|
||||
d += emitCopyNoRepeatSize(repeat, s-base)
|
||||
if false {
|
||||
// Validate match.
|
||||
a := src[base:s]
|
||||
b := src[base-repeat : base-repeat+(s-base)]
|
||||
if !bytes.Equal(a, b) {
|
||||
panic("mismatch")
|
||||
}
|
||||
}
|
||||
|
||||
nextEmit = s
|
||||
if s >= sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
if d > dstLimit {
|
||||
// Do we have space for more, if not bail.
|
||||
return 0
|
||||
}
|
||||
// Check for an immediate match, otherwise start search at s+1
|
||||
x := load64(src, s-2)
|
||||
m2Hash := hash6(x, tableBits)
|
||||
currHash := hash6(x>>16, tableBits)
|
||||
candidate = int(table[currHash])
|
||||
table[m2Hash] = uint32(s - 2)
|
||||
table[currHash] = uint32(s)
|
||||
if uint32(x>>16) != load32(src, candidate) {
|
||||
cv = load64(src, s+1)
|
||||
s++
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
emitRemainder:
|
||||
if nextEmit < len(src) {
|
||||
// Bail if we exceed the maximum size.
|
||||
if d+len(src)-nextEmit > dstLimit {
|
||||
return 0
|
||||
}
|
||||
d += emitLiteralSize(src[nextEmit:])
|
||||
}
|
||||
return d
|
||||
}
|
||||
|
||||
// length must be > inputMargin.
|
||||
func calcBlockSizeSmall(src []byte, _ *[2048]byte) (d int) {
|
||||
// Initialize the hash table.
|
||||
const (
|
||||
tableBits = 9
|
||||
maxTableSize = 1 << tableBits
|
||||
)
|
||||
|
||||
var table [maxTableSize]uint32
|
||||
|
||||
// sLimit is when to stop looking for offset/length copies. The inputMargin
|
||||
// lets us use a fast path for emitLiteral in the main loop, while we are
|
||||
// looking for copies.
|
||||
sLimit := len(src) - inputMargin
|
||||
|
||||
// Bail if we can't compress to at least this.
|
||||
dstLimit := len(src) - len(src)>>5 - 5
|
||||
|
||||
// nextEmit is where in src the next emitLiteral should start from.
|
||||
nextEmit := 0
|
||||
|
||||
// The encoded form must start with a literal, as there are no previous
|
||||
// bytes to copy, so we start looking for hash matches at s == 1.
|
||||
s := 1
|
||||
cv := load64(src, s)
|
||||
|
||||
// We search for a repeat at -1, but don't output repeats when nextEmit == 0
|
||||
repeat := 1
|
||||
|
||||
for {
|
||||
candidate := 0
|
||||
for {
|
||||
// Next src position to check
|
||||
nextS := s + (s-nextEmit)>>6 + 4
|
||||
if nextS > sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
hash0 := hash6(cv, tableBits)
|
||||
hash1 := hash6(cv>>8, tableBits)
|
||||
candidate = int(table[hash0])
|
||||
candidate2 := int(table[hash1])
|
||||
table[hash0] = uint32(s)
|
||||
table[hash1] = uint32(s + 1)
|
||||
hash2 := hash6(cv>>16, tableBits)
|
||||
|
||||
// Check repeat at offset checkRep.
|
||||
const checkRep = 1
|
||||
if uint32(cv>>(checkRep*8)) == load32(src, s-repeat+checkRep) {
|
||||
base := s + checkRep
|
||||
// Extend back
|
||||
for i := base - repeat; base > nextEmit && i > 0 && src[i-1] == src[base-1]; {
|
||||
i--
|
||||
base--
|
||||
}
|
||||
d += emitLiteralSize(src[nextEmit:base])
|
||||
|
||||
// Extend forward
|
||||
candidate := s - repeat + 4 + checkRep
|
||||
s += 4 + checkRep
|
||||
for s <= sLimit {
|
||||
if diff := load64(src, s) ^ load64(src, candidate); diff != 0 {
|
||||
s += bits.TrailingZeros64(diff) >> 3
|
||||
break
|
||||
}
|
||||
s += 8
|
||||
candidate += 8
|
||||
}
|
||||
|
||||
d += emitCopyNoRepeatSize(repeat, s-base)
|
||||
nextEmit = s
|
||||
if s >= sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
cv = load64(src, s)
|
||||
continue
|
||||
}
|
||||
|
||||
if uint32(cv) == load32(src, candidate) {
|
||||
break
|
||||
}
|
||||
candidate = int(table[hash2])
|
||||
if uint32(cv>>8) == load32(src, candidate2) {
|
||||
table[hash2] = uint32(s + 2)
|
||||
candidate = candidate2
|
||||
s++
|
||||
break
|
||||
}
|
||||
table[hash2] = uint32(s + 2)
|
||||
if uint32(cv>>16) == load32(src, candidate) {
|
||||
s += 2
|
||||
break
|
||||
}
|
||||
|
||||
cv = load64(src, nextS)
|
||||
s = nextS
|
||||
}
|
||||
|
||||
// Extend backwards
|
||||
for candidate > 0 && s > nextEmit && src[candidate-1] == src[s-1] {
|
||||
candidate--
|
||||
s--
|
||||
}
|
||||
|
||||
// Bail if we exceed the maximum size.
|
||||
if d+(s-nextEmit) > dstLimit {
|
||||
return 0
|
||||
}
|
||||
|
||||
// A 4-byte match has been found. We'll later see if more than 4 bytes
|
||||
// match. But, prior to the match, src[nextEmit:s] are unmatched. Emit
|
||||
// them as literal bytes.
|
||||
|
||||
d += emitLiteralSize(src[nextEmit:s])
|
||||
|
||||
// Call emitCopy, and then see if another emitCopy could be our next
|
||||
// move. Repeat until we find no match for the input immediately after
|
||||
// what was consumed by the last emitCopy call.
|
||||
//
|
||||
// If we exit this loop normally then we need to call emitLiteral next,
|
||||
// though we don't yet know how big the literal will be. We handle that
|
||||
// by proceeding to the next iteration of the main loop. We also can
|
||||
// exit this loop via goto if we get close to exhausting the input.
|
||||
for {
|
||||
// Invariant: we have a 4-byte match at s, and no need to emit any
|
||||
// literal bytes prior to s.
|
||||
base := s
|
||||
repeat = base - candidate
|
||||
|
||||
// Extend the 4-byte match as long as possible.
|
||||
s += 4
|
||||
candidate += 4
|
||||
for s <= len(src)-8 {
|
||||
if diff := load64(src, s) ^ load64(src, candidate); diff != 0 {
|
||||
s += bits.TrailingZeros64(diff) >> 3
|
||||
break
|
||||
}
|
||||
s += 8
|
||||
candidate += 8
|
||||
}
|
||||
|
||||
d += emitCopyNoRepeatSize(repeat, s-base)
|
||||
if false {
|
||||
// Validate match.
|
||||
a := src[base:s]
|
||||
b := src[base-repeat : base-repeat+(s-base)]
|
||||
if !bytes.Equal(a, b) {
|
||||
panic("mismatch")
|
||||
}
|
||||
}
|
||||
|
||||
nextEmit = s
|
||||
if s >= sLimit {
|
||||
goto emitRemainder
|
||||
}
|
||||
|
||||
if d > dstLimit {
|
||||
// Do we have space for more, if not bail.
|
||||
return 0
|
||||
}
|
||||
// Check for an immediate match, otherwise start search at s+1
|
||||
x := load64(src, s-2)
|
||||
m2Hash := hash6(x, tableBits)
|
||||
currHash := hash6(x>>16, tableBits)
|
||||
candidate = int(table[currHash])
|
||||
table[m2Hash] = uint32(s - 2)
|
||||
table[currHash] = uint32(s)
|
||||
if uint32(x>>16) != load32(src, candidate) {
|
||||
cv = load64(src, s+1)
|
||||
s++
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
emitRemainder:
|
||||
if nextEmit < len(src) {
|
||||
// Bail if we exceed the maximum size.
|
||||
if d+len(src)-nextEmit > dstLimit {
|
||||
return 0
|
||||
}
|
||||
d += emitLiteralSize(src[nextEmit:])
|
||||
}
|
||||
return d
|
||||
}
|
||||
|
||||
// emitLiteral writes a literal chunk and returns the number of bytes written.
|
||||
//
|
||||
// It assumes that:
|
||||
//
|
||||
// dst is long enough to hold the encoded bytes
|
||||
// 0 <= len(lit) && len(lit) <= math.MaxUint32
|
||||
func emitLiteralSize(lit []byte) int {
|
||||
if len(lit) == 0 {
|
||||
return 0
|
||||
}
|
||||
switch {
|
||||
case len(lit) <= 60:
|
||||
return len(lit) + 1
|
||||
case len(lit) <= 1<<8:
|
||||
return len(lit) + 2
|
||||
case len(lit) <= 1<<16:
|
||||
return len(lit) + 3
|
||||
case len(lit) <= 1<<24:
|
||||
return len(lit) + 4
|
||||
default:
|
||||
return len(lit) + 5
|
||||
}
|
||||
}
|
||||
|
||||
func cvtLZ4BlockAsm(dst []byte, src []byte) (uncompressed int, dstUsed int) {
|
||||
panic("cvtLZ4BlockAsm should be unreachable")
|
||||
}
|
||||
|
||||
func cvtLZ4BlockSnappyAsm(dst []byte, src []byte) (uncompressed int, dstUsed int) {
|
||||
panic("cvtLZ4BlockSnappyAsm should be unreachable")
|
||||
}
|
||||
|
||||
func cvtLZ4sBlockAsm(dst []byte, src []byte) (uncompressed int, dstUsed int) {
|
||||
panic("cvtLZ4sBlockAsm should be unreachable")
|
||||
}
|
||||
|
||||
func cvtLZ4sBlockSnappyAsm(dst []byte, src []byte) (uncompressed int, dstUsed int) {
|
||||
panic("cvtLZ4sBlockSnappyAsm should be unreachable")
|
||||
}
|
||||
Generated
Vendored
-20883
File diff suppressed because it is too large
Load Diff
Generated
Vendored
-23562
File diff suppressed because it is too large
Load Diff
Generated
Vendored
-228
@@ -1,228 +0,0 @@
|
||||
// Code generated by command: go run gen.go -out ../encodeblock_amd64.s -stubs ../encodeblock_asm.go -pkg=s2. DO NOT EDIT.
|
||||
|
||||
//go:build (amd64 || arm64) && !appengine && !noasm && gc && !noasm
|
||||
|
||||
package s2
|
||||
|
||||
func _dummy_()
|
||||
|
||||
// encodeBlockAsm encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 4294967295 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeBlockAsm(dst []byte, src []byte, tmp *[65536]byte) int
|
||||
|
||||
// encodeBlockAsm4MB encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 4194304 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeBlockAsm4MB(dst []byte, src []byte, tmp *[65536]byte) int
|
||||
|
||||
// encodeBlockAsm12B encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 16383 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeBlockAsm12B(dst []byte, src []byte, tmp *[16384]byte) int
|
||||
|
||||
// encodeBlockAsm10B encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 4095 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeBlockAsm10B(dst []byte, src []byte, tmp *[4096]byte) int
|
||||
|
||||
// encodeBlockAsm8B encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 511 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeBlockAsm8B(dst []byte, src []byte, tmp *[1024]byte) int
|
||||
|
||||
// encodeBetterBlockAsm encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 4294967295 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeBetterBlockAsm(dst []byte, src []byte, tmp *[589824]byte) int
|
||||
|
||||
// encodeBetterBlockAsm4MB encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 4194304 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeBetterBlockAsm4MB(dst []byte, src []byte, tmp *[589824]byte) int
|
||||
|
||||
// encodeBetterBlockAsm12B encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 16383 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeBetterBlockAsm12B(dst []byte, src []byte, tmp *[81920]byte) int
|
||||
|
||||
// encodeBetterBlockAsm10B encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 4095 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeBetterBlockAsm10B(dst []byte, src []byte, tmp *[20480]byte) int
|
||||
|
||||
// encodeBetterBlockAsm8B encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 511 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeBetterBlockAsm8B(dst []byte, src []byte, tmp *[5120]byte) int
|
||||
|
||||
// encodeSnappyBlockAsm encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 4294967295 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeSnappyBlockAsm(dst []byte, src []byte, tmp *[65536]byte) int
|
||||
|
||||
// encodeSnappyBlockAsm64K encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 65535 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeSnappyBlockAsm64K(dst []byte, src []byte, tmp *[65536]byte) int
|
||||
|
||||
// encodeSnappyBlockAsm12B encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 16383 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeSnappyBlockAsm12B(dst []byte, src []byte, tmp *[16384]byte) int
|
||||
|
||||
// encodeSnappyBlockAsm10B encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 4095 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeSnappyBlockAsm10B(dst []byte, src []byte, tmp *[4096]byte) int
|
||||
|
||||
// encodeSnappyBlockAsm8B encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 511 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeSnappyBlockAsm8B(dst []byte, src []byte, tmp *[1024]byte) int
|
||||
|
||||
// encodeSnappyBetterBlockAsm encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 4294967295 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeSnappyBetterBlockAsm(dst []byte, src []byte, tmp *[589824]byte) int
|
||||
|
||||
// encodeSnappyBetterBlockAsm64K encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 65535 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeSnappyBetterBlockAsm64K(dst []byte, src []byte, tmp *[294912]byte) int
|
||||
|
||||
// encodeSnappyBetterBlockAsm12B encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 16383 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeSnappyBetterBlockAsm12B(dst []byte, src []byte, tmp *[81920]byte) int
|
||||
|
||||
// encodeSnappyBetterBlockAsm10B encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 4095 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeSnappyBetterBlockAsm10B(dst []byte, src []byte, tmp *[20480]byte) int
|
||||
|
||||
// encodeSnappyBetterBlockAsm8B encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 511 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func encodeSnappyBetterBlockAsm8B(dst []byte, src []byte, tmp *[5120]byte) int
|
||||
|
||||
// calcBlockSize encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 4294967295 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func calcBlockSize(src []byte, tmp *[32768]byte) int
|
||||
|
||||
// calcBlockSizeSmall encodes a non-empty src to a guaranteed-large-enough dst.
|
||||
// Maximum input 1024 bytes.
|
||||
// It assumes that the varint-encoded length of the decompressed bytes has already been written.
|
||||
//
|
||||
//go:noescape
|
||||
func calcBlockSizeSmall(src []byte, tmp *[2048]byte) int
|
||||
|
||||
// emitLiteral writes a literal chunk and returns the number of bytes written.
|
||||
//
|
||||
// It assumes that:
|
||||
//
|
||||
// dst is long enough to hold the encoded bytes with margin of 0 bytes
|
||||
// 0 <= len(lit) && len(lit) <= math.MaxUint32
|
||||
//
|
||||
//go:noescape
|
||||
func emitLiteral(dst []byte, lit []byte) int
|
||||
|
||||
// emitRepeat writes a repeat chunk and returns the number of bytes written.
|
||||
// Length must be at least 4 and < 1<<32
|
||||
//
|
||||
//go:noescape
|
||||
func emitRepeat(dst []byte, offset int, length int) int
|
||||
|
||||
// emitCopy writes a copy chunk and returns the number of bytes written.
|
||||
//
|
||||
// It assumes that:
|
||||
//
|
||||
// dst is long enough to hold the encoded bytes
|
||||
// 1 <= offset && offset <= math.MaxUint32
|
||||
// 4 <= length && length <= 1 << 24
|
||||
//
|
||||
//go:noescape
|
||||
func emitCopy(dst []byte, offset int, length int) int
|
||||
|
||||
// emitCopyNoRepeat writes a copy chunk and returns the number of bytes written.
|
||||
//
|
||||
// It assumes that:
|
||||
//
|
||||
// dst is long enough to hold the encoded bytes
|
||||
// 1 <= offset && offset <= math.MaxUint32
|
||||
// 4 <= length && length <= 1 << 24
|
||||
//
|
||||
//go:noescape
|
||||
func emitCopyNoRepeat(dst []byte, offset int, length int) int
|
||||
|
||||
// matchLen returns how many bytes match in a and b
|
||||
//
|
||||
// It assumes that:
|
||||
//
|
||||
// len(a) <= len(b)
|
||||
//
|
||||
//go:noescape
|
||||
func matchLen(a []byte, b []byte) int
|
||||
|
||||
// cvtLZ4Block converts an LZ4 block to S2
|
||||
//
|
||||
//go:noescape
|
||||
func cvtLZ4BlockAsm(dst []byte, src []byte) (uncompressed int, dstUsed int)
|
||||
|
||||
// cvtLZ4sBlock converts an LZ4s block to S2
|
||||
//
|
||||
//go:noescape
|
||||
func cvtLZ4sBlockAsm(dst []byte, src []byte) (uncompressed int, dstUsed int)
|
||||
|
||||
// cvtLZ4Block converts an LZ4 block to Snappy
|
||||
//
|
||||
//go:noescape
|
||||
func cvtLZ4BlockSnappyAsm(dst []byte, src []byte) (uncompressed int, dstUsed int)
|
||||
|
||||
// cvtLZ4sBlock converts an LZ4s block to Snappy
|
||||
//
|
||||
//go:noescape
|
||||
func cvtLZ4sBlockSnappyAsm(dst []byte, src []byte) (uncompressed int, dstUsed int)
|
||||
Generated
Vendored
-65
@@ -1,65 +0,0 @@
|
||||
package s2
|
||||
|
||||
import "sync"
|
||||
|
||||
// Table size constants
|
||||
const (
|
||||
betterLongTableBits = 17
|
||||
betterLongTableSize = 1 << betterLongTableBits // 131072
|
||||
|
||||
betterShortTableBits = 14
|
||||
betterShortTableSize = 1 << betterShortTableBits // 16384
|
||||
|
||||
betterSnappyLongTableBits = 16
|
||||
betterSnappyLongTableSize = 1 << betterSnappyLongTableBits // 65536
|
||||
|
||||
bestLongTableBits = 19
|
||||
bestLongTableSize = 1 << bestLongTableBits // 524288
|
||||
|
||||
bestShortTableBits = 16
|
||||
bestShortTableSize = 1 << bestShortTableBits // 65536
|
||||
)
|
||||
|
||||
type betterTables struct {
|
||||
lTable [betterLongTableSize]uint32
|
||||
sTable [betterShortTableSize]uint32
|
||||
}
|
||||
|
||||
var betterTablePool = sync.Pool{New: func() any { return &betterTables{} }}
|
||||
|
||||
// betterSnappyTables holds better-snappy compression hash tables.
|
||||
type betterSnappyTables struct {
|
||||
lTable [betterSnappyLongTableSize]uint32
|
||||
sTable [betterShortTableSize]uint32
|
||||
}
|
||||
|
||||
var betterSnappyTablePool = sync.Pool{New: func() any { return &betterSnappyTables{} }}
|
||||
|
||||
// bestTables holds best compression hash tables.
|
||||
type bestTables struct {
|
||||
lTable [bestLongTableSize]uint64
|
||||
sTable [bestShortTableSize]uint64
|
||||
}
|
||||
|
||||
var bestTablePool = sync.Pool{New: func() any { return &bestTables{} }}
|
||||
|
||||
// getBetterTables gets a zeroed betterTables from the pool.
|
||||
func getBetterTables() *betterTables {
|
||||
t := betterTablePool.Get().(*betterTables)
|
||||
*t = betterTables{}
|
||||
return t
|
||||
}
|
||||
|
||||
// getBetterSnappyTables gets a zeroed betterSnappyTables from the pool.
|
||||
func getBetterSnappyTables() *betterSnappyTables {
|
||||
t := betterSnappyTablePool.Get().(*betterSnappyTables)
|
||||
*t = betterSnappyTables{}
|
||||
return t
|
||||
}
|
||||
|
||||
// getBestTables gets a zeroed bestTables from the pool.
|
||||
func getBestTables() *bestTables {
|
||||
t := bestTablePool.Get().(*bestTables)
|
||||
*t = bestTables{}
|
||||
return t
|
||||
}
|
||||
Generated
Vendored
-602
@@ -1,602 +0,0 @@
|
||||
// Copyright (c) 2022+ Klaus Post. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package s2
|
||||
|
||||
import (
|
||||
"bytes"
|
||||
"encoding/binary"
|
||||
"encoding/json"
|
||||
"fmt"
|
||||
"io"
|
||||
"sort"
|
||||
)
|
||||
|
||||
const (
|
||||
S2IndexHeader = "s2idx\x00"
|
||||
S2IndexTrailer = "\x00xdi2s"
|
||||
maxIndexEntries = 1 << 16
|
||||
// If distance is less than this, we do not add the entry.
|
||||
minIndexDist = 1 << 20
|
||||
)
|
||||
|
||||
// Index represents an S2/Snappy index.
|
||||
type Index struct {
|
||||
TotalUncompressed int64 // Total Uncompressed size if known. Will be -1 if unknown.
|
||||
TotalCompressed int64 // Total Compressed size if known. Will be -1 if unknown.
|
||||
info []struct {
|
||||
compressedOffset int64
|
||||
uncompressedOffset int64
|
||||
}
|
||||
estBlockUncomp int64
|
||||
}
|
||||
|
||||
func (i *Index) reset(maxBlock int) {
|
||||
i.estBlockUncomp = int64(maxBlock)
|
||||
i.TotalCompressed = -1
|
||||
i.TotalUncompressed = -1
|
||||
if len(i.info) > 0 {
|
||||
i.info = i.info[:0]
|
||||
}
|
||||
}
|
||||
|
||||
// allocInfos will allocate an empty slice of infos.
|
||||
func (i *Index) allocInfos(n int) {
|
||||
if n > maxIndexEntries {
|
||||
panic("n > maxIndexEntries")
|
||||
}
|
||||
i.info = make([]struct {
|
||||
compressedOffset int64
|
||||
uncompressedOffset int64
|
||||
}, 0, n)
|
||||
}
|
||||
|
||||
// add an uncompressed and compressed pair.
|
||||
// Entries must be sent in order.
|
||||
func (i *Index) add(compressedOffset, uncompressedOffset int64) error {
|
||||
if i == nil {
|
||||
return nil
|
||||
}
|
||||
lastIdx := len(i.info) - 1
|
||||
if lastIdx >= 0 {
|
||||
latest := i.info[lastIdx]
|
||||
if latest.uncompressedOffset == uncompressedOffset {
|
||||
// Uncompressed didn't change, don't add entry,
|
||||
// but update start index.
|
||||
latest.compressedOffset = compressedOffset
|
||||
i.info[lastIdx] = latest
|
||||
return nil
|
||||
}
|
||||
if latest.uncompressedOffset > uncompressedOffset {
|
||||
return fmt.Errorf("internal error: Earlier uncompressed received (%d > %d)", latest.uncompressedOffset, uncompressedOffset)
|
||||
}
|
||||
if latest.compressedOffset > compressedOffset {
|
||||
return fmt.Errorf("internal error: Earlier compressed received (%d > %d)", latest.compressedOffset, compressedOffset)
|
||||
}
|
||||
if latest.uncompressedOffset+minIndexDist > uncompressedOffset {
|
||||
// Only add entry if distance is large enough.
|
||||
return nil
|
||||
}
|
||||
}
|
||||
i.info = append(i.info, struct {
|
||||
compressedOffset int64
|
||||
uncompressedOffset int64
|
||||
}{compressedOffset: compressedOffset, uncompressedOffset: uncompressedOffset})
|
||||
return nil
|
||||
}
|
||||
|
||||
// Find the offset at or before the wanted (uncompressed) offset.
|
||||
// If offset is 0 or positive it is the offset from the beginning of the file.
|
||||
// If the uncompressed size is known, the offset must be within the file.
|
||||
// If an offset outside the file is requested io.ErrUnexpectedEOF is returned.
|
||||
// If the offset is negative, it is interpreted as the distance from the end of the file,
|
||||
// where -1 represents the last byte.
|
||||
// If offset from the end of the file is requested, but size is unknown,
|
||||
// ErrUnsupported will be returned.
|
||||
func (i *Index) Find(offset int64) (compressedOff, uncompressedOff int64, err error) {
|
||||
if i.TotalUncompressed < 0 {
|
||||
return 0, 0, ErrCorrupt
|
||||
}
|
||||
if offset < 0 {
|
||||
offset = i.TotalUncompressed + offset
|
||||
if offset < 0 {
|
||||
return 0, 0, io.ErrUnexpectedEOF
|
||||
}
|
||||
}
|
||||
if offset > i.TotalUncompressed {
|
||||
return 0, 0, io.ErrUnexpectedEOF
|
||||
}
|
||||
if len(i.info) > 200 {
|
||||
n := sort.Search(len(i.info), func(n int) bool {
|
||||
return i.info[n].uncompressedOffset > offset
|
||||
})
|
||||
if n == 0 {
|
||||
n = 1
|
||||
}
|
||||
return i.info[n-1].compressedOffset, i.info[n-1].uncompressedOffset, nil
|
||||
}
|
||||
for _, info := range i.info {
|
||||
if info.uncompressedOffset > offset {
|
||||
break
|
||||
}
|
||||
compressedOff = info.compressedOffset
|
||||
uncompressedOff = info.uncompressedOffset
|
||||
}
|
||||
return compressedOff, uncompressedOff, nil
|
||||
}
|
||||
|
||||
// reduce to stay below maxIndexEntries
|
||||
func (i *Index) reduce() {
|
||||
if len(i.info) < maxIndexEntries && i.estBlockUncomp >= minIndexDist {
|
||||
return
|
||||
}
|
||||
|
||||
// Algorithm, keep 1, remove removeN entries...
|
||||
removeN := (len(i.info) + 1) / maxIndexEntries
|
||||
src := i.info
|
||||
j := 0
|
||||
|
||||
// Each block should be at least 1MB, but don't reduce below 1000 entries.
|
||||
for i.estBlockUncomp*(int64(removeN)+1) < minIndexDist && len(i.info)/(removeN+1) > 1000 {
|
||||
removeN++
|
||||
}
|
||||
for idx := 0; idx < len(src); idx++ {
|
||||
i.info[j] = src[idx]
|
||||
j++
|
||||
idx += removeN
|
||||
}
|
||||
i.info = i.info[:j]
|
||||
// Update maxblock estimate.
|
||||
i.estBlockUncomp += i.estBlockUncomp * int64(removeN)
|
||||
}
|
||||
|
||||
func (i *Index) appendTo(b []byte, uncompTotal, compTotal int64) []byte {
|
||||
i.reduce()
|
||||
var tmp [binary.MaxVarintLen64]byte
|
||||
|
||||
initSize := len(b)
|
||||
// We make the start a skippable header+size.
|
||||
b = append(b, ChunkTypeIndex, 0, 0, 0)
|
||||
b = append(b, []byte(S2IndexHeader)...)
|
||||
// Total Uncompressed size
|
||||
n := binary.PutVarint(tmp[:], uncompTotal)
|
||||
b = append(b, tmp[:n]...)
|
||||
// Total Compressed size
|
||||
n = binary.PutVarint(tmp[:], compTotal)
|
||||
b = append(b, tmp[:n]...)
|
||||
// Put EstBlockUncomp size
|
||||
n = binary.PutVarint(tmp[:], i.estBlockUncomp)
|
||||
b = append(b, tmp[:n]...)
|
||||
// Put length
|
||||
n = binary.PutVarint(tmp[:], int64(len(i.info)))
|
||||
b = append(b, tmp[:n]...)
|
||||
|
||||
// Check if we should add uncompressed offsets
|
||||
var hasUncompressed byte
|
||||
for idx, info := range i.info {
|
||||
if idx == 0 {
|
||||
if info.uncompressedOffset != 0 {
|
||||
hasUncompressed = 1
|
||||
break
|
||||
}
|
||||
continue
|
||||
}
|
||||
if info.uncompressedOffset != i.info[idx-1].uncompressedOffset+i.estBlockUncomp {
|
||||
hasUncompressed = 1
|
||||
break
|
||||
}
|
||||
}
|
||||
b = append(b, hasUncompressed)
|
||||
|
||||
// Add each entry
|
||||
if hasUncompressed == 1 {
|
||||
for idx, info := range i.info {
|
||||
uOff := info.uncompressedOffset
|
||||
if idx > 0 {
|
||||
prev := i.info[idx-1]
|
||||
uOff -= prev.uncompressedOffset + (i.estBlockUncomp)
|
||||
}
|
||||
n = binary.PutVarint(tmp[:], uOff)
|
||||
b = append(b, tmp[:n]...)
|
||||
}
|
||||
}
|
||||
|
||||
// Initial compressed size estimate.
|
||||
cPredict := i.estBlockUncomp / 2
|
||||
|
||||
for idx, info := range i.info {
|
||||
cOff := info.compressedOffset
|
||||
if idx > 0 {
|
||||
prev := i.info[idx-1]
|
||||
cOff -= prev.compressedOffset + cPredict
|
||||
// Update compressed size prediction, with half the error.
|
||||
cPredict += cOff / 2
|
||||
}
|
||||
n = binary.PutVarint(tmp[:], cOff)
|
||||
b = append(b, tmp[:n]...)
|
||||
}
|
||||
|
||||
// Add Total Size.
|
||||
// Stored as fixed size for easier reading.
|
||||
binary.LittleEndian.PutUint32(tmp[:], uint32(len(b)-initSize+4+len(S2IndexTrailer)))
|
||||
b = append(b, tmp[:4]...)
|
||||
// Trailer
|
||||
b = append(b, []byte(S2IndexTrailer)...)
|
||||
|
||||
// Update size
|
||||
chunkLen := len(b) - initSize - skippableFrameHeader
|
||||
b[initSize+1] = uint8(chunkLen >> 0)
|
||||
b[initSize+2] = uint8(chunkLen >> 8)
|
||||
b[initSize+3] = uint8(chunkLen >> 16)
|
||||
//fmt.Printf("chunklen: 0x%x Uncomp:%d, Comp:%d\n", chunkLen, uncompTotal, compTotal)
|
||||
return b
|
||||
}
|
||||
|
||||
// Load a binary index.
|
||||
// A zero value Index can be used or a previous one can be reused.
|
||||
func (i *Index) Load(b []byte) ([]byte, error) {
|
||||
if len(b) <= 4+len(S2IndexHeader)+len(S2IndexTrailer) {
|
||||
return b, io.ErrUnexpectedEOF
|
||||
}
|
||||
if b[0] != ChunkTypeIndex {
|
||||
return b, ErrCorrupt
|
||||
}
|
||||
chunkLen := int(b[1]) | int(b[2])<<8 | int(b[3])<<16
|
||||
b = b[4:]
|
||||
|
||||
// Validate we have enough...
|
||||
if len(b) < chunkLen {
|
||||
return b, io.ErrUnexpectedEOF
|
||||
}
|
||||
if !bytes.Equal(b[:len(S2IndexHeader)], []byte(S2IndexHeader)) {
|
||||
return b, ErrUnsupported
|
||||
}
|
||||
b = b[len(S2IndexHeader):]
|
||||
|
||||
// Total Uncompressed
|
||||
if v, n := binary.Varint(b); n <= 0 || v < 0 {
|
||||
return b, ErrCorrupt
|
||||
} else {
|
||||
i.TotalUncompressed = v
|
||||
b = b[n:]
|
||||
}
|
||||
|
||||
// Total Compressed
|
||||
if v, n := binary.Varint(b); n <= 0 {
|
||||
return b, ErrCorrupt
|
||||
} else {
|
||||
i.TotalCompressed = v
|
||||
b = b[n:]
|
||||
}
|
||||
|
||||
// Read EstBlockUncomp
|
||||
if v, n := binary.Varint(b); n <= 0 {
|
||||
return b, ErrCorrupt
|
||||
} else {
|
||||
if v < 0 {
|
||||
return b, ErrCorrupt
|
||||
}
|
||||
i.estBlockUncomp = v
|
||||
b = b[n:]
|
||||
}
|
||||
|
||||
var entries int
|
||||
if v, n := binary.Varint(b); n <= 0 {
|
||||
return b, ErrCorrupt
|
||||
} else {
|
||||
if v < 0 || v > maxIndexEntries {
|
||||
return b, ErrCorrupt
|
||||
}
|
||||
entries = int(v)
|
||||
b = b[n:]
|
||||
}
|
||||
if cap(i.info) < entries {
|
||||
i.allocInfos(entries)
|
||||
}
|
||||
i.info = i.info[:entries]
|
||||
|
||||
if len(b) < 1 {
|
||||
return b, io.ErrUnexpectedEOF
|
||||
}
|
||||
hasUncompressed := b[0]
|
||||
b = b[1:]
|
||||
if hasUncompressed&1 != hasUncompressed {
|
||||
return b, ErrCorrupt
|
||||
}
|
||||
|
||||
// Add each uncompressed entry
|
||||
for idx := range i.info {
|
||||
var uOff int64
|
||||
if hasUncompressed != 0 {
|
||||
// Load delta
|
||||
if v, n := binary.Varint(b); n <= 0 {
|
||||
return b, ErrCorrupt
|
||||
} else {
|
||||
uOff = v
|
||||
b = b[n:]
|
||||
}
|
||||
}
|
||||
|
||||
if idx > 0 {
|
||||
prev := i.info[idx-1].uncompressedOffset
|
||||
uOff += prev + (i.estBlockUncomp)
|
||||
if uOff <= prev {
|
||||
return b, ErrCorrupt
|
||||
}
|
||||
}
|
||||
if uOff < 0 {
|
||||
return b, ErrCorrupt
|
||||
}
|
||||
i.info[idx].uncompressedOffset = uOff
|
||||
}
|
||||
|
||||
// Initial compressed size estimate.
|
||||
cPredict := i.estBlockUncomp / 2
|
||||
|
||||
// Add each compressed entry
|
||||
for idx := range i.info {
|
||||
var cOff int64
|
||||
if v, n := binary.Varint(b); n <= 0 {
|
||||
return b, ErrCorrupt
|
||||
} else {
|
||||
cOff = v
|
||||
b = b[n:]
|
||||
}
|
||||
|
||||
if idx > 0 {
|
||||
// Update compressed size prediction, with half the error.
|
||||
cPredictNew := cPredict + cOff/2
|
||||
|
||||
prev := i.info[idx-1].compressedOffset
|
||||
cOff += prev + cPredict
|
||||
if cOff <= prev {
|
||||
return b, ErrCorrupt
|
||||
}
|
||||
cPredict = cPredictNew
|
||||
}
|
||||
if cOff < 0 {
|
||||
return b, ErrCorrupt
|
||||
}
|
||||
i.info[idx].compressedOffset = cOff
|
||||
}
|
||||
if len(b) < 4+len(S2IndexTrailer) {
|
||||
return b, io.ErrUnexpectedEOF
|
||||
}
|
||||
// Skip size...
|
||||
b = b[4:]
|
||||
|
||||
// Check trailer...
|
||||
if !bytes.Equal(b[:len(S2IndexTrailer)], []byte(S2IndexTrailer)) {
|
||||
return b, ErrCorrupt
|
||||
}
|
||||
return b[len(S2IndexTrailer):], nil
|
||||
}
|
||||
|
||||
// LoadStream will load an index from the end of the supplied stream.
|
||||
// ErrUnsupported will be returned if the signature cannot be found.
|
||||
// ErrCorrupt will be returned if unexpected values are found.
|
||||
// io.ErrUnexpectedEOF is returned if there are too few bytes.
|
||||
// IO errors are returned as-is.
|
||||
func (i *Index) LoadStream(rs io.ReadSeeker) error {
|
||||
// Go to end.
|
||||
_, err := rs.Seek(-10, io.SeekEnd)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
var tmp [10]byte
|
||||
_, err = io.ReadFull(rs, tmp[:])
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
// Check trailer...
|
||||
if !bytes.Equal(tmp[4:4+len(S2IndexTrailer)], []byte(S2IndexTrailer)) {
|
||||
return ErrUnsupported
|
||||
}
|
||||
sz := binary.LittleEndian.Uint32(tmp[:4])
|
||||
if sz > maxChunkSize+skippableFrameHeader {
|
||||
return ErrCorrupt
|
||||
}
|
||||
_, err = rs.Seek(-int64(sz), io.SeekEnd)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
// Read index.
|
||||
buf := make([]byte, sz)
|
||||
_, err = io.ReadFull(rs, buf)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
_, err = i.Load(buf)
|
||||
return err
|
||||
}
|
||||
|
||||
// IndexStream will return an index for a stream.
|
||||
// The stream structure will be checked, but
|
||||
// data within blocks is not verified.
|
||||
// The returned index can either be appended to the end of the stream
|
||||
// or stored separately.
|
||||
func IndexStream(r io.Reader) ([]byte, error) {
|
||||
var i Index
|
||||
var buf [maxChunkSize]byte
|
||||
var readHeader bool
|
||||
for {
|
||||
_, err := io.ReadFull(r, buf[:4])
|
||||
if err != nil {
|
||||
if err == io.EOF {
|
||||
return i.appendTo(nil, i.TotalUncompressed, i.TotalCompressed), nil
|
||||
}
|
||||
return nil, err
|
||||
}
|
||||
// Start of this chunk.
|
||||
startChunk := i.TotalCompressed
|
||||
i.TotalCompressed += 4
|
||||
|
||||
chunkType := buf[0]
|
||||
if !readHeader {
|
||||
if chunkType != chunkTypeStreamIdentifier {
|
||||
return nil, ErrCorrupt
|
||||
}
|
||||
readHeader = true
|
||||
}
|
||||
chunkLen := int(buf[1]) | int(buf[2])<<8 | int(buf[3])<<16
|
||||
if chunkLen < checksumSize {
|
||||
return nil, ErrCorrupt
|
||||
}
|
||||
|
||||
i.TotalCompressed += int64(chunkLen)
|
||||
_, err = io.ReadFull(r, buf[:chunkLen])
|
||||
if err != nil {
|
||||
return nil, io.ErrUnexpectedEOF
|
||||
}
|
||||
// The chunk types are specified at
|
||||
// https://github.com/google/snappy/blob/master/framing_format.txt
|
||||
switch chunkType {
|
||||
case chunkTypeCompressedData:
|
||||
// Section 4.2. Compressed data (chunk type 0x00).
|
||||
// Skip checksum.
|
||||
dLen, err := DecodedLen(buf[checksumSize:])
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
if dLen > maxBlockSize {
|
||||
return nil, ErrCorrupt
|
||||
}
|
||||
if i.estBlockUncomp == 0 {
|
||||
// Use first block for estimate...
|
||||
i.estBlockUncomp = int64(dLen)
|
||||
}
|
||||
err = i.add(startChunk, i.TotalUncompressed)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
i.TotalUncompressed += int64(dLen)
|
||||
continue
|
||||
case chunkTypeUncompressedData:
|
||||
n2 := chunkLen - checksumSize
|
||||
if n2 > maxBlockSize {
|
||||
return nil, ErrCorrupt
|
||||
}
|
||||
if i.estBlockUncomp == 0 {
|
||||
// Use first block for estimate...
|
||||
i.estBlockUncomp = int64(n2)
|
||||
}
|
||||
err = i.add(startChunk, i.TotalUncompressed)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
i.TotalUncompressed += int64(n2)
|
||||
continue
|
||||
case chunkTypeStreamIdentifier:
|
||||
// Section 4.1. Stream identifier (chunk type 0xff).
|
||||
if chunkLen != len(magicBody) {
|
||||
return nil, ErrCorrupt
|
||||
}
|
||||
|
||||
if string(buf[:len(magicBody)]) != magicBody {
|
||||
if string(buf[:len(magicBody)]) != magicBodySnappy {
|
||||
return nil, ErrCorrupt
|
||||
}
|
||||
}
|
||||
|
||||
continue
|
||||
}
|
||||
|
||||
if chunkType <= 0x7f {
|
||||
// Section 4.5. Reserved unskippable chunks (chunk types 0x02-0x7f).
|
||||
return nil, ErrUnsupported
|
||||
}
|
||||
if chunkLen > maxChunkSize {
|
||||
return nil, ErrUnsupported
|
||||
}
|
||||
// Section 4.4 Padding (chunk type 0xfe).
|
||||
// Section 4.6. Reserved skippable chunks (chunk types 0x80-0xfd).
|
||||
}
|
||||
}
|
||||
|
||||
// JSON returns the index as JSON text.
|
||||
func (i *Index) JSON() []byte {
|
||||
type offset struct {
|
||||
CompressedOffset int64 `json:"compressed"`
|
||||
UncompressedOffset int64 `json:"uncompressed"`
|
||||
}
|
||||
x := struct {
|
||||
TotalUncompressed int64 `json:"total_uncompressed"` // Total Uncompressed size if known. Will be -1 if unknown.
|
||||
TotalCompressed int64 `json:"total_compressed"` // Total Compressed size if known. Will be -1 if unknown.
|
||||
Offsets []offset `json:"offsets"`
|
||||
EstBlockUncomp int64 `json:"est_block_uncompressed"`
|
||||
}{
|
||||
TotalUncompressed: i.TotalUncompressed,
|
||||
TotalCompressed: i.TotalCompressed,
|
||||
EstBlockUncomp: i.estBlockUncomp,
|
||||
}
|
||||
for _, v := range i.info {
|
||||
x.Offsets = append(x.Offsets, offset{CompressedOffset: v.compressedOffset, UncompressedOffset: v.uncompressedOffset})
|
||||
}
|
||||
b, _ := json.MarshalIndent(x, "", " ")
|
||||
return b
|
||||
}
|
||||
|
||||
// RemoveIndexHeaders will trim all headers and trailers from a given index.
|
||||
// This is expected to save 20 bytes.
|
||||
// These can be restored using RestoreIndexHeaders.
|
||||
// This removes a layer of security, but is the most compact representation.
|
||||
// Returns nil if headers contains errors.
|
||||
// The returned slice references the provided slice.
|
||||
func RemoveIndexHeaders(b []byte) []byte {
|
||||
const save = 4 + len(S2IndexHeader) + len(S2IndexTrailer) + 4
|
||||
if len(b) <= save {
|
||||
return nil
|
||||
}
|
||||
if b[0] != ChunkTypeIndex {
|
||||
return nil
|
||||
}
|
||||
chunkLen := int(b[1]) | int(b[2])<<8 | int(b[3])<<16
|
||||
b = b[4:]
|
||||
|
||||
// Validate we have enough...
|
||||
if len(b) < chunkLen {
|
||||
return nil
|
||||
}
|
||||
b = b[:chunkLen]
|
||||
|
||||
if !bytes.Equal(b[:len(S2IndexHeader)], []byte(S2IndexHeader)) {
|
||||
return nil
|
||||
}
|
||||
b = b[len(S2IndexHeader):]
|
||||
if !bytes.HasSuffix(b, []byte(S2IndexTrailer)) {
|
||||
return nil
|
||||
}
|
||||
b = bytes.TrimSuffix(b, []byte(S2IndexTrailer))
|
||||
|
||||
if len(b) < 4 {
|
||||
return nil
|
||||
}
|
||||
return b[:len(b)-4]
|
||||
}
|
||||
|
||||
// RestoreIndexHeaders will index restore headers removed by RemoveIndexHeaders.
|
||||
// No error checking is performed on the input.
|
||||
// If a 0 length slice is sent, it is returned without modification.
|
||||
func RestoreIndexHeaders(in []byte) []byte {
|
||||
if len(in) == 0 {
|
||||
return in
|
||||
}
|
||||
b := make([]byte, 0, 4+len(S2IndexHeader)+len(in)+len(S2IndexTrailer)+4)
|
||||
b = append(b, ChunkTypeIndex, 0, 0, 0)
|
||||
b = append(b, []byte(S2IndexHeader)...)
|
||||
b = append(b, in...)
|
||||
|
||||
var tmp [4]byte
|
||||
binary.LittleEndian.PutUint32(tmp[:], uint32(len(b)+4+len(S2IndexTrailer)))
|
||||
b = append(b, tmp[:4]...)
|
||||
// Trailer
|
||||
b = append(b, []byte(S2IndexTrailer)...)
|
||||
|
||||
chunkLen := len(b) - skippableFrameHeader
|
||||
b[1] = uint8(chunkLen >> 0)
|
||||
b[2] = uint8(chunkLen >> 8)
|
||||
b[3] = uint8(chunkLen >> 16)
|
||||
return b
|
||||
}
|
||||
Generated
Vendored
-585
@@ -1,585 +0,0 @@
|
||||
// Copyright (c) 2022 Klaus Post. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package s2
|
||||
|
||||
import (
|
||||
"encoding/binary"
|
||||
"errors"
|
||||
"fmt"
|
||||
)
|
||||
|
||||
// LZ4Converter provides conversion from LZ4 blocks as defined here:
|
||||
// https://github.com/lz4/lz4/blob/dev/doc/lz4_Block_format.md
|
||||
type LZ4Converter struct {
|
||||
}
|
||||
|
||||
// ErrDstTooSmall is returned when provided destination is too small.
|
||||
var ErrDstTooSmall = errors.New("s2: destination too small")
|
||||
|
||||
// ConvertBlock will convert an LZ4 block and append it as an S2
|
||||
// block without block length to dst.
|
||||
// The uncompressed size is returned as well.
|
||||
// dst must have capacity to contain the entire compressed block.
|
||||
func (l *LZ4Converter) ConvertBlock(dst, src []byte) ([]byte, int, error) {
|
||||
if len(src) == 0 {
|
||||
return dst, 0, nil
|
||||
}
|
||||
const debug = false
|
||||
const inline = true
|
||||
const lz4MinMatch = 4
|
||||
|
||||
s, d := 0, len(dst)
|
||||
dst = dst[:cap(dst)]
|
||||
if !debug && hasAsm {
|
||||
res, sz := cvtLZ4BlockAsm(dst[d:], src)
|
||||
if res < 0 {
|
||||
const (
|
||||
errCorrupt = -1
|
||||
errDstTooSmall = -2
|
||||
)
|
||||
switch res {
|
||||
case errCorrupt:
|
||||
return nil, 0, ErrCorrupt
|
||||
case errDstTooSmall:
|
||||
return nil, 0, ErrDstTooSmall
|
||||
default:
|
||||
return nil, 0, fmt.Errorf("unexpected result: %d", res)
|
||||
}
|
||||
}
|
||||
if d+sz > len(dst) {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
return dst[:d+sz], res, nil
|
||||
}
|
||||
|
||||
dLimit := len(dst) - 10
|
||||
var lastOffset uint16
|
||||
var uncompressed int
|
||||
if debug {
|
||||
fmt.Printf("convert block start: len(src): %d, len(dst):%d \n", len(src), len(dst))
|
||||
}
|
||||
|
||||
for {
|
||||
if s >= len(src) {
|
||||
return dst[:d], 0, ErrCorrupt
|
||||
}
|
||||
// Read literal info
|
||||
token := src[s]
|
||||
ll := int(token >> 4)
|
||||
ml := int(lz4MinMatch + (token & 0xf))
|
||||
|
||||
// If upper nibble is 15, literal length is extended
|
||||
if token >= 0xf0 {
|
||||
for {
|
||||
s++
|
||||
if s >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error reading ll: s (%d) >= len(src) (%d)\n", s, len(src))
|
||||
}
|
||||
return dst[:d], 0, ErrCorrupt
|
||||
}
|
||||
val := src[s]
|
||||
ll += int(val)
|
||||
if val != 255 {
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
// Skip past token
|
||||
if s+ll >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error literals: s+ll (%d+%d) >= len(src) (%d)\n", s, ll, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
s++
|
||||
if ll > 0 {
|
||||
if d+ll > dLimit {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
if debug {
|
||||
fmt.Printf("emit %d literals\n", ll)
|
||||
}
|
||||
d += emitLiteralGo(dst[d:], src[s:s+ll])
|
||||
s += ll
|
||||
uncompressed += ll
|
||||
}
|
||||
|
||||
// Check if we are done...
|
||||
if s == len(src) && ml == lz4MinMatch {
|
||||
break
|
||||
}
|
||||
// 2 byte offset
|
||||
if s >= len(src)-2 {
|
||||
if debug {
|
||||
fmt.Printf("s (%d) >= len(src)-2 (%d)", s, len(src)-2)
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
offset := binary.LittleEndian.Uint16(src[s:])
|
||||
s += 2
|
||||
if offset == 0 {
|
||||
if debug {
|
||||
fmt.Printf("error: offset 0, ml: %d, len(src)-s: %d\n", ml, len(src)-s)
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
if int(offset) > uncompressed {
|
||||
if debug {
|
||||
fmt.Printf("error: offset (%d)> uncompressed (%d)\n", offset, uncompressed)
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
|
||||
if ml == lz4MinMatch+15 {
|
||||
for {
|
||||
if s >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error reading ml: s (%d) >= len(src) (%d)\n", s, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
val := src[s]
|
||||
s++
|
||||
ml += int(val)
|
||||
if val != 255 {
|
||||
if s >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error reading ml: s (%d) >= len(src) (%d)\n", s, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
if offset == lastOffset {
|
||||
if debug {
|
||||
fmt.Printf("emit repeat, length: %d, offset: %d\n", ml, offset)
|
||||
}
|
||||
if !inline {
|
||||
d += emitRepeat16(dst[d:], offset, ml)
|
||||
} else {
|
||||
length := ml
|
||||
dst := dst[d:]
|
||||
for len(dst) > 5 {
|
||||
// Repeat offset, make length cheaper
|
||||
length -= 4
|
||||
if length <= 4 {
|
||||
dst[0] = uint8(length)<<2 | tagCopy1
|
||||
dst[1] = 0
|
||||
d += 2
|
||||
break
|
||||
}
|
||||
if length < 8 && offset < 2048 {
|
||||
// Encode WITH offset
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(offset>>8)<<5 | uint8(length)<<2 | tagCopy1
|
||||
d += 2
|
||||
break
|
||||
}
|
||||
if length < (1<<8)+4 {
|
||||
length -= 4
|
||||
dst[2] = uint8(length)
|
||||
dst[1] = 0
|
||||
dst[0] = 5<<2 | tagCopy1
|
||||
d += 3
|
||||
break
|
||||
}
|
||||
if length < (1<<16)+(1<<8) {
|
||||
length -= 1 << 8
|
||||
dst[3] = uint8(length >> 8)
|
||||
dst[2] = uint8(length >> 0)
|
||||
dst[1] = 0
|
||||
dst[0] = 6<<2 | tagCopy1
|
||||
d += 4
|
||||
break
|
||||
}
|
||||
const maxRepeat = (1 << 24) - 1
|
||||
length -= 1 << 16
|
||||
left := 0
|
||||
if length > maxRepeat {
|
||||
left = length - maxRepeat + 4
|
||||
length = maxRepeat - 4
|
||||
}
|
||||
dst[4] = uint8(length >> 16)
|
||||
dst[3] = uint8(length >> 8)
|
||||
dst[2] = uint8(length >> 0)
|
||||
dst[1] = 0
|
||||
dst[0] = 7<<2 | tagCopy1
|
||||
if left > 0 {
|
||||
d += 5 + emitRepeat16(dst[5:], offset, left)
|
||||
break
|
||||
}
|
||||
d += 5
|
||||
break
|
||||
}
|
||||
}
|
||||
} else {
|
||||
if debug {
|
||||
fmt.Printf("emit copy, length: %d, offset: %d\n", ml, offset)
|
||||
}
|
||||
if !inline {
|
||||
d += emitCopy16(dst[d:], offset, ml)
|
||||
} else {
|
||||
length := ml
|
||||
dst := dst[d:]
|
||||
for len(dst) > 5 {
|
||||
// Offset no more than 2 bytes.
|
||||
if length > 64 {
|
||||
off := 3
|
||||
if offset < 2048 {
|
||||
// emit 8 bytes as tagCopy1, rest as repeats.
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(offset>>8)<<5 | uint8(8-4)<<2 | tagCopy1
|
||||
length -= 8
|
||||
off = 2
|
||||
} else {
|
||||
// Emit a length 60 copy, encoded as 3 bytes.
|
||||
// Emit remaining as repeat value (minimum 4 bytes).
|
||||
dst[2] = uint8(offset >> 8)
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = 59<<2 | tagCopy2
|
||||
length -= 60
|
||||
}
|
||||
// Emit remaining as repeats, at least 4 bytes remain.
|
||||
d += off + emitRepeat16(dst[off:], offset, length)
|
||||
break
|
||||
}
|
||||
if length >= 12 || offset >= 2048 {
|
||||
// Emit the remaining copy, encoded as 3 bytes.
|
||||
dst[2] = uint8(offset >> 8)
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(length-1)<<2 | tagCopy2
|
||||
d += 3
|
||||
break
|
||||
}
|
||||
// Emit the remaining copy, encoded as 2 bytes.
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(offset>>8)<<5 | uint8(length-4)<<2 | tagCopy1
|
||||
d += 2
|
||||
break
|
||||
}
|
||||
}
|
||||
lastOffset = offset
|
||||
}
|
||||
uncompressed += ml
|
||||
if d > dLimit {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
}
|
||||
|
||||
return dst[:d], uncompressed, nil
|
||||
}
|
||||
|
||||
// ConvertBlockSnappy will convert an LZ4 block and append it
|
||||
// as a Snappy block without block length to dst.
|
||||
// The uncompressed size is returned as well.
|
||||
// dst must have capacity to contain the entire compressed block.
|
||||
func (l *LZ4Converter) ConvertBlockSnappy(dst, src []byte) ([]byte, int, error) {
|
||||
if len(src) == 0 {
|
||||
return dst, 0, nil
|
||||
}
|
||||
const debug = false
|
||||
const lz4MinMatch = 4
|
||||
|
||||
s, d := 0, len(dst)
|
||||
dst = dst[:cap(dst)]
|
||||
// Use assembly when possible
|
||||
if !debug && hasAsm {
|
||||
res, sz := cvtLZ4BlockSnappyAsm(dst[d:], src)
|
||||
if res < 0 {
|
||||
const (
|
||||
errCorrupt = -1
|
||||
errDstTooSmall = -2
|
||||
)
|
||||
switch res {
|
||||
case errCorrupt:
|
||||
return nil, 0, ErrCorrupt
|
||||
case errDstTooSmall:
|
||||
return nil, 0, ErrDstTooSmall
|
||||
default:
|
||||
return nil, 0, fmt.Errorf("unexpected result: %d", res)
|
||||
}
|
||||
}
|
||||
if d+sz > len(dst) {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
return dst[:d+sz], res, nil
|
||||
}
|
||||
|
||||
dLimit := len(dst) - 10
|
||||
var uncompressed int
|
||||
if debug {
|
||||
fmt.Printf("convert block start: len(src): %d, len(dst):%d \n", len(src), len(dst))
|
||||
}
|
||||
|
||||
for {
|
||||
if s >= len(src) {
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
// Read literal info
|
||||
token := src[s]
|
||||
ll := int(token >> 4)
|
||||
ml := int(lz4MinMatch + (token & 0xf))
|
||||
|
||||
// If upper nibble is 15, literal length is extended
|
||||
if token >= 0xf0 {
|
||||
for {
|
||||
s++
|
||||
if s >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error reading ll: s (%d) >= len(src) (%d)\n", s, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
val := src[s]
|
||||
ll += int(val)
|
||||
if val != 255 {
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
// Skip past token
|
||||
if s+ll >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error literals: s+ll (%d+%d) >= len(src) (%d)\n", s, ll, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
s++
|
||||
if ll > 0 {
|
||||
if d+ll > dLimit {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
if debug {
|
||||
fmt.Printf("emit %d literals\n", ll)
|
||||
}
|
||||
d += emitLiteralGo(dst[d:], src[s:s+ll])
|
||||
s += ll
|
||||
uncompressed += ll
|
||||
}
|
||||
|
||||
// Check if we are done...
|
||||
if s == len(src) && ml == lz4MinMatch {
|
||||
break
|
||||
}
|
||||
// 2 byte offset
|
||||
if s >= len(src)-2 {
|
||||
if debug {
|
||||
fmt.Printf("s (%d) >= len(src)-2 (%d)", s, len(src)-2)
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
offset := binary.LittleEndian.Uint16(src[s:])
|
||||
s += 2
|
||||
if offset == 0 {
|
||||
if debug {
|
||||
fmt.Printf("error: offset 0, ml: %d, len(src)-s: %d\n", ml, len(src)-s)
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
if int(offset) > uncompressed {
|
||||
if debug {
|
||||
fmt.Printf("error: offset (%d)> uncompressed (%d)\n", offset, uncompressed)
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
|
||||
if ml == lz4MinMatch+15 {
|
||||
for {
|
||||
if s >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error reading ml: s (%d) >= len(src) (%d)\n", s, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
val := src[s]
|
||||
s++
|
||||
ml += int(val)
|
||||
if val != 255 {
|
||||
if s >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error reading ml: s (%d) >= len(src) (%d)\n", s, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
if debug {
|
||||
fmt.Printf("emit copy, length: %d, offset: %d\n", ml, offset)
|
||||
}
|
||||
length := ml
|
||||
// d += emitCopyNoRepeat(dst[d:], int(offset), ml)
|
||||
for length > 0 {
|
||||
if d >= dLimit {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
|
||||
// Offset no more than 2 bytes.
|
||||
if length > 64 {
|
||||
// Emit a length 64 copy, encoded as 3 bytes.
|
||||
dst[d+2] = uint8(offset >> 8)
|
||||
dst[d+1] = uint8(offset)
|
||||
dst[d+0] = 63<<2 | tagCopy2
|
||||
length -= 64
|
||||
d += 3
|
||||
continue
|
||||
}
|
||||
if length >= 12 || offset >= 2048 || length < 4 {
|
||||
// Emit the remaining copy, encoded as 3 bytes.
|
||||
dst[d+2] = uint8(offset >> 8)
|
||||
dst[d+1] = uint8(offset)
|
||||
dst[d+0] = uint8(length-1)<<2 | tagCopy2
|
||||
d += 3
|
||||
break
|
||||
}
|
||||
// Emit the remaining copy, encoded as 2 bytes.
|
||||
dst[d+1] = uint8(offset)
|
||||
dst[d+0] = uint8(offset>>8)<<5 | uint8(length-4)<<2 | tagCopy1
|
||||
d += 2
|
||||
break
|
||||
}
|
||||
uncompressed += ml
|
||||
if d > dLimit {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
}
|
||||
|
||||
return dst[:d], uncompressed, nil
|
||||
}
|
||||
|
||||
// emitRepeat writes a repeat chunk and returns the number of bytes written.
|
||||
// Length must be at least 4 and < 1<<24
|
||||
func emitRepeat16(dst []byte, offset uint16, length int) int {
|
||||
// Repeat offset, make length cheaper
|
||||
length -= 4
|
||||
if length <= 4 {
|
||||
dst[0] = uint8(length)<<2 | tagCopy1
|
||||
dst[1] = 0
|
||||
return 2
|
||||
}
|
||||
if length < 8 && offset < 2048 {
|
||||
// Encode WITH offset
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(offset>>8)<<5 | uint8(length)<<2 | tagCopy1
|
||||
return 2
|
||||
}
|
||||
if length < (1<<8)+4 {
|
||||
length -= 4
|
||||
dst[2] = uint8(length)
|
||||
dst[1] = 0
|
||||
dst[0] = 5<<2 | tagCopy1
|
||||
return 3
|
||||
}
|
||||
if length < (1<<16)+(1<<8) {
|
||||
length -= 1 << 8
|
||||
dst[3] = uint8(length >> 8)
|
||||
dst[2] = uint8(length >> 0)
|
||||
dst[1] = 0
|
||||
dst[0] = 6<<2 | tagCopy1
|
||||
return 4
|
||||
}
|
||||
const maxRepeat = (1 << 24) - 1
|
||||
length -= 1 << 16
|
||||
left := 0
|
||||
if length > maxRepeat {
|
||||
left = length - maxRepeat + 4
|
||||
length = maxRepeat - 4
|
||||
}
|
||||
dst[4] = uint8(length >> 16)
|
||||
dst[3] = uint8(length >> 8)
|
||||
dst[2] = uint8(length >> 0)
|
||||
dst[1] = 0
|
||||
dst[0] = 7<<2 | tagCopy1
|
||||
if left > 0 {
|
||||
return 5 + emitRepeat16(dst[5:], offset, left)
|
||||
}
|
||||
return 5
|
||||
}
|
||||
|
||||
// emitCopy writes a copy chunk and returns the number of bytes written.
|
||||
//
|
||||
// It assumes that:
|
||||
//
|
||||
// dst is long enough to hold the encoded bytes
|
||||
// 1 <= offset && offset <= math.MaxUint16
|
||||
// 4 <= length && length <= math.MaxUint32
|
||||
func emitCopy16(dst []byte, offset uint16, length int) int {
|
||||
// Offset no more than 2 bytes.
|
||||
if length > 64 {
|
||||
off := 3
|
||||
if offset < 2048 {
|
||||
// emit 8 bytes as tagCopy1, rest as repeats.
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(offset>>8)<<5 | uint8(8-4)<<2 | tagCopy1
|
||||
length -= 8
|
||||
off = 2
|
||||
} else {
|
||||
// Emit a length 60 copy, encoded as 3 bytes.
|
||||
// Emit remaining as repeat value (minimum 4 bytes).
|
||||
dst[2] = uint8(offset >> 8)
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = 59<<2 | tagCopy2
|
||||
length -= 60
|
||||
}
|
||||
// Emit remaining as repeats, at least 4 bytes remain.
|
||||
return off + emitRepeat16(dst[off:], offset, length)
|
||||
}
|
||||
if length >= 12 || offset >= 2048 {
|
||||
// Emit the remaining copy, encoded as 3 bytes.
|
||||
dst[2] = uint8(offset >> 8)
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(length-1)<<2 | tagCopy2
|
||||
return 3
|
||||
}
|
||||
// Emit the remaining copy, encoded as 2 bytes.
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(offset>>8)<<5 | uint8(length-4)<<2 | tagCopy1
|
||||
return 2
|
||||
}
|
||||
|
||||
// emitLiteral writes a literal chunk and returns the number of bytes written.
|
||||
//
|
||||
// It assumes that:
|
||||
//
|
||||
// dst is long enough to hold the encoded bytes
|
||||
// 0 <= len(lit) && len(lit) <= math.MaxUint32
|
||||
func emitLiteralGo(dst, lit []byte) int {
|
||||
if len(lit) == 0 {
|
||||
return 0
|
||||
}
|
||||
i, n := 0, uint(len(lit)-1)
|
||||
switch {
|
||||
case n < 60:
|
||||
dst[0] = uint8(n)<<2 | tagLiteral
|
||||
i = 1
|
||||
case n < 1<<8:
|
||||
dst[1] = uint8(n)
|
||||
dst[0] = 60<<2 | tagLiteral
|
||||
i = 2
|
||||
case n < 1<<16:
|
||||
dst[2] = uint8(n >> 8)
|
||||
dst[1] = uint8(n)
|
||||
dst[0] = 61<<2 | tagLiteral
|
||||
i = 3
|
||||
case n < 1<<24:
|
||||
dst[3] = uint8(n >> 16)
|
||||
dst[2] = uint8(n >> 8)
|
||||
dst[1] = uint8(n)
|
||||
dst[0] = 62<<2 | tagLiteral
|
||||
i = 4
|
||||
default:
|
||||
dst[4] = uint8(n >> 24)
|
||||
dst[3] = uint8(n >> 16)
|
||||
dst[2] = uint8(n >> 8)
|
||||
dst[1] = uint8(n)
|
||||
dst[0] = 63<<2 | tagLiteral
|
||||
i = 5
|
||||
}
|
||||
return i + copy(dst[i:], lit)
|
||||
}
|
||||
Generated
Vendored
-467
@@ -1,467 +0,0 @@
|
||||
// Copyright (c) 2022 Klaus Post. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
package s2
|
||||
|
||||
import (
|
||||
"encoding/binary"
|
||||
"fmt"
|
||||
)
|
||||
|
||||
// LZ4sConverter provides conversion from LZ4s.
|
||||
// (Intel modified LZ4 Blocks)
|
||||
// https://cdrdv2-public.intel.com/743912/743912-qat-programmers-guide-v2.0.pdf
|
||||
// LZ4s is a variant of LZ4 block format. LZ4s should be considered as an intermediate compressed block format.
|
||||
// The LZ4s format is selected when the application sets the compType to CPA_DC_LZ4S in CpaDcSessionSetupData.
|
||||
// The LZ4s block returned by the Intel® QAT hardware can be used by an external
|
||||
// software post-processing to generate other compressed data formats.
|
||||
// The following table lists the differences between LZ4 and LZ4s block format. LZ4s block format uses
|
||||
// the same high-level formatting as LZ4 block format with the following encoding changes:
|
||||
// For Min Match of 4 bytes, Copy length value 1-15 means length 4-18 with 18 bytes adding an extra byte.
|
||||
// ONLY "Min match of 4 bytes" is supported.
|
||||
type LZ4sConverter struct {
|
||||
}
|
||||
|
||||
// ConvertBlock will convert an LZ4s block and append it as an S2
|
||||
// block without block length to dst.
|
||||
// The uncompressed size is returned as well.
|
||||
// dst must have capacity to contain the entire compressed block.
|
||||
func (l *LZ4sConverter) ConvertBlock(dst, src []byte) ([]byte, int, error) {
|
||||
if len(src) == 0 {
|
||||
return dst, 0, nil
|
||||
}
|
||||
const debug = false
|
||||
const inline = true
|
||||
const lz4MinMatch = 3
|
||||
|
||||
s, d := 0, len(dst)
|
||||
dst = dst[:cap(dst)]
|
||||
if !debug && hasAsm {
|
||||
res, sz := cvtLZ4sBlockAsm(dst[d:], src)
|
||||
if res < 0 {
|
||||
const (
|
||||
errCorrupt = -1
|
||||
errDstTooSmall = -2
|
||||
)
|
||||
switch res {
|
||||
case errCorrupt:
|
||||
return nil, 0, ErrCorrupt
|
||||
case errDstTooSmall:
|
||||
return nil, 0, ErrDstTooSmall
|
||||
default:
|
||||
return nil, 0, fmt.Errorf("unexpected result: %d", res)
|
||||
}
|
||||
}
|
||||
if d+sz > len(dst) {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
return dst[:d+sz], res, nil
|
||||
}
|
||||
|
||||
dLimit := len(dst) - 10
|
||||
var lastOffset uint16
|
||||
var uncompressed int
|
||||
if debug {
|
||||
fmt.Printf("convert block start: len(src): %d, len(dst):%d \n", len(src), len(dst))
|
||||
}
|
||||
|
||||
for {
|
||||
if s >= len(src) {
|
||||
return dst[:d], 0, ErrCorrupt
|
||||
}
|
||||
// Read literal info
|
||||
token := src[s]
|
||||
ll := int(token >> 4)
|
||||
ml := int(lz4MinMatch + (token & 0xf))
|
||||
|
||||
// If upper nibble is 15, literal length is extended
|
||||
if token >= 0xf0 {
|
||||
for {
|
||||
s++
|
||||
if s >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error reading ll: s (%d) >= len(src) (%d)\n", s, len(src))
|
||||
}
|
||||
return dst[:d], 0, ErrCorrupt
|
||||
}
|
||||
val := src[s]
|
||||
ll += int(val)
|
||||
if val != 255 {
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
// Skip past token
|
||||
if s+ll >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error literals: s+ll (%d+%d) >= len(src) (%d)\n", s, ll, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
s++
|
||||
if ll > 0 {
|
||||
if d+ll > dLimit {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
if debug {
|
||||
fmt.Printf("emit %d literals\n", ll)
|
||||
}
|
||||
d += emitLiteralGo(dst[d:], src[s:s+ll])
|
||||
s += ll
|
||||
uncompressed += ll
|
||||
}
|
||||
|
||||
// Check if we are done...
|
||||
if ml == lz4MinMatch {
|
||||
if s == len(src) {
|
||||
break
|
||||
}
|
||||
// 0 bytes.
|
||||
continue
|
||||
}
|
||||
// 2 byte offset
|
||||
if s >= len(src)-2 {
|
||||
if debug {
|
||||
fmt.Printf("s (%d) >= len(src)-2 (%d)", s, len(src)-2)
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
offset := binary.LittleEndian.Uint16(src[s:])
|
||||
s += 2
|
||||
if offset == 0 {
|
||||
if debug {
|
||||
fmt.Printf("error: offset 0, ml: %d, len(src)-s: %d\n", ml, len(src)-s)
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
if int(offset) > uncompressed {
|
||||
if debug {
|
||||
fmt.Printf("error: offset (%d)> uncompressed (%d)\n", offset, uncompressed)
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
|
||||
if ml == lz4MinMatch+15 {
|
||||
for {
|
||||
if s >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error reading ml: s (%d) >= len(src) (%d)\n", s, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
val := src[s]
|
||||
s++
|
||||
ml += int(val)
|
||||
if val != 255 {
|
||||
if s >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error reading ml: s (%d) >= len(src) (%d)\n", s, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
if offset == lastOffset {
|
||||
if debug {
|
||||
fmt.Printf("emit repeat, length: %d, offset: %d\n", ml, offset)
|
||||
}
|
||||
if !inline {
|
||||
d += emitRepeat16(dst[d:], offset, ml)
|
||||
} else {
|
||||
length := ml
|
||||
dst := dst[d:]
|
||||
for len(dst) > 5 {
|
||||
// Repeat offset, make length cheaper
|
||||
length -= 4
|
||||
if length <= 4 {
|
||||
dst[0] = uint8(length)<<2 | tagCopy1
|
||||
dst[1] = 0
|
||||
d += 2
|
||||
break
|
||||
}
|
||||
if length < 8 && offset < 2048 {
|
||||
// Encode WITH offset
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(offset>>8)<<5 | uint8(length)<<2 | tagCopy1
|
||||
d += 2
|
||||
break
|
||||
}
|
||||
if length < (1<<8)+4 {
|
||||
length -= 4
|
||||
dst[2] = uint8(length)
|
||||
dst[1] = 0
|
||||
dst[0] = 5<<2 | tagCopy1
|
||||
d += 3
|
||||
break
|
||||
}
|
||||
if length < (1<<16)+(1<<8) {
|
||||
length -= 1 << 8
|
||||
dst[3] = uint8(length >> 8)
|
||||
dst[2] = uint8(length >> 0)
|
||||
dst[1] = 0
|
||||
dst[0] = 6<<2 | tagCopy1
|
||||
d += 4
|
||||
break
|
||||
}
|
||||
const maxRepeat = (1 << 24) - 1
|
||||
length -= 1 << 16
|
||||
left := 0
|
||||
if length > maxRepeat {
|
||||
left = length - maxRepeat + 4
|
||||
length = maxRepeat - 4
|
||||
}
|
||||
dst[4] = uint8(length >> 16)
|
||||
dst[3] = uint8(length >> 8)
|
||||
dst[2] = uint8(length >> 0)
|
||||
dst[1] = 0
|
||||
dst[0] = 7<<2 | tagCopy1
|
||||
if left > 0 {
|
||||
d += 5 + emitRepeat16(dst[5:], offset, left)
|
||||
break
|
||||
}
|
||||
d += 5
|
||||
break
|
||||
}
|
||||
}
|
||||
} else {
|
||||
if debug {
|
||||
fmt.Printf("emit copy, length: %d, offset: %d\n", ml, offset)
|
||||
}
|
||||
if !inline {
|
||||
d += emitCopy16(dst[d:], offset, ml)
|
||||
} else {
|
||||
length := ml
|
||||
dst := dst[d:]
|
||||
for len(dst) > 5 {
|
||||
// Offset no more than 2 bytes.
|
||||
if length > 64 {
|
||||
off := 3
|
||||
if offset < 2048 {
|
||||
// emit 8 bytes as tagCopy1, rest as repeats.
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(offset>>8)<<5 | uint8(8-4)<<2 | tagCopy1
|
||||
length -= 8
|
||||
off = 2
|
||||
} else {
|
||||
// Emit a length 60 copy, encoded as 3 bytes.
|
||||
// Emit remaining as repeat value (minimum 4 bytes).
|
||||
dst[2] = uint8(offset >> 8)
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = 59<<2 | tagCopy2
|
||||
length -= 60
|
||||
}
|
||||
// Emit remaining as repeats, at least 4 bytes remain.
|
||||
d += off + emitRepeat16(dst[off:], offset, length)
|
||||
break
|
||||
}
|
||||
if length >= 12 || offset >= 2048 {
|
||||
// Emit the remaining copy, encoded as 3 bytes.
|
||||
dst[2] = uint8(offset >> 8)
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(length-1)<<2 | tagCopy2
|
||||
d += 3
|
||||
break
|
||||
}
|
||||
// Emit the remaining copy, encoded as 2 bytes.
|
||||
dst[1] = uint8(offset)
|
||||
dst[0] = uint8(offset>>8)<<5 | uint8(length-4)<<2 | tagCopy1
|
||||
d += 2
|
||||
break
|
||||
}
|
||||
}
|
||||
lastOffset = offset
|
||||
}
|
||||
uncompressed += ml
|
||||
if d > dLimit {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
}
|
||||
|
||||
return dst[:d], uncompressed, nil
|
||||
}
|
||||
|
||||
// ConvertBlockSnappy will convert an LZ4s block and append it
|
||||
// as a Snappy block without block length to dst.
|
||||
// The uncompressed size is returned as well.
|
||||
// dst must have capacity to contain the entire compressed block.
|
||||
func (l *LZ4sConverter) ConvertBlockSnappy(dst, src []byte) ([]byte, int, error) {
|
||||
if len(src) == 0 {
|
||||
return dst, 0, nil
|
||||
}
|
||||
const debug = false
|
||||
const lz4MinMatch = 3
|
||||
|
||||
s, d := 0, len(dst)
|
||||
dst = dst[:cap(dst)]
|
||||
// Use assembly when possible
|
||||
if !debug && hasAsm {
|
||||
res, sz := cvtLZ4sBlockSnappyAsm(dst[d:], src)
|
||||
if res < 0 {
|
||||
const (
|
||||
errCorrupt = -1
|
||||
errDstTooSmall = -2
|
||||
)
|
||||
switch res {
|
||||
case errCorrupt:
|
||||
return nil, 0, ErrCorrupt
|
||||
case errDstTooSmall:
|
||||
return nil, 0, ErrDstTooSmall
|
||||
default:
|
||||
return nil, 0, fmt.Errorf("unexpected result: %d", res)
|
||||
}
|
||||
}
|
||||
if d+sz > len(dst) {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
return dst[:d+sz], res, nil
|
||||
}
|
||||
|
||||
dLimit := len(dst) - 10
|
||||
var uncompressed int
|
||||
if debug {
|
||||
fmt.Printf("convert block start: len(src): %d, len(dst):%d \n", len(src), len(dst))
|
||||
}
|
||||
|
||||
for {
|
||||
if s >= len(src) {
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
// Read literal info
|
||||
token := src[s]
|
||||
ll := int(token >> 4)
|
||||
ml := int(lz4MinMatch + (token & 0xf))
|
||||
|
||||
// If upper nibble is 15, literal length is extended
|
||||
if token >= 0xf0 {
|
||||
for {
|
||||
s++
|
||||
if s >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error reading ll: s (%d) >= len(src) (%d)\n", s, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
val := src[s]
|
||||
ll += int(val)
|
||||
if val != 255 {
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
// Skip past token
|
||||
if s+ll >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error literals: s+ll (%d+%d) >= len(src) (%d)\n", s, ll, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
s++
|
||||
if ll > 0 {
|
||||
if d+ll > dLimit {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
if debug {
|
||||
fmt.Printf("emit %d literals\n", ll)
|
||||
}
|
||||
d += emitLiteralGo(dst[d:], src[s:s+ll])
|
||||
s += ll
|
||||
uncompressed += ll
|
||||
}
|
||||
|
||||
// Check if we are done...
|
||||
if ml == lz4MinMatch {
|
||||
if s == len(src) {
|
||||
break
|
||||
}
|
||||
// 0 bytes.
|
||||
continue
|
||||
}
|
||||
// 2 byte offset
|
||||
if s >= len(src)-2 {
|
||||
if debug {
|
||||
fmt.Printf("s (%d) >= len(src)-2 (%d)", s, len(src)-2)
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
offset := binary.LittleEndian.Uint16(src[s:])
|
||||
s += 2
|
||||
if offset == 0 {
|
||||
if debug {
|
||||
fmt.Printf("error: offset 0, ml: %d, len(src)-s: %d\n", ml, len(src)-s)
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
if int(offset) > uncompressed {
|
||||
if debug {
|
||||
fmt.Printf("error: offset (%d)> uncompressed (%d)\n", offset, uncompressed)
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
|
||||
if ml == lz4MinMatch+15 {
|
||||
for {
|
||||
if s >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error reading ml: s (%d) >= len(src) (%d)\n", s, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
val := src[s]
|
||||
s++
|
||||
ml += int(val)
|
||||
if val != 255 {
|
||||
if s >= len(src) {
|
||||
if debug {
|
||||
fmt.Printf("error reading ml: s (%d) >= len(src) (%d)\n", s, len(src))
|
||||
}
|
||||
return nil, 0, ErrCorrupt
|
||||
}
|
||||
break
|
||||
}
|
||||
}
|
||||
}
|
||||
if debug {
|
||||
fmt.Printf("emit copy, length: %d, offset: %d\n", ml, offset)
|
||||
}
|
||||
length := ml
|
||||
// d += emitCopyNoRepeat(dst[d:], int(offset), ml)
|
||||
for length > 0 {
|
||||
if d >= dLimit {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
|
||||
// Offset no more than 2 bytes.
|
||||
if length > 64 {
|
||||
// Emit a length 64 copy, encoded as 3 bytes.
|
||||
dst[d+2] = uint8(offset >> 8)
|
||||
dst[d+1] = uint8(offset)
|
||||
dst[d+0] = 63<<2 | tagCopy2
|
||||
length -= 64
|
||||
d += 3
|
||||
continue
|
||||
}
|
||||
if length >= 12 || offset >= 2048 || length < 4 {
|
||||
// Emit the remaining copy, encoded as 3 bytes.
|
||||
dst[d+2] = uint8(offset >> 8)
|
||||
dst[d+1] = uint8(offset)
|
||||
dst[d+0] = uint8(length-1)<<2 | tagCopy2
|
||||
d += 3
|
||||
break
|
||||
}
|
||||
// Emit the remaining copy, encoded as 2 bytes.
|
||||
dst[d+1] = uint8(offset)
|
||||
dst[d+0] = uint8(offset>>8)<<5 | uint8(length-4)<<2 | tagCopy1
|
||||
d += 2
|
||||
break
|
||||
}
|
||||
uncompressed += ml
|
||||
if d > dLimit {
|
||||
return nil, 0, ErrDstTooSmall
|
||||
}
|
||||
}
|
||||
|
||||
return dst[:d], uncompressed, nil
|
||||
}
|
||||
Generated
Vendored
-1078
File diff suppressed because it is too large
Load Diff
-151
@@ -1,151 +0,0 @@
|
||||
// Copyright 2011 The Snappy-Go Authors. All rights reserved.
|
||||
// Copyright (c) 2019 Klaus Post. All rights reserved.
|
||||
// Use of this source code is governed by a BSD-style
|
||||
// license that can be found in the LICENSE file.
|
||||
|
||||
// Package s2 implements the S2 compression format.
|
||||
//
|
||||
// S2 is an extension of Snappy. Similar to Snappy S2 is aimed for high throughput,
|
||||
// which is why it features concurrent compression for bigger payloads.
|
||||
//
|
||||
// Decoding is compatible with Snappy compressed content,
|
||||
// but content compressed with S2 cannot be decompressed by Snappy.
|
||||
//
|
||||
// For more information on Snappy/S2 differences see README in: https://github.com/klauspost/compress/tree/master/s2
|
||||
//
|
||||
// There are actually two S2 formats: block and stream. They are related,
|
||||
// but different: trying to decompress block-compressed data as a S2 stream
|
||||
// will fail, and vice versa. The block format is the Decode and Encode
|
||||
// functions and the stream format is the Reader and Writer types.
|
||||
//
|
||||
// A "better" compression option is available. This will trade some compression
|
||||
// speed
|
||||
//
|
||||
// The block format, the more common case, is used when the complete size (the
|
||||
// number of bytes) of the original data is known upfront, at the time
|
||||
// compression starts. The stream format, also known as the framing format, is
|
||||
// for when that isn't always true.
|
||||
//
|
||||
// Blocks to not offer much data protection, so it is up to you to
|
||||
// add data validation of decompressed blocks.
|
||||
//
|
||||
// Streams perform CRC validation of the decompressed data.
|
||||
// Stream compression will also be performed on multiple CPU cores concurrently
|
||||
// significantly improving throughput.
|
||||
package s2
|
||||
|
||||
import (
|
||||
"bytes"
|
||||
"hash/crc32"
|
||||
|
||||
"github.com/klauspost/compress/internal/race"
|
||||
)
|
||||
|
||||
/*
|
||||
Each encoded block begins with the varint-encoded length of the decoded data,
|
||||
followed by a sequence of chunks. Chunks begin and end on byte boundaries. The
|
||||
first byte of each chunk is broken into its 2 least and 6 most significant bits
|
||||
called l and m: l ranges in [0, 4) and m ranges in [0, 64). l is the chunk tag.
|
||||
Zero means a literal tag. All other values mean a copy tag.
|
||||
|
||||
For literal tags:
|
||||
- If m < 60, the next 1 + m bytes are literal bytes.
|
||||
- Otherwise, let n be the little-endian unsigned integer denoted by the next
|
||||
m - 59 bytes. The next 1 + n bytes after that are literal bytes.
|
||||
|
||||
For copy tags, length bytes are copied from offset bytes ago, in the style of
|
||||
Lempel-Ziv compression algorithms. In particular:
|
||||
- For l == 1, the offset ranges in [0, 1<<11) and the length in [4, 12).
|
||||
The length is 4 + the low 3 bits of m. The high 3 bits of m form bits 8-10
|
||||
of the offset. The next byte is bits 0-7 of the offset.
|
||||
- For l == 2, the offset ranges in [0, 1<<16) and the length in [1, 65).
|
||||
The length is 1 + m. The offset is the little-endian unsigned integer
|
||||
denoted by the next 2 bytes.
|
||||
- For l == 3, the offset ranges in [0, 1<<32) and the length in
|
||||
[1, 65). The length is 1 + m. The offset is the little-endian unsigned
|
||||
integer denoted by the next 4 bytes.
|
||||
*/
|
||||
const (
|
||||
tagLiteral = 0x00
|
||||
tagCopy1 = 0x01
|
||||
tagCopy2 = 0x02
|
||||
tagCopy4 = 0x03
|
||||
)
|
||||
|
||||
const (
|
||||
checksumSize = 4
|
||||
chunkHeaderSize = 4
|
||||
magicChunk = "\xff\x06\x00\x00" + magicBody
|
||||
magicChunkSnappy = "\xff\x06\x00\x00" + magicBodySnappy
|
||||
magicBodySnappy = "sNaPpY"
|
||||
magicBody = "S2sTwO"
|
||||
|
||||
// maxBlockSize is the maximum size of the input to encodeBlock.
|
||||
//
|
||||
// For the framing format (Writer type instead of Encode function),
|
||||
// this is the maximum uncompressed size of a block.
|
||||
maxBlockSize = 4 << 20
|
||||
|
||||
// minBlockSize is the minimum size of block setting when creating a writer.
|
||||
minBlockSize = 4 << 10
|
||||
|
||||
skippableFrameHeader = 4
|
||||
maxChunkSize = 1<<24 - 1 // 16777215
|
||||
|
||||
// Default block size
|
||||
defaultBlockSize = 1 << 20
|
||||
|
||||
// maxSnappyBlockSize is the maximum snappy block size.
|
||||
maxSnappyBlockSize = 1 << 16
|
||||
|
||||
obufHeaderLen = checksumSize + chunkHeaderSize
|
||||
)
|
||||
|
||||
const (
|
||||
chunkTypeCompressedData = 0x00
|
||||
chunkTypeUncompressedData = 0x01
|
||||
ChunkTypeIndex = 0x99
|
||||
chunkTypePadding = 0xfe
|
||||
chunkTypeStreamIdentifier = 0xff
|
||||
)
|
||||
|
||||
var (
|
||||
crcTable = crc32.MakeTable(crc32.Castagnoli)
|
||||
magicChunkSnappyBytes = []byte(magicChunkSnappy) // Can be passed to functions where it escapes.
|
||||
magicChunkBytes = []byte(magicChunk) // Can be passed to functions where it escapes.
|
||||
)
|
||||
|
||||
// crc implements the checksum specified in section 3 of
|
||||
// https://github.com/google/snappy/blob/master/framing_format.txt
|
||||
func crc(b []byte) uint32 {
|
||||
race.ReadSlice(b)
|
||||
|
||||
c := crc32.Update(0, crcTable, b)
|
||||
return c>>15 | c<<17 + 0xa282ead8
|
||||
}
|
||||
|
||||
// literalExtraSize returns the extra size of encoding n literals.
|
||||
// n should be >= 0 and <= math.MaxUint32.
|
||||
func literalExtraSize(n int64) int64 {
|
||||
if n == 0 {
|
||||
return 0
|
||||
}
|
||||
switch {
|
||||
case n < 60:
|
||||
return 1
|
||||
case n < 1<<8:
|
||||
return 2
|
||||
case n < 1<<16:
|
||||
return 3
|
||||
case n < 1<<24:
|
||||
return 4
|
||||
default:
|
||||
return 5
|
||||
}
|
||||
}
|
||||
|
||||
type byter interface {
|
||||
Bytes() []byte
|
||||
}
|
||||
|
||||
var _ byter = &bytes.Buffer{}
|
||||
Generated
Vendored
-1062
File diff suppressed because it is too large
Load Diff
-1
@@ -1 +0,0 @@
|
||||
*.test
|
||||
Generated
Vendored
-28
@@ -1,28 +0,0 @@
|
||||
linters-settings:
|
||||
golint:
|
||||
min-confidence: 0
|
||||
|
||||
misspell:
|
||||
locale: US
|
||||
|
||||
linters:
|
||||
disable-all: true
|
||||
enable:
|
||||
- typecheck
|
||||
- goimports
|
||||
- misspell
|
||||
- govet
|
||||
- revive
|
||||
- ineffassign
|
||||
- gosimple
|
||||
- unparam
|
||||
- unused
|
||||
|
||||
issues:
|
||||
exclude-use-default: false
|
||||
exclude:
|
||||
- should have a package comment
|
||||
- error strings should not be capitalized or end with punctuation or a newline
|
||||
- should have comment # TODO(aead): Remove once all exported ident. have comments!
|
||||
service:
|
||||
golangci-lint-version: 1.51.2 # use the fixed version to not introduce new linters unexpectedly
|
||||
-202
@@ -1,202 +0,0 @@
|
||||
|
||||
Apache License
|
||||
Version 2.0, January 2004
|
||||
http://www.apache.org/licenses/
|
||||
|
||||
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
||||
|
||||
1. Definitions.
|
||||
|
||||
"License" shall mean the terms and conditions for use, reproduction,
|
||||
and distribution as defined by Sections 1 through 9 of this document.
|
||||
|
||||
"Licensor" shall mean the copyright owner or entity authorized by
|
||||
the copyright owner that is granting the License.
|
||||
|
||||
"Legal Entity" shall mean the union of the acting entity and all
|
||||
other entities that control, are controlled by, or are under common
|
||||
control with that entity. For the purposes of this definition,
|
||||
"control" means (i) the power, direct or indirect, to cause the
|
||||
direction or management of such entity, whether by contract or
|
||||
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
||||
outstanding shares, or (iii) beneficial ownership of such entity.
|
||||
|
||||
"You" (or "Your") shall mean an individual or Legal Entity
|
||||
exercising permissions granted by this License.
|
||||
|
||||
"Source" form shall mean the preferred form for making modifications,
|
||||
including but not limited to software source code, documentation
|
||||
source, and configuration files.
|
||||
|
||||
"Object" form shall mean any form resulting from mechanical
|
||||
transformation or translation of a Source form, including but
|
||||
not limited to compiled object code, generated documentation,
|
||||
and conversions to other media types.
|
||||
|
||||
"Work" shall mean the work of authorship, whether in Source or
|
||||
Object form, made available under the License, as indicated by a
|
||||
copyright notice that is included in or attached to the work
|
||||
(an example is provided in the Appendix below).
|
||||
|
||||
"Derivative Works" shall mean any work, whether in Source or Object
|
||||
form, that is based on (or derived from) the Work and for which the
|
||||
editorial revisions, annotations, elaborations, or other modifications
|
||||
represent, as a whole, an original work of authorship. For the purposes
|
||||
of this License, Derivative Works shall not include works that remain
|
||||
separable from, or merely link (or bind by name) to the interfaces of,
|
||||
the Work and Derivative Works thereof.
|
||||
|
||||
"Contribution" shall mean any work of authorship, including
|
||||
the original version of the Work and any modifications or additions
|
||||
to that Work or Derivative Works thereof, that is intentionally
|
||||
submitted to Licensor for inclusion in the Work by the copyright owner
|
||||
or by an individual or Legal Entity authorized to submit on behalf of
|
||||
the copyright owner. For the purposes of this definition, "submitted"
|
||||
means any form of electronic, verbal, or written communication sent
|
||||
to the Licensor or its representatives, including but not limited to
|
||||
communication on electronic mailing lists, source code control systems,
|
||||
and issue tracking systems that are managed by, or on behalf of, the
|
||||
Licensor for the purpose of discussing and improving the Work, but
|
||||
excluding communication that is conspicuously marked or otherwise
|
||||
designated in writing by the copyright owner as "Not a Contribution."
|
||||
|
||||
"Contributor" shall mean Licensor and any individual or Legal Entity
|
||||
on behalf of whom a Contribution has been received by Licensor and
|
||||
subsequently incorporated within the Work.
|
||||
|
||||
2. Grant of Copyright License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
copyright license to reproduce, prepare Derivative Works of,
|
||||
publicly display, publicly perform, sublicense, and distribute the
|
||||
Work and such Derivative Works in Source or Object form.
|
||||
|
||||
3. Grant of Patent License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
(except as stated in this section) patent license to make, have made,
|
||||
use, offer to sell, sell, import, and otherwise transfer the Work,
|
||||
where such license applies only to those patent claims licensable
|
||||
by such Contributor that are necessarily infringed by their
|
||||
Contribution(s) alone or by combination of their Contribution(s)
|
||||
with the Work to which such Contribution(s) was submitted. If You
|
||||
institute patent litigation against any entity (including a
|
||||
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
||||
or a Contribution incorporated within the Work constitutes direct
|
||||
or contributory patent infringement, then any patent licenses
|
||||
granted to You under this License for that Work shall terminate
|
||||
as of the date such litigation is filed.
|
||||
|
||||
4. Redistribution. You may reproduce and distribute copies of the
|
||||
Work or Derivative Works thereof in any medium, with or without
|
||||
modifications, and in Source or Object form, provided that You
|
||||
meet the following conditions:
|
||||
|
||||
(a) You must give any other recipients of the Work or
|
||||
Derivative Works a copy of this License; and
|
||||
|
||||
(b) You must cause any modified files to carry prominent notices
|
||||
stating that You changed the files; and
|
||||
|
||||
(c) You must retain, in the Source form of any Derivative Works
|
||||
that You distribute, all copyright, patent, trademark, and
|
||||
attribution notices from the Source form of the Work,
|
||||
excluding those notices that do not pertain to any part of
|
||||
the Derivative Works; and
|
||||
|
||||
(d) If the Work includes a "NOTICE" text file as part of its
|
||||
distribution, then any Derivative Works that You distribute must
|
||||
include a readable copy of the attribution notices contained
|
||||
within such NOTICE file, excluding those notices that do not
|
||||
pertain to any part of the Derivative Works, in at least one
|
||||
of the following places: within a NOTICE text file distributed
|
||||
as part of the Derivative Works; within the Source form or
|
||||
documentation, if provided along with the Derivative Works; or,
|
||||
within a display generated by the Derivative Works, if and
|
||||
wherever such third-party notices normally appear. The contents
|
||||
of the NOTICE file are for informational purposes only and
|
||||
do not modify the License. You may add Your own attribution
|
||||
notices within Derivative Works that You distribute, alongside
|
||||
or as an addendum to the NOTICE text from the Work, provided
|
||||
that such additional attribution notices cannot be construed
|
||||
as modifying the License.
|
||||
|
||||
You may add Your own copyright statement to Your modifications and
|
||||
may provide additional or different license terms and conditions
|
||||
for use, reproduction, or distribution of Your modifications, or
|
||||
for any such Derivative Works as a whole, provided Your use,
|
||||
reproduction, and distribution of the Work otherwise complies with
|
||||
the conditions stated in this License.
|
||||
|
||||
5. Submission of Contributions. Unless You explicitly state otherwise,
|
||||
any Contribution intentionally submitted for inclusion in the Work
|
||||
by You to the Licensor shall be under the terms and conditions of
|
||||
this License, without any additional terms or conditions.
|
||||
Notwithstanding the above, nothing herein shall supersede or modify
|
||||
the terms of any separate license agreement you may have executed
|
||||
with Licensor regarding such Contributions.
|
||||
|
||||
6. Trademarks. This License does not grant permission to use the trade
|
||||
names, trademarks, service marks, or product names of the Licensor,
|
||||
except as required for reasonable and customary use in describing the
|
||||
origin of the Work and reproducing the content of the NOTICE file.
|
||||
|
||||
7. Disclaimer of Warranty. Unless required by applicable law or
|
||||
agreed to in writing, Licensor provides the Work (and each
|
||||
Contributor provides its Contributions) on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
||||
implied, including, without limitation, any warranties or conditions
|
||||
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
||||
PARTICULAR PURPOSE. You are solely responsible for determining the
|
||||
appropriateness of using or redistributing the Work and assume any
|
||||
risks associated with Your exercise of permissions under this License.
|
||||
|
||||
8. Limitation of Liability. In no event and under no legal theory,
|
||||
whether in tort (including negligence), contract, or otherwise,
|
||||
unless required by applicable law (such as deliberate and grossly
|
||||
negligent acts) or agreed to in writing, shall any Contributor be
|
||||
liable to You for damages, including any direct, indirect, special,
|
||||
incidental, or consequential damages of any character arising as a
|
||||
result of this License or out of the use or inability to use the
|
||||
Work (including but not limited to damages for loss of goodwill,
|
||||
work stoppage, computer failure or malfunction, or any and all
|
||||
other commercial damages or losses), even if such Contributor
|
||||
has been advised of the possibility of such damages.
|
||||
|
||||
9. Accepting Warranty or Additional Liability. While redistributing
|
||||
the Work or Derivative Works thereof, You may choose to offer,
|
||||
and charge a fee for, acceptance of support, warranty, indemnity,
|
||||
or other liability obligations and/or rights consistent with this
|
||||
License. However, in accepting such obligations, You may act only
|
||||
on Your own behalf and on Your sole responsibility, not on behalf
|
||||
of any other Contributor, and only if You agree to indemnify,
|
||||
defend, and hold each Contributor harmless for any liability
|
||||
incurred by, or claims asserted against, such Contributor by reason
|
||||
of your accepting any such warranty or additional liability.
|
||||
|
||||
END OF TERMS AND CONDITIONS
|
||||
|
||||
APPENDIX: How to apply the Apache License to your work.
|
||||
|
||||
To apply the Apache License to your work, attach the following
|
||||
boilerplate notice, with the fields enclosed by brackets "[]"
|
||||
replaced with your own identifying information. (Don't include
|
||||
the brackets!) The text should be enclosed in the appropriate
|
||||
comment syntax for the file format. We also recommend that a
|
||||
file or class name and description of purpose be included on the
|
||||
same "printed page" as the copyright notice for easier
|
||||
identification within third-party archives.
|
||||
|
||||
Copyright [yyyy] [name of copyright owner]
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
-99
@@ -1,99 +0,0 @@
|
||||
[](https://godoc.org/github.com/minio/highwayhash)
|
||||
[](https://travis-ci.org/minio/highwayhash)
|
||||
|
||||
## HighwayHash
|
||||
|
||||
[HighwayHash](https://github.com/google/highwayhash) is a pseudo-random-function (PRF) developed by Jyrki Alakuijala, Bill Cox and Jan Wassenberg (Google research). HighwayHash takes a 256 bit key and computes 64, 128 or 256 bit hash values of given messages.
|
||||
|
||||
It can be used to prevent hash-flooding attacks or authenticate short-lived messages. Additionally it can be used as a fingerprinting function. HighwayHash is not a general purpose cryptographic hash function (such as Blake2b, SHA-3 or SHA-2) and should not be used if strong collision resistance is required.
|
||||
|
||||
This repository contains a native Go version and optimized assembly implementations for Intel, ARM and ppc64le architectures.
|
||||
|
||||
### High performance
|
||||
|
||||
HighwayHash is an approximately 5x faster SIMD hash function as compared to [SipHash](https://www.131002.net/siphash/siphash.pdf) which in itself is a fast and 'cryptographically strong' pseudo-random function designed by Aumasson and Bernstein.
|
||||
|
||||
HighwayHash uses a new way of mixing inputs with AVX2 multiply and permute instructions. The multiplications are 32x32 bit giving 64 bits-wide results and are therefore infeasible to reverse. Additionally permuting equalizes the distribution of the resulting bytes. The algorithm outputs digests ranging from 64 bits up to 256 bits at no extra cost.
|
||||
|
||||
### Stable
|
||||
|
||||
All three output sizes of HighwayHash have been declared [stable](https://github.com/google/highwayhash/#versioning-and-stability) as of January 2018. This means that the hash results for any given input message are guaranteed not to change.
|
||||
|
||||
### Installation
|
||||
|
||||
Install: `go get -u github.com/minio/highwayhash`
|
||||
|
||||
### Intel Performance
|
||||
|
||||
Below are the single core results on an Intel Core i7 (3.1 GHz) for 256 bit outputs:
|
||||
|
||||
```
|
||||
BenchmarkSum256_16 204.17 MB/s
|
||||
BenchmarkSum256_64 1040.63 MB/s
|
||||
BenchmarkSum256_1K 8653.30 MB/s
|
||||
BenchmarkSum256_8K 13476.07 MB/s
|
||||
BenchmarkSum256_1M 14928.71 MB/s
|
||||
BenchmarkSum256_5M 14180.04 MB/s
|
||||
BenchmarkSum256_10M 12458.65 MB/s
|
||||
BenchmarkSum256_25M 11927.25 MB/s
|
||||
```
|
||||
|
||||
So for moderately sized messages it tops out at about 15 GB/sec. Also for small messages (1K) the performance is already at approximately 60% of the maximum throughput.
|
||||
|
||||
### ARM Performance
|
||||
|
||||
Below are the single core results on an EC2 c7g.4xlarge (Graviton3) instance for 256 bit outputs:
|
||||
|
||||
```
|
||||
BenchmarkSum256_16 143.66 MB/s
|
||||
BenchmarkSum256_64 628.75 MB/s
|
||||
BenchmarkSum256_1K 3621.71 MB/s
|
||||
BenchmarkSum256_8K 5039.64 MB/s
|
||||
BenchmarkSum256_1M 5279.79 MB/s
|
||||
BenchmarkSum256_5M 5474.60 MB/s
|
||||
BenchmarkSum256_10M 5621.73 MB/s
|
||||
BenchmarkSum256_25M 5250.47 MB/s
|
||||
```
|
||||
|
||||
### ppc64le Performance
|
||||
|
||||
The ppc64le accelerated version is roughly 10x faster compared to the non-optimized version:
|
||||
|
||||
```
|
||||
benchmark old MB/s new MB/s speedup
|
||||
BenchmarkWrite_8K 531.19 5566.41 10.48x
|
||||
BenchmarkSum64_8K 518.86 4971.88 9.58x
|
||||
BenchmarkSum256_8K 502.45 4474.20 8.90x
|
||||
```
|
||||
|
||||
### Performance compared to other hashing techniques
|
||||
|
||||
On a Skylake CPU (3.0 GHz Xeon Platinum 8124M) the table below shows how HighwayHash compares to other hashing techniques for 5 MB messages (single core performance, all Golang implementations, see [benchmark](https://github.com/fwessels/HashCompare/blob/master/benchmarks_test.go)).
|
||||
|
||||
```
|
||||
BenchmarkHighwayHash 11986.98 MB/s
|
||||
BenchmarkSHA256_AVX512 3552.74 MB/s
|
||||
BenchmarkBlake2b 972.38 MB/s
|
||||
BenchmarkSHA1 950.64 MB/s
|
||||
BenchmarkMD5 684.18 MB/s
|
||||
BenchmarkSHA512 562.04 MB/s
|
||||
BenchmarkSHA256 383.07 MB/s
|
||||
```
|
||||
|
||||
*Note: the AVX512 version of SHA256 uses the [multi-buffer crypto library](https://github.com/intel/intel-ipsec-mb) technique as developed by Intel, more details can be found in [sha256-simd](https://github.com/minio/sha256-simd/).*
|
||||
|
||||
### Qualitative assessment
|
||||
|
||||
We have performed a 'qualitative' assessment of how HighwayHash compares to Blake2b in terms of the distribution of the checksums for varying numbers of messages. It shows that HighwayHash behaves similarly according to the following graph:
|
||||
|
||||
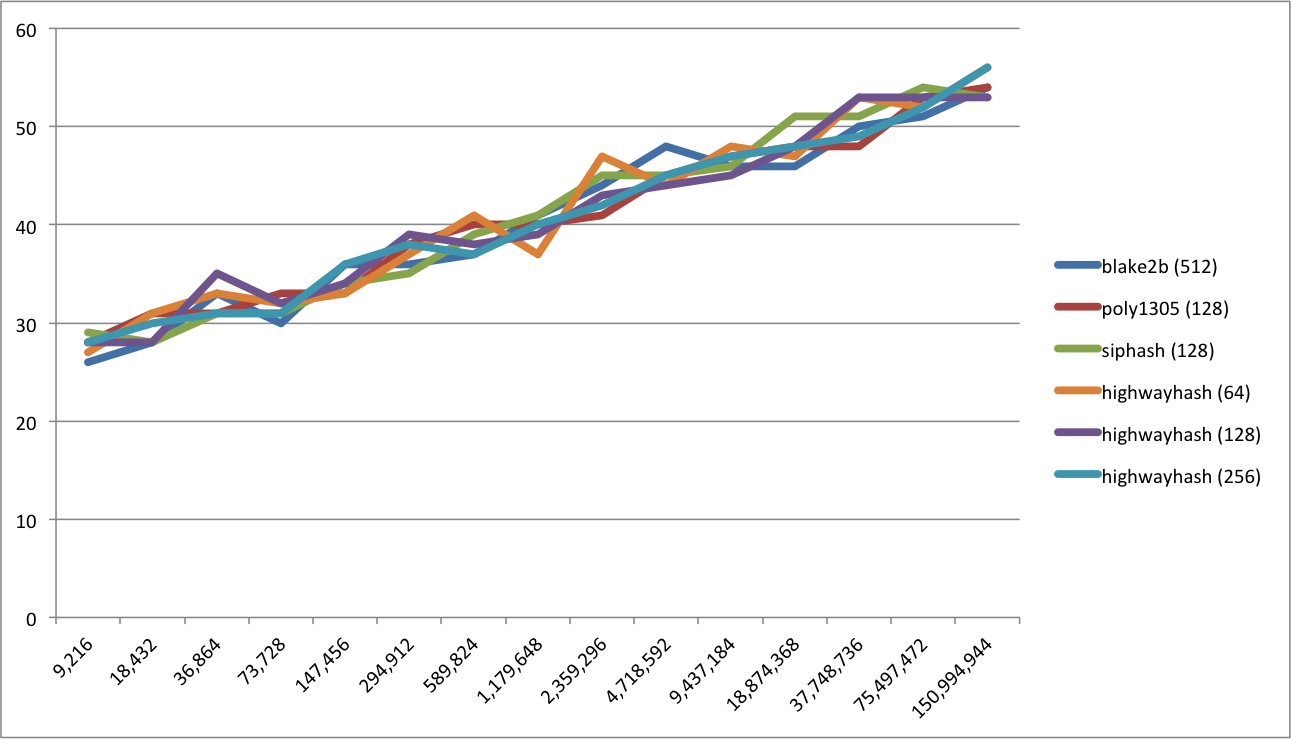
|
||||
|
||||
More information can be found in [HashCompare](https://github.com/fwessels/HashCompare).
|
||||
|
||||
### Requirements
|
||||
|
||||
All Go versions >= 1.11 are supported (needed for required assembly support for the different platforms).
|
||||
|
||||
### Contributing
|
||||
|
||||
Contributions are welcome, please send PRs for any enhancements.
|
||||
Generated
Vendored
-250
@@ -1,250 +0,0 @@
|
||||
// Copyright (c) 2017 Minio Inc. All rights reserved.
|
||||
// Use of this source code is governed by a license that can be
|
||||
// found in the LICENSE file.
|
||||
|
||||
// Package highwayhash implements the pseudo-random-function (PRF) HighwayHash.
|
||||
// HighwayHash is a fast hash function designed to defend hash-flooding attacks
|
||||
// or to authenticate short-lived messages.
|
||||
//
|
||||
// HighwayHash is not a general purpose cryptographic hash function and does not
|
||||
// provide (strong) collision resistance.
|
||||
package highwayhash
|
||||
|
||||
import (
|
||||
"encoding/binary"
|
||||
"errors"
|
||||
"hash"
|
||||
)
|
||||
|
||||
const (
|
||||
// Size is the size of HighwayHash-256 checksum in bytes.
|
||||
Size = 32
|
||||
// Size128 is the size of HighwayHash-128 checksum in bytes.
|
||||
Size128 = 16
|
||||
// Size64 is the size of HighwayHash-64 checksum in bytes.
|
||||
Size64 = 8
|
||||
)
|
||||
|
||||
// These will error at compile time if the interface is not conformant.
|
||||
var _ hash.Hash = &Digest{}
|
||||
var _ hash.Hash = &Digest64{}
|
||||
|
||||
var errKeySize = errors.New("highwayhash: invalid key size")
|
||||
|
||||
// New returns a hash.Hash computing the HighwayHash-256 checksum.
|
||||
// It returns a non-nil error if the key is not 32 bytes long.
|
||||
func New(key []byte) (hash.Hash, error) {
|
||||
return NewDigest(key)
|
||||
}
|
||||
|
||||
// New128 returns a hash.Hash computing the HighwayHash-128 checksum.
|
||||
// It returns a non-nil error if the key is not 32 bytes long.
|
||||
func New128(key []byte) (hash.Hash, error) {
|
||||
return NewDigest128(key)
|
||||
}
|
||||
|
||||
// New64 returns a hash.Hash64 computing the HighwayHash-64 checksum.
|
||||
// It returns a non-nil error if the key is not 32 bytes long.
|
||||
func New64(key []byte) (hash.Hash64, error) {
|
||||
return NewDigest64(key)
|
||||
}
|
||||
|
||||
// NewDigest returns a *Digest that conforms to hash.Hash computing
|
||||
// the HighwayHash-256 checksum.
|
||||
// It returns a non-nil error if the key is not 32 bytes long.
|
||||
func NewDigest(key []byte) (*Digest, error) {
|
||||
if len(key) != Size {
|
||||
return nil, errKeySize
|
||||
}
|
||||
h := &Digest{size: Size}
|
||||
copy(h.key[:], key)
|
||||
h.Reset()
|
||||
return h, nil
|
||||
}
|
||||
|
||||
// NewDigest128 returns a *Digest that conforms to hash.Hash computing
|
||||
// the HighwayHash-128 checksum.
|
||||
// It returns a non-nil error if the key is not 32 bytes long.
|
||||
func NewDigest128(key []byte) (*Digest, error) {
|
||||
if len(key) != Size {
|
||||
return nil, errKeySize
|
||||
}
|
||||
h := &Digest{size: Size128}
|
||||
copy(h.key[:], key)
|
||||
h.Reset()
|
||||
return h, nil
|
||||
}
|
||||
|
||||
// NewDigest64 returns a *Digest that conforms to hash.Hash computing
|
||||
// the HighwayHash-64 checksum.
|
||||
// It returns a non-nil error if the key is not 32 bytes long.
|
||||
func NewDigest64(key []byte) (*Digest64, error) {
|
||||
if len(key) != Size {
|
||||
return nil, errKeySize
|
||||
}
|
||||
h := new(Digest64)
|
||||
h.size = Size64
|
||||
copy(h.key[:], key)
|
||||
h.Reset()
|
||||
return h, nil
|
||||
}
|
||||
|
||||
// Sum computes the HighwayHash-256 checksum of data.
|
||||
// It panics if the key is not 32 bytes long.
|
||||
func Sum(data, key []byte) [Size]byte {
|
||||
if len(key) != Size {
|
||||
panic(errKeySize)
|
||||
}
|
||||
var state [16]uint64
|
||||
initialize(&state, key)
|
||||
if n := len(data) & (^(Size - 1)); n > 0 {
|
||||
update(&state, data[:n])
|
||||
data = data[n:]
|
||||
}
|
||||
if len(data) > 0 {
|
||||
var block [Size]byte
|
||||
offset := copy(block[:], data)
|
||||
hashBuffer(&state, &block, offset)
|
||||
}
|
||||
var hash [Size]byte
|
||||
finalize(hash[:], &state)
|
||||
return hash
|
||||
}
|
||||
|
||||
// Sum128 computes the HighwayHash-128 checksum of data.
|
||||
// It panics if the key is not 32 bytes long.
|
||||
func Sum128(data, key []byte) [Size128]byte {
|
||||
if len(key) != Size {
|
||||
panic(errKeySize)
|
||||
}
|
||||
var state [16]uint64
|
||||
initialize(&state, key)
|
||||
if n := len(data) & (^(Size - 1)); n > 0 {
|
||||
update(&state, data[:n])
|
||||
data = data[n:]
|
||||
}
|
||||
if len(data) > 0 {
|
||||
var block [Size]byte
|
||||
offset := copy(block[:], data)
|
||||
hashBuffer(&state, &block, offset)
|
||||
}
|
||||
var hash [Size128]byte
|
||||
finalize(hash[:], &state)
|
||||
return hash
|
||||
}
|
||||
|
||||
// Sum64 computes the HighwayHash-64 checksum of data.
|
||||
// It panics if the key is not 32 bytes long.
|
||||
func Sum64(data, key []byte) uint64 {
|
||||
if len(key) != Size {
|
||||
panic(errKeySize)
|
||||
}
|
||||
var state [16]uint64
|
||||
initialize(&state, key)
|
||||
if n := len(data) & (^(Size - 1)); n > 0 {
|
||||
update(&state, data[:n])
|
||||
data = data[n:]
|
||||
}
|
||||
if len(data) > 0 {
|
||||
var block [Size]byte
|
||||
offset := copy(block[:], data)
|
||||
hashBuffer(&state, &block, offset)
|
||||
}
|
||||
var hash [Size64]byte
|
||||
finalize(hash[:], &state)
|
||||
return binary.LittleEndian.Uint64(hash[:])
|
||||
}
|
||||
|
||||
type Digest64 struct{ Digest }
|
||||
|
||||
func (d *Digest64) Sum64() uint64 {
|
||||
state := d.state
|
||||
if d.offset > 0 {
|
||||
hashBuffer(&state, &d.buffer, d.offset)
|
||||
}
|
||||
var hash [8]byte
|
||||
finalize(hash[:], &state)
|
||||
return binary.LittleEndian.Uint64(hash[:])
|
||||
}
|
||||
|
||||
type Digest struct {
|
||||
state [16]uint64 // v0 | v1 | mul0 | mul1
|
||||
|
||||
key, buffer [Size]byte
|
||||
offset int
|
||||
|
||||
size int
|
||||
}
|
||||
|
||||
func (d *Digest) Size() int { return d.size }
|
||||
|
||||
func (d *Digest) BlockSize() int { return Size }
|
||||
|
||||
func (d *Digest) Reset() {
|
||||
initialize(&d.state, d.key[:])
|
||||
d.offset = 0
|
||||
}
|
||||
|
||||
func (d *Digest) Write(p []byte) (n int, err error) {
|
||||
n = len(p)
|
||||
if d.offset > 0 {
|
||||
remaining := Size - d.offset
|
||||
if n < remaining {
|
||||
d.offset += copy(d.buffer[d.offset:], p)
|
||||
return
|
||||
}
|
||||
copy(d.buffer[d.offset:], p[:remaining])
|
||||
update(&d.state, d.buffer[:])
|
||||
p = p[remaining:]
|
||||
d.offset = 0
|
||||
}
|
||||
if nn := len(p) & (^(Size - 1)); nn > 0 {
|
||||
update(&d.state, p[:nn])
|
||||
p = p[nn:]
|
||||
}
|
||||
if len(p) > 0 {
|
||||
d.offset = copy(d.buffer[d.offset:], p)
|
||||
}
|
||||
return
|
||||
}
|
||||
|
||||
func (d *Digest) Sum(b []byte) []byte {
|
||||
state := d.state
|
||||
if d.offset > 0 {
|
||||
hashBuffer(&state, &d.buffer, d.offset)
|
||||
}
|
||||
var hash [Size]byte
|
||||
finalize(hash[:d.size], &state)
|
||||
return append(b, hash[:d.size]...)
|
||||
}
|
||||
|
||||
func hashBuffer(state *[16]uint64, buffer *[32]byte, offset int) {
|
||||
var block [Size]byte
|
||||
mod32 := (uint64(offset) << 32) + uint64(offset)
|
||||
for i := range state[:4] {
|
||||
state[i] += mod32
|
||||
}
|
||||
for i := range state[4:8] {
|
||||
t0 := uint32(state[i+4])
|
||||
t0 = (t0 << uint(offset)) | (t0 >> uint(32-offset))
|
||||
|
||||
t1 := uint32(state[i+4] >> 32)
|
||||
t1 = (t1 << uint(offset)) | (t1 >> uint(32-offset))
|
||||
|
||||
state[i+4] = (uint64(t1) << 32) | uint64(t0)
|
||||
}
|
||||
|
||||
mod4 := offset & 3
|
||||
remain := offset - mod4
|
||||
|
||||
copy(block[:], buffer[:remain])
|
||||
if offset >= 16 {
|
||||
copy(block[28:], buffer[offset-4:])
|
||||
} else if mod4 != 0 {
|
||||
last := uint32(buffer[remain])
|
||||
last += uint32(buffer[remain+mod4>>1]) << 8
|
||||
last += uint32(buffer[offset-1]) << 16
|
||||
binary.LittleEndian.PutUint32(block[16:], last)
|
||||
}
|
||||
update(state, block[:])
|
||||
}
|
||||
Generated
Vendored
-248
@@ -1,248 +0,0 @@
|
||||
// Copyright (c) 2017 Minio Inc. All rights reserved.
|
||||
// Use of this source code is governed by a license that can be
|
||||
// found in the LICENSE file.
|
||||
|
||||
// +build amd64,!gccgo,!appengine,!nacl,!noasm
|
||||
|
||||
#include "textflag.h"
|
||||
|
||||
DATA ·consAVX2<>+0x00(SB)/8, $0xdbe6d5d5fe4cce2f
|
||||
DATA ·consAVX2<>+0x08(SB)/8, $0xa4093822299f31d0
|
||||
DATA ·consAVX2<>+0x10(SB)/8, $0x13198a2e03707344
|
||||
DATA ·consAVX2<>+0x18(SB)/8, $0x243f6a8885a308d3
|
||||
DATA ·consAVX2<>+0x20(SB)/8, $0x3bd39e10cb0ef593
|
||||
DATA ·consAVX2<>+0x28(SB)/8, $0xc0acf169b5f18a8c
|
||||
DATA ·consAVX2<>+0x30(SB)/8, $0xbe5466cf34e90c6c
|
||||
DATA ·consAVX2<>+0x38(SB)/8, $0x452821e638d01377
|
||||
GLOBL ·consAVX2<>(SB), (NOPTR+RODATA), $64
|
||||
|
||||
DATA ·zipperMergeAVX2<>+0x00(SB)/8, $0xf010e05020c03
|
||||
DATA ·zipperMergeAVX2<>+0x08(SB)/8, $0x70806090d0a040b
|
||||
DATA ·zipperMergeAVX2<>+0x10(SB)/8, $0xf010e05020c03
|
||||
DATA ·zipperMergeAVX2<>+0x18(SB)/8, $0x70806090d0a040b
|
||||
GLOBL ·zipperMergeAVX2<>(SB), (NOPTR+RODATA), $32
|
||||
|
||||
#define REDUCE_MOD(x0, x1, x2, x3, tmp0, tmp1, y0, y1) \
|
||||
MOVQ $0x3FFFFFFFFFFFFFFF, tmp0 \
|
||||
ANDQ tmp0, x3 \
|
||||
MOVQ x2, y0 \
|
||||
MOVQ x3, y1 \
|
||||
\
|
||||
MOVQ x2, tmp0 \
|
||||
MOVQ x3, tmp1 \
|
||||
SHLQ $1, tmp1 \
|
||||
SHRQ $63, tmp0 \
|
||||
MOVQ tmp1, x3 \
|
||||
ORQ tmp0, x3 \
|
||||
\
|
||||
SHLQ $1, x2 \
|
||||
\
|
||||
MOVQ y0, tmp0 \
|
||||
MOVQ y1, tmp1 \
|
||||
SHLQ $2, tmp1 \
|
||||
SHRQ $62, tmp0 \
|
||||
MOVQ tmp1, y1 \
|
||||
ORQ tmp0, y1 \
|
||||
\
|
||||
SHLQ $2, y0 \
|
||||
\
|
||||
XORQ x0, y0 \
|
||||
XORQ x2, y0 \
|
||||
XORQ x1, y1 \
|
||||
XORQ x3, y1
|
||||
|
||||
#define UPDATE(msg) \
|
||||
VPADDQ msg, Y2, Y2 \
|
||||
VPADDQ Y3, Y2, Y2 \
|
||||
\
|
||||
VPSRLQ $32, Y1, Y0 \
|
||||
BYTE $0xC5; BYTE $0xFD; BYTE $0xF4; BYTE $0xC2 \ // VPMULUDQ Y2, Y0, Y0
|
||||
VPXOR Y0, Y3, Y3 \
|
||||
\
|
||||
VPADDQ Y4, Y1, Y1 \
|
||||
\
|
||||
VPSRLQ $32, Y2, Y0 \
|
||||
BYTE $0xC5; BYTE $0xFD; BYTE $0xF4; BYTE $0xC1 \ // VPMULUDQ Y1, Y0, Y0
|
||||
VPXOR Y0, Y4, Y4 \
|
||||
\
|
||||
VPSHUFB Y5, Y2, Y0 \
|
||||
VPADDQ Y0, Y1, Y1 \
|
||||
\
|
||||
VPSHUFB Y5, Y1, Y0 \
|
||||
VPADDQ Y0, Y2, Y2
|
||||
|
||||
// func initializeAVX2(state *[16]uint64, key []byte)
|
||||
TEXT ·initializeAVX2(SB), 4, $0-32
|
||||
MOVQ state+0(FP), AX
|
||||
MOVQ key_base+8(FP), BX
|
||||
MOVQ $·consAVX2<>(SB), CX
|
||||
|
||||
VMOVDQU 0(BX), Y1
|
||||
VPSHUFD $177, Y1, Y2
|
||||
|
||||
VMOVDQU 0(CX), Y3
|
||||
VMOVDQU 32(CX), Y4
|
||||
|
||||
VPXOR Y3, Y1, Y1
|
||||
VPXOR Y4, Y2, Y2
|
||||
|
||||
VMOVDQU Y1, 0(AX)
|
||||
VMOVDQU Y2, 32(AX)
|
||||
VMOVDQU Y3, 64(AX)
|
||||
VMOVDQU Y4, 96(AX)
|
||||
VZEROUPPER
|
||||
RET
|
||||
|
||||
// func updateAVX2(state *[16]uint64, msg []byte)
|
||||
TEXT ·updateAVX2(SB), 4, $0-32
|
||||
MOVQ state+0(FP), AX
|
||||
MOVQ msg_base+8(FP), BX
|
||||
MOVQ msg_len+16(FP), CX
|
||||
|
||||
CMPQ CX, $32
|
||||
JB DONE
|
||||
|
||||
VMOVDQU 0(AX), Y1
|
||||
VMOVDQU 32(AX), Y2
|
||||
VMOVDQU 64(AX), Y3
|
||||
VMOVDQU 96(AX), Y4
|
||||
|
||||
VMOVDQU ·zipperMergeAVX2<>(SB), Y5
|
||||
|
||||
LOOP:
|
||||
VMOVDQU 0(BX), Y0
|
||||
UPDATE(Y0)
|
||||
|
||||
ADDQ $32, BX
|
||||
SUBQ $32, CX
|
||||
JA LOOP
|
||||
|
||||
VMOVDQU Y1, 0(AX)
|
||||
VMOVDQU Y2, 32(AX)
|
||||
VMOVDQU Y3, 64(AX)
|
||||
VMOVDQU Y4, 96(AX)
|
||||
VZEROUPPER
|
||||
|
||||
DONE:
|
||||
RET
|
||||
|
||||
// func finalizeAVX2(out []byte, state *[16]uint64)
|
||||
TEXT ·finalizeAVX2(SB), 4, $0-32
|
||||
MOVQ state+24(FP), AX
|
||||
MOVQ out_base+0(FP), BX
|
||||
MOVQ out_len+8(FP), CX
|
||||
|
||||
VMOVDQU 0(AX), Y1
|
||||
VMOVDQU 32(AX), Y2
|
||||
VMOVDQU 64(AX), Y3
|
||||
VMOVDQU 96(AX), Y4
|
||||
|
||||
VMOVDQU ·zipperMergeAVX2<>(SB), Y5
|
||||
|
||||
VPERM2I128 $1, Y1, Y1, Y0
|
||||
VPSHUFD $177, Y0, Y0
|
||||
UPDATE(Y0)
|
||||
|
||||
VPERM2I128 $1, Y1, Y1, Y0
|
||||
VPSHUFD $177, Y0, Y0
|
||||
UPDATE(Y0)
|
||||
|
||||
VPERM2I128 $1, Y1, Y1, Y0
|
||||
VPSHUFD $177, Y0, Y0
|
||||
UPDATE(Y0)
|
||||
|
||||
VPERM2I128 $1, Y1, Y1, Y0
|
||||
VPSHUFD $177, Y0, Y0
|
||||
UPDATE(Y0)
|
||||
|
||||
CMPQ CX, $8
|
||||
JE skipUpdate // Just 4 rounds for 64-bit checksum
|
||||
|
||||
VPERM2I128 $1, Y1, Y1, Y0
|
||||
VPSHUFD $177, Y0, Y0
|
||||
UPDATE(Y0)
|
||||
|
||||
VPERM2I128 $1, Y1, Y1, Y0
|
||||
VPSHUFD $177, Y0, Y0
|
||||
UPDATE(Y0)
|
||||
|
||||
CMPQ CX, $16
|
||||
JE skipUpdate // 6 rounds for 128-bit checksum
|
||||
|
||||
VPERM2I128 $1, Y1, Y1, Y0
|
||||
VPSHUFD $177, Y0, Y0
|
||||
UPDATE(Y0)
|
||||
|
||||
VPERM2I128 $1, Y1, Y1, Y0
|
||||
VPSHUFD $177, Y0, Y0
|
||||
UPDATE(Y0)
|
||||
|
||||
VPERM2I128 $1, Y1, Y1, Y0
|
||||
VPSHUFD $177, Y0, Y0
|
||||
UPDATE(Y0)
|
||||
|
||||
VPERM2I128 $1, Y1, Y1, Y0
|
||||
VPSHUFD $177, Y0, Y0
|
||||
UPDATE(Y0)
|
||||
|
||||
skipUpdate:
|
||||
VMOVDQU Y1, 0(AX)
|
||||
VMOVDQU Y2, 32(AX)
|
||||
VMOVDQU Y3, 64(AX)
|
||||
VMOVDQU Y4, 96(AX)
|
||||
VZEROUPPER
|
||||
|
||||
CMPQ CX, $8
|
||||
JE hash64
|
||||
CMPQ CX, $16
|
||||
JE hash128
|
||||
|
||||
// 256-bit checksum
|
||||
MOVQ 0*8(AX), R8
|
||||
MOVQ 1*8(AX), R9
|
||||
MOVQ 4*8(AX), R10
|
||||
MOVQ 5*8(AX), R11
|
||||
ADDQ 8*8(AX), R8
|
||||
ADDQ 9*8(AX), R9
|
||||
ADDQ 12*8(AX), R10
|
||||
ADDQ 13*8(AX), R11
|
||||
|
||||
REDUCE_MOD(R8, R9, R10, R11, R12, R13, R14, R15)
|
||||
MOVQ R14, 0(BX)
|
||||
MOVQ R15, 8(BX)
|
||||
|
||||
MOVQ 2*8(AX), R8
|
||||
MOVQ 3*8(AX), R9
|
||||
MOVQ 6*8(AX), R10
|
||||
MOVQ 7*8(AX), R11
|
||||
ADDQ 10*8(AX), R8
|
||||
ADDQ 11*8(AX), R9
|
||||
ADDQ 14*8(AX), R10
|
||||
ADDQ 15*8(AX), R11
|
||||
|
||||
REDUCE_MOD(R8, R9, R10, R11, R12, R13, R14, R15)
|
||||
MOVQ R14, 16(BX)
|
||||
MOVQ R15, 24(BX)
|
||||
RET
|
||||
|
||||
hash128:
|
||||
MOVQ 0*8(AX), R8
|
||||
MOVQ 1*8(AX), R9
|
||||
ADDQ 6*8(AX), R8
|
||||
ADDQ 7*8(AX), R9
|
||||
ADDQ 8*8(AX), R8
|
||||
ADDQ 9*8(AX), R9
|
||||
ADDQ 14*8(AX), R8
|
||||
ADDQ 15*8(AX), R9
|
||||
MOVQ R8, 0(BX)
|
||||
MOVQ R9, 8(BX)
|
||||
RET
|
||||
|
||||
hash64:
|
||||
MOVQ 0*8(AX), DX
|
||||
ADDQ 4*8(AX), DX
|
||||
ADDQ 8*8(AX), DX
|
||||
ADDQ 12*8(AX), DX
|
||||
MOVQ DX, 0(BX)
|
||||
RET
|
||||
|
||||
Generated
Vendored
-132
@@ -1,132 +0,0 @@
|
||||
//
|
||||
// Copyright (c) 2024 Minio Inc. All rights reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
//
|
||||
|
||||
//+build !noasm,!appengine
|
||||
|
||||
#include "textflag.h"
|
||||
|
||||
TEXT ·getVectorLength(SB), NOSPLIT, $0
|
||||
WORD $0xd2800002 // mov x2, #0
|
||||
WORD $0x04225022 // addvl x2, x2, #1
|
||||
WORD $0xd37df042 // lsl x2, x2, #3
|
||||
WORD $0xd2800003 // mov x3, #0
|
||||
WORD $0x04635023 // addpl x3, x3, #1
|
||||
WORD $0xd37df063 // lsl x3, x3, #3
|
||||
MOVD R2, vl+0(FP)
|
||||
MOVD R3, pl+8(FP)
|
||||
RET
|
||||
|
||||
TEXT ·updateArm64Sve(SB), NOSPLIT, $0
|
||||
MOVD state+0(FP), R0
|
||||
MOVD msg_base+8(FP), R1
|
||||
MOVD msg_len+16(FP), R2 // length of message
|
||||
SUBS $32, R2
|
||||
BMI completeSve
|
||||
|
||||
WORD $0x2518e3e1 // ptrue p1.b
|
||||
WORD $0xa5e0a401 // ld1d z1.d, p1/z, [x0]
|
||||
WORD $0xa5e1a402 // ld1d z2.d, p1/z, [x0, #1, MUL VL]
|
||||
WORD $0xa5e2a403 // ld1d z3.d, p1/z, [x0, #2, MUL VL]
|
||||
WORD $0xa5e3a404 // ld1d z4.d, p1/z, [x0, #3, MUL VL]
|
||||
|
||||
// Load zipper merge constants table pointer
|
||||
MOVD $·zipperMergeSve(SB), R3
|
||||
WORD $0xa5e0a465 // ld1d z5.d, p1/z, [x3]
|
||||
WORD $0x25b8c006 // mov z6.s, #0
|
||||
WORD $0x25d8e3e2 // ptrue p2.d /* set every other lane for "s" type */
|
||||
|
||||
loopSve:
|
||||
WORD $0xa5e0a420 // ld1d z0.d, p1/z, [x1]
|
||||
ADD $32, R1
|
||||
|
||||
WORD $0x04e00042 // add z2.d, z2.d, z0.d
|
||||
WORD $0x04e30042 // add z2.d, z2.d, z3.d
|
||||
WORD $0x04e09420 // lsr z0.d, z1.d, #32
|
||||
WORD $0x05a6c847 // sel z7.s, p2, z2.s, z6.s
|
||||
WORD $0x04d004e0 // mul z0.d, p1/m, z0.d, z7.d
|
||||
WORD $0x04a33003 // eor z3.d, z0.d, z3.d
|
||||
WORD $0x04e10081 // add z1.d, z4.d, z1.d
|
||||
WORD $0x04e09440 // lsr z0.d, z2.d, #32
|
||||
WORD $0x05a6c827 // sel z7.s, p2, z1.s, z6.s
|
||||
WORD $0x04d004e0 // mul z0.d, p1/m, z0.d, z7.d
|
||||
WORD $0x04a43004 // eor z4.d, z0.d, z4.d
|
||||
WORD $0x05253040 // tbl z0.b, z2.b, z5.b
|
||||
WORD $0x04e00021 // add z1.d, z1.d, z0.d
|
||||
WORD $0x05253020 // tbl z0.b, z1.b, z5.b
|
||||
WORD $0x04e00042 // add z2.d, z2.d, z0.d
|
||||
|
||||
SUBS $32, R2
|
||||
BPL loopSve
|
||||
|
||||
WORD $0xe5e0e401 // st1d z1.d, p1, [x0]
|
||||
WORD $0xe5e1e402 // st1d z2.d, p1, [x0, #1, MUL VL]
|
||||
WORD $0xe5e2e403 // st1d z3.d, p1, [x0, #2, MUL VL]
|
||||
WORD $0xe5e3e404 // st1d z4.d, p1, [x0, #3, MUL VL]
|
||||
|
||||
completeSve:
|
||||
RET
|
||||
|
||||
TEXT ·updateArm64Sve2(SB), NOSPLIT, $0
|
||||
MOVD state+0(FP), R0
|
||||
MOVD msg_base+8(FP), R1
|
||||
MOVD msg_len+16(FP), R2 // length of message
|
||||
SUBS $32, R2
|
||||
BMI completeSve2
|
||||
|
||||
WORD $0x2518e3e1 // ptrue p1.b
|
||||
WORD $0xa5e0a401 // ld1d z1.d, p1/z, [x0]
|
||||
WORD $0xa5e1a402 // ld1d z2.d, p1/z, [x0, #1, MUL VL]
|
||||
WORD $0xa5e2a403 // ld1d z3.d, p1/z, [x0, #2, MUL VL]
|
||||
WORD $0xa5e3a404 // ld1d z4.d, p1/z, [x0, #3, MUL VL]
|
||||
|
||||
// Load zipper merge constants table pointer
|
||||
MOVD $·zipperMergeSve(SB), R3
|
||||
WORD $0xa5e0a465 // ld1d z5.d, p1/z, [x3]
|
||||
|
||||
loopSve2:
|
||||
WORD $0xa5e0a420 // ld1d z0.d, p1/z, [x1]
|
||||
ADD $32, R1
|
||||
|
||||
WORD $0x04e00042 // add z2.d, z2.d, z0.d
|
||||
WORD $0x04e30042 // add z2.d, z2.d, z3.d
|
||||
WORD $0x04e09420 // lsr z0.d, z1.d, #32
|
||||
WORD $0x45c27800 // umullb z0.d, z0.s, z2.s
|
||||
WORD $0x04a33003 // eor z3.d, z0.d, z3.d
|
||||
WORD $0x04e10081 // add z1.d, z4.d, z1.d
|
||||
WORD $0x04e09440 // lsr z0.d, z2.d, #32
|
||||
WORD $0x45c17800 // umullb z0.d, z0.s, z1.s
|
||||
WORD $0x04a43004 // eor z4.d, z0.d, z4.d
|
||||
WORD $0x05253040 // tbl z0.b, z2.b, z5.b
|
||||
WORD $0x04e00021 // add z1.d, z1.d, z0.d
|
||||
WORD $0x05253020 // tbl z0.b, z1.b, z5.b
|
||||
WORD $0x04e00042 // add z2.d, z2.d, z0.d
|
||||
|
||||
SUBS $32, R2
|
||||
BPL loopSve2
|
||||
|
||||
WORD $0xe5e0e401 // st1d z1.d, p1, [x0]
|
||||
WORD $0xe5e1e402 // st1d z2.d, p1, [x0, #1, MUL VL]
|
||||
WORD $0xe5e2e403 // st1d z3.d, p1, [x0, #2, MUL VL]
|
||||
WORD $0xe5e3e404 // st1d z4.d, p1, [x0, #3, MUL VL]
|
||||
|
||||
completeSve2:
|
||||
RET
|
||||
|
||||
DATA ·zipperMergeSve+0x00(SB)/8, $0x000f010e05020c03
|
||||
DATA ·zipperMergeSve+0x08(SB)/8, $0x070806090d0a040b
|
||||
DATA ·zipperMergeSve+0x10(SB)/8, $0x101f111e15121c13
|
||||
DATA ·zipperMergeSve+0x18(SB)/8, $0x171816191d1a141b
|
||||
GLOBL ·zipperMergeSve(SB), (NOPTR+RODATA), $32
|
||||
Generated
Vendored
-70
@@ -1,70 +0,0 @@
|
||||
// Copyright (c) 2017 Minio Inc. All rights reserved.
|
||||
// Use of this source code is governed by a license that can be
|
||||
// found in the LICENSE file.
|
||||
|
||||
//go:build amd64 && !gccgo && !appengine && !nacl && !noasm
|
||||
// +build amd64,!gccgo,!appengine,!nacl,!noasm
|
||||
|
||||
package highwayhash
|
||||
|
||||
import "golang.org/x/sys/cpu"
|
||||
|
||||
var (
|
||||
useSSE4 = cpu.X86.HasSSE41
|
||||
useAVX2 = cpu.X86.HasAVX2
|
||||
useNEON = false
|
||||
useSVE = false
|
||||
useSVE2 = false
|
||||
useVMX = false
|
||||
)
|
||||
|
||||
//go:noescape
|
||||
func initializeSSE4(state *[16]uint64, key []byte)
|
||||
|
||||
//go:noescape
|
||||
func initializeAVX2(state *[16]uint64, key []byte)
|
||||
|
||||
//go:noescape
|
||||
func updateSSE4(state *[16]uint64, msg []byte)
|
||||
|
||||
//go:noescape
|
||||
func updateAVX2(state *[16]uint64, msg []byte)
|
||||
|
||||
//go:noescape
|
||||
func finalizeSSE4(out []byte, state *[16]uint64)
|
||||
|
||||
//go:noescape
|
||||
func finalizeAVX2(out []byte, state *[16]uint64)
|
||||
|
||||
func initialize(state *[16]uint64, key []byte) {
|
||||
switch {
|
||||
case useAVX2:
|
||||
initializeAVX2(state, key)
|
||||
case useSSE4:
|
||||
initializeSSE4(state, key)
|
||||
default:
|
||||
initializeGeneric(state, key)
|
||||
}
|
||||
}
|
||||
|
||||
func update(state *[16]uint64, msg []byte) {
|
||||
switch {
|
||||
case useAVX2:
|
||||
updateAVX2(state, msg)
|
||||
case useSSE4:
|
||||
updateSSE4(state, msg)
|
||||
default:
|
||||
updateGeneric(state, msg)
|
||||
}
|
||||
}
|
||||
|
||||
func finalize(out []byte, state *[16]uint64) {
|
||||
switch {
|
||||
case useAVX2:
|
||||
finalizeAVX2(out, state)
|
||||
case useSSE4:
|
||||
finalizeSSE4(out, state)
|
||||
default:
|
||||
finalizeGeneric(out, state)
|
||||
}
|
||||
}
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user